To add an element, you run it through k independent hash functions. Each hash produces an index into the bit array, and you set those k bits to 1. Adding the string "alice" with three hash functions might set bits 4, 19, and 88.
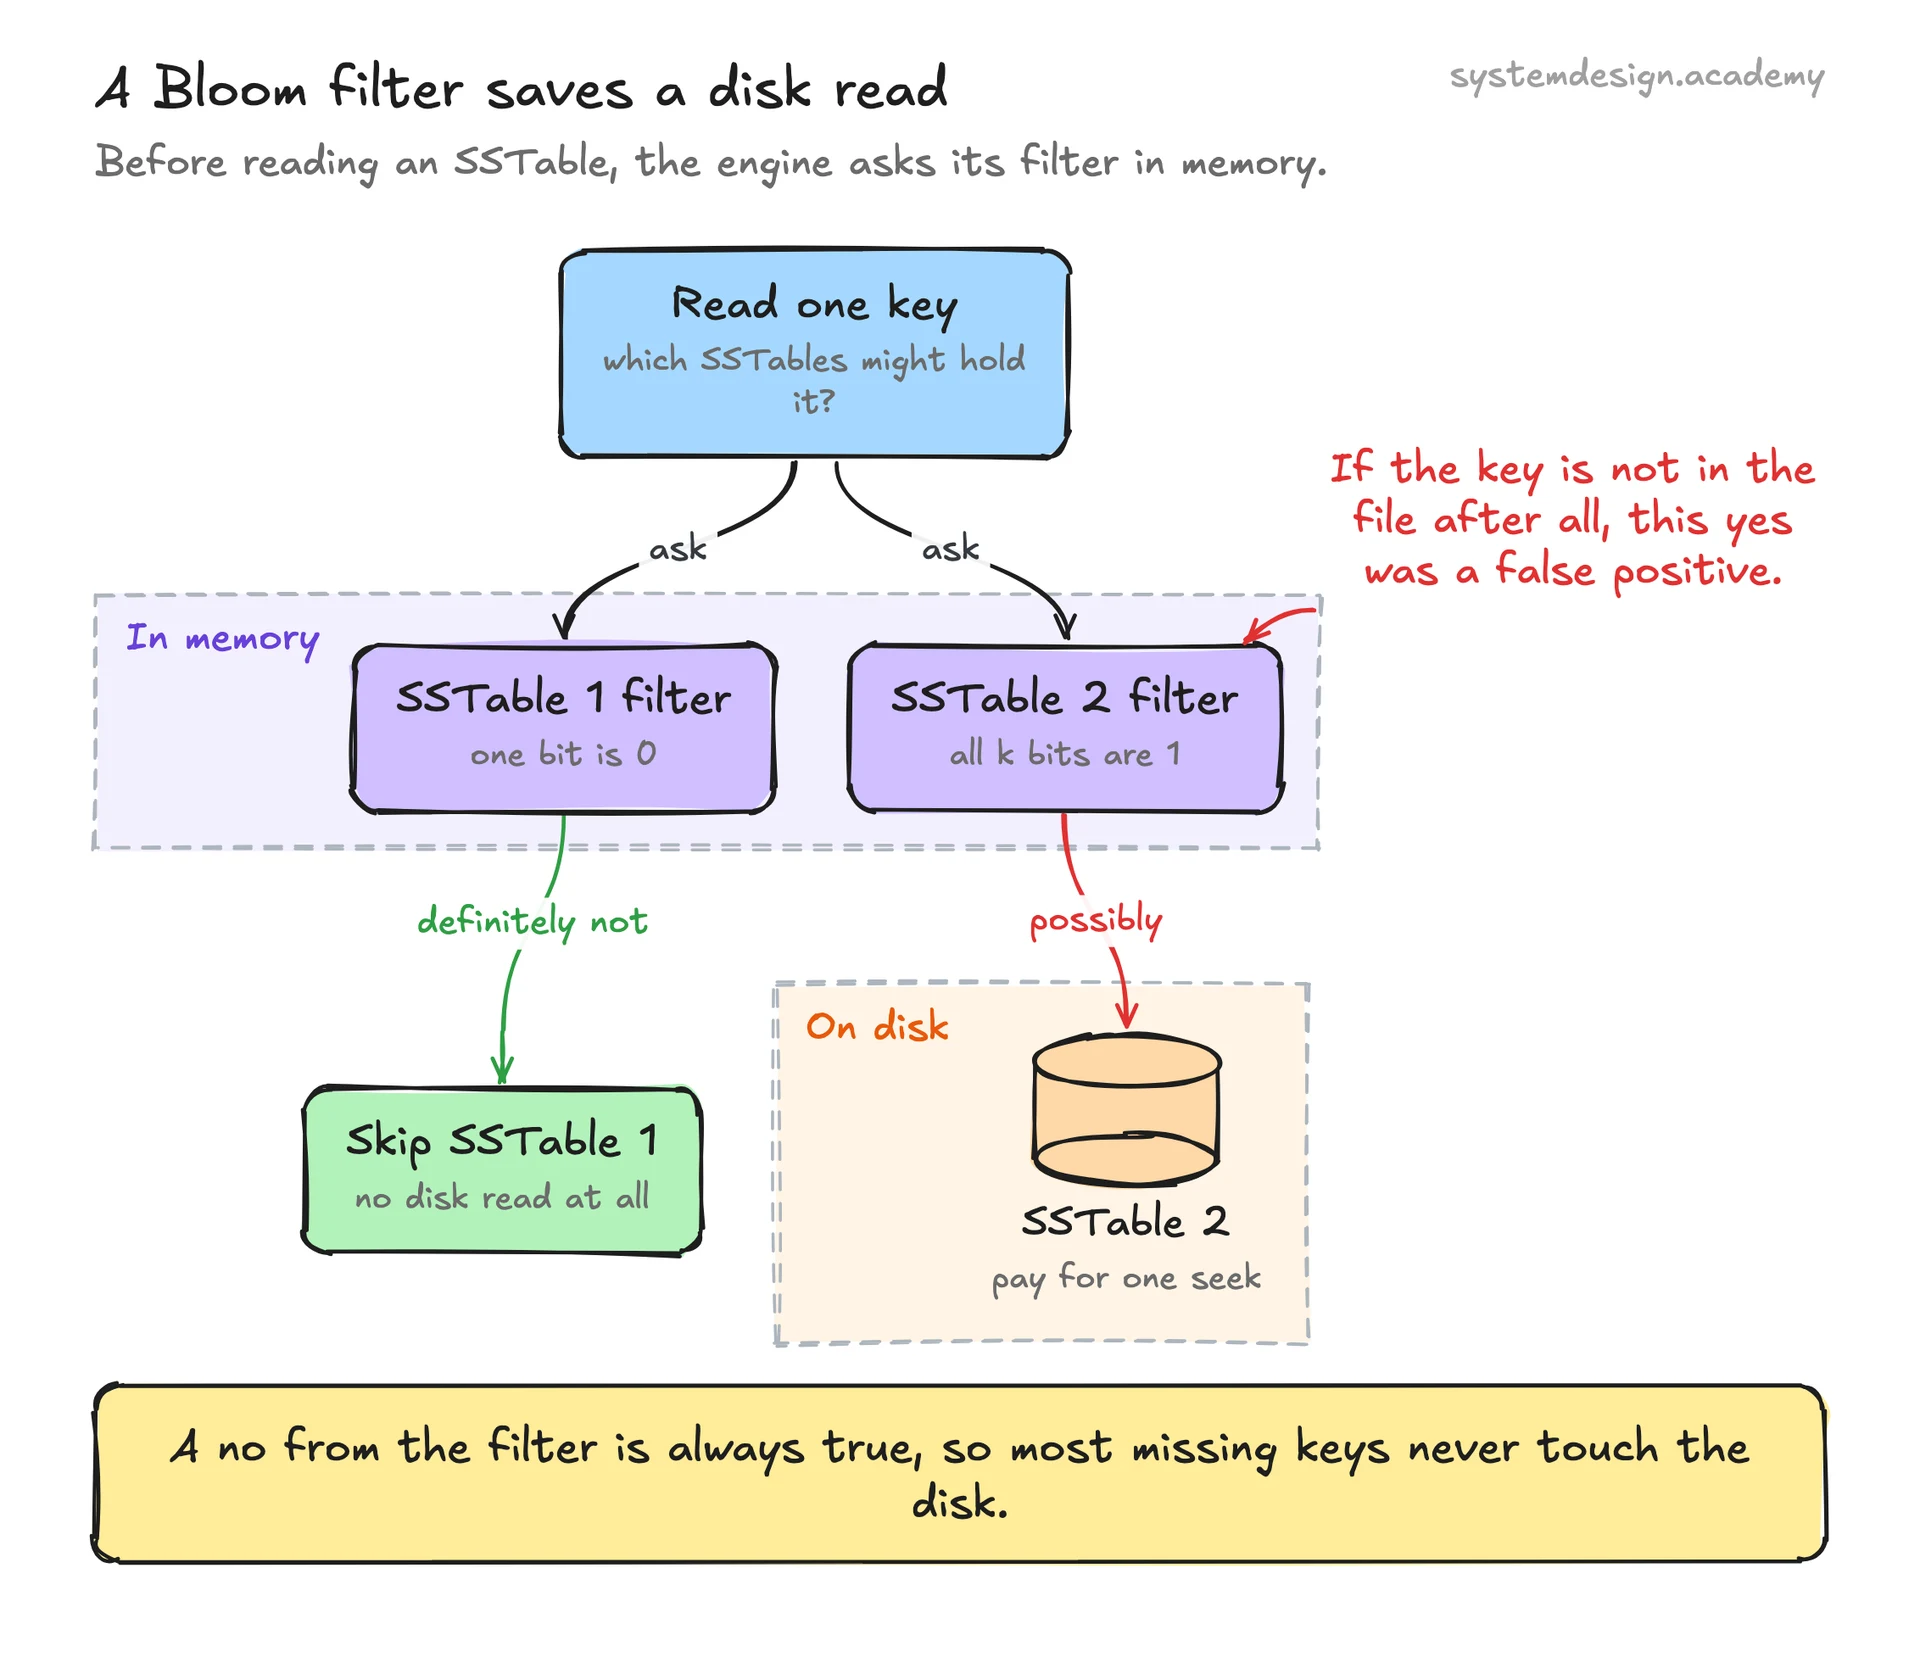
To test for membership, you hash the element the same way and check whether all k of those bits are 1. If even one of them is still 0, the element was never added, so the answer is a definite no. If all k bits are 1, the answer is "possibly yes" because those bits could have been set to 1 by a combination of other elements.
That collision risk is the source of false positives. As you add more elements, more bits flip to 1, and the chance that an unrelated query happens to hit all-ones rises. The false positive rate is tunable: pick the array size m and the hash count k for your expected element count n. The optimal number of hashes is roughly k = (m/n) times ln(2), and adding more memory drives the error rate down fast.
Standard Bloom filters do not support deletion, because clearing a bit might undo bits shared with other elements. Variants exist to handle this. A counting Bloom filter replaces each bit with a small counter so items can be removed, and a scalable Bloom filter grows new layers as the dataset expands beyond the original sizing.