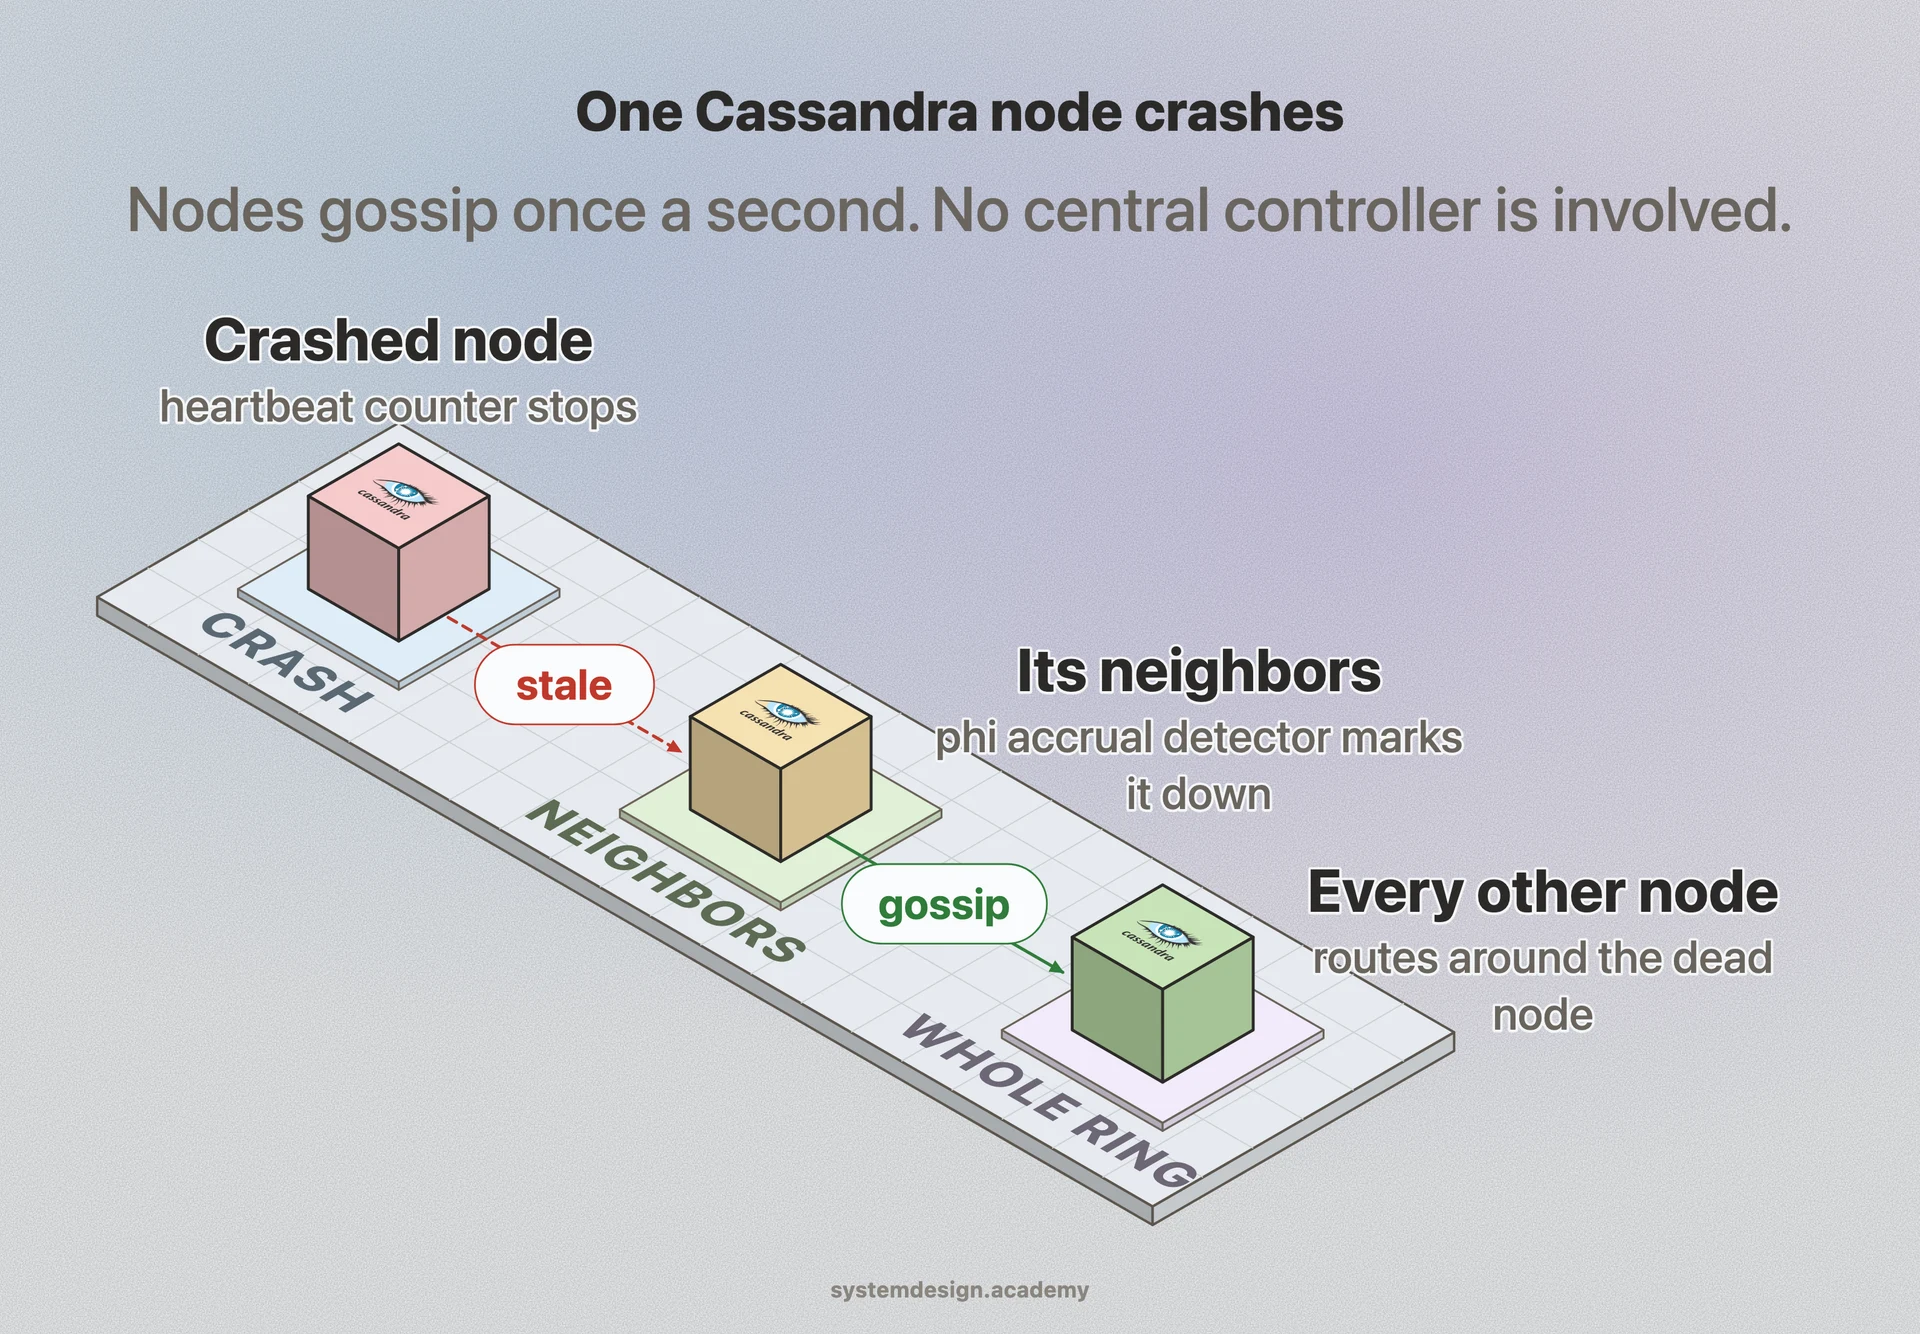
Each round, a node selects peers at random and runs one of three exchange styles. In push, the node sends its updates to the peer. In pull, it asks the peer for updates. In push-pull, both sides send what they have and reconcile, which converges fastest because every contact corrects both nodes at once.
To keep messages small, nodes attach a version number or logical clock to each entry. When two nodes gossip, they compare versions and keep the newer value for each key. This is how Cassandra spreads schema changes and node state: each node carries a heartbeat counter that only goes up, and a higher counter always wins. A node that has not had its counter bumped in a while is suspected dead.
Failure detection rides on the same channel. A common design is the phi accrual failure detector, used in Cassandra and Akka, which does not give a hard alive or dead answer. Instead it tracks the gap between heartbeats and outputs a suspicion level, so the cluster can tune how trigger-happy it is about declaring nodes down. SWIM, used by HashiCorp Serf and Consul, separates failure detection from membership dissemination and adds indirect probing: if node A cannot reach node B, it asks a few other nodes to ping B before declaring it dead, which cuts down false positives on a flaky network.
Convergence time grows logarithmically with cluster size. With a fan-out of a handful of peers per round, a fact reaches a thousand nodes in roughly ten rounds, so about ten seconds at a one-second interval. Bandwidth per node stays roughly constant no matter how large the cluster gets, which is the whole point.