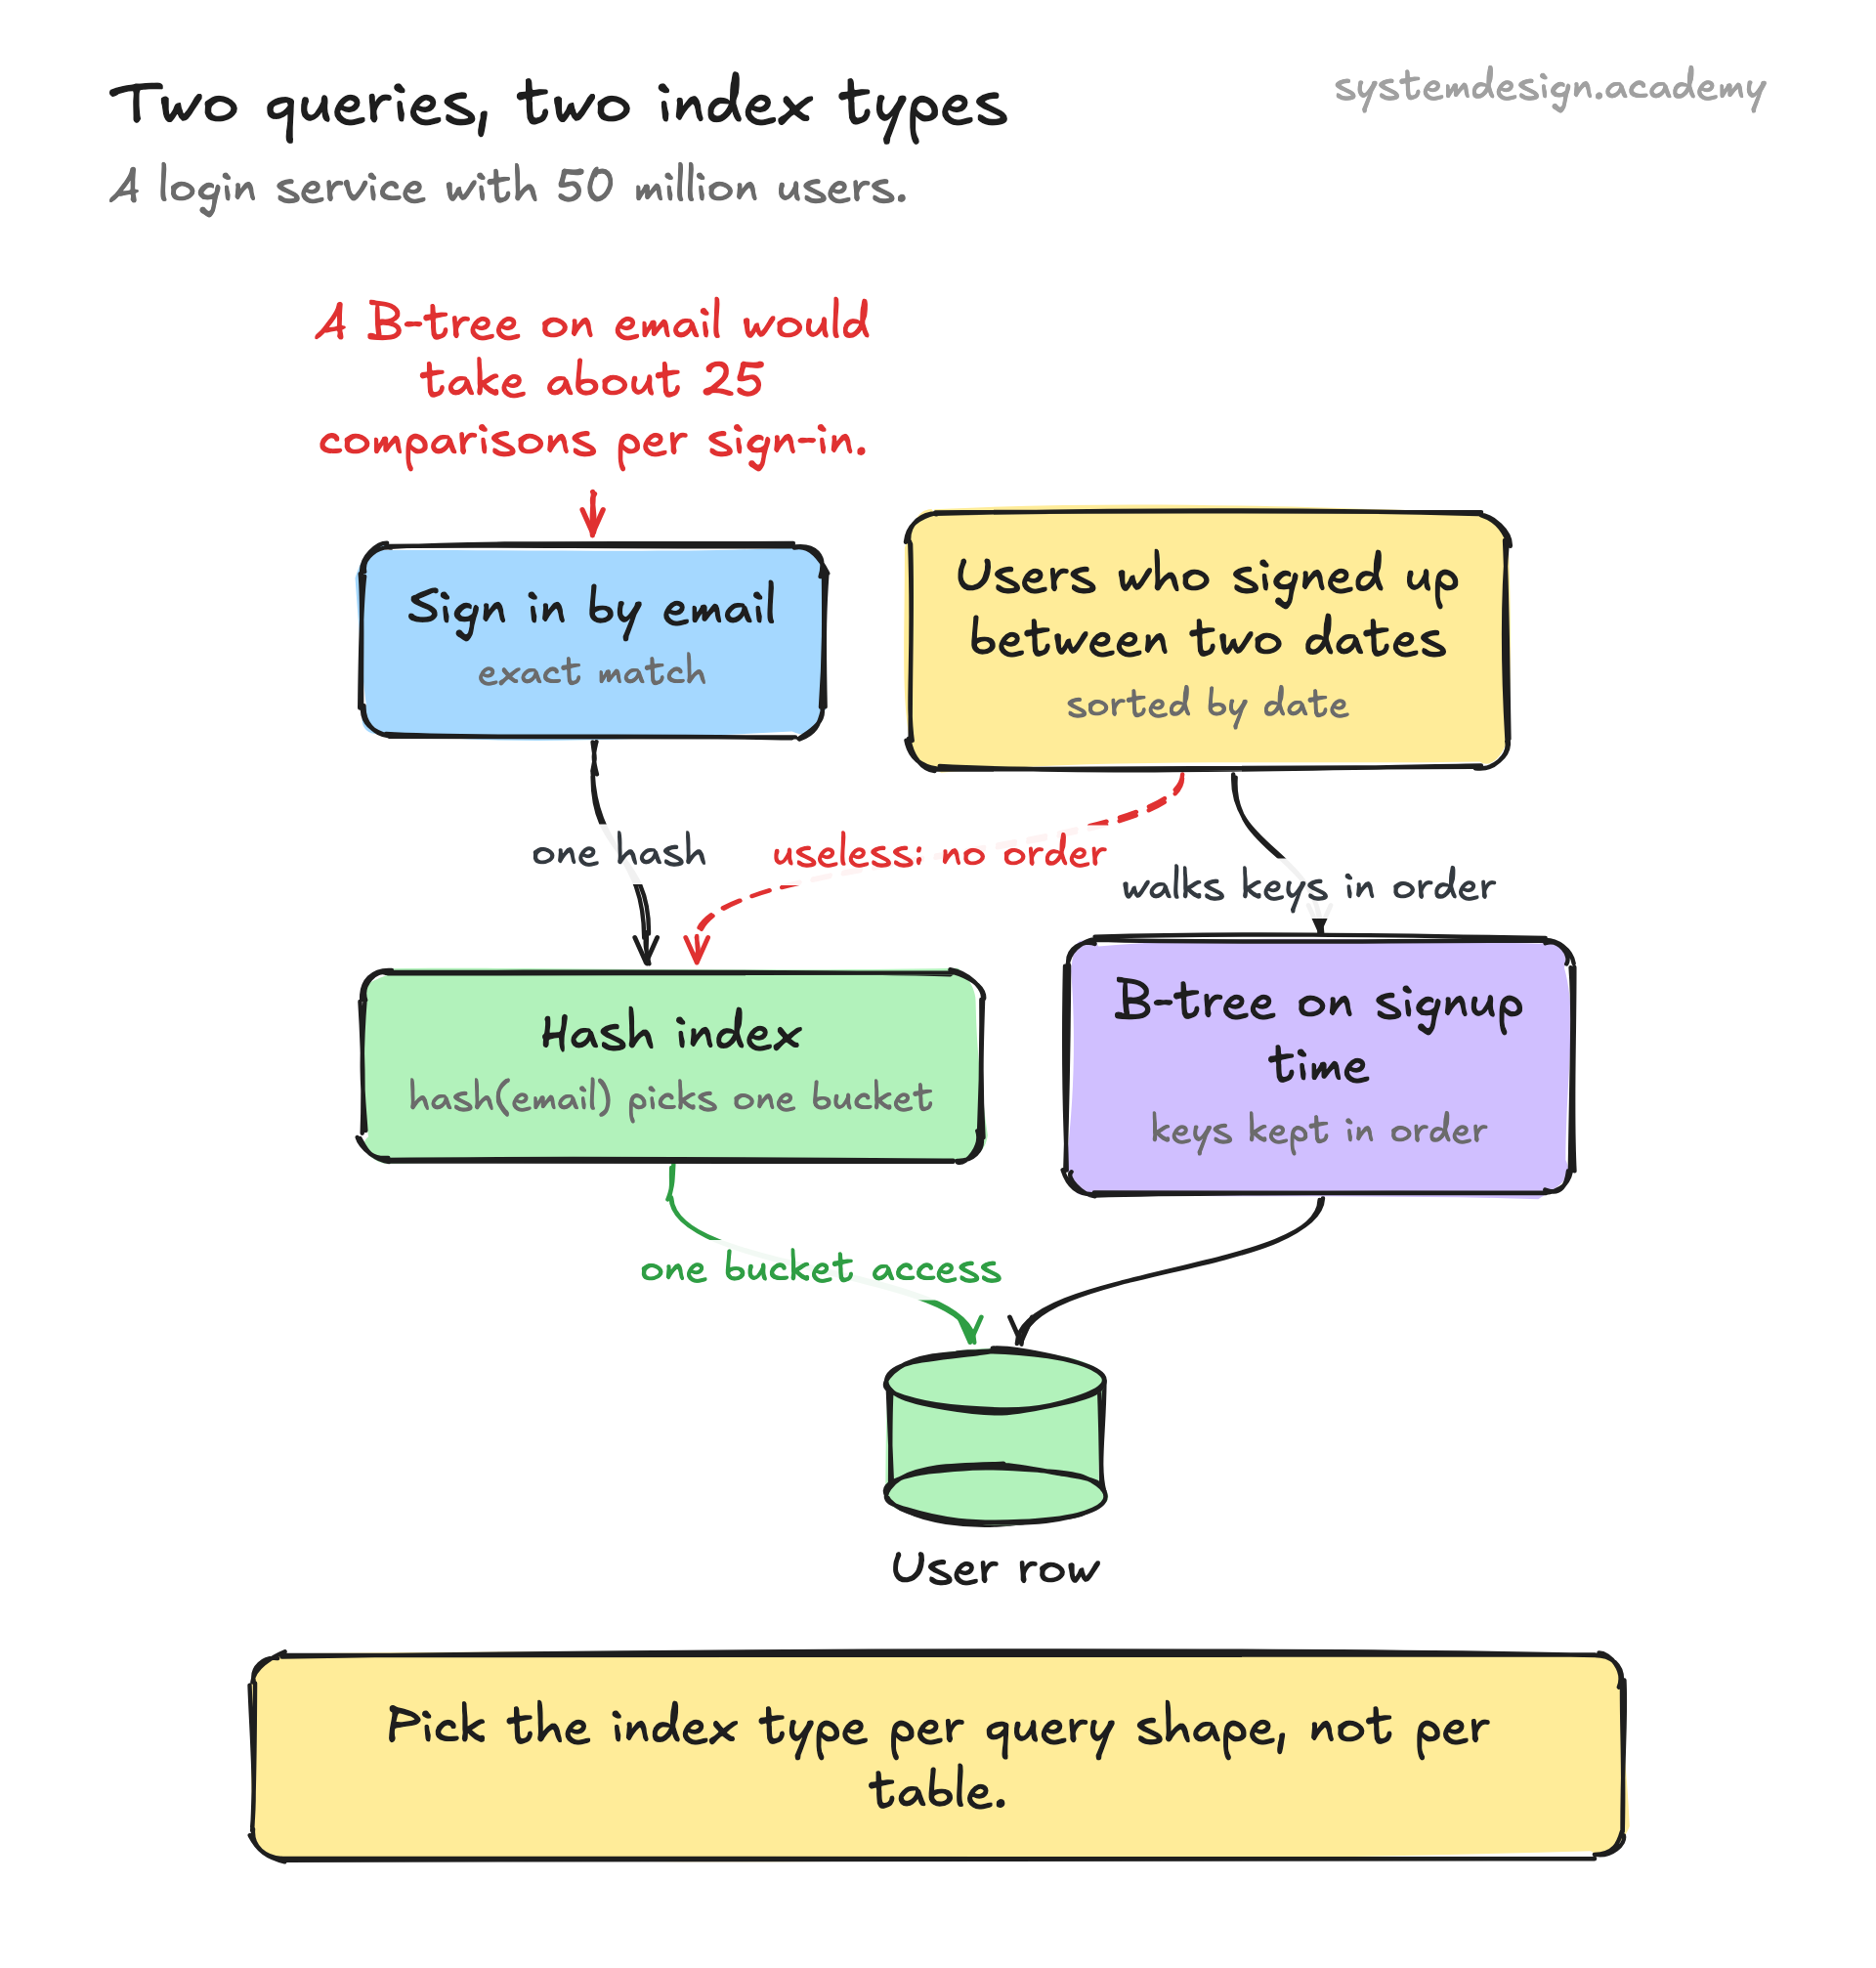
The index is an array of buckets. A hash function maps each key to a bucket number, usually with something like hash(key) modulo bucket_count. Inside each bucket sits a pointer to the actual data, or in an in-memory store like Redis, the value itself.
Two different keys can hash to the same bucket. That is a collision, and it is unavoidable once you have more keys than buckets. The common fix is chaining: each bucket holds a small linked list of entries, and a lookup walks that short list comparing full keys until it finds the match. As long as the table stays well below full, these chains stay length one or two, so lookups stay effectively constant time.
When the table fills up past a load factor (often around 0.7 to 0.75), chains grow long and lookups slow down. The structure then rehashes: it allocates a larger bucket array, often double the size, and re-inserts every key. This is an expensive one-time cost amortized across many fast inserts. PostgreSQL hash indexes, Java's HashMap, and Python's dict all do versions of this.
On-disk hash indexes add a wrinkle: a naive rehash would rewrite the whole file. Linear hashing and extendible hashing solve this by splitting buckets incrementally instead of rebuilding everything at once, which is why production database hash indexes use those schemes rather than a plain in-memory table.