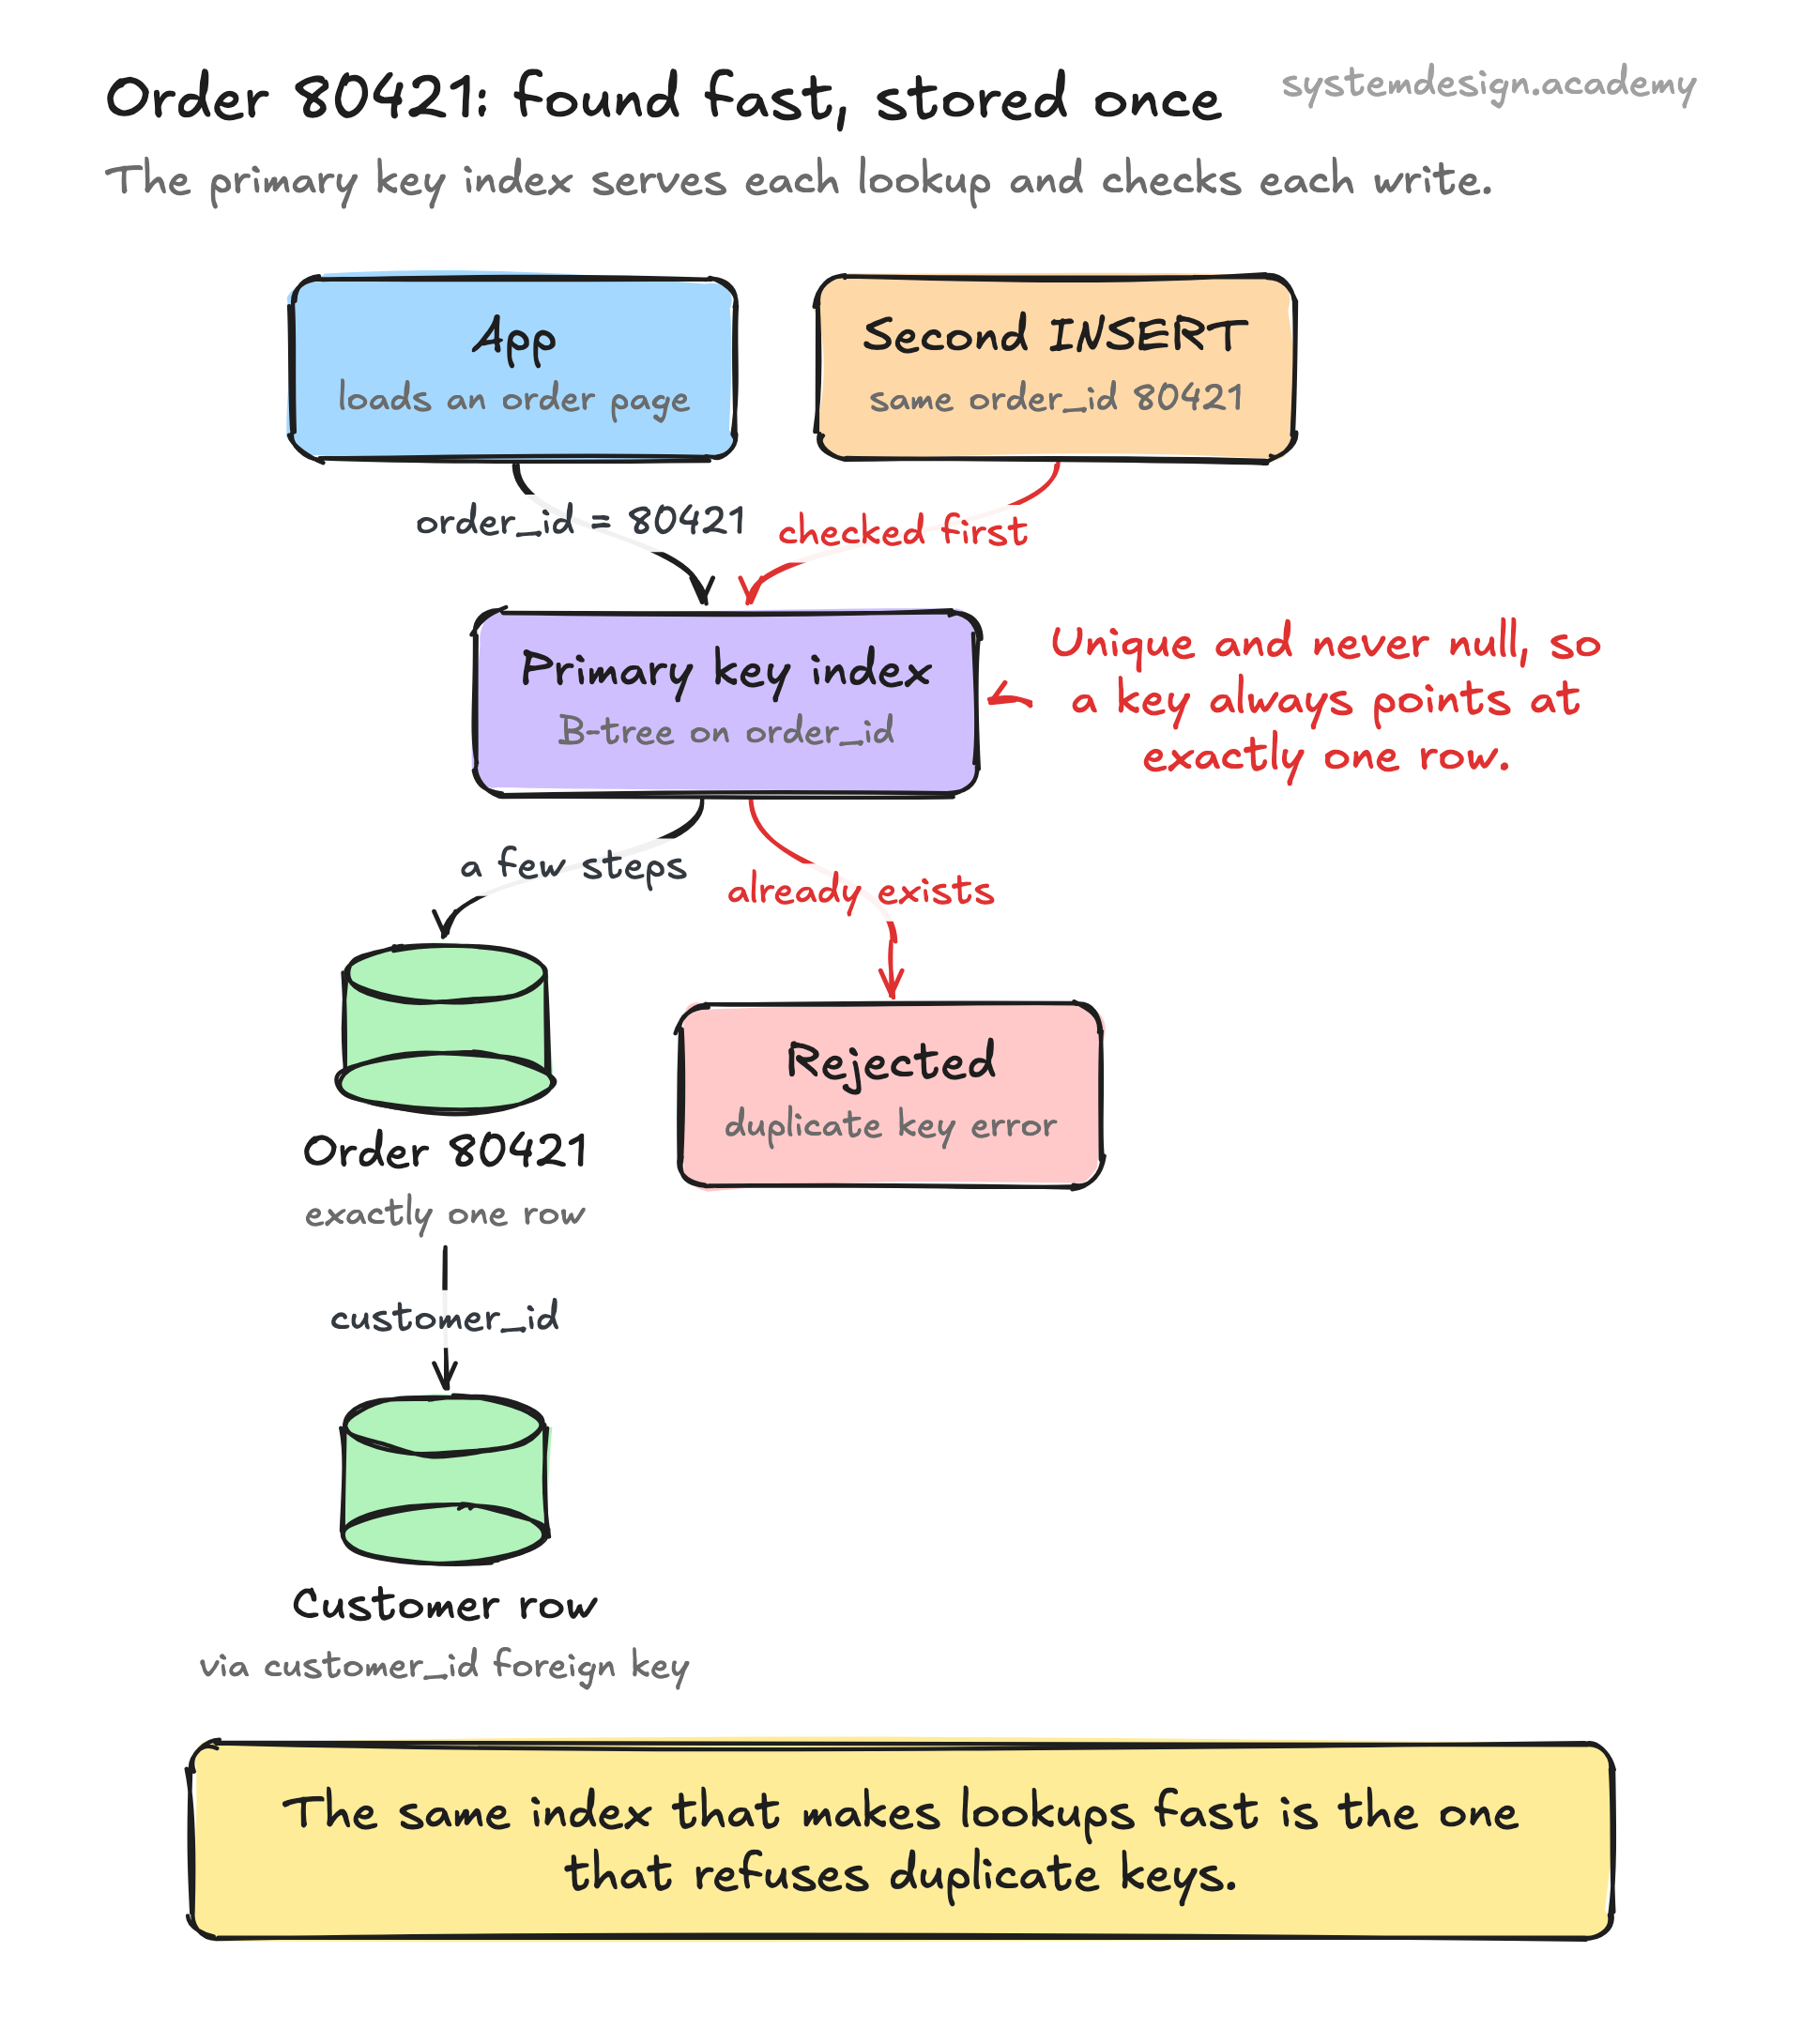
When you declare a primary key, the database builds an index on those columns automatically. In PostgreSQL and most engines this is a B-tree index, a sorted tree structure that lets the engine find any row by its key in a handful of steps instead of scanning the whole table. So a lookup by primary key on a table with 50 million rows is still nearly instant.
That same index is what enforces the uniqueness rule. Before any INSERT or UPDATE commits, the engine checks the index to see if the value already exists. If it does, the write is rejected with a duplicate key error. The not-null rule is also checked at write time, before the row lands, as a check on the row itself rather than a lookup in the index.
In InnoDB, the MySQL storage engine, the primary key goes one step further. The table is physically stored sorted by the primary key, which is called a clustered index. The actual row data lives in the leaf nodes of that key's tree. This is why range scans on the primary key are fast in MySQL, and why every secondary index quietly stores a copy of the primary key to find the full row.