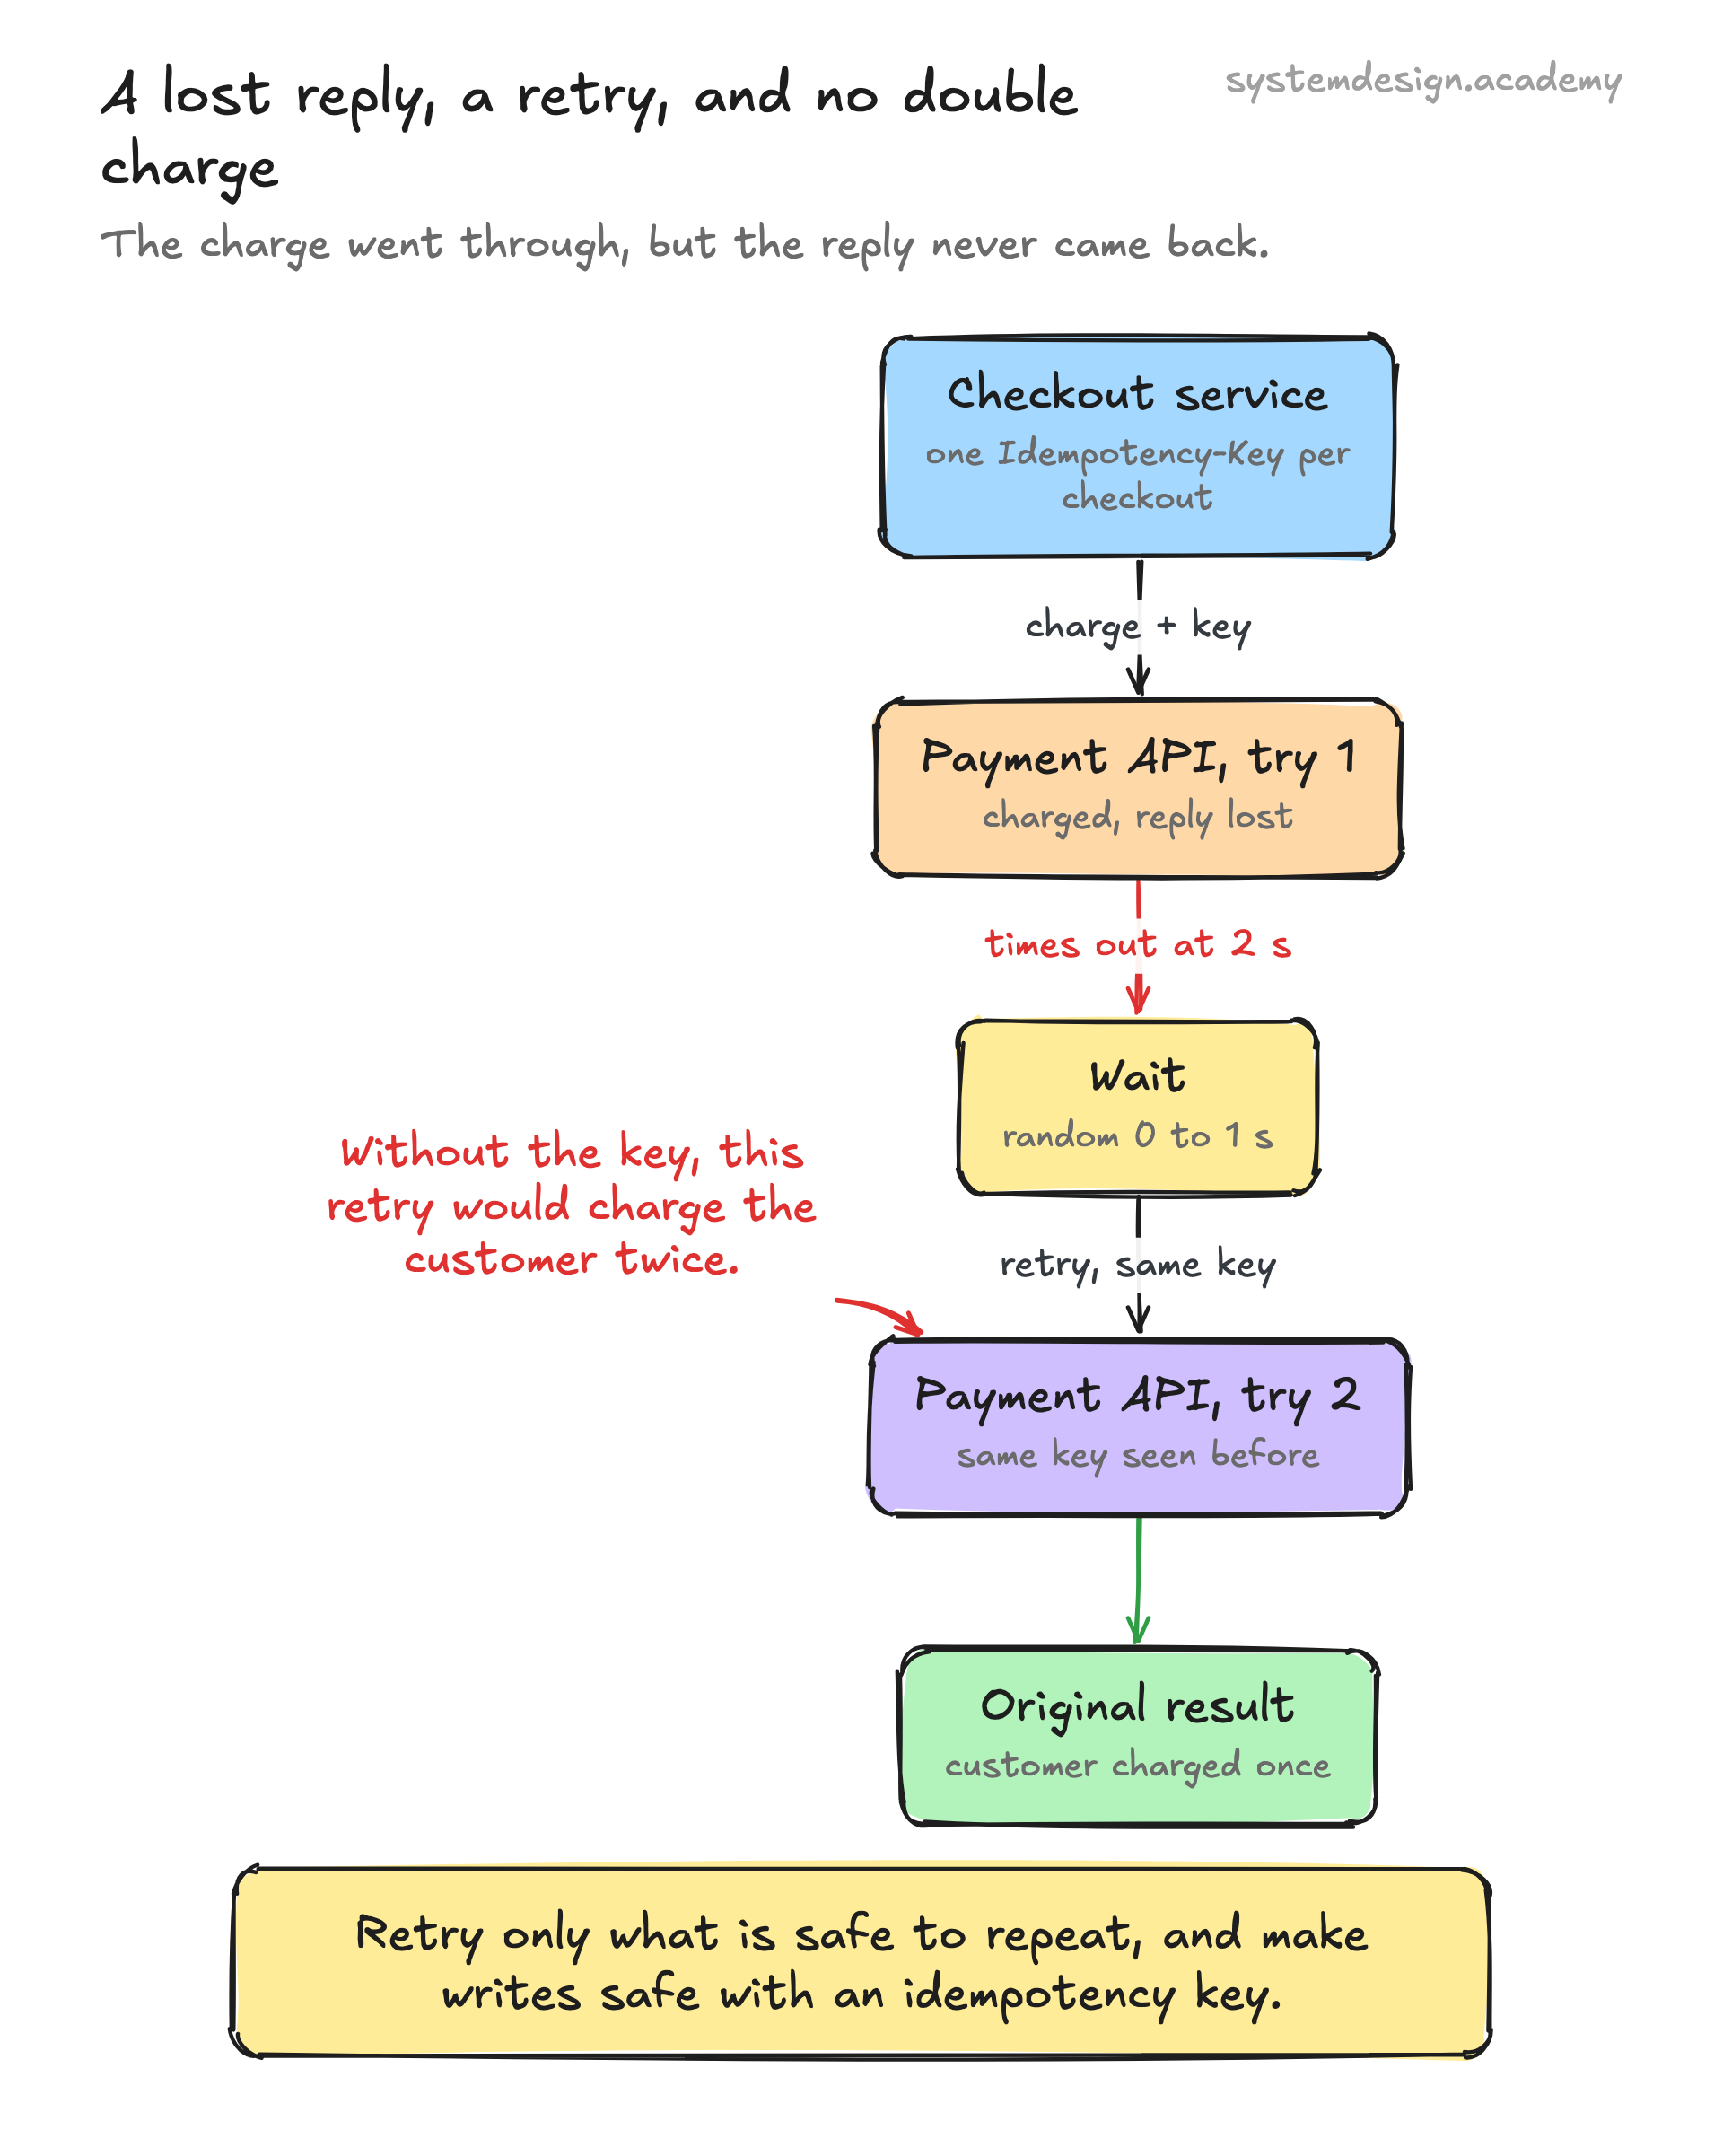
A naive retry loop tries again immediately, which is the worst thing to do when a service is overloaded. Every client retrying at once produces a thundering herd that keeps the service down. The fix is exponential backoff: wait longer after each failure. A common schedule is 1 second, then 2, then 4, then 8, doubling each time up to a ceiling.
Backoff alone is not enough, because clients that all failed at the same instant will also all retry at the same instant. Adding jitter (a random amount of delay) spreads those attempts out. AWS recommends full jitter, where the actual wait is a random value between zero and the computed backoff. This smooths the load into a steady trickle instead of synchronized spikes.
Every retry policy needs a hard cap, both on attempts (often 3 to 5) and on total elapsed time. Without a cap, a retry loop can hold a request open for minutes, tying up threads and connections while the user stares at a spinner. Pair retries with a circuit breaker so that once a downstream is clearly dead, calls fail fast instead of retrying into the void.