There are three common strategies, and most systems mix them. The first is time based expiry, or TTL. You tag each entry with a lifetime, say 60 seconds, and the cache automatically drops it when the clock runs out. It is simple and needs no coordination, but it accepts staleness for the length of the TTL.
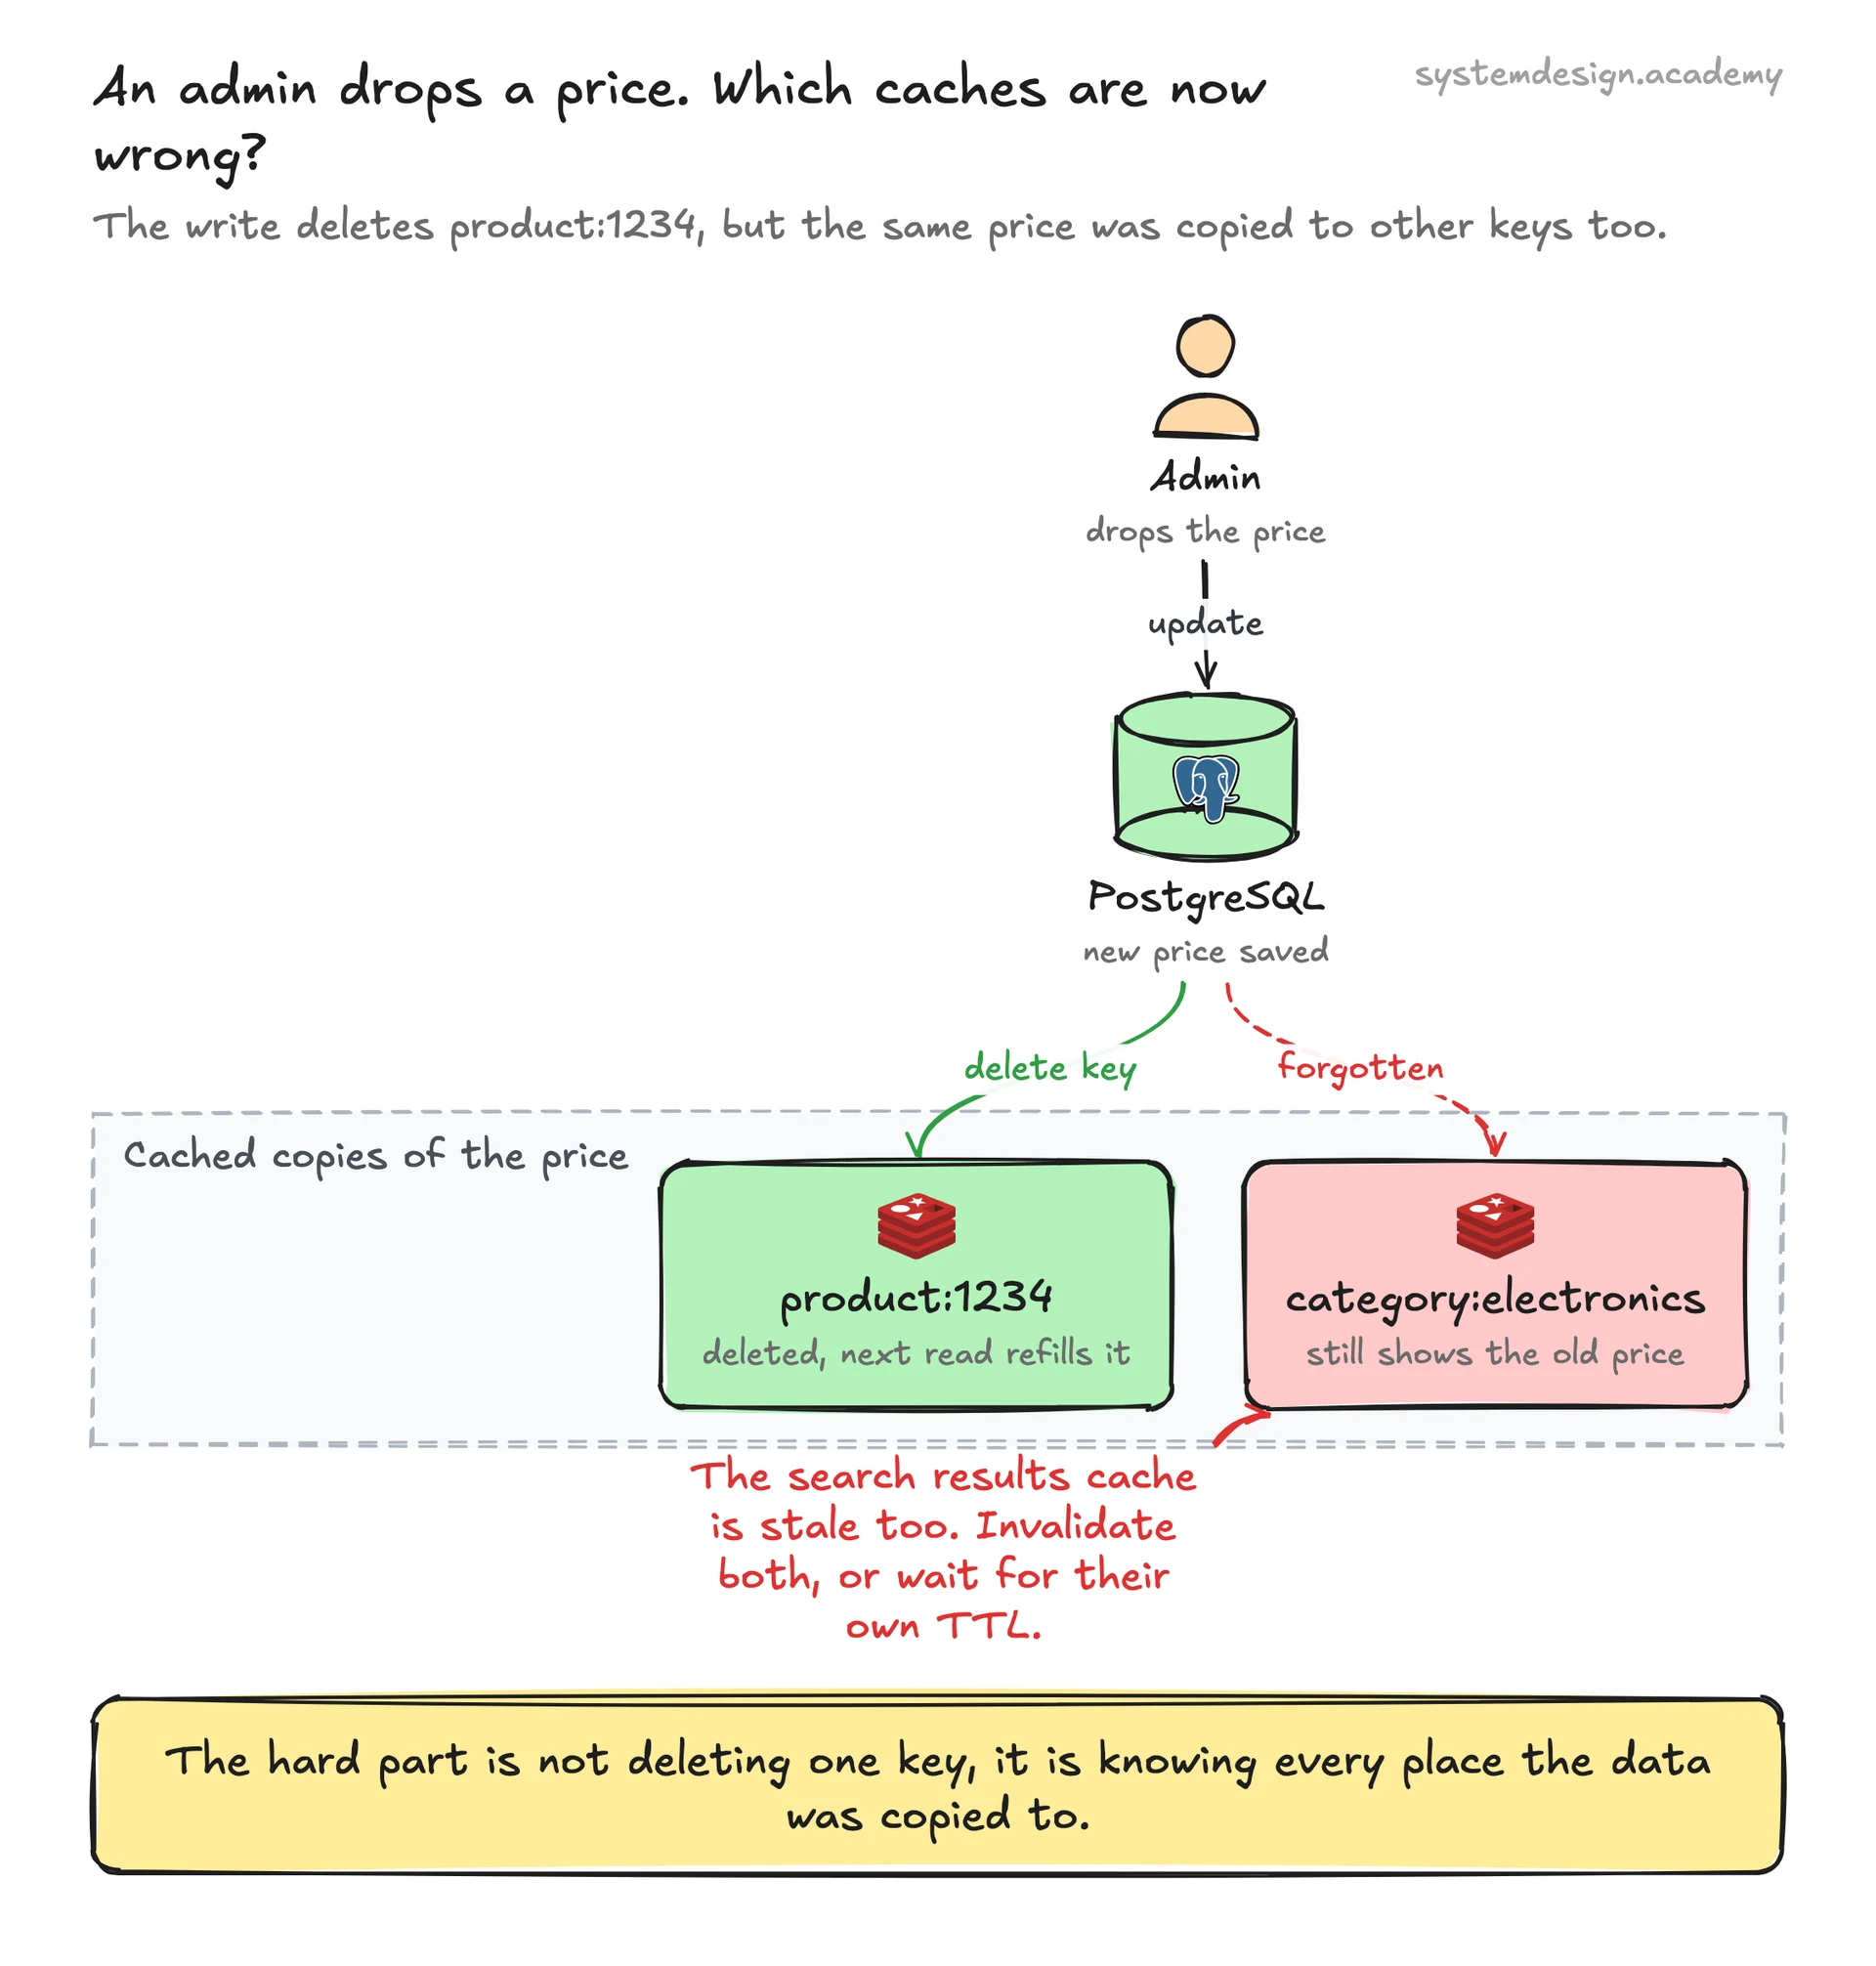
The second is explicit invalidation on write. When your application updates a record, it also deletes or updates the matching cache key in the same code path. A common pattern is cache-aside: the app reads from the cache, falls back to the database on a miss, and on any write it deletes the key so the next read repopulates it. Deleting is usually safer than updating in place because it avoids a race where two writers leave a wrong value behind.
The third is event based invalidation. Instead of every writer knowing about every cache, a change emits an event, often through a log like Kafka or a database change stream, and subscribers purge the affected keys. CDNs work this way too: you call a purge API and the edge nodes drop the cached object. This decouples the writer from the caches but adds propagation delay measured in milliseconds to seconds.
Key design is the quiet part that decides whether any of this works. If a single piece of data is cached under five different keys, all five have to be invalidated or you will leak stale copies. Many bugs are not in the invalidation logic itself but in forgetting which keys depend on a given record.