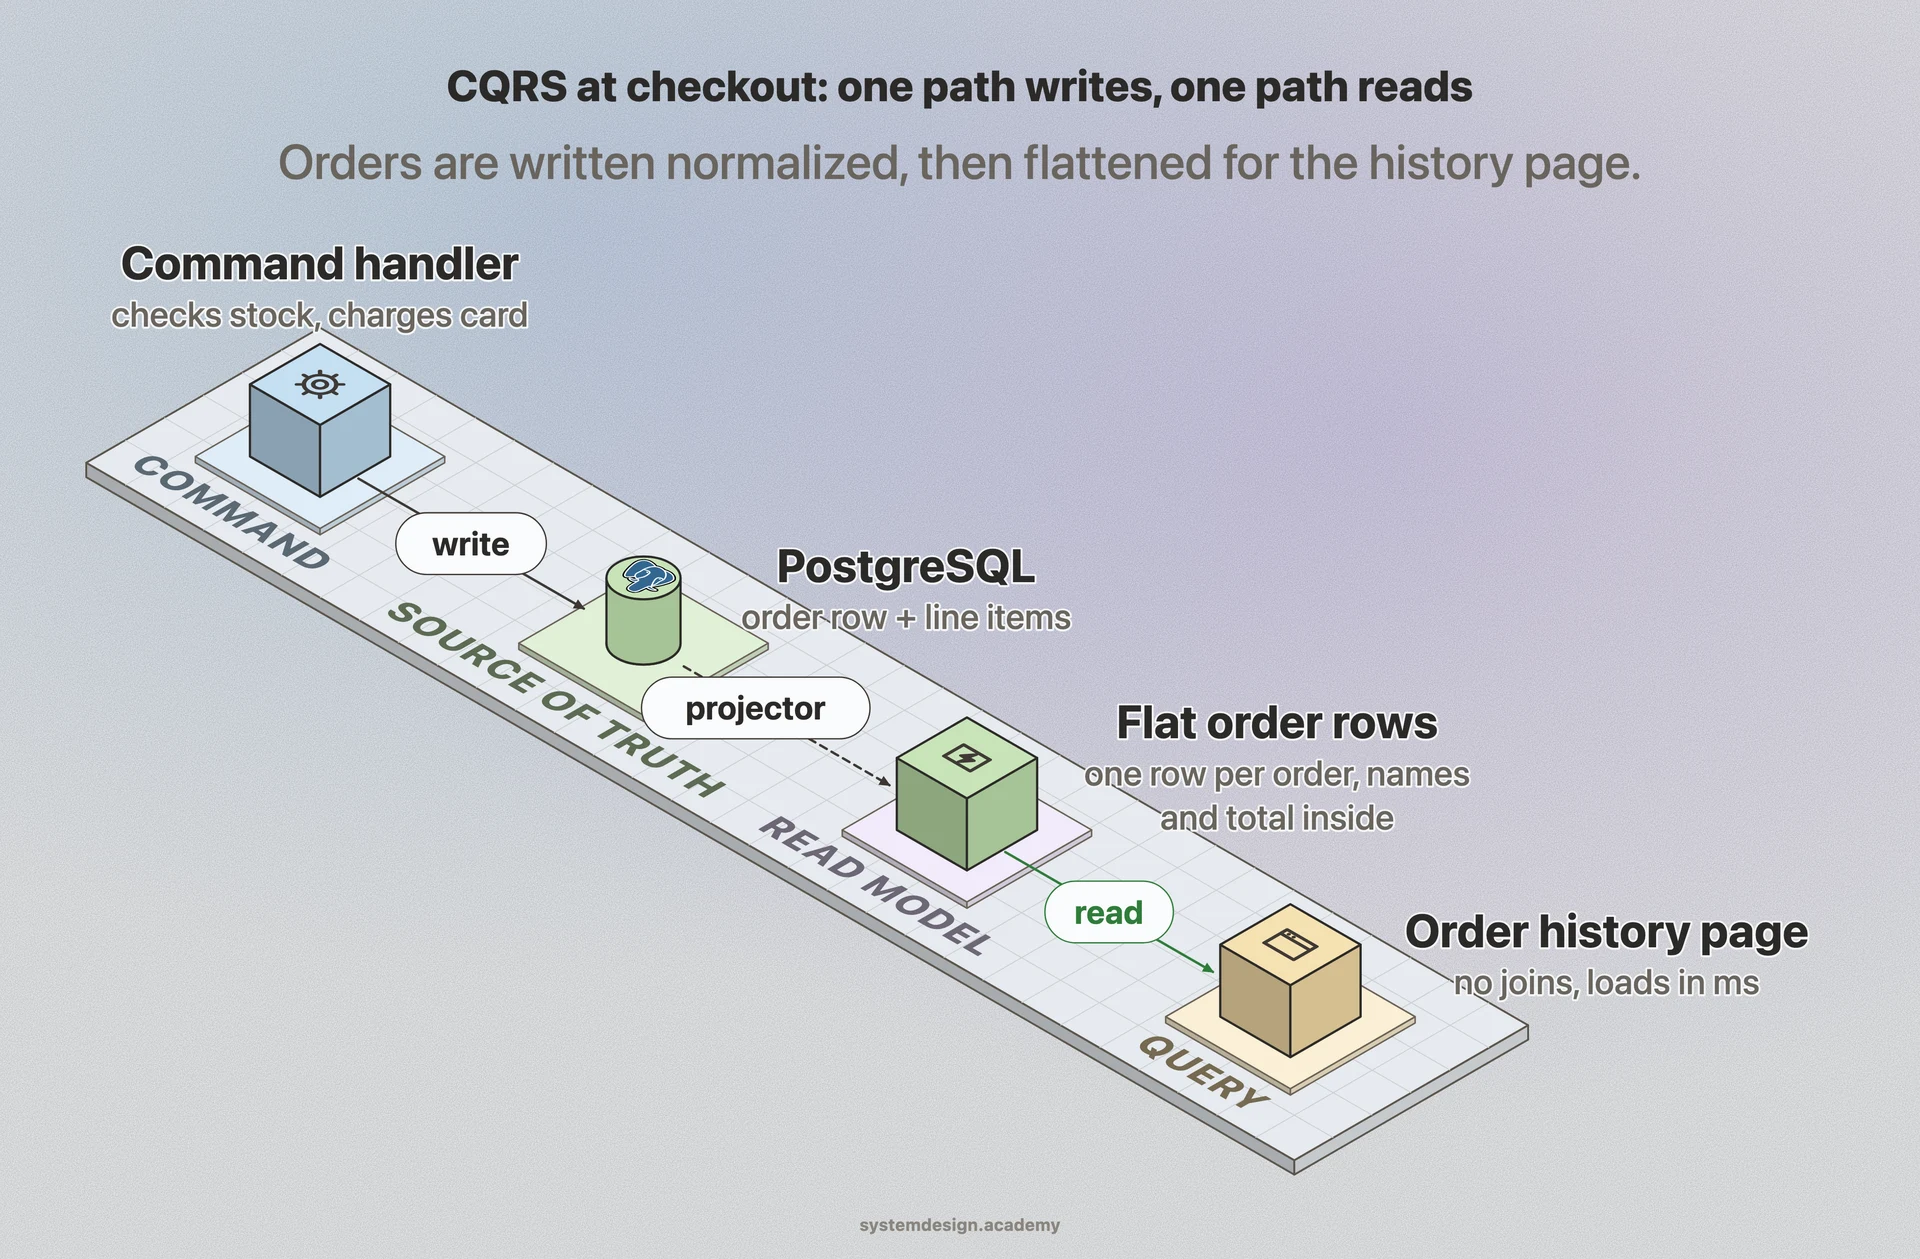
The write side accepts a command, validates it against business rules, and updates the authoritative data store. This is your source of truth. It stays normalized and consistent because correctness matters more than read speed here.
The read side serves queries from a read model that is optimized for display. In the full version, this read model lives in a separate store: a denormalized table, a document in MongoDB, a search index in Elasticsearch, or a cache in Redis. When the write side changes data, it publishes an event, and a projector listens for that event and updates the read model to match.
That last step introduces the most important property to understand: the read model is updated asynchronously, so it is eventually consistent. There is a small window, usually milliseconds, where a user who just wrote data could query the read side and not see their own change yet. Systems handle this by reading their own writes from the write side, or by showing an optimistic UI update until the projection catches up.
When CQRS is paired with event sourcing, the write side stores the full sequence of events rather than just the current state, and read models are built by replaying those events. The two patterns fit together well, but neither requires the other.