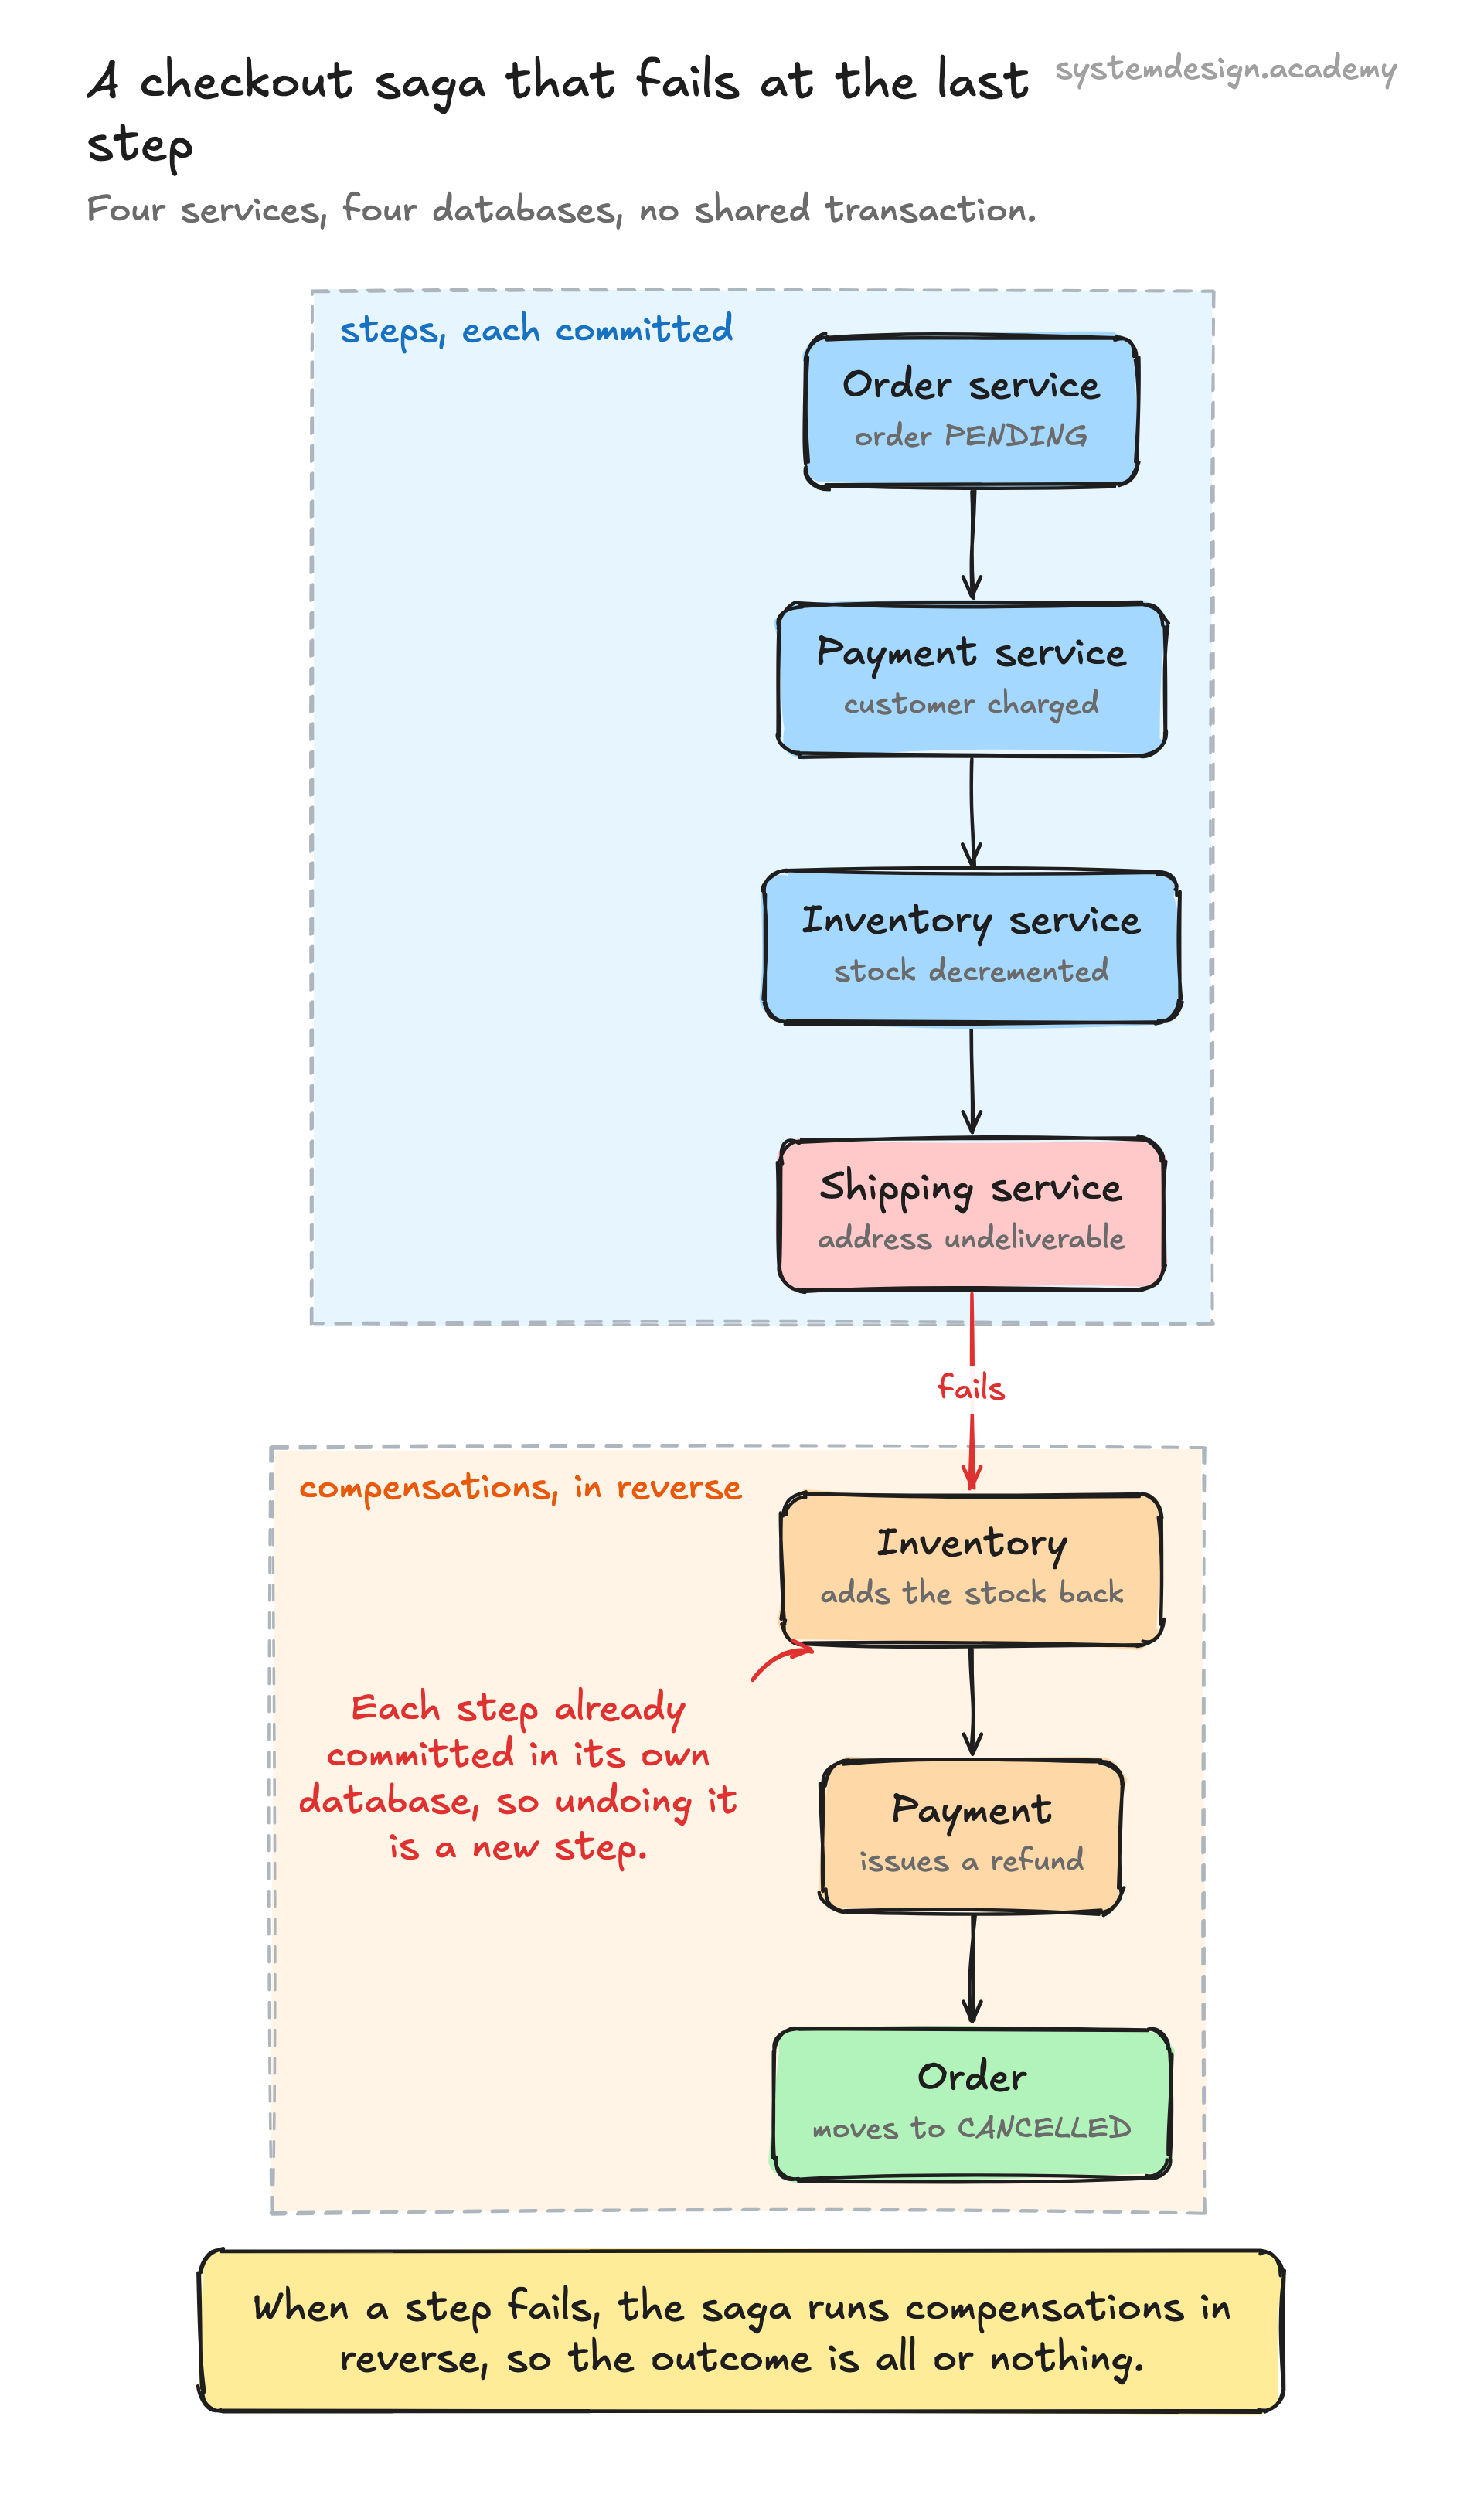
There are two common ways to coordinate the steps. Choreography is event-driven and has no central brain: each service listens for events on a message broker like Kafka or RabbitMQ, does its work, and emits a new event that the next service reacts to. It is loosely coupled and easy to start with, but the overall flow is implicit and hard to trace once you have more than three or four steps.
Orchestration uses a central coordinator, often called a saga orchestrator, that tells each service what to do and waits for the reply. The orchestrator holds the saga state machine: which step we are on, what to call next on success, and what compensation to call on failure. Frameworks like Temporal, AWS Step Functions, Camunda, and Axon implement this. The flow is explicit and observable, at the cost of one more moving part.
Either way, two properties are non-negotiable. Steps and their compensations must be idempotent, because the broker will redeliver messages and the orchestrator will retry after crashes, so running the same step twice must not double-charge a card. The saga state must also be persisted durably after each step, so a crash mid-saga can be recovered and resumed rather than left half-finished.