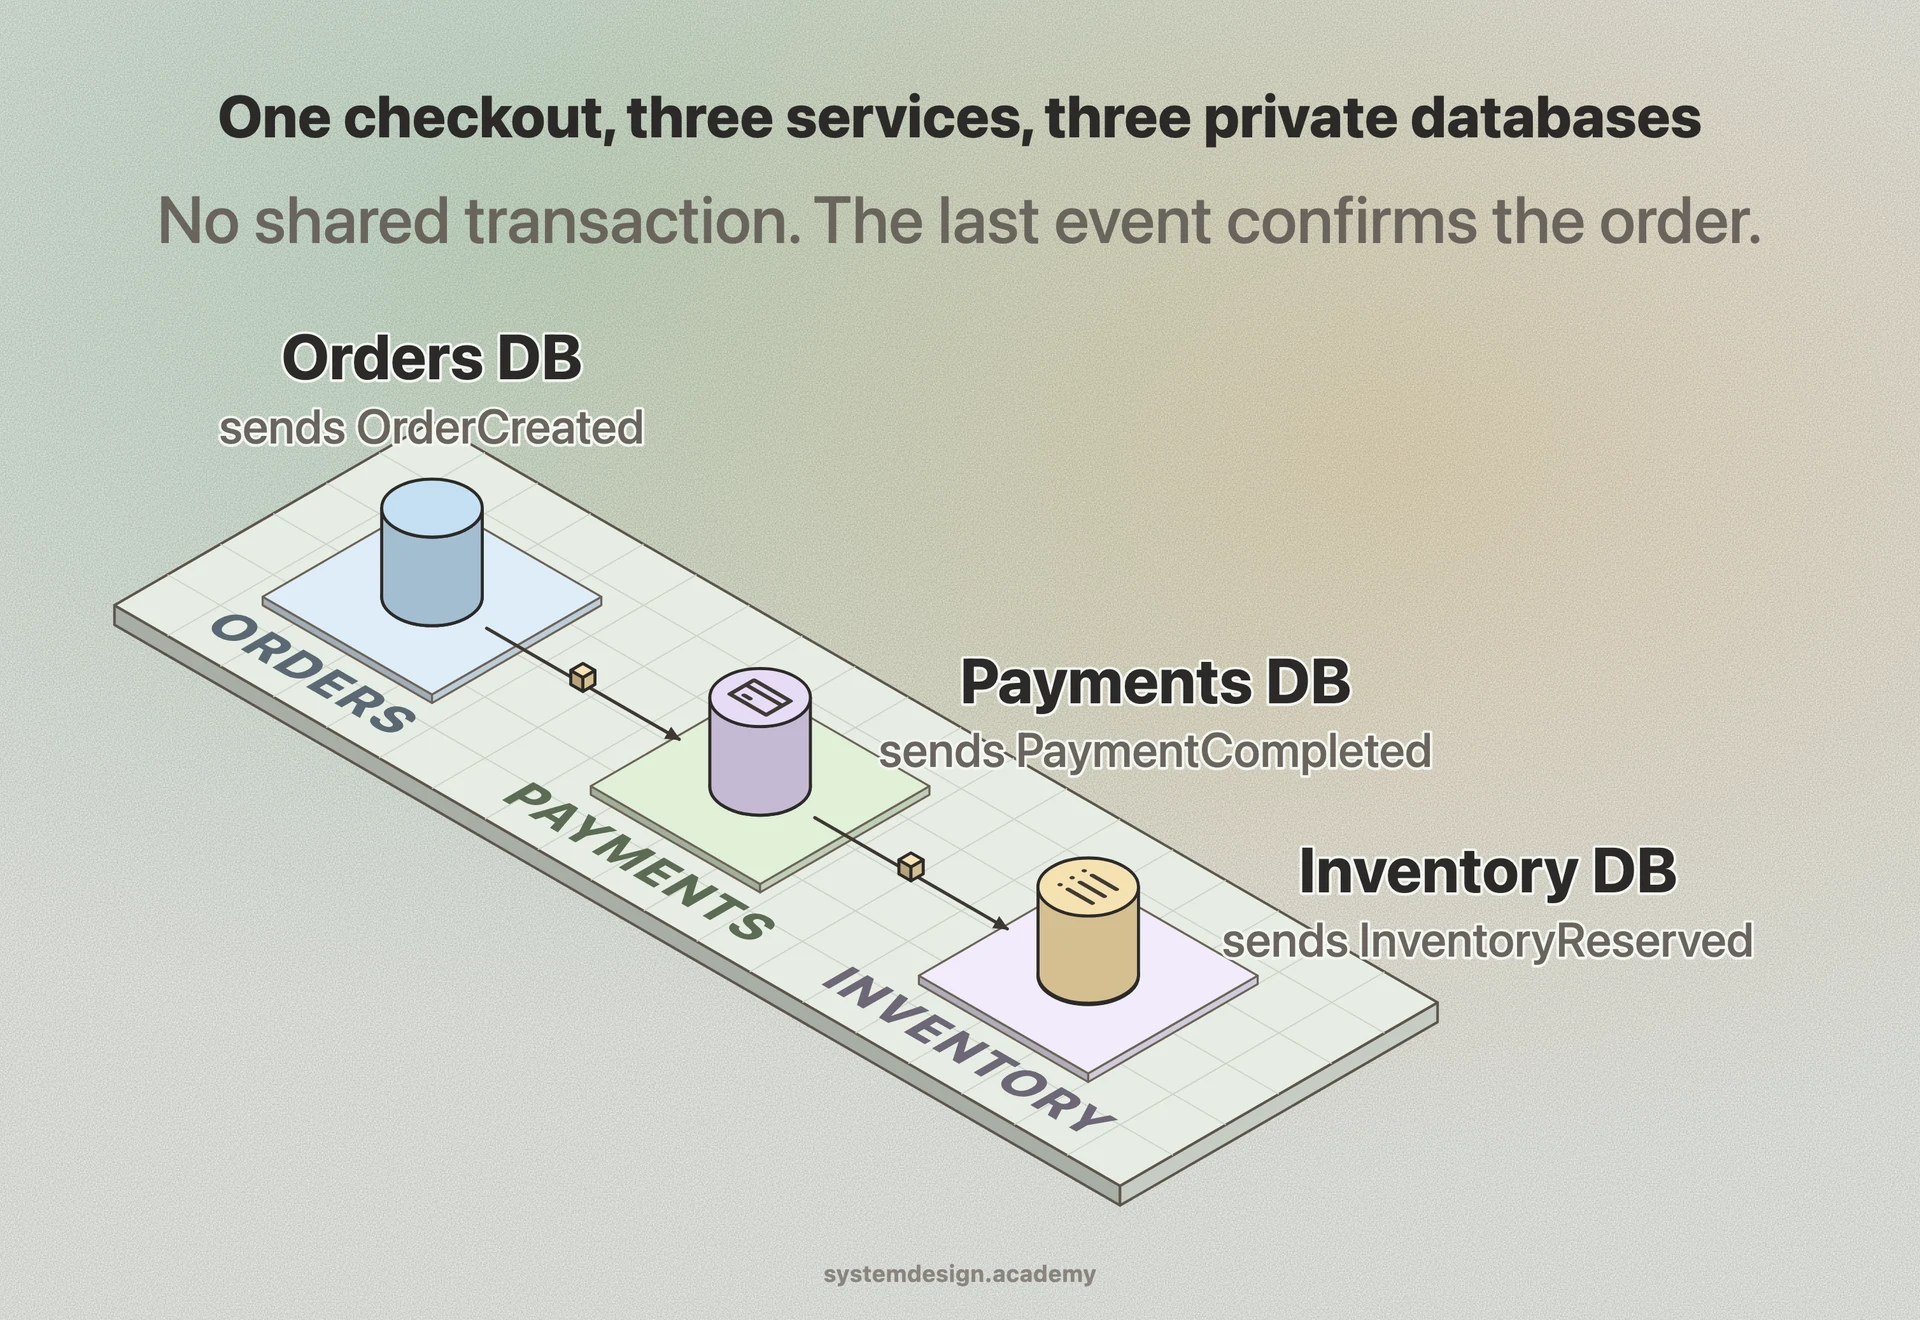
Use it when you genuinely have independent teams owning independent services and you want them to deploy, scale, and change their schema without coordinating with everyone else. The biggest win is exactly that: a team can alter its tables, add an index, or migrate engines without breaking another team, because nobody else is allowed to touch its data.
The cost is real. You give up cross-table joins and single-database transactions. You take on eventual consistency, duplicate data across services, and the operational burden of running many databases with their own backups, migrations, and monitoring. Reporting and analytics get harder because the data lives in many places, which usually means building a separate data warehouse fed by change-data-capture.
If your application is small, has one team, or relies heavily on transactions and joins across the whole dataset, a single shared database (the monolith approach, or a modular monolith) is usually the right call. Database per service pays off at organizational scale, not at the start of a project. Splitting too early is one of the most common and expensive microservices mistakes.