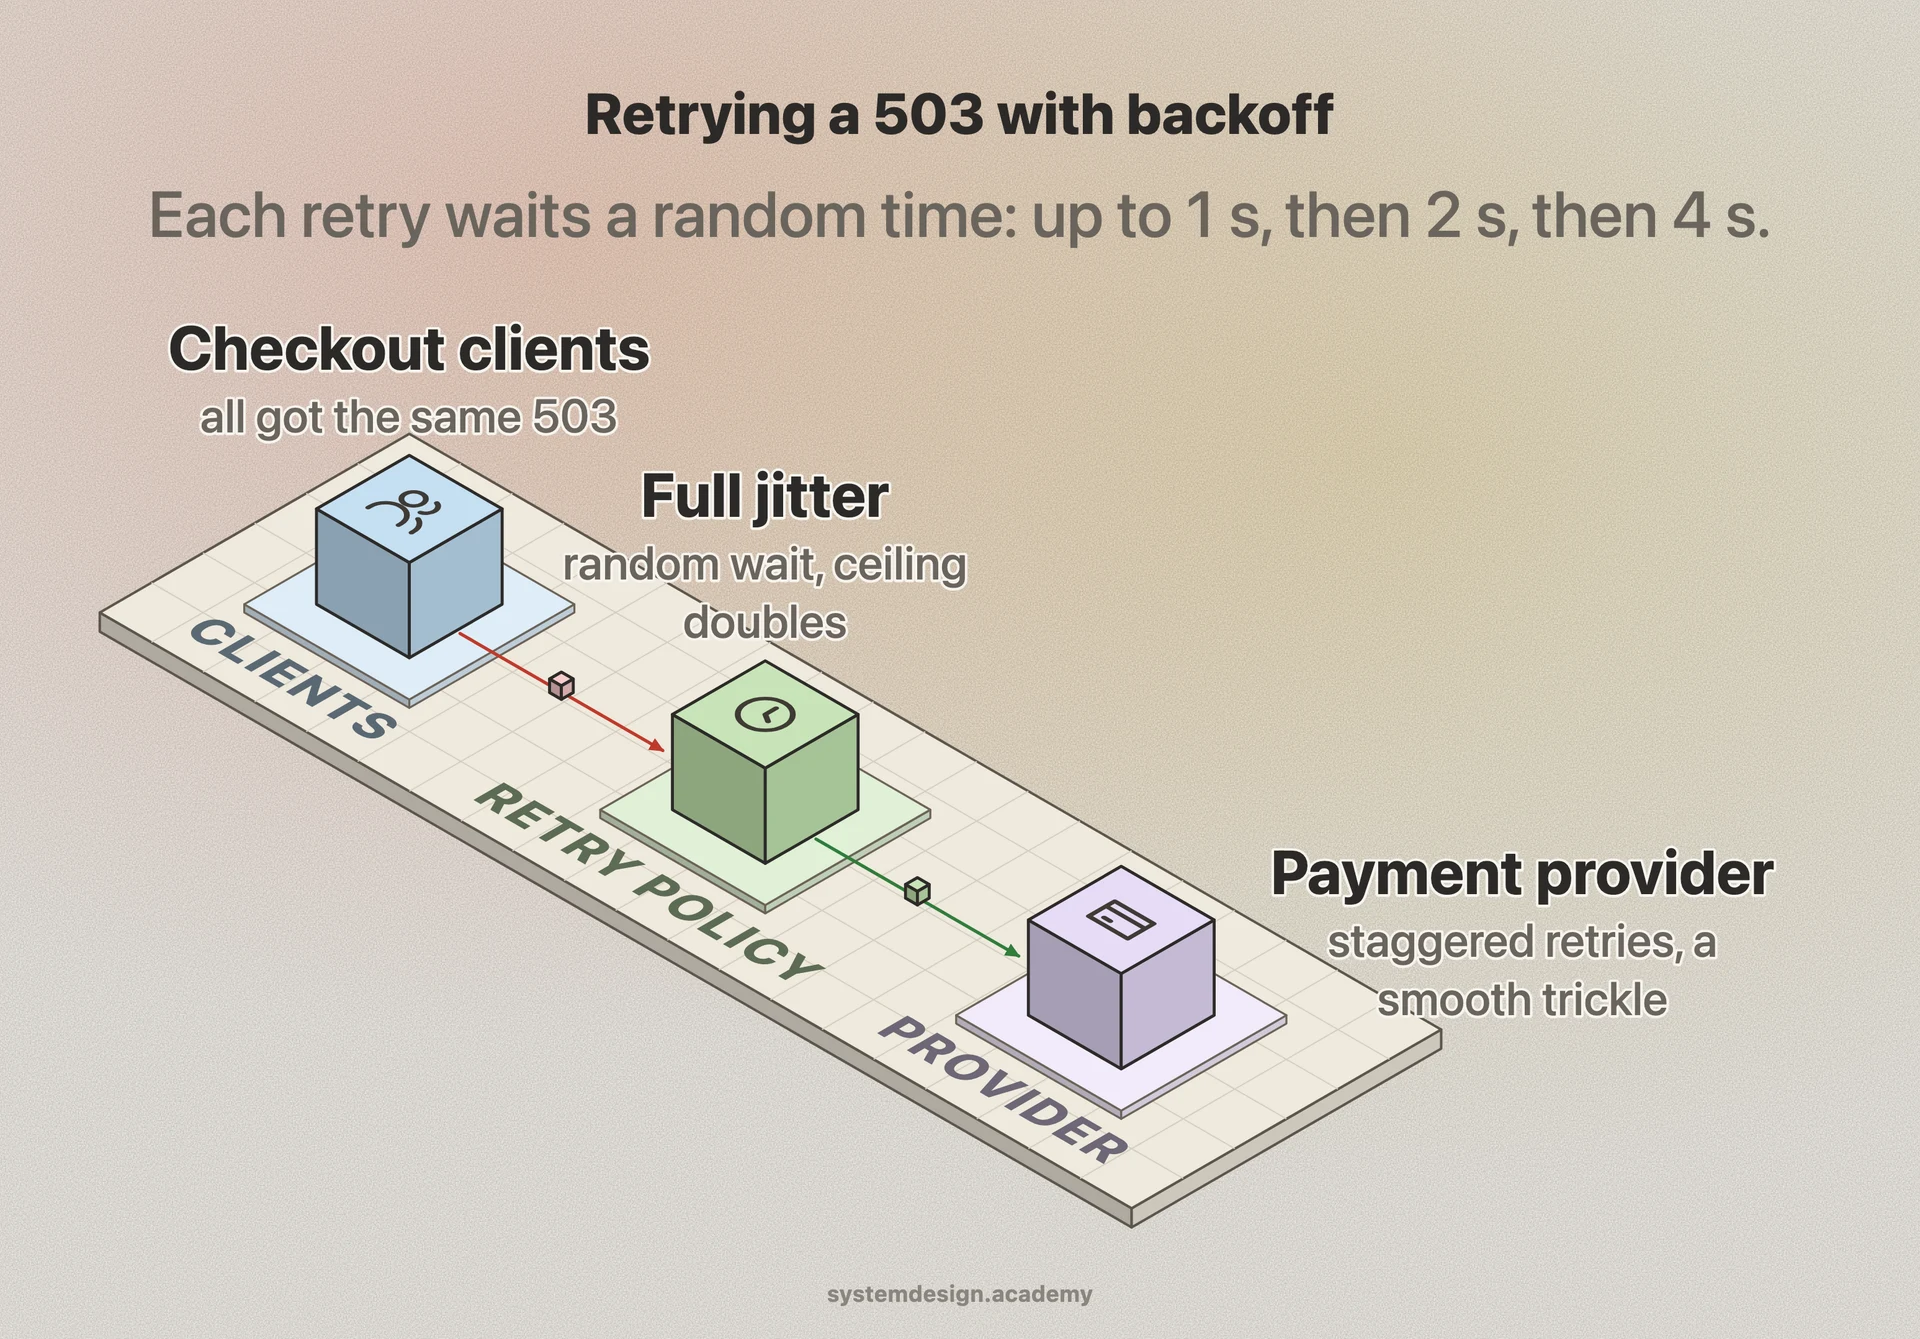
When a network call fails, the simplest fix is to try again. But retrying immediately, or on a fixed timer, is dangerous: if a service is overloaded, a flood of instant retries makes the overload worse. Exponential backoff solves this by increasing the delay after each failed attempt, typically by a factor of 2.
A common schedule looks like: wait 1 second, then 2, then 4, then 8, then 16, often with a cap (a maximum delay) so it never grows past, say, 30 or 60 seconds. After a set number of attempts the client gives up and surfaces an error.
The point is to give the failing system room to recover. Each retry waits longer than the last, so a temporary blip gets one or two quick retries, while a longer outage triggers fewer, more spaced-out attempts instead of a relentless barrage.