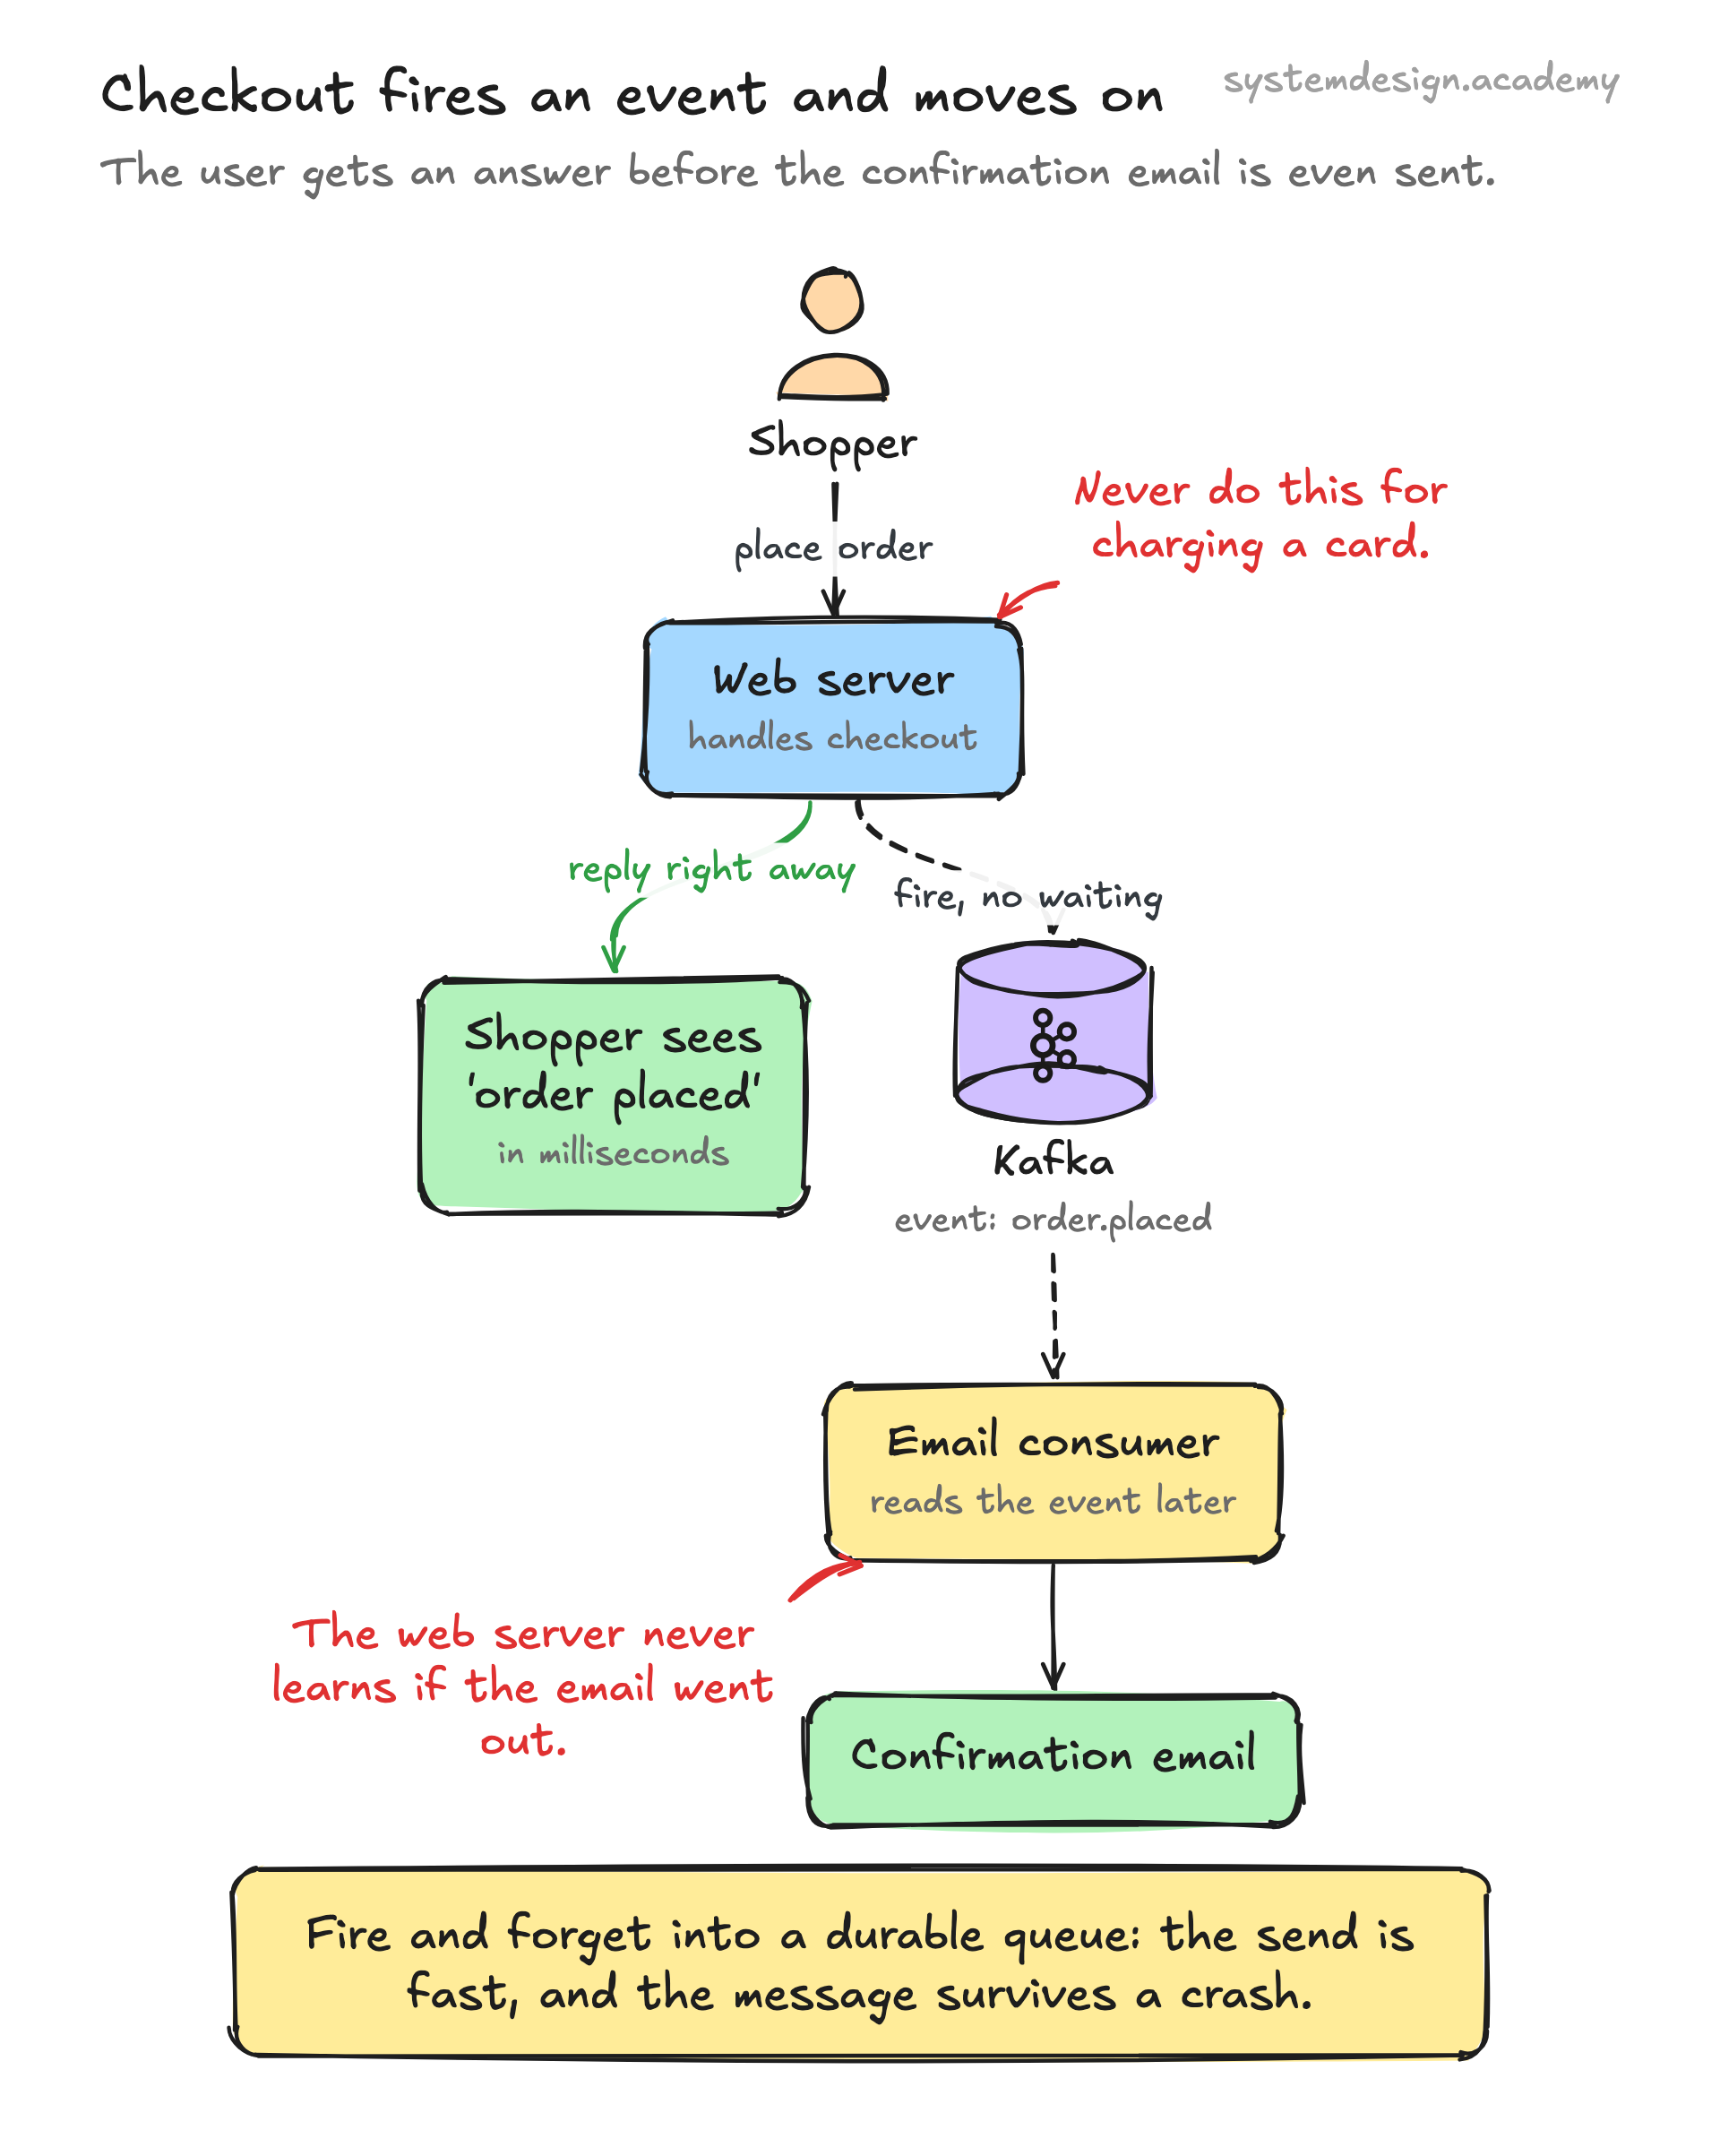
Reach for fire and forget when the message is not essential to the outcome the user is waiting on, and when an occasional loss does not break anything. Logging, metrics, page-view tracking, cache invalidation hints, and best-effort push notifications all fit. If your analytics drops 1 in 10,000 events, your dashboards are still useful.
Do not use it for anything that must happen exactly once or that the caller depends on, like charging a card, transferring money, or persisting an order. For those you need a request-reply pattern or at-least-once delivery with acknowledgements, retries, and idempotency keys so a retry does not double-charge.
The core trade-off is latency and decoupling versus reliability and observability. You get a snappy, loosely coupled system where the sender does not care if the receiver is down. You lose the ability to know if work completed, and debugging gets harder because failures are silent. Many teams split the difference: fire and forget into a durable queue, so the send is fast but the message survives a consumer crash and gets retried.