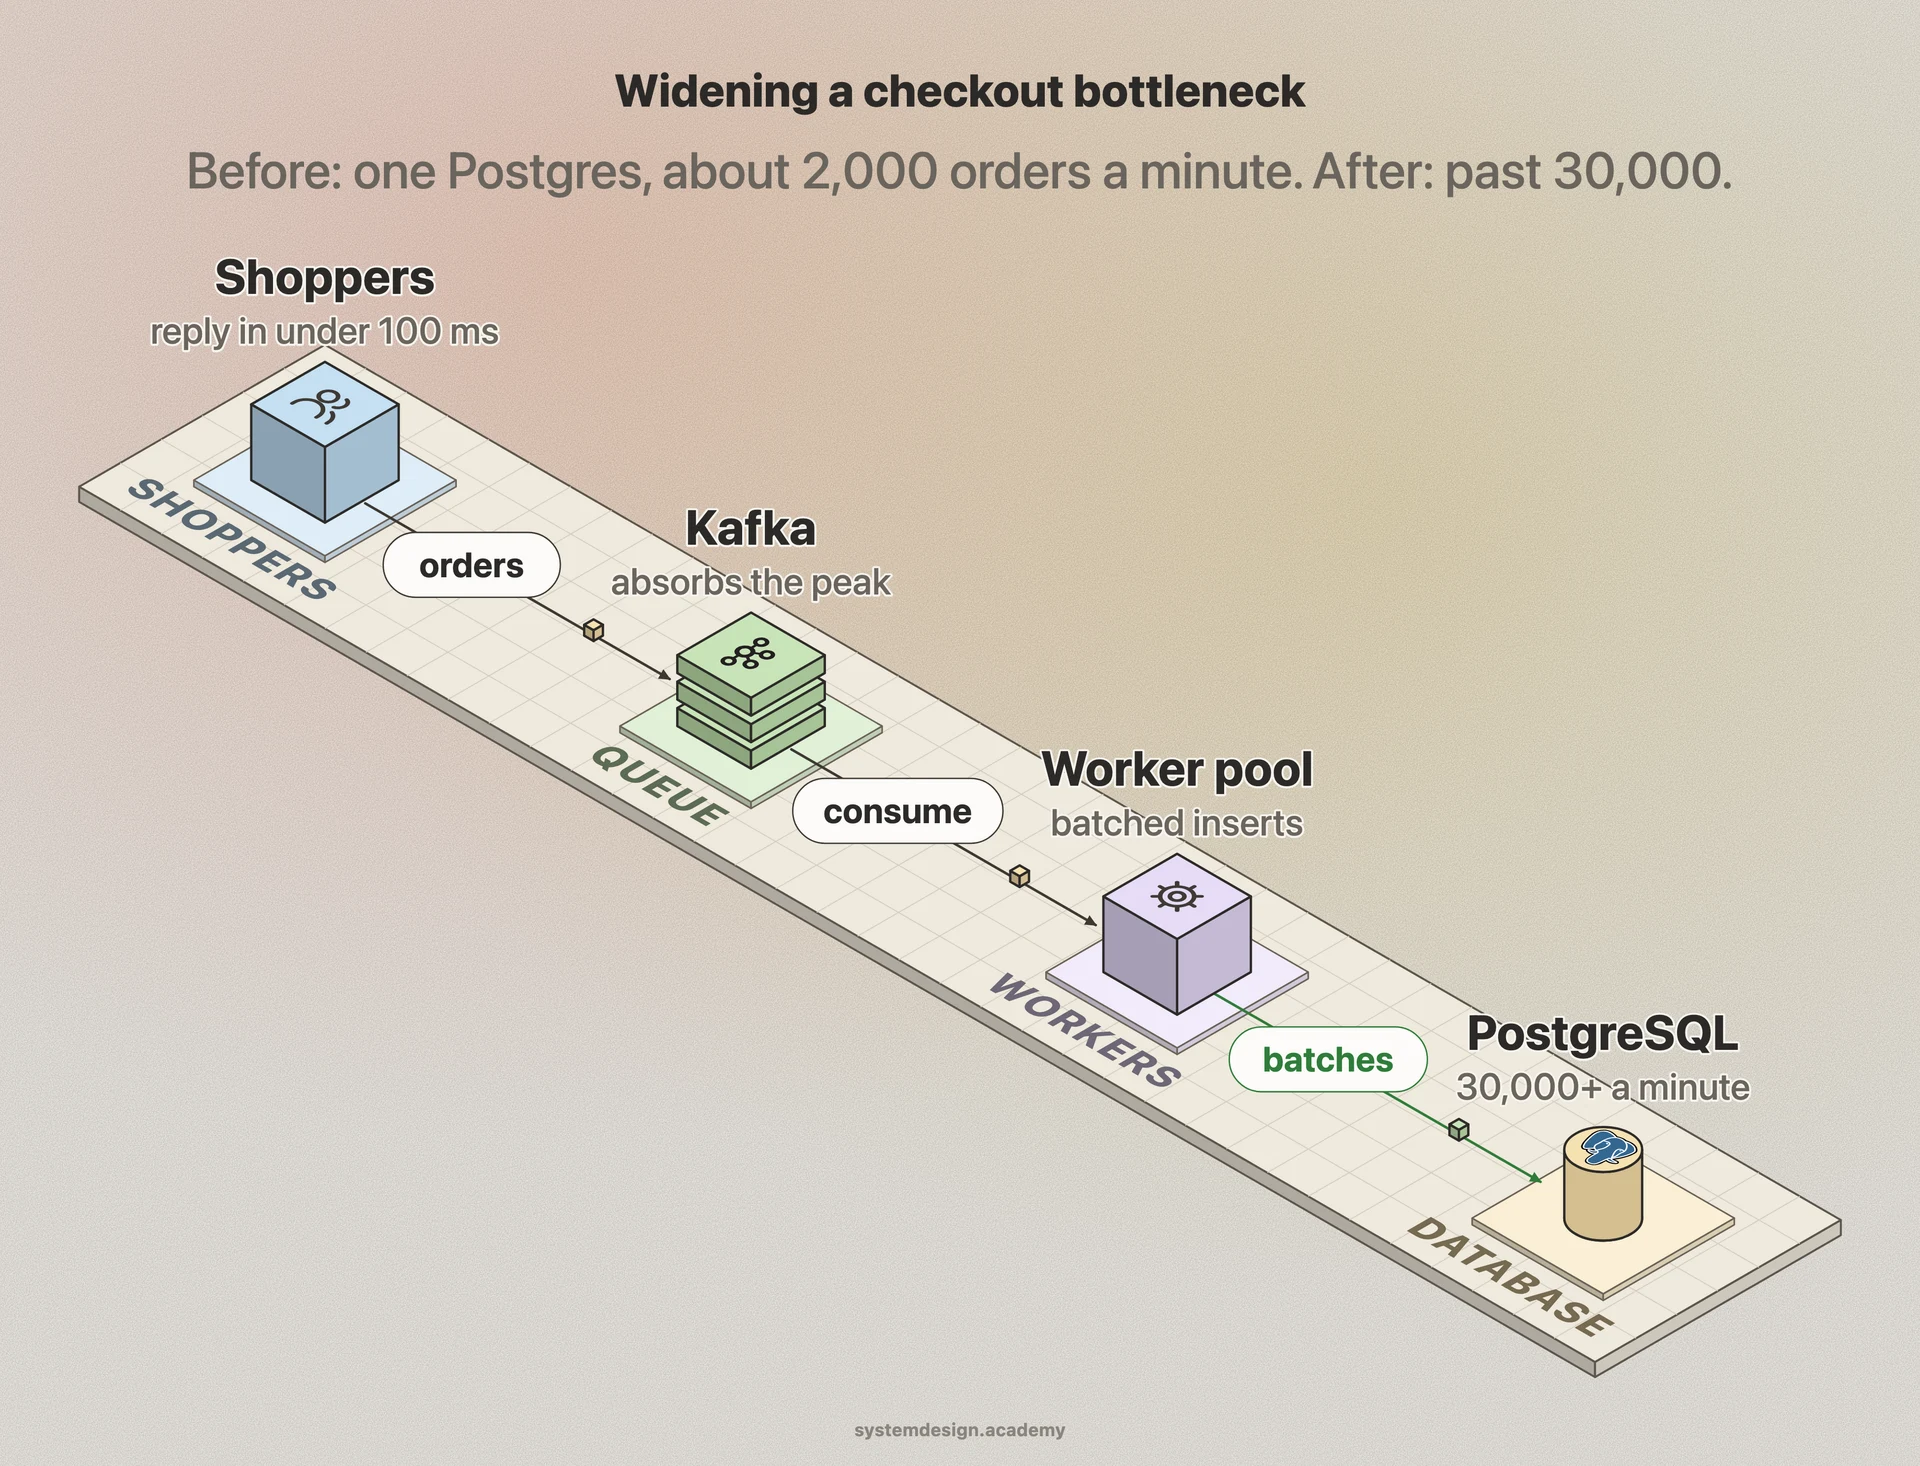
The first lever is concurrency. If one worker handles one request at a time and each takes 100 ms, that worker tops out near 10 RPS. Run 100 workers and you approach 1,000 RPS for the same per-request latency. This is why servers use thread pools, async event loops, and connection pools, and why you scale out by adding more machines behind a load balancer.
The second lever is batching. Writing 1,000 database rows one at a time pays the round-trip and commit cost 1,000 times. Sending them as a single batched insert pays it once and can lift write throughput by 10x or more. Kafka producers batch messages, databases group commits, and GPUs batch inference requests for the same reason.
Every system also has a bottleneck, the single slowest stage that caps the whole pipeline. If your app servers can handle 20,000 RPS but the database maxes out at 5,000 QPS, system throughput is 5,000, not 20,000. Raising throughput means finding and widening that bottleneck, often with caching, read replicas, sharding, or queues that absorb spikes.
Little's Law ties it together: the average number of requests in flight equals throughput multiplied by average latency. So at 1,000 RPS with 200 ms average latency, roughly 200 requests are being processed at any moment. This is why you cannot push throughput arbitrarily high without either more concurrency capacity or lower latency.