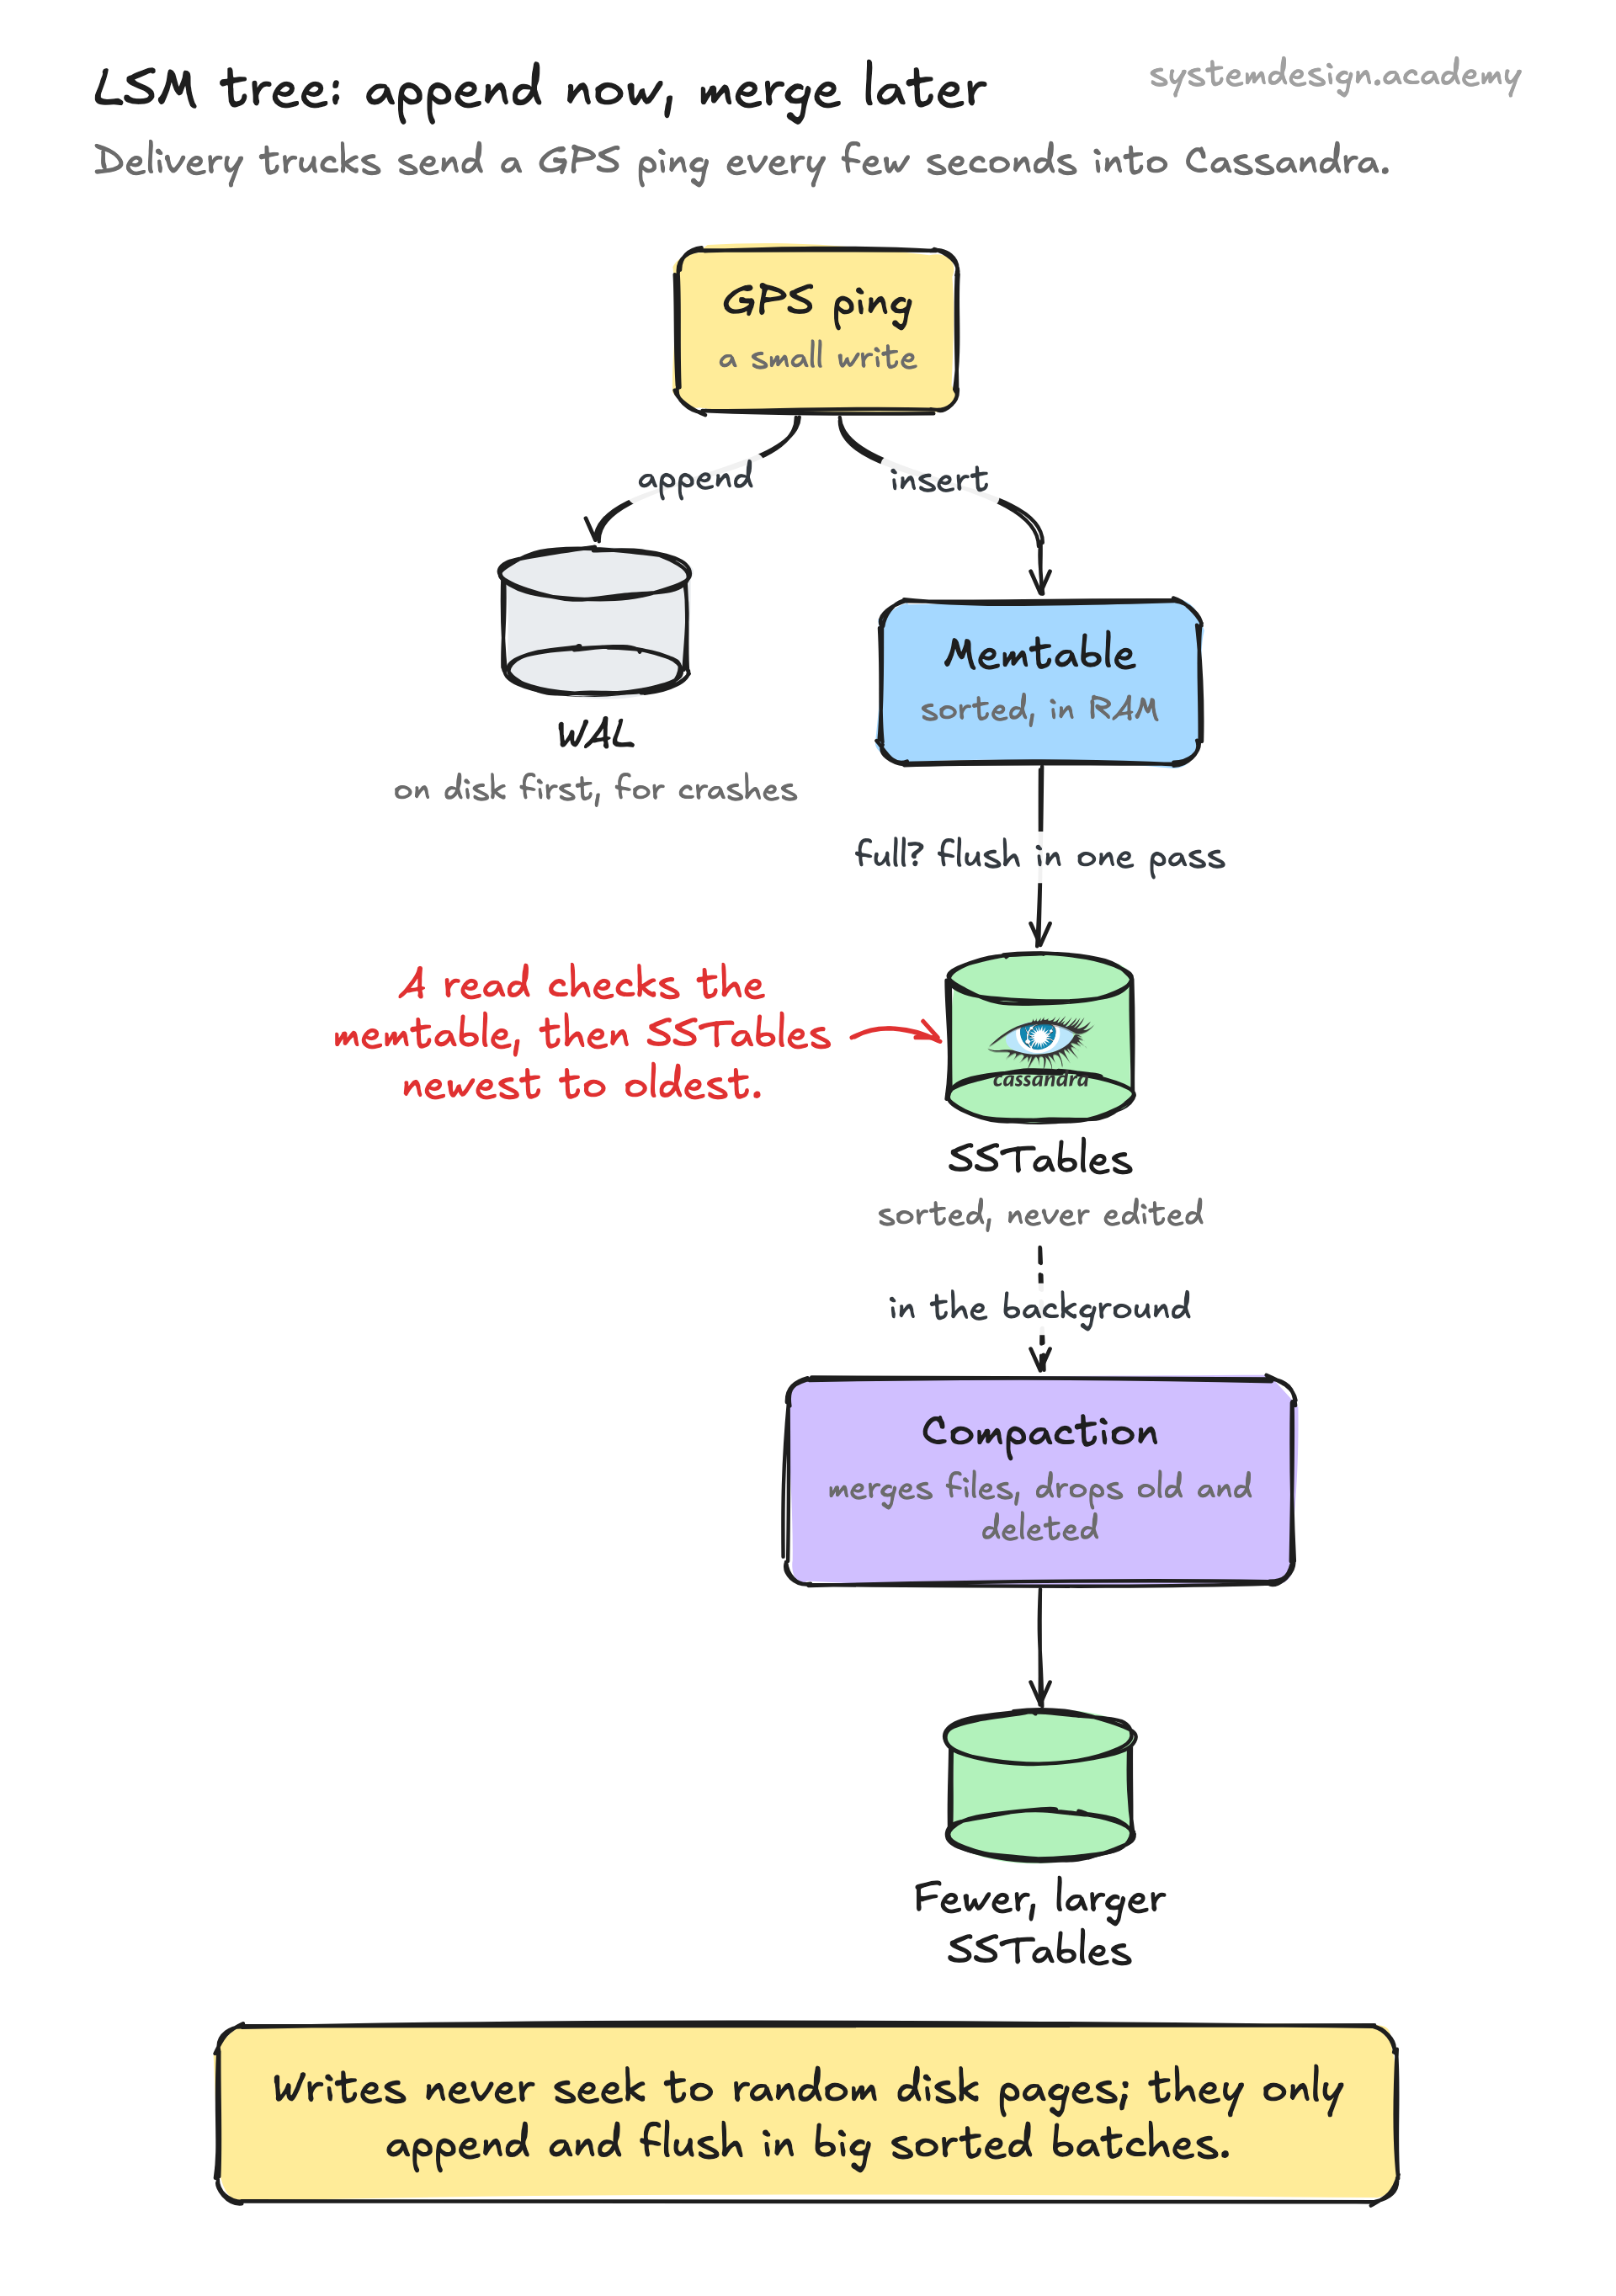
Every write goes to the WAL and the memtable at the same time. The memtable keeps keys sorted as they arrive, so reads of recently written data are served straight from RAM. When the memtable fills up, typically at 64 to 256 MB, it is frozen and written to disk as a single new SSTable in one sequential pass.
Over time you accumulate many SSTables. Reads now have to check the memtable, then each SSTable from newest to oldest, because a newer file may hold an updated value or a tombstone marking a deletion. Two structures keep this cheap. A bloom filter per SSTable answers definitely not here without touching disk, and a sparse index per file points reads near the right offset.
Compaction is the background job that keeps things from sprawling. It merges several SSTables into fewer, larger sorted files, drops overwritten and deleted entries, and deletes the old files. Two common strategies are size-tiered, which merges files of similar size and is used by Cassandra by default, and leveled, which keeps non-overlapping key ranges per level and is the default in RocksDB and LevelDB.