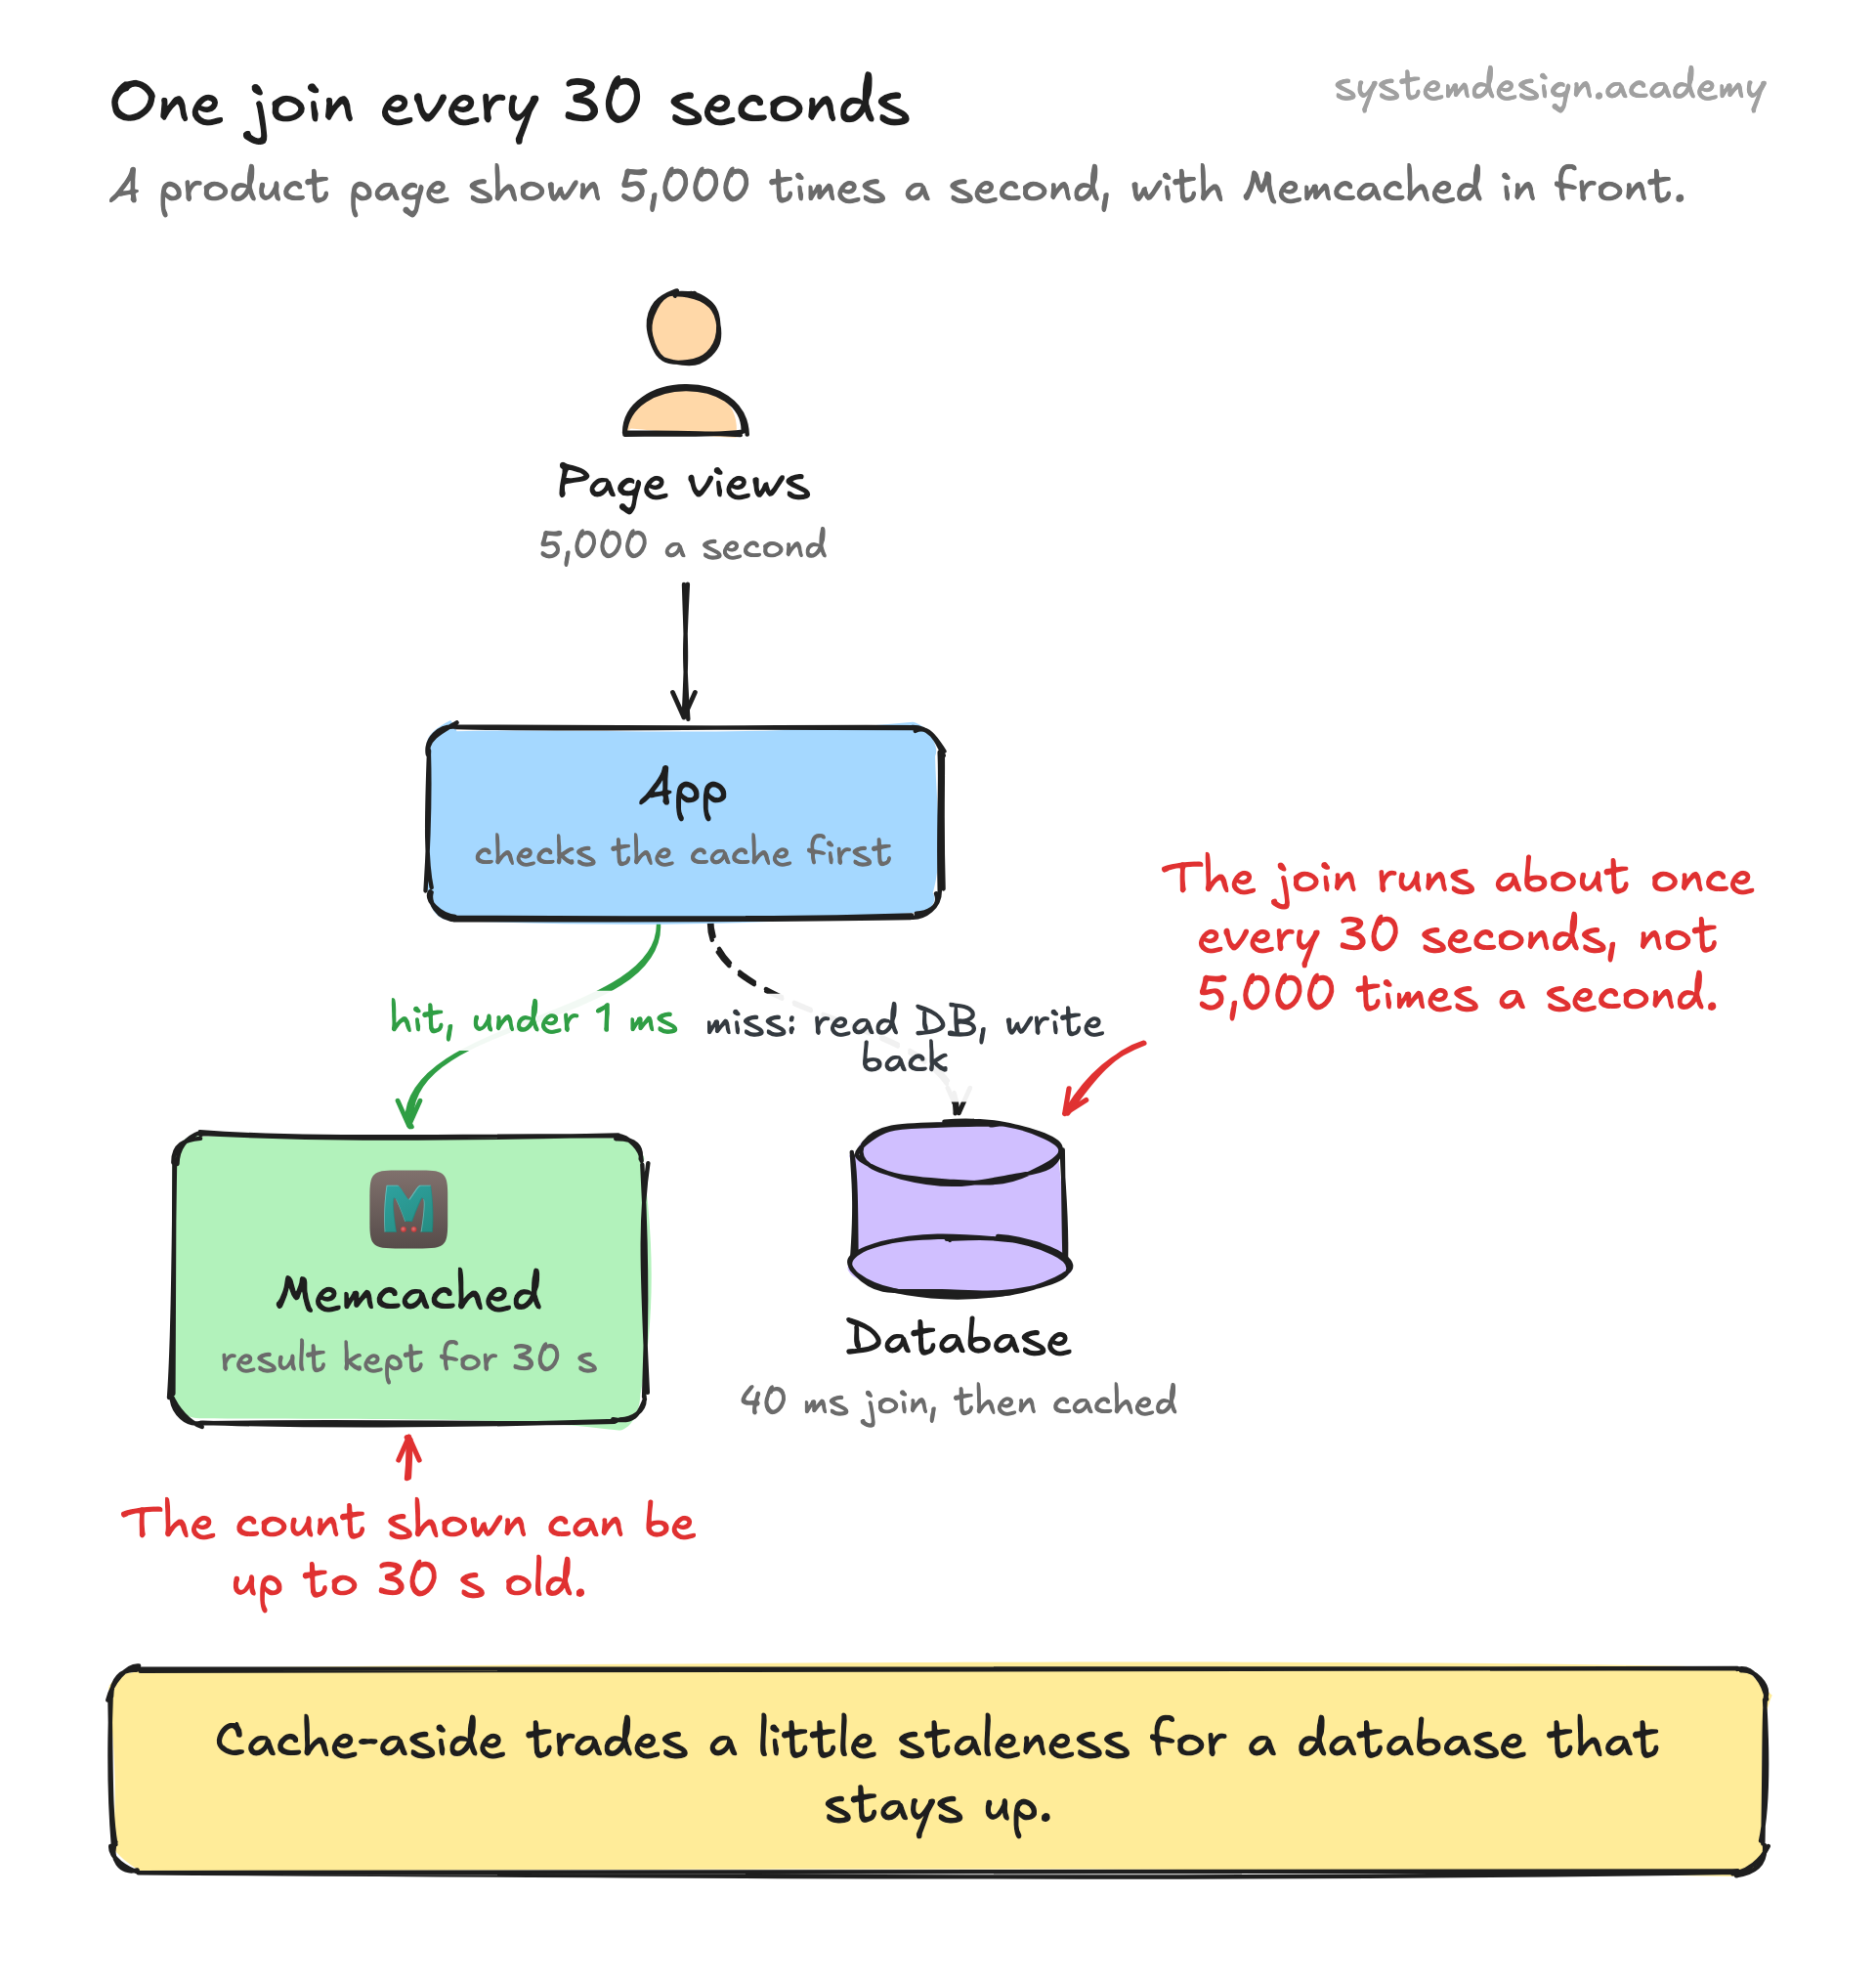
Reach for Memcached when you have a read-heavy workload and a clear set of values that are expensive to compute but cheap to store as flat blobs: database query results, fully rendered HTML fragments, API responses, or login session objects. The classic pattern is cache-aside, where the app checks Memcached first, and on a miss reads the database, then writes the result back into the cache with a short expiry.
Its strength is also its limitation. Because it is just a flat key-value store, there are no lists, sets, sorted sets, counters with atomic guarantees beyond increment, pub/sub, or persistence. If your data vanishes when a node restarts, that has to be fine, because everything is volatile. Memcached is purely a cache, never a source of truth.
The honest comparison is with Redis. Redis has richer data structures, optional persistence, replication, and clustering built in, which is why many new projects start there. Memcached still wins in narrow cases: it is genuinely multithreaded so one large instance uses many cores well, its slab allocator can have lower memory overhead for large numbers of small uniform values, and its smaller feature surface means fewer ways to misuse it. Pick Memcached when you want a dumb, fast, horizontally scalable blob cache and nothing more.