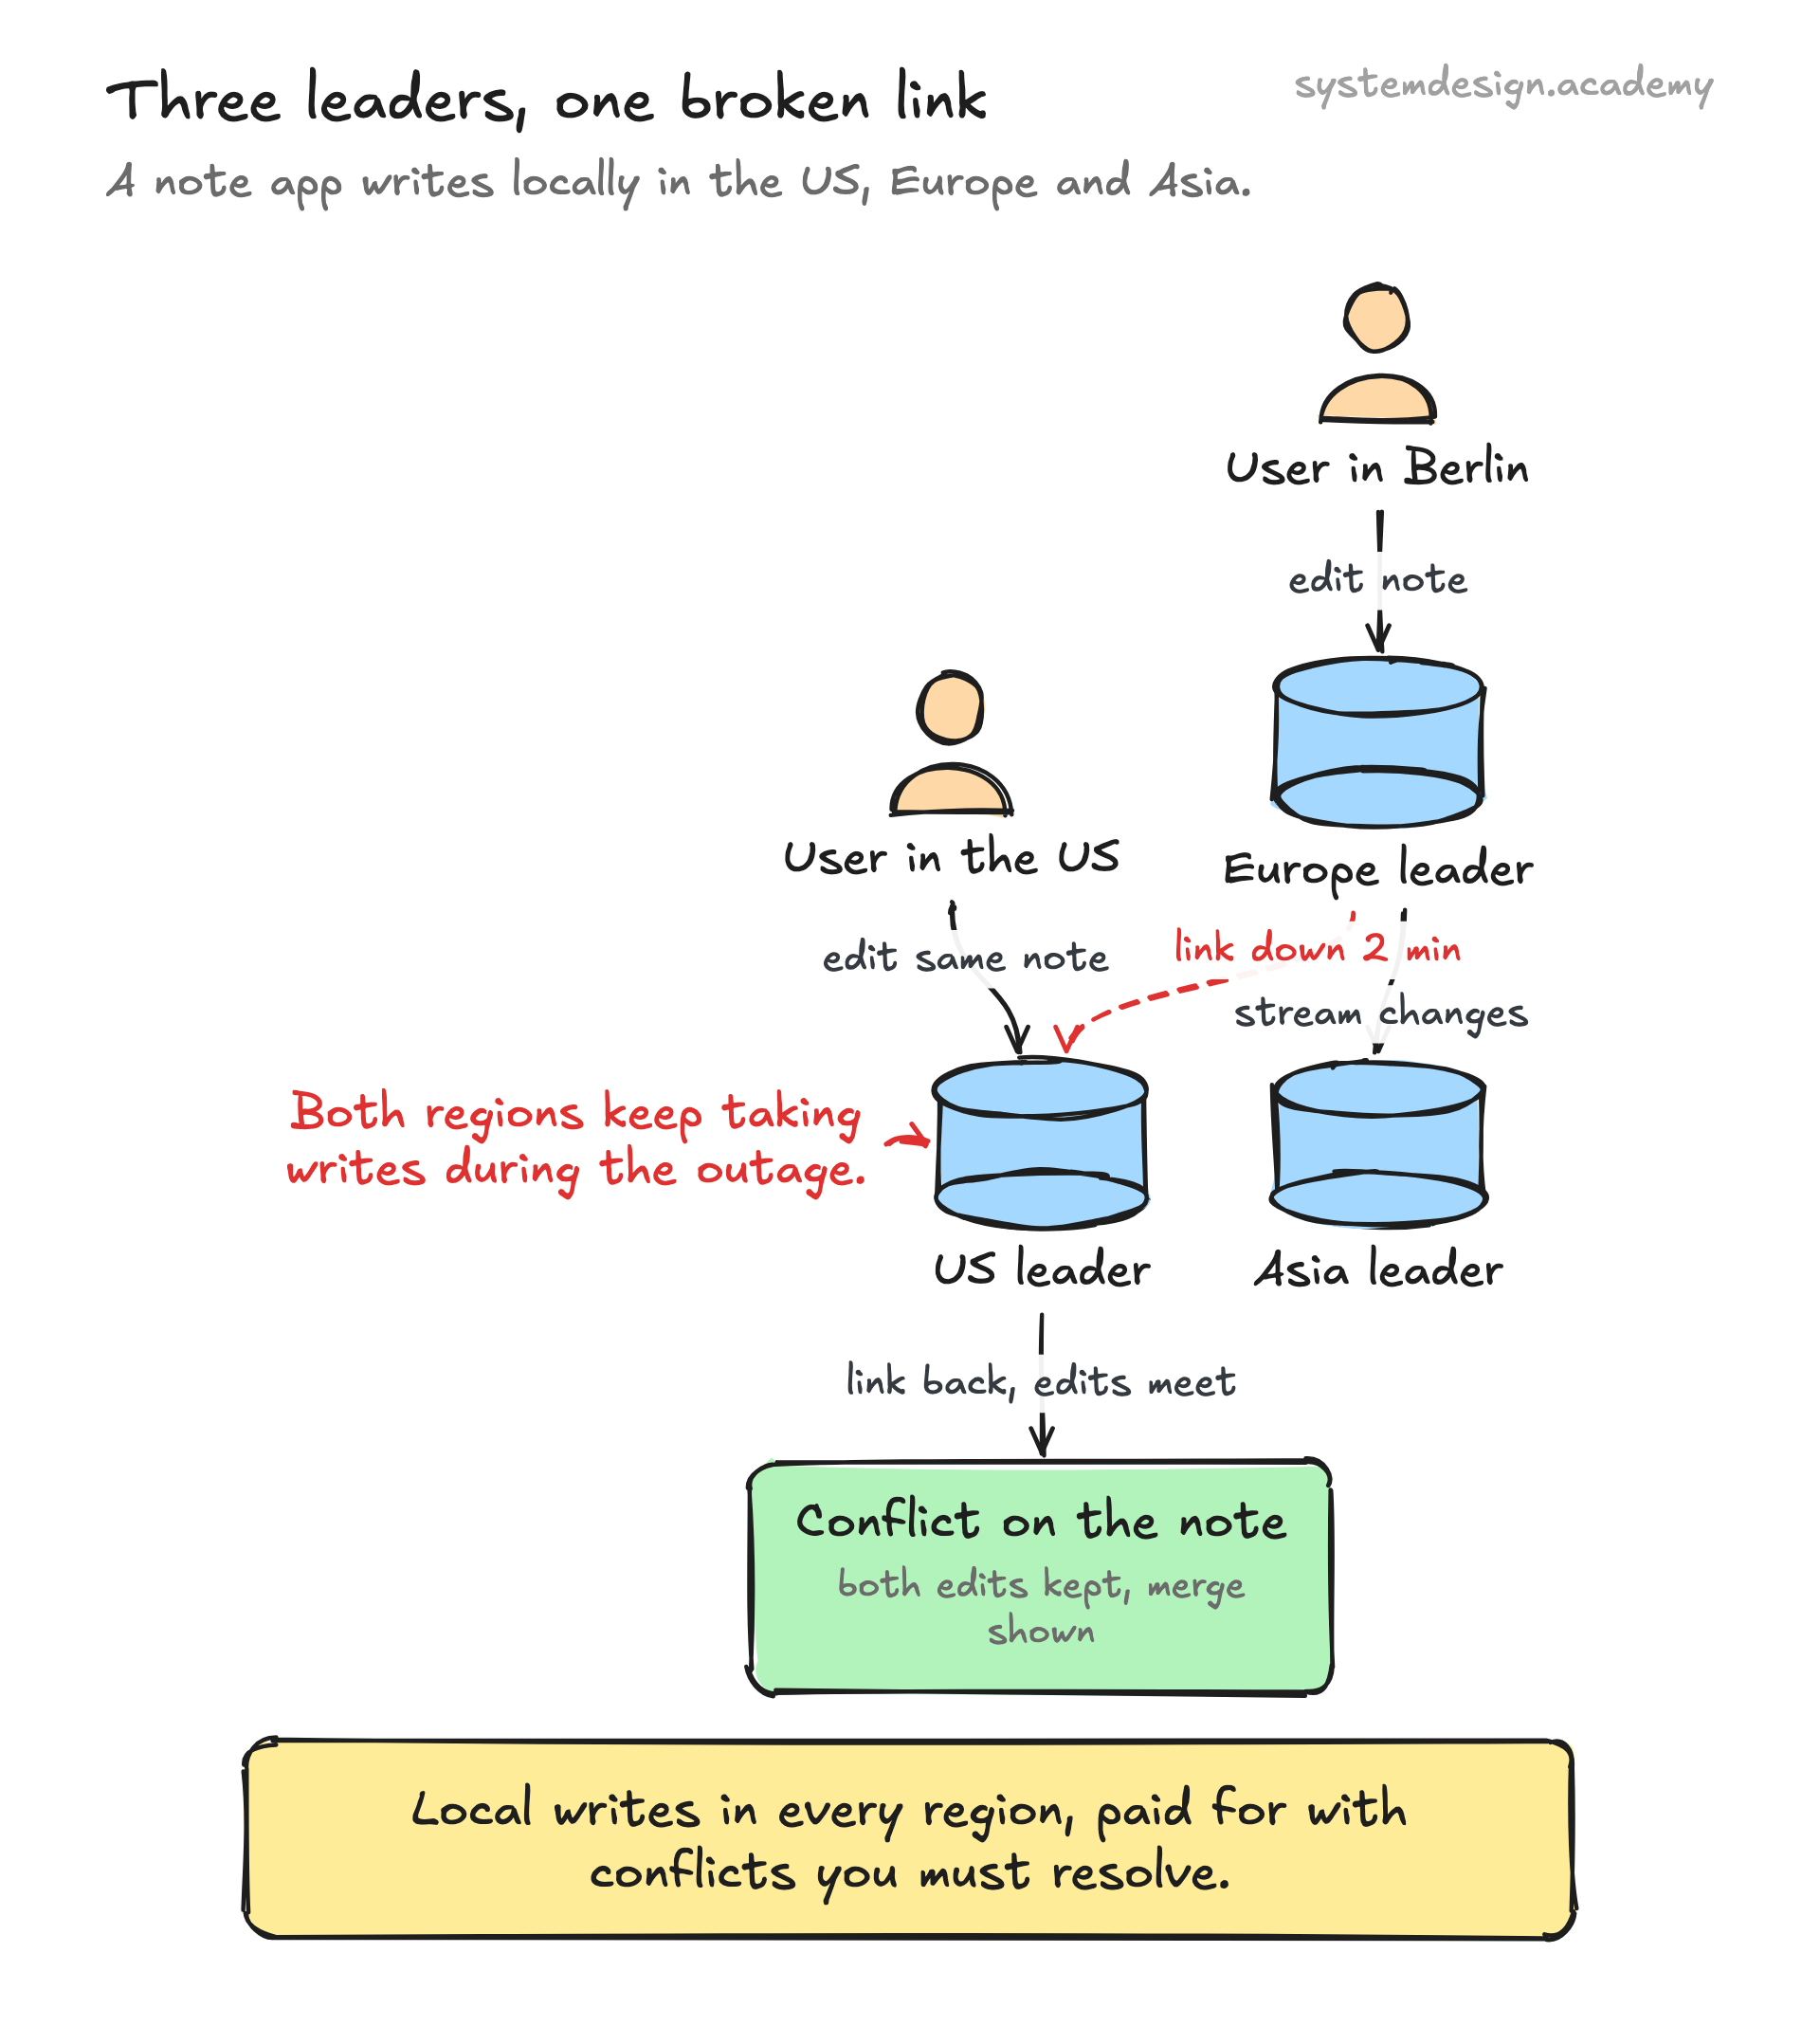
Each leader writes to its own local storage first and acks the client immediately. In the background, it ships its change log (a replication stream) to the other leaders. This is almost always asynchronous, so the regions are eventually consistent, not strongly consistent.
To stop changes from looping forever, every write carries an origin identifier, and a leader ignores any incoming change that originated from itself. Topologies vary: all-to-all (every leader talks to every other leader), circular (A to B to C to A), and star (one hub relays to the rest). All-to-all tolerates a single node failure better, but circular and star topologies can stall completely if one link breaks.
Conflict resolution is the hard part and you have to choose a strategy. Last-write-wins picks the change with the highest timestamp and silently drops the other, which is simple but loses data. Better options include keeping both versions and letting the application or user pick, merging the values (for example, union two shopping carts), or using conflict-free replicated data types (CRDTs) that are designed to merge deterministically. Riak, for instance, exposes siblings so the application can resolve them.