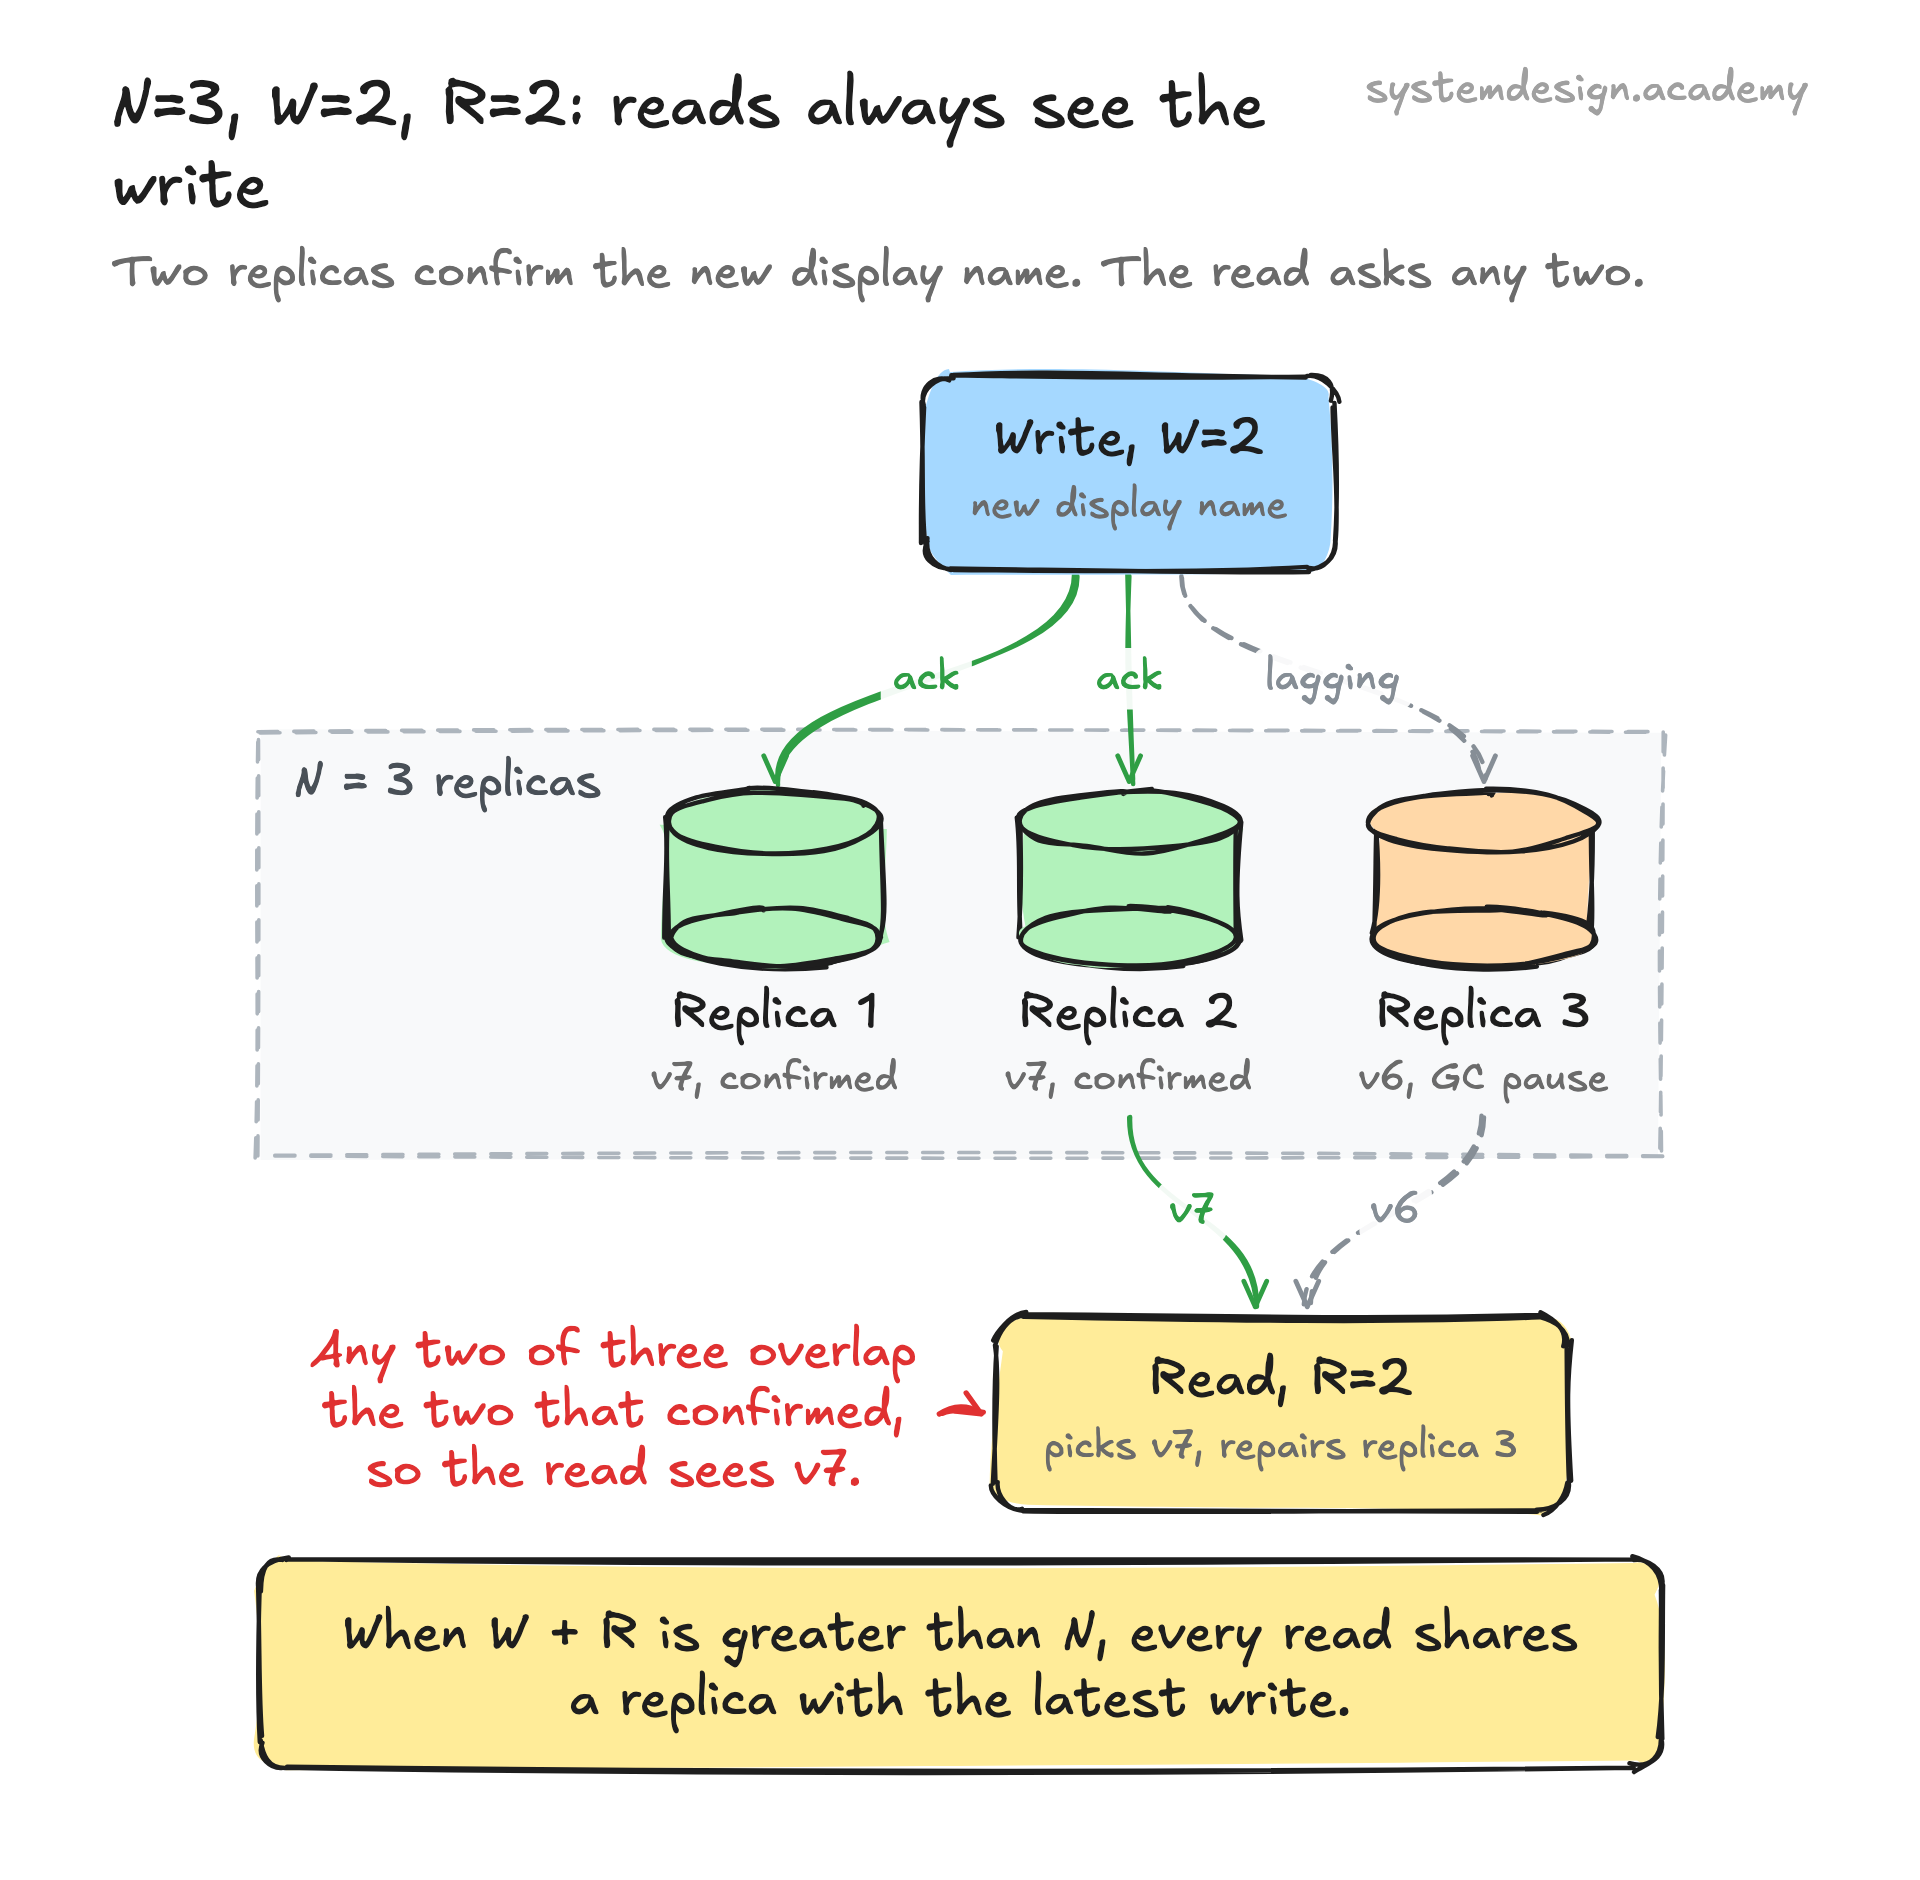
On a write, a coordinator node sends the new value to all N replicas in parallel but only waits for W acknowledgements. Each value is tagged with a version, usually a logical timestamp or a vector clock, so replicas and readers can tell which copy is newer. Once W replicas confirm, the write returns success even if the remaining replicas have not applied it yet.
On a read, the coordinator queries R replicas and compares their versions. If they disagree, it returns the newest one and often triggers read repair, quietly pushing the fresh value back to the stale replicas so they catch up.
Tuning W and R lets you slide along a spectrum. W=N, R=1 makes reads fast and writes strict. W=1, R=N flips it. W=2, R=2 with N=3 balances both. You can also break the overlap rule on purpose: W=1, R=1 gives very fast eventual consistency where a read might miss a recent write, which some workloads accept.