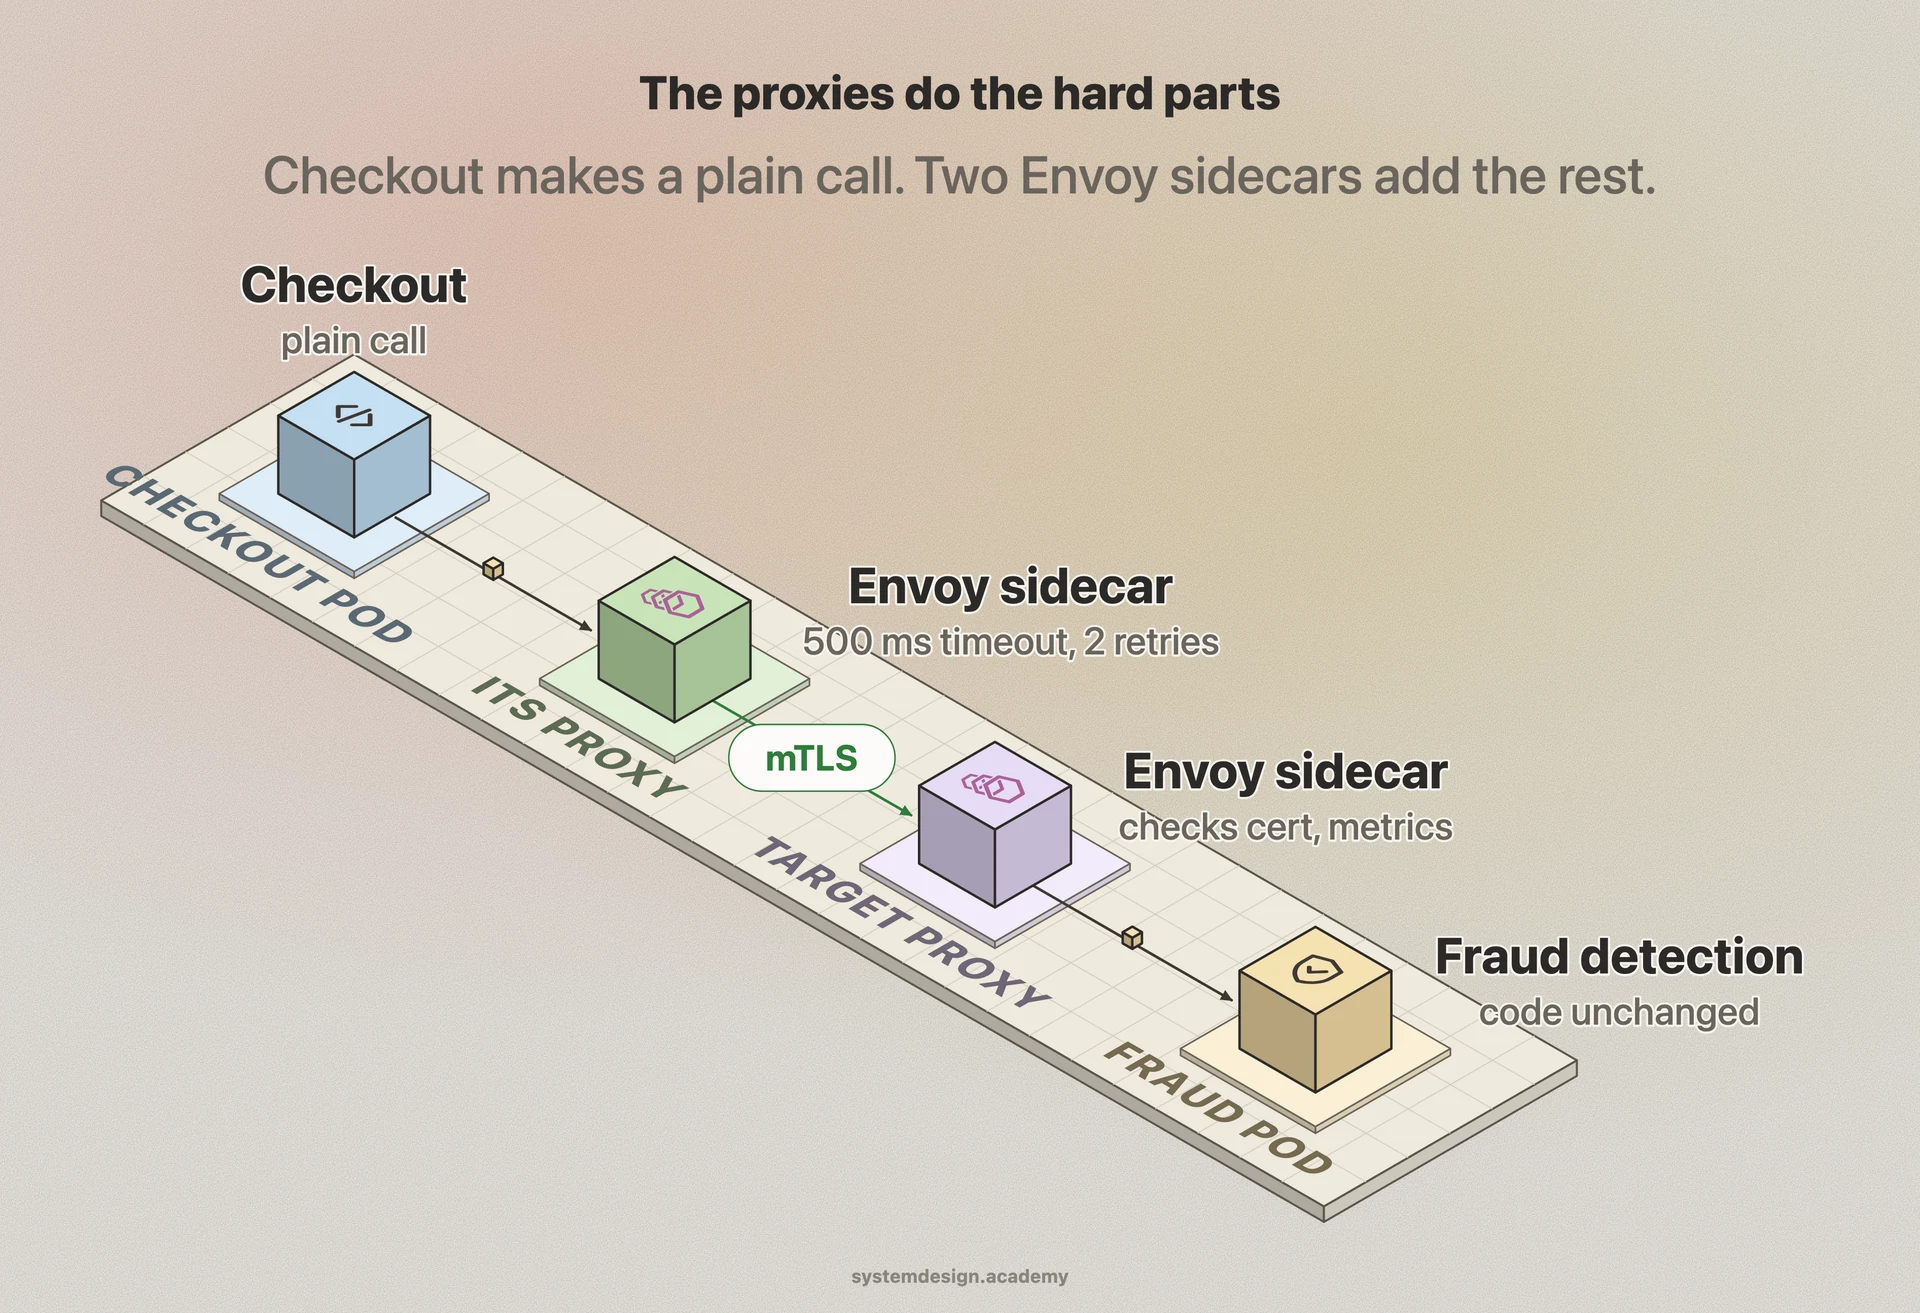
A service mesh earns its keep when you have many services, multiple teams, and real requirements around zero-trust security, traffic control, and observability. If you need mutual TLS between every service for compliance, or you want to do canary deployments by shifting 5 percent of traffic to a new version, the mesh gives you that with configuration instead of code.
The cost is real. Every request now passes through two extra proxies, which adds latency, often around 1 to 3 milliseconds per hop, and consumes CPU and memory across the cluster. The control plane is another distributed system you have to run, upgrade, and debug, and mesh failures can be confusing because the problem lives in the network layer, not your code.
For a handful of services, a service mesh is usually overkill. A simpler API gateway, a client-side library, or built-in Kubernetes networking will do the job with far less operational weight. Teams often adopt a mesh only after they have felt the pain of inconsistent retries, missing metrics, or unencrypted internal traffic across a large fleet.