There are two common ways to turn a shard key value into a shard. Range-based sharding sorts the key and assigns contiguous ranges to shards. For example user_ids 1 to 1,000,000 go to shard A, 1,000,001 to 2,000,000 go to shard B. This makes range scans efficient but tends to send all the newest inserts to the last shard.
Hash-based sharding runs the key through a hash function and uses the result to pick a shard. A hashed user_id scatters records across all shards evenly, which kills hot spots on writes, but it destroys ordering so range scans now have to touch every shard.
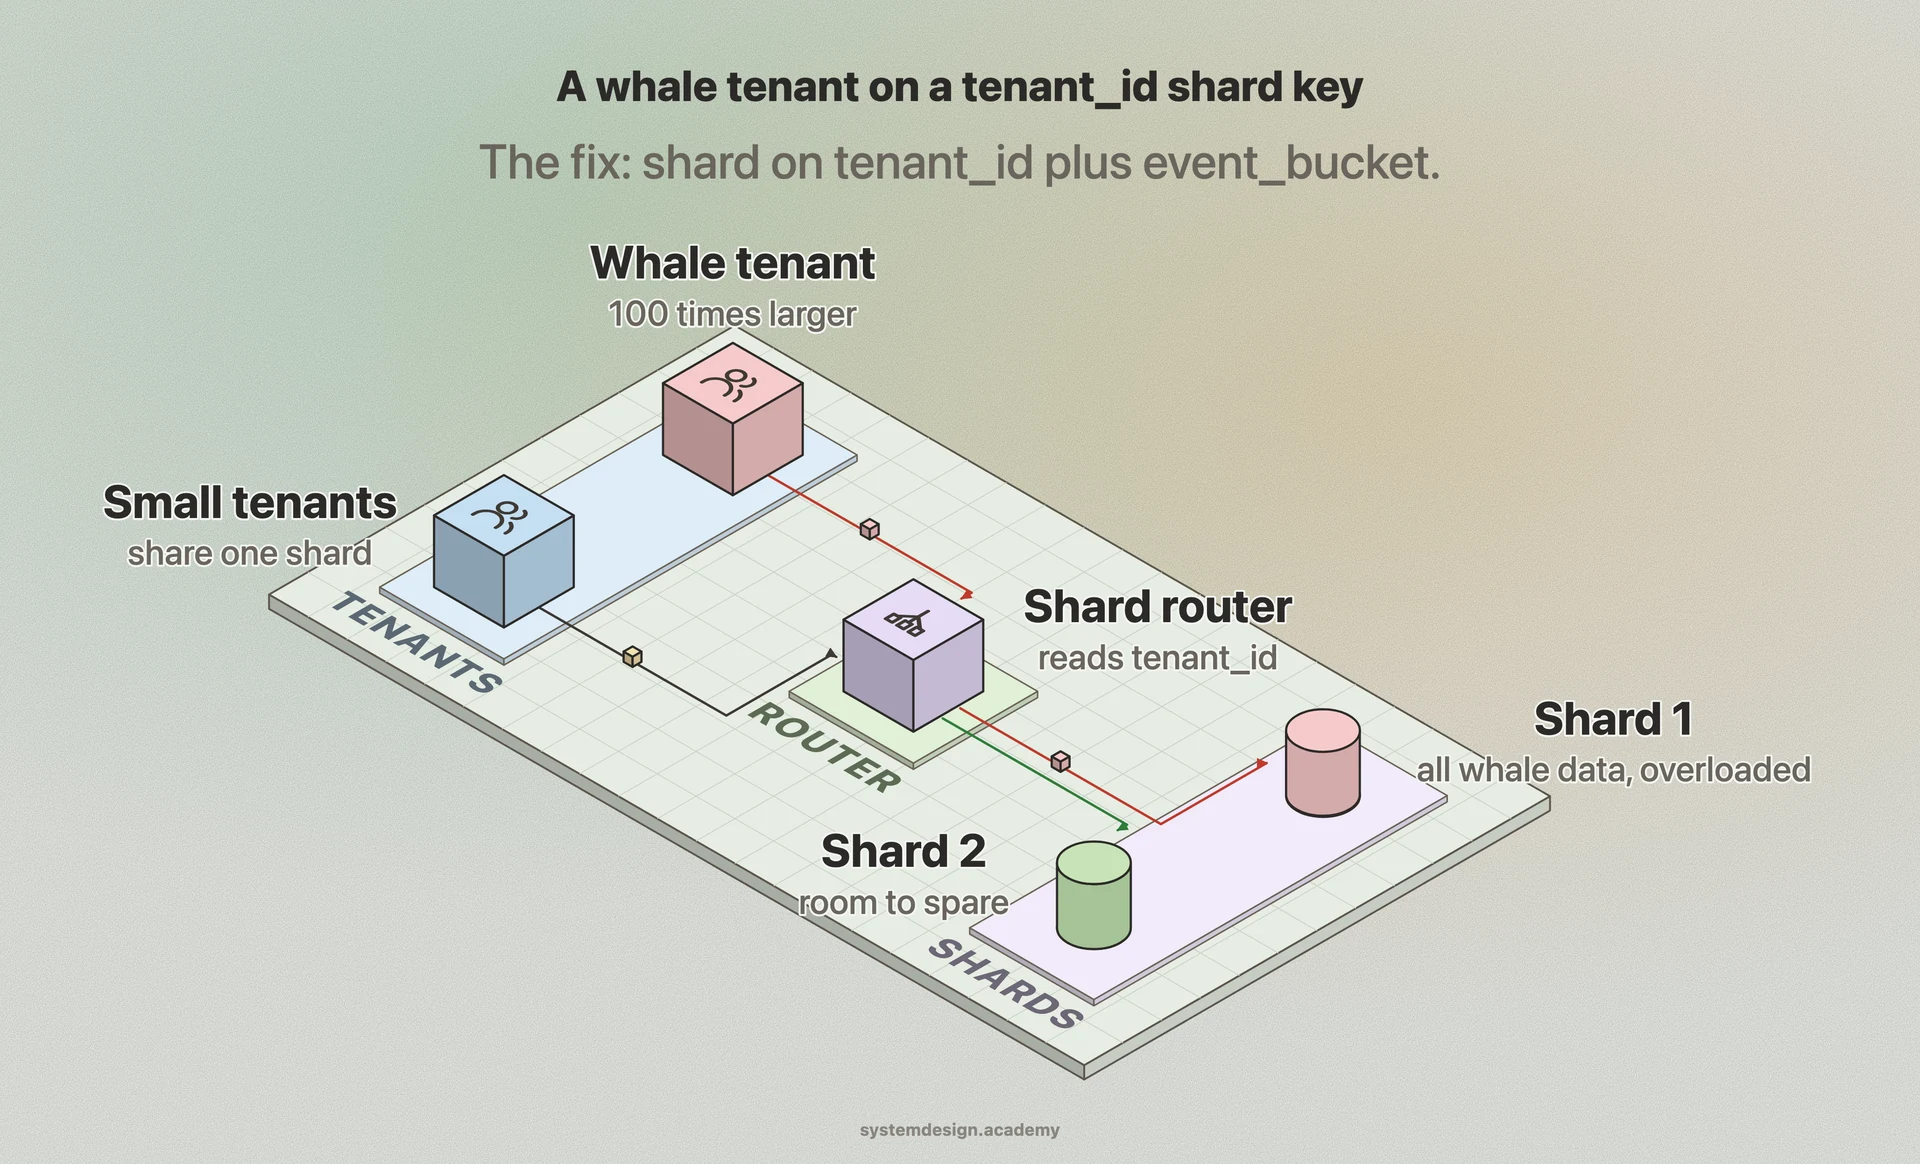
Many systems add a layer of consistent hashing or a lookup table so they can add or remove shards without rehashing every record. MongoDB keeps a config server that maps key ranges (chunks) to shards. Vitess and Citus keep similar routing metadata. The application usually does not pick the shard itself; a router or proxy reads the shard key off the query and forwards it.
The hard rule is that the shard key has to be present in the query for the router to find the data in one hop. A query that filters only on email when the shard key is user_id cannot be routed, so it fans out to every shard and waits for all of them. That scatter-gather query is slow and scales badly.