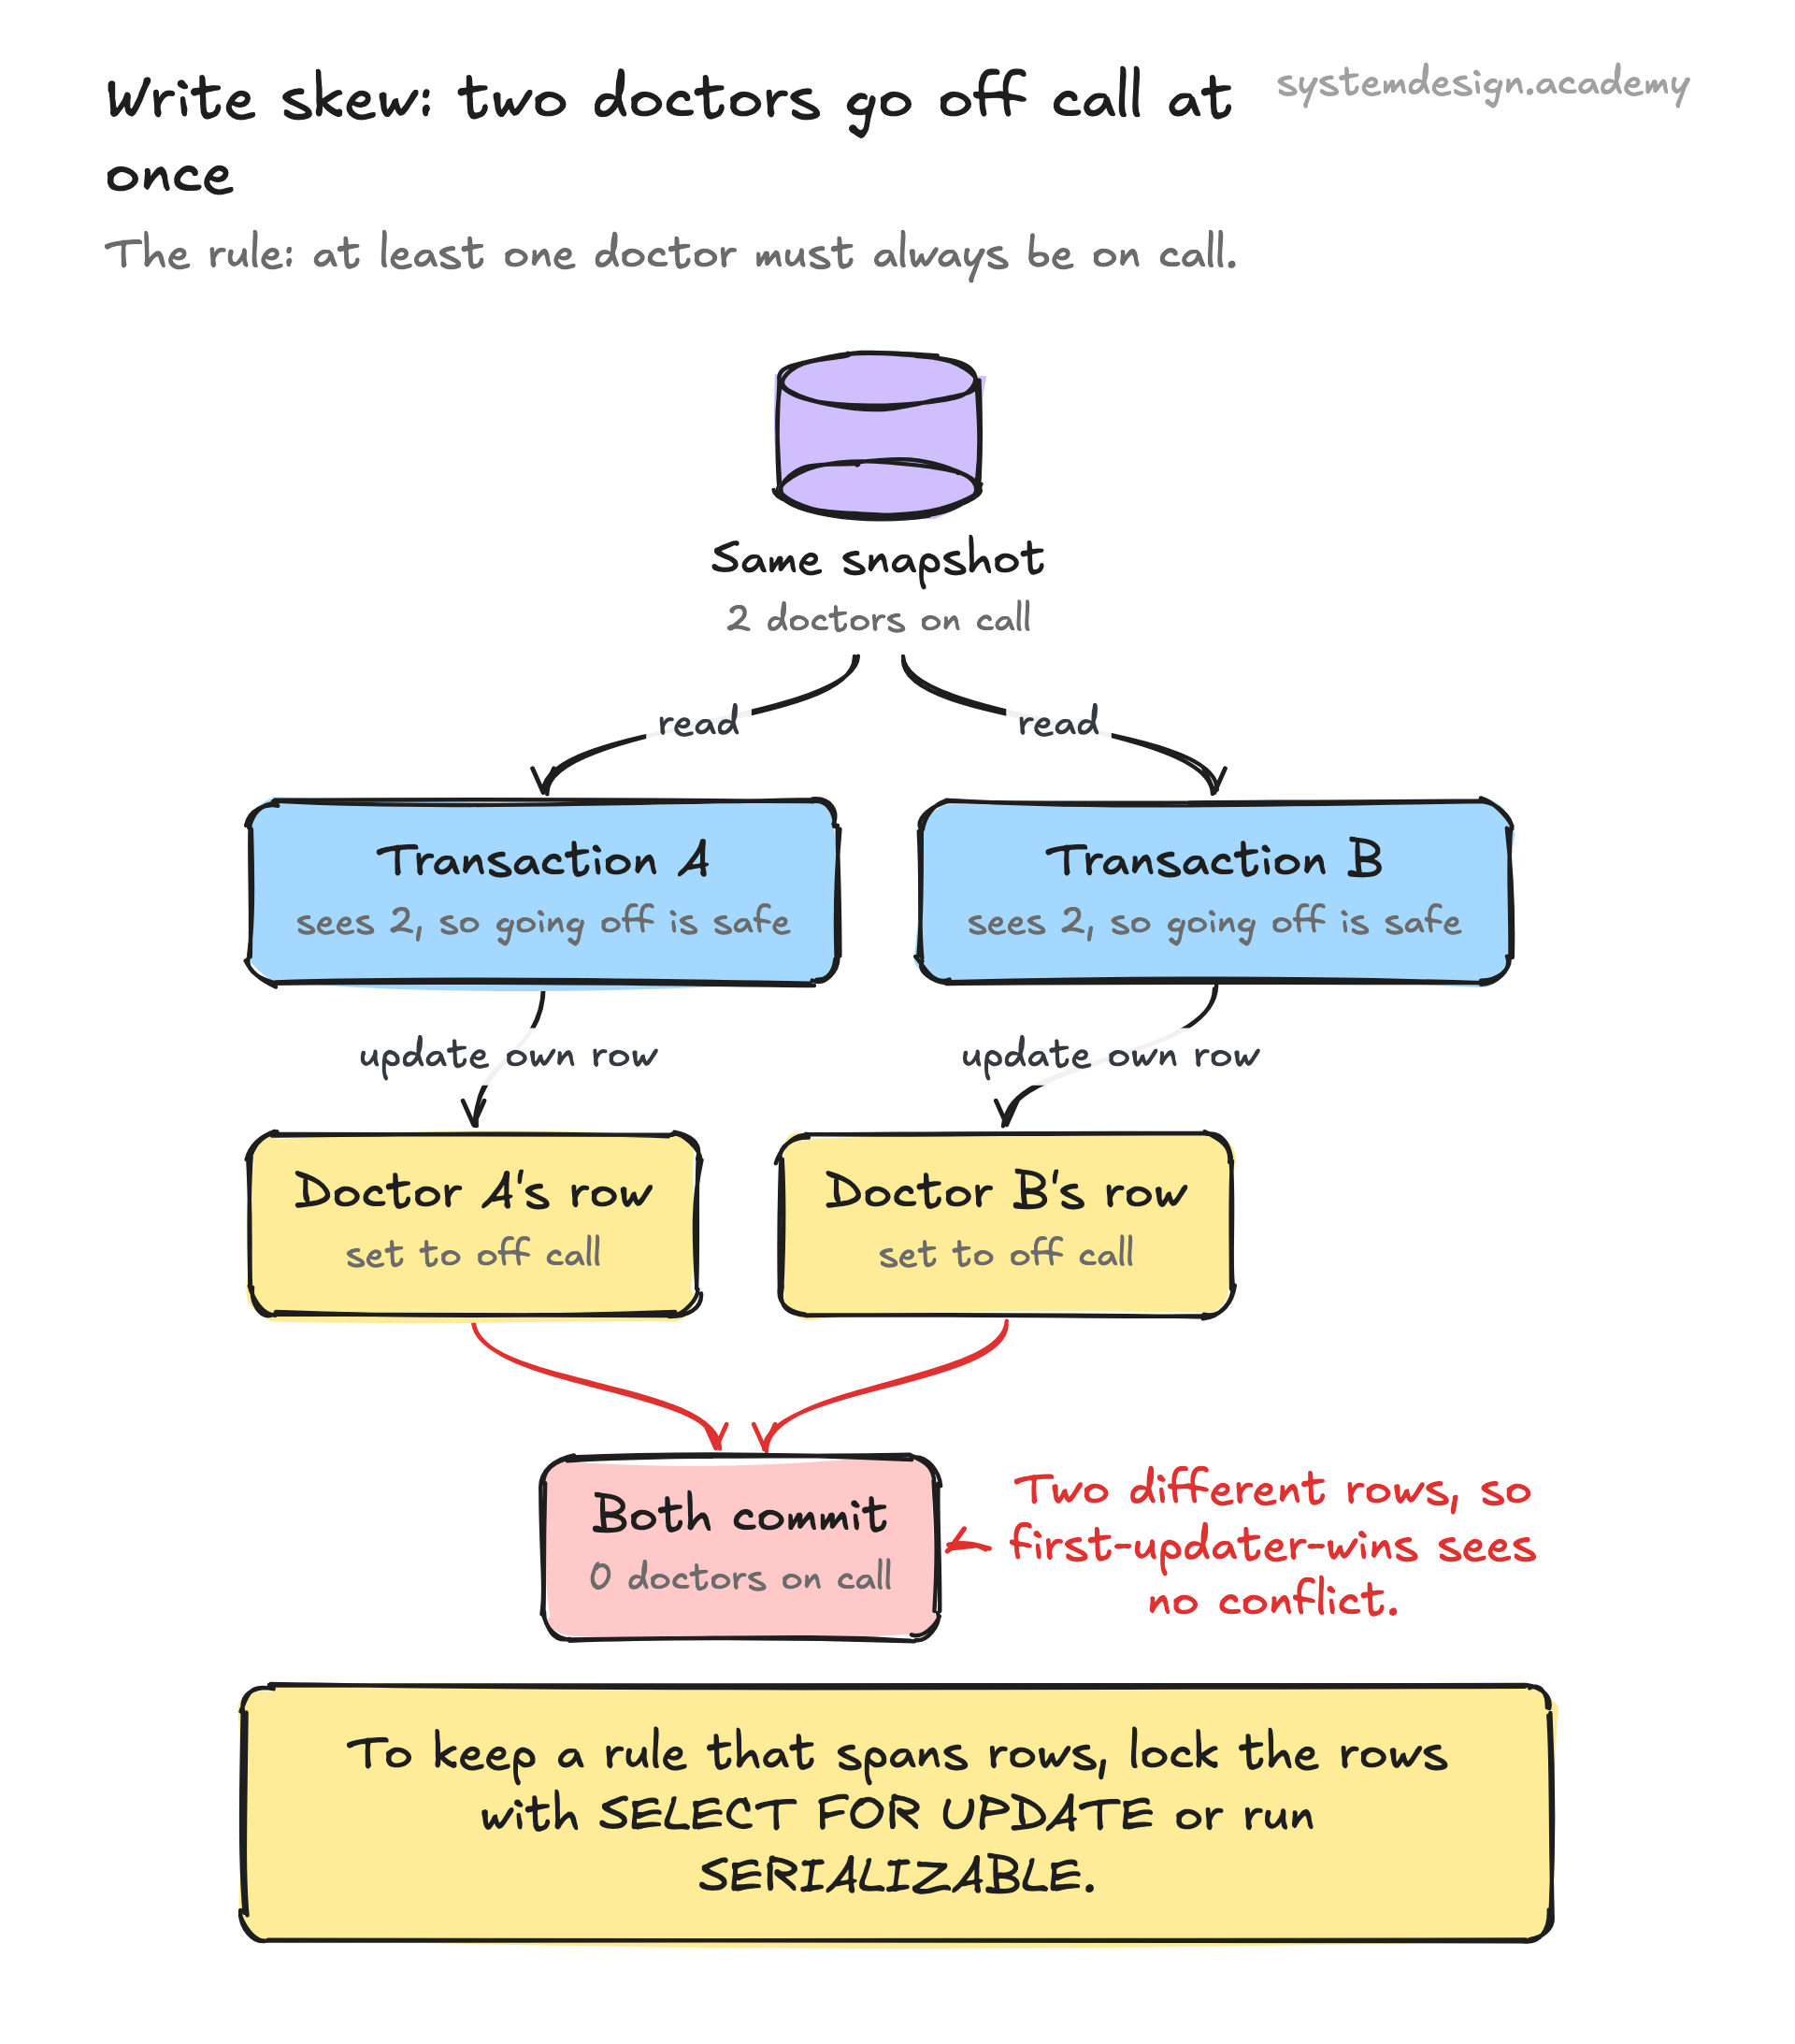
Snapshot isolation gives each transaction its own private, unchanging view of the database. The moment a transaction starts, the system records a logical point in time, and from then on every read returns the data as it looked at that instant. If five other transactions commit while yours is running, you do not see any of their changes. Your snapshot is yours alone.
This solves the most common read anomalies. You never see uncommitted data from another transaction (no dirty reads). If you read the same row twice, you get the same value both times (no non-repeatable reads). A range query run twice returns the same rows (no phantom reads under most implementations). Readers and writers never block each other, which is the headline benefit.
The catch is that snapshot isolation is weaker than serializability. Two transactions can each read the same snapshot, make decisions based on rows the other is about to change, and both commit. The classic failure is write skew: each transaction reads a shared constraint, sees it satisfied, and writes a different row, and together they violate the constraint that neither alone broke.