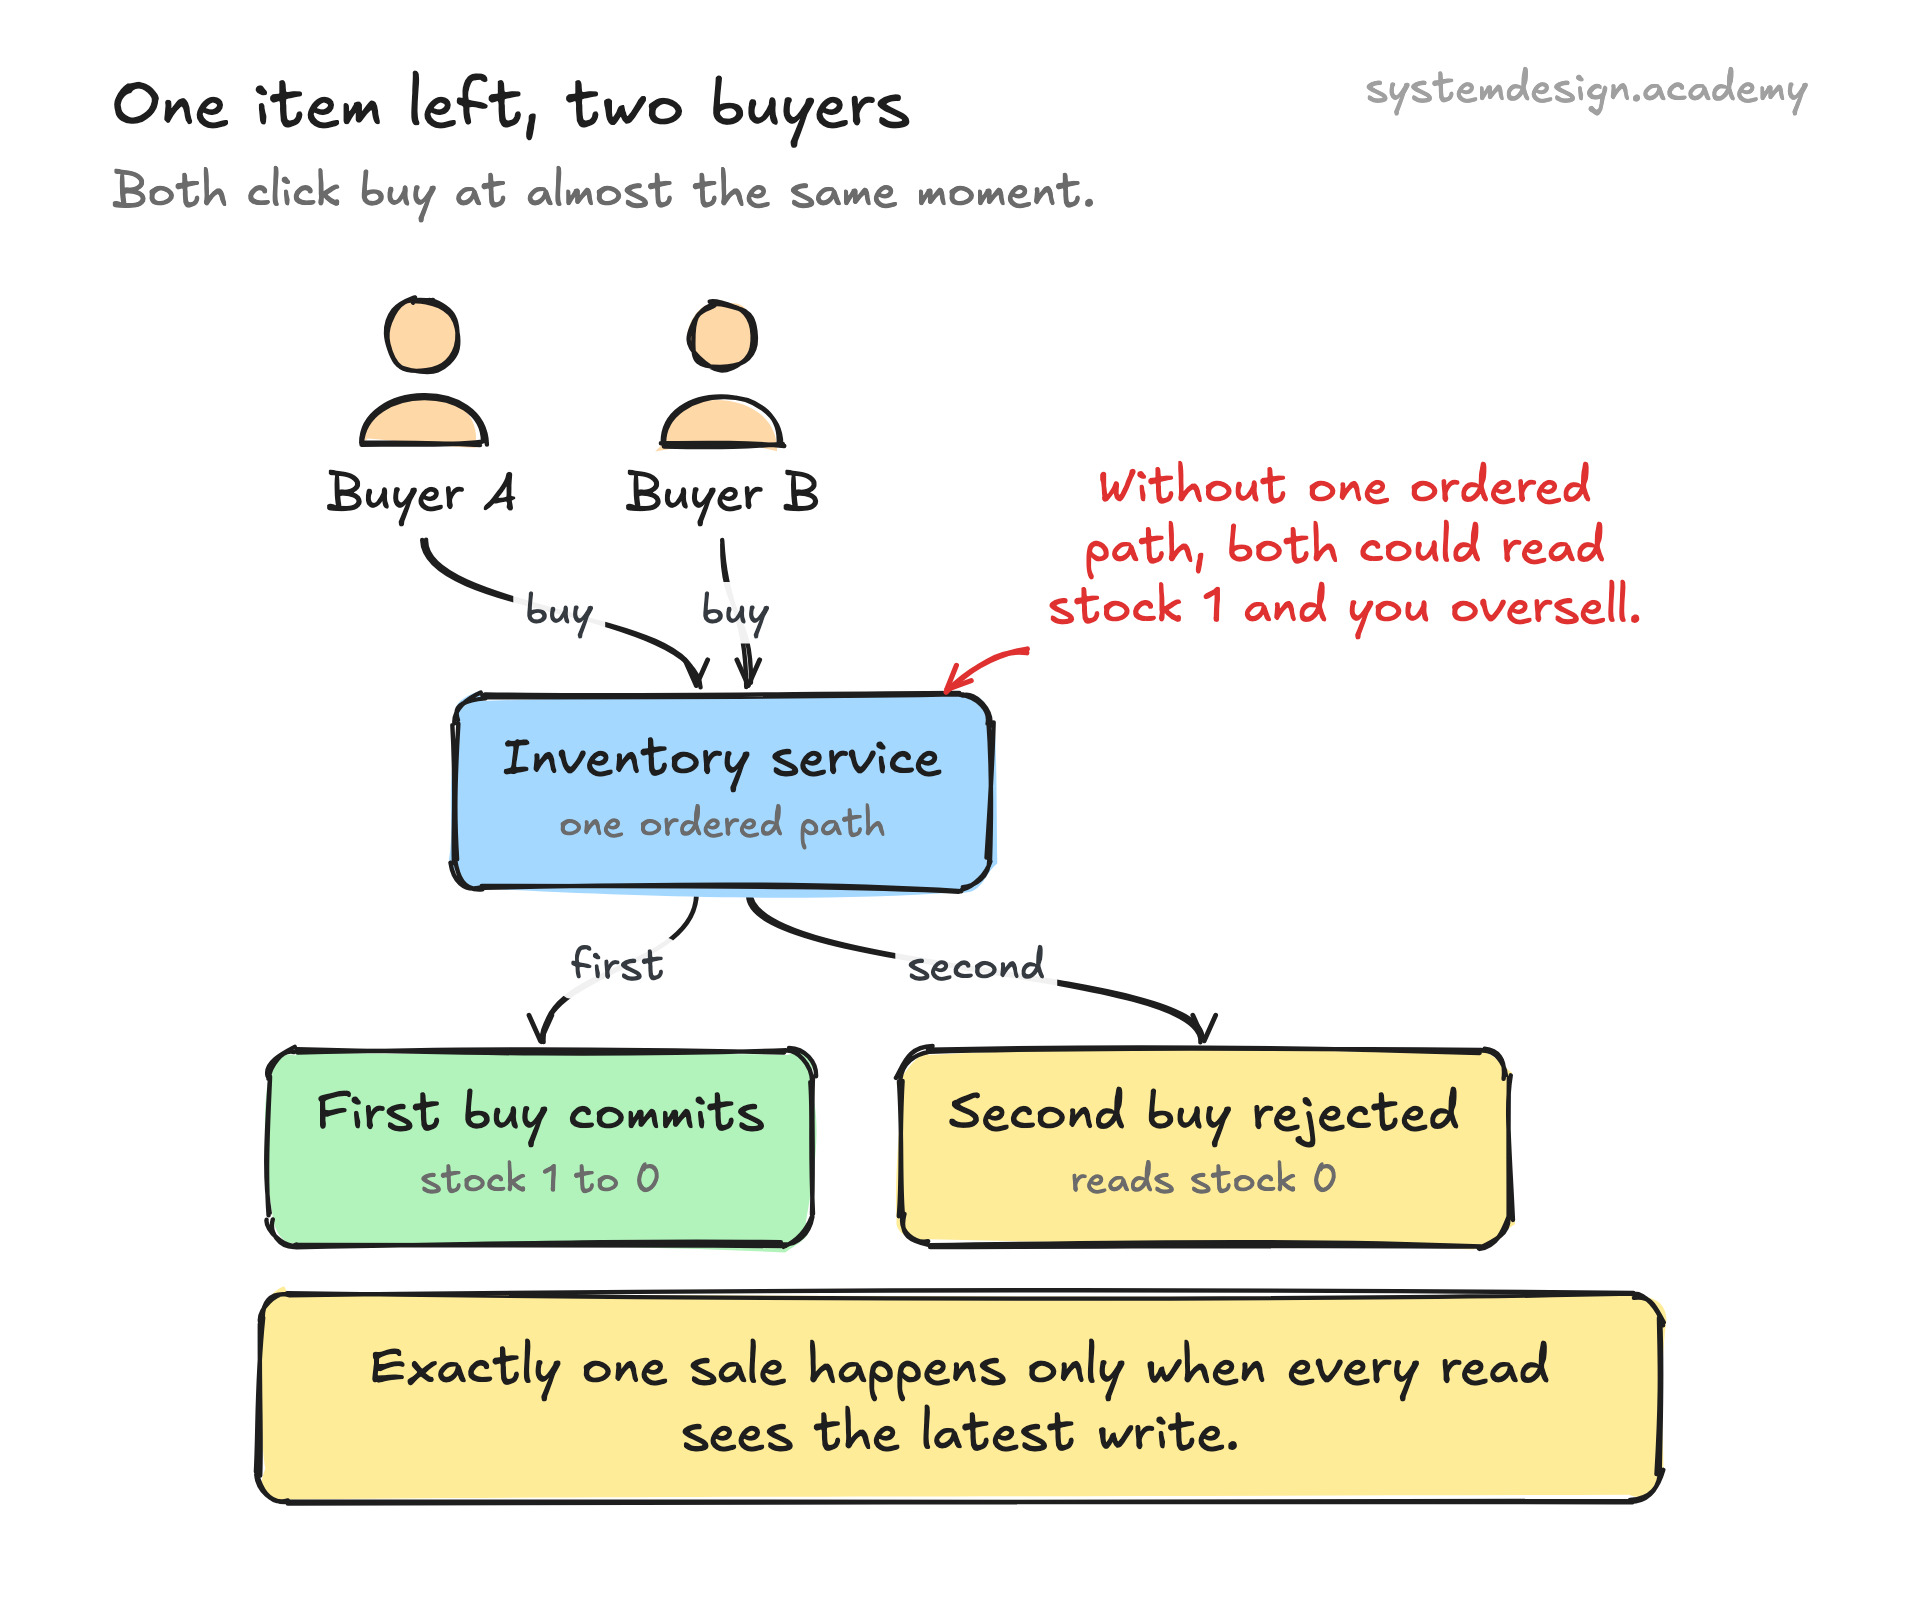
Reach for strong consistency when a stale read is a correctness bug, not a cosmetic glitch. Bank balances, inventory counts, payment idempotency, unique username registration, distributed locks, and leader election all break badly if two nodes disagree about the truth. A double-spend or a negative inventory count is far worse than a few extra milliseconds of latency.
The cost is real. Every write pays for coordination, so throughput drops and tail latency rises, especially across regions where a quorum round trip can be 100 milliseconds or more. The CAP theorem says that during a partition you must give up either consistency or availability, and strong consistency chooses to stay consistent and reject requests it cannot safely serve.
Many large systems split the difference. They keep strongly consistent stores for money and identity, and push high-volume, low-stakes data such as view counts, feeds, or recommendation caches into eventually consistent stores. The skill is deciding which data truly needs the guarantee, because applying it everywhere makes the whole system slow.