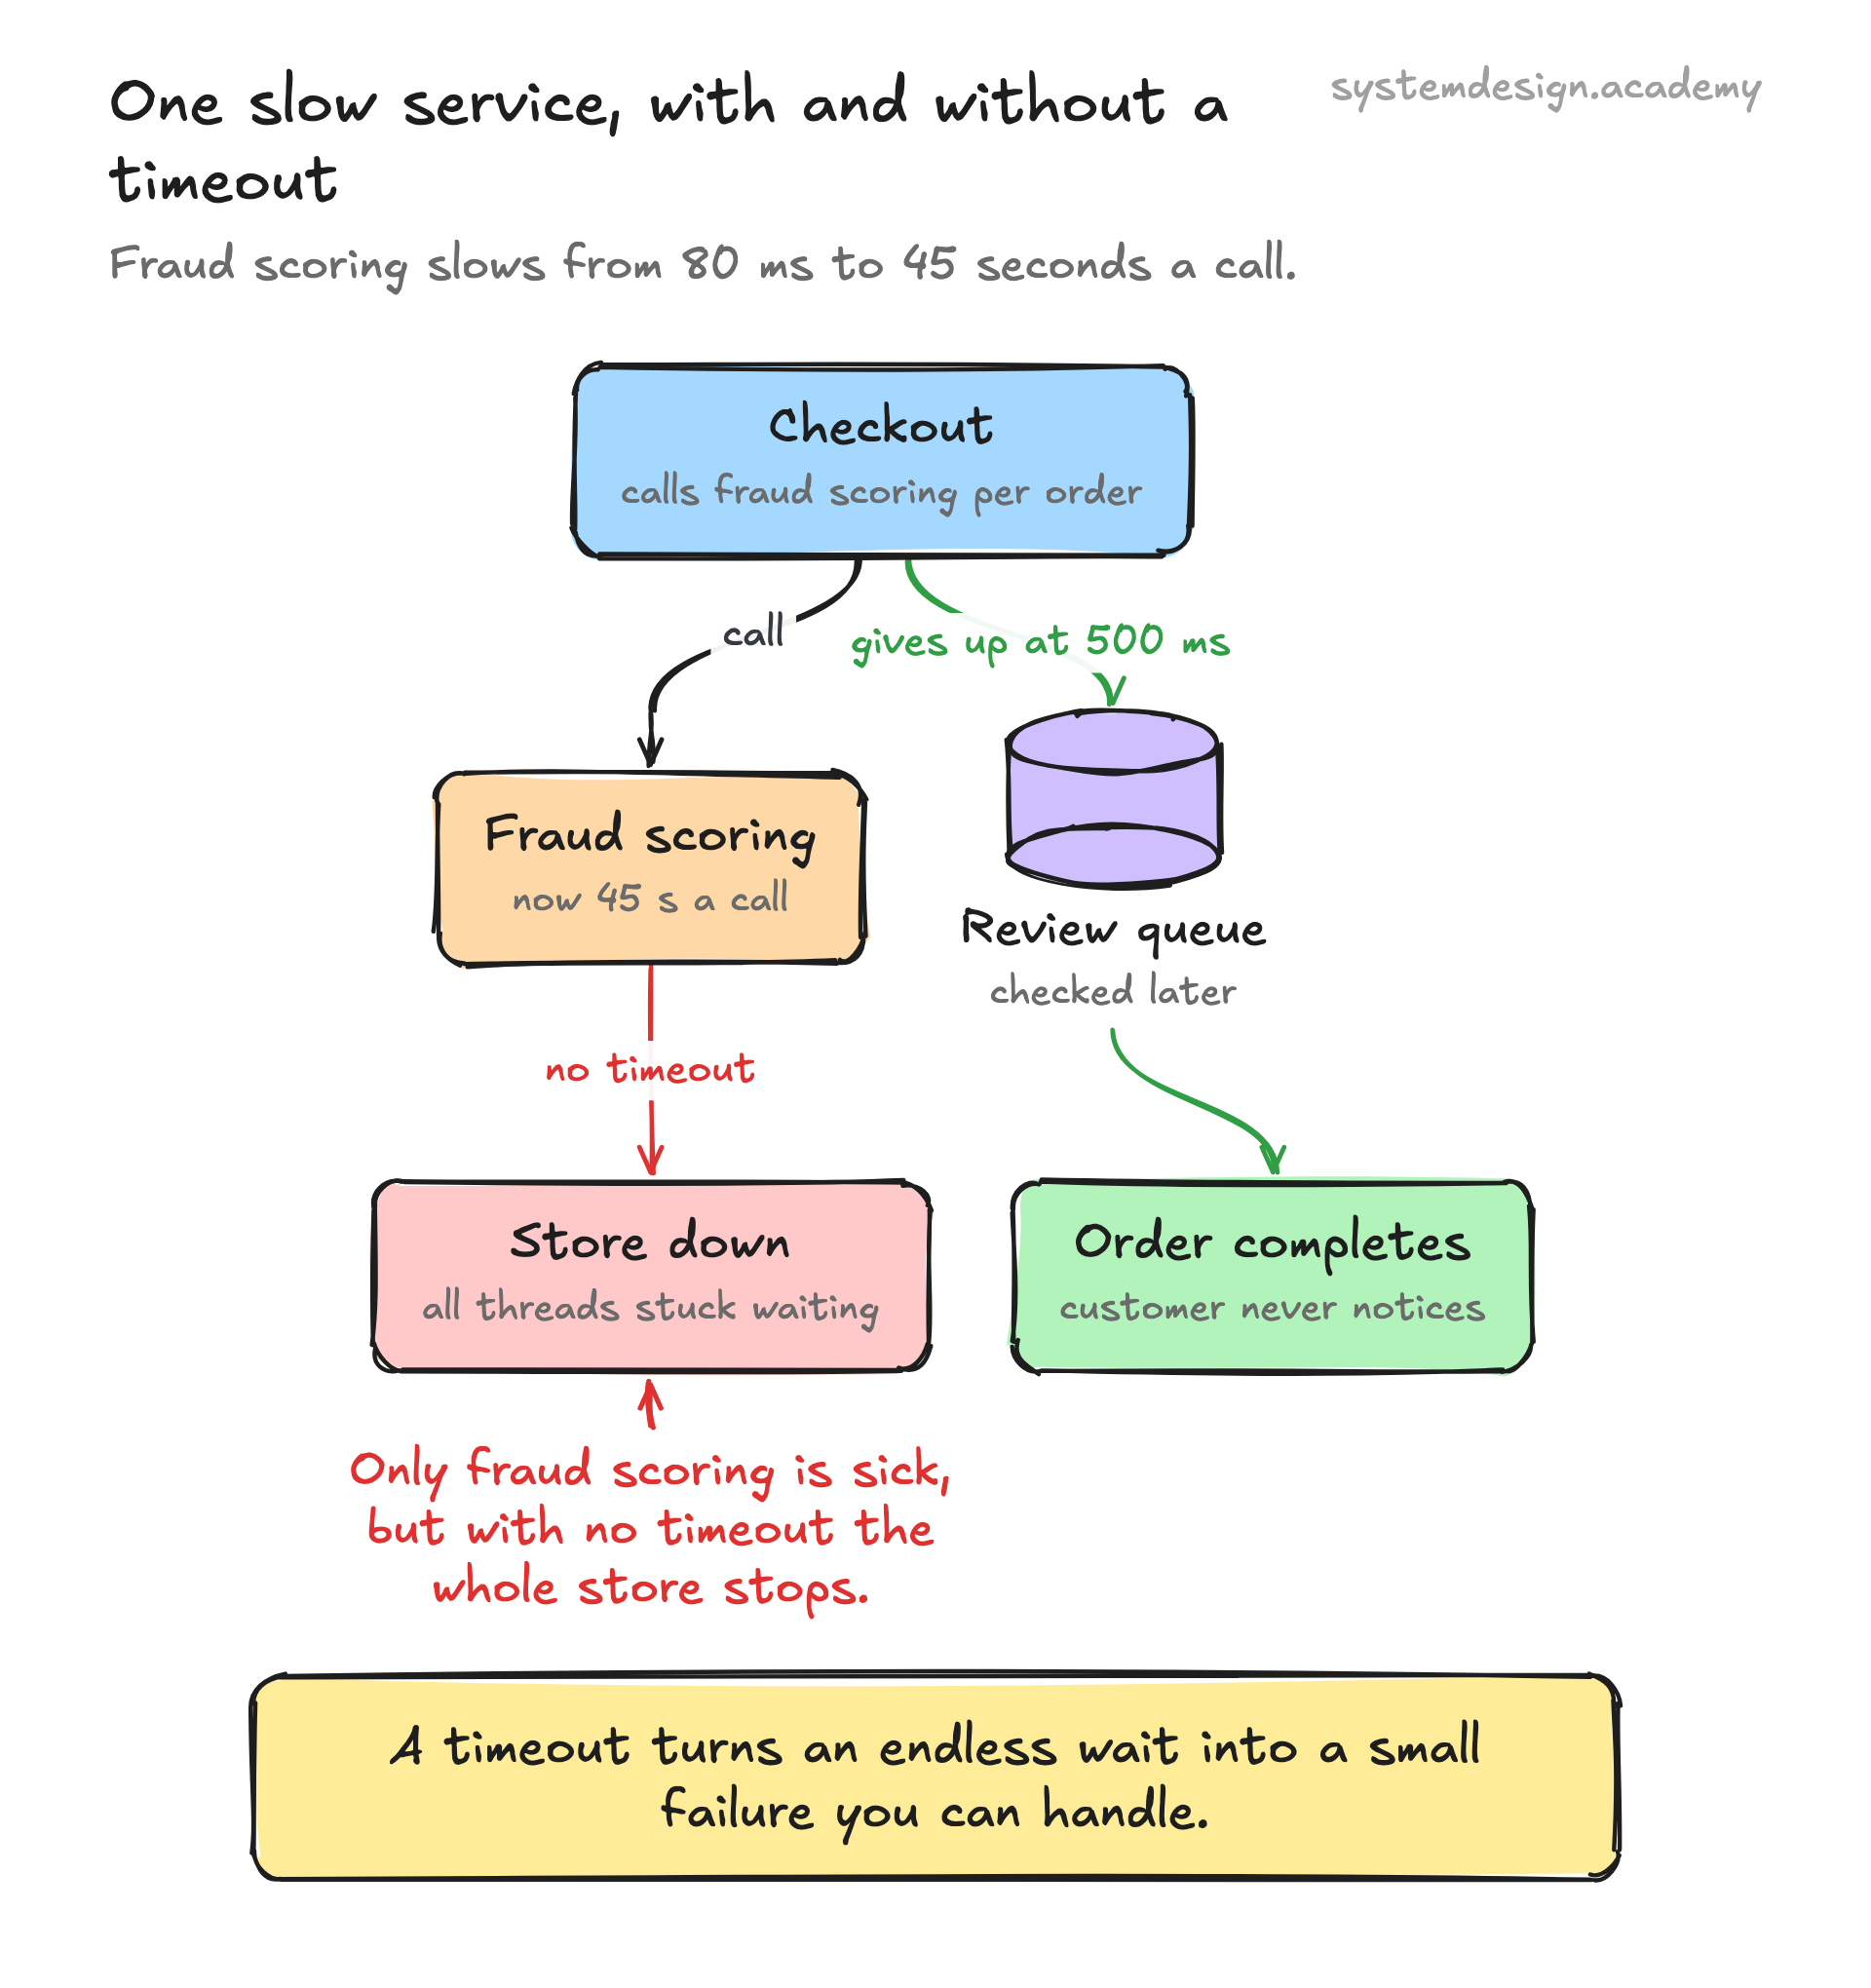
When you make a blocking call, the runtime arms a timer for the deadline you gave it. If the response comes back first, the timer is canceled and you get your data. If the timer fires first, the runtime interrupts the wait, usually by closing the socket or throwing a timeout exception, and the call returns control to you.
In modern systems the deadline is often passed down the call chain. A request comes in with a 2 second budget, the service spends 300ms, then calls a downstream with the remaining 1.7 seconds, which calls its own downstream with what is left. This is deadline propagation, and gRPC supports it directly. It stops a deep chain from each independently waiting its full timeout and blowing past the original budget.
A timeout on its own does not free the work happening downstream. The server may keep processing a query you already gave up on. That is why timeouts pair with cancellation: pass a cancellation token or context so the downstream can see the caller left and stop wasting CPU, connections, and locks.
Picking the number matters. A common rule is to set the timeout above the high percentile of normal latency, often the p99 plus headroom, not the average. If your p99 is 200ms, a 150ms timeout will fail healthy requests, and a 30 second timeout will let real failures hang far too long.