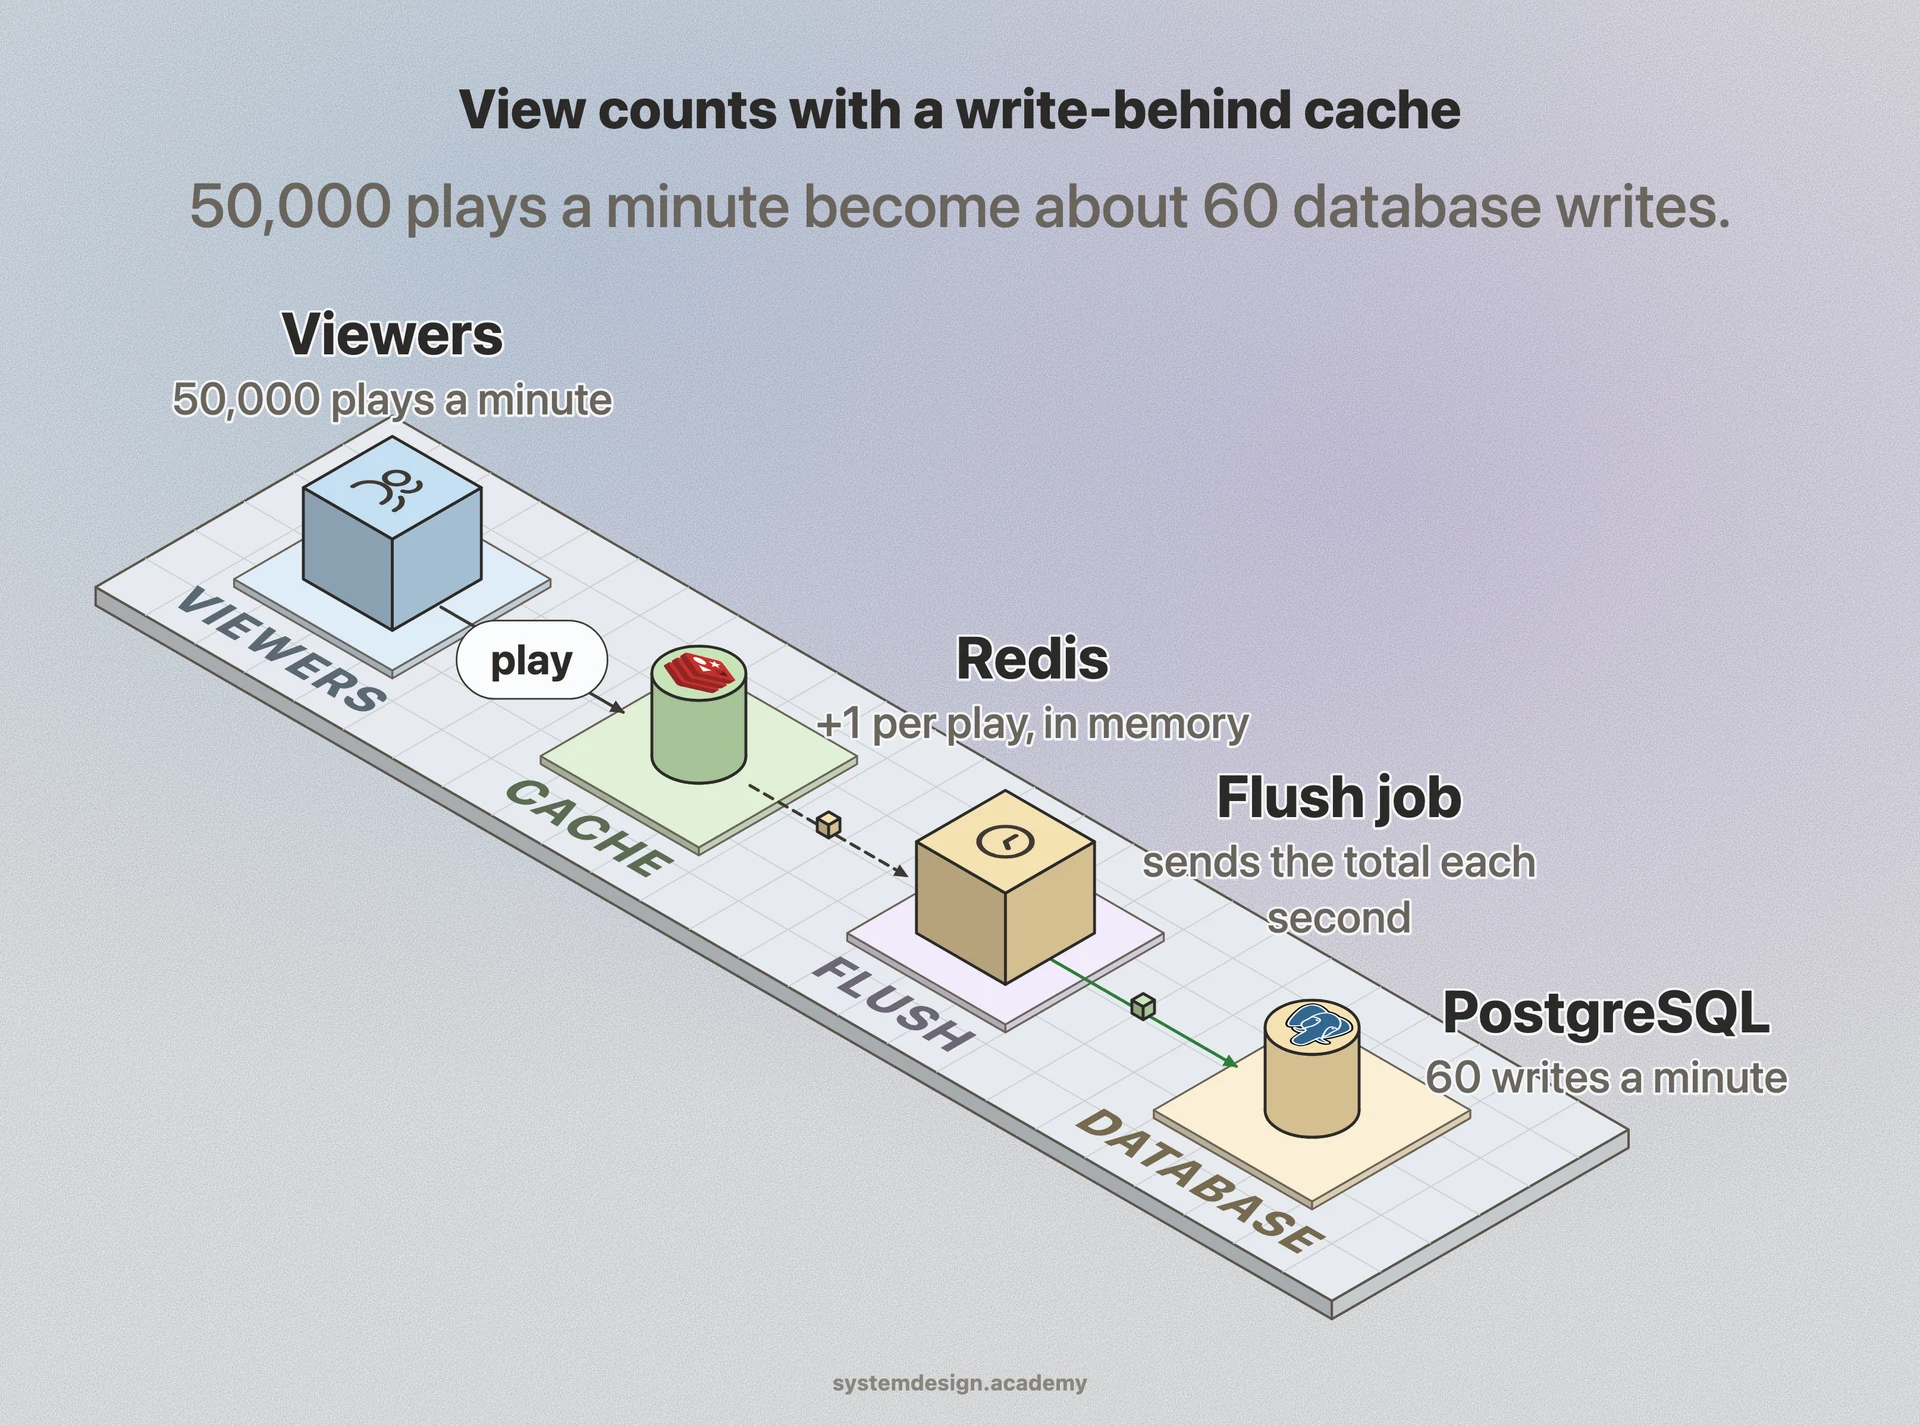
Reach for write-behind when write volume is high, writes are bursty, and the data can tolerate a small risk of loss. Counters, view counts, like tallies, telemetry, session activity, and game state are good fits. Losing the last second of a view counter rarely matters; losing a payment record does.
The core trade-off is durability versus speed. Because the database lags the cache, a cache crash or power loss can drop every entry still in the dirty queue. Production systems reduce this by replicating the cache, using append-only logs, or persisting the queue to disk so it survives a restart.
There are two more sharp edges. First, if another service reads directly from the database while a write is still in the queue, it sees stale data, so the database is no longer the single source of truth in real time. Second, a write to the database can fail after the application already got a success response, which means error handling moves into the background worker with retries and dead-letter handling instead of failing the original request.