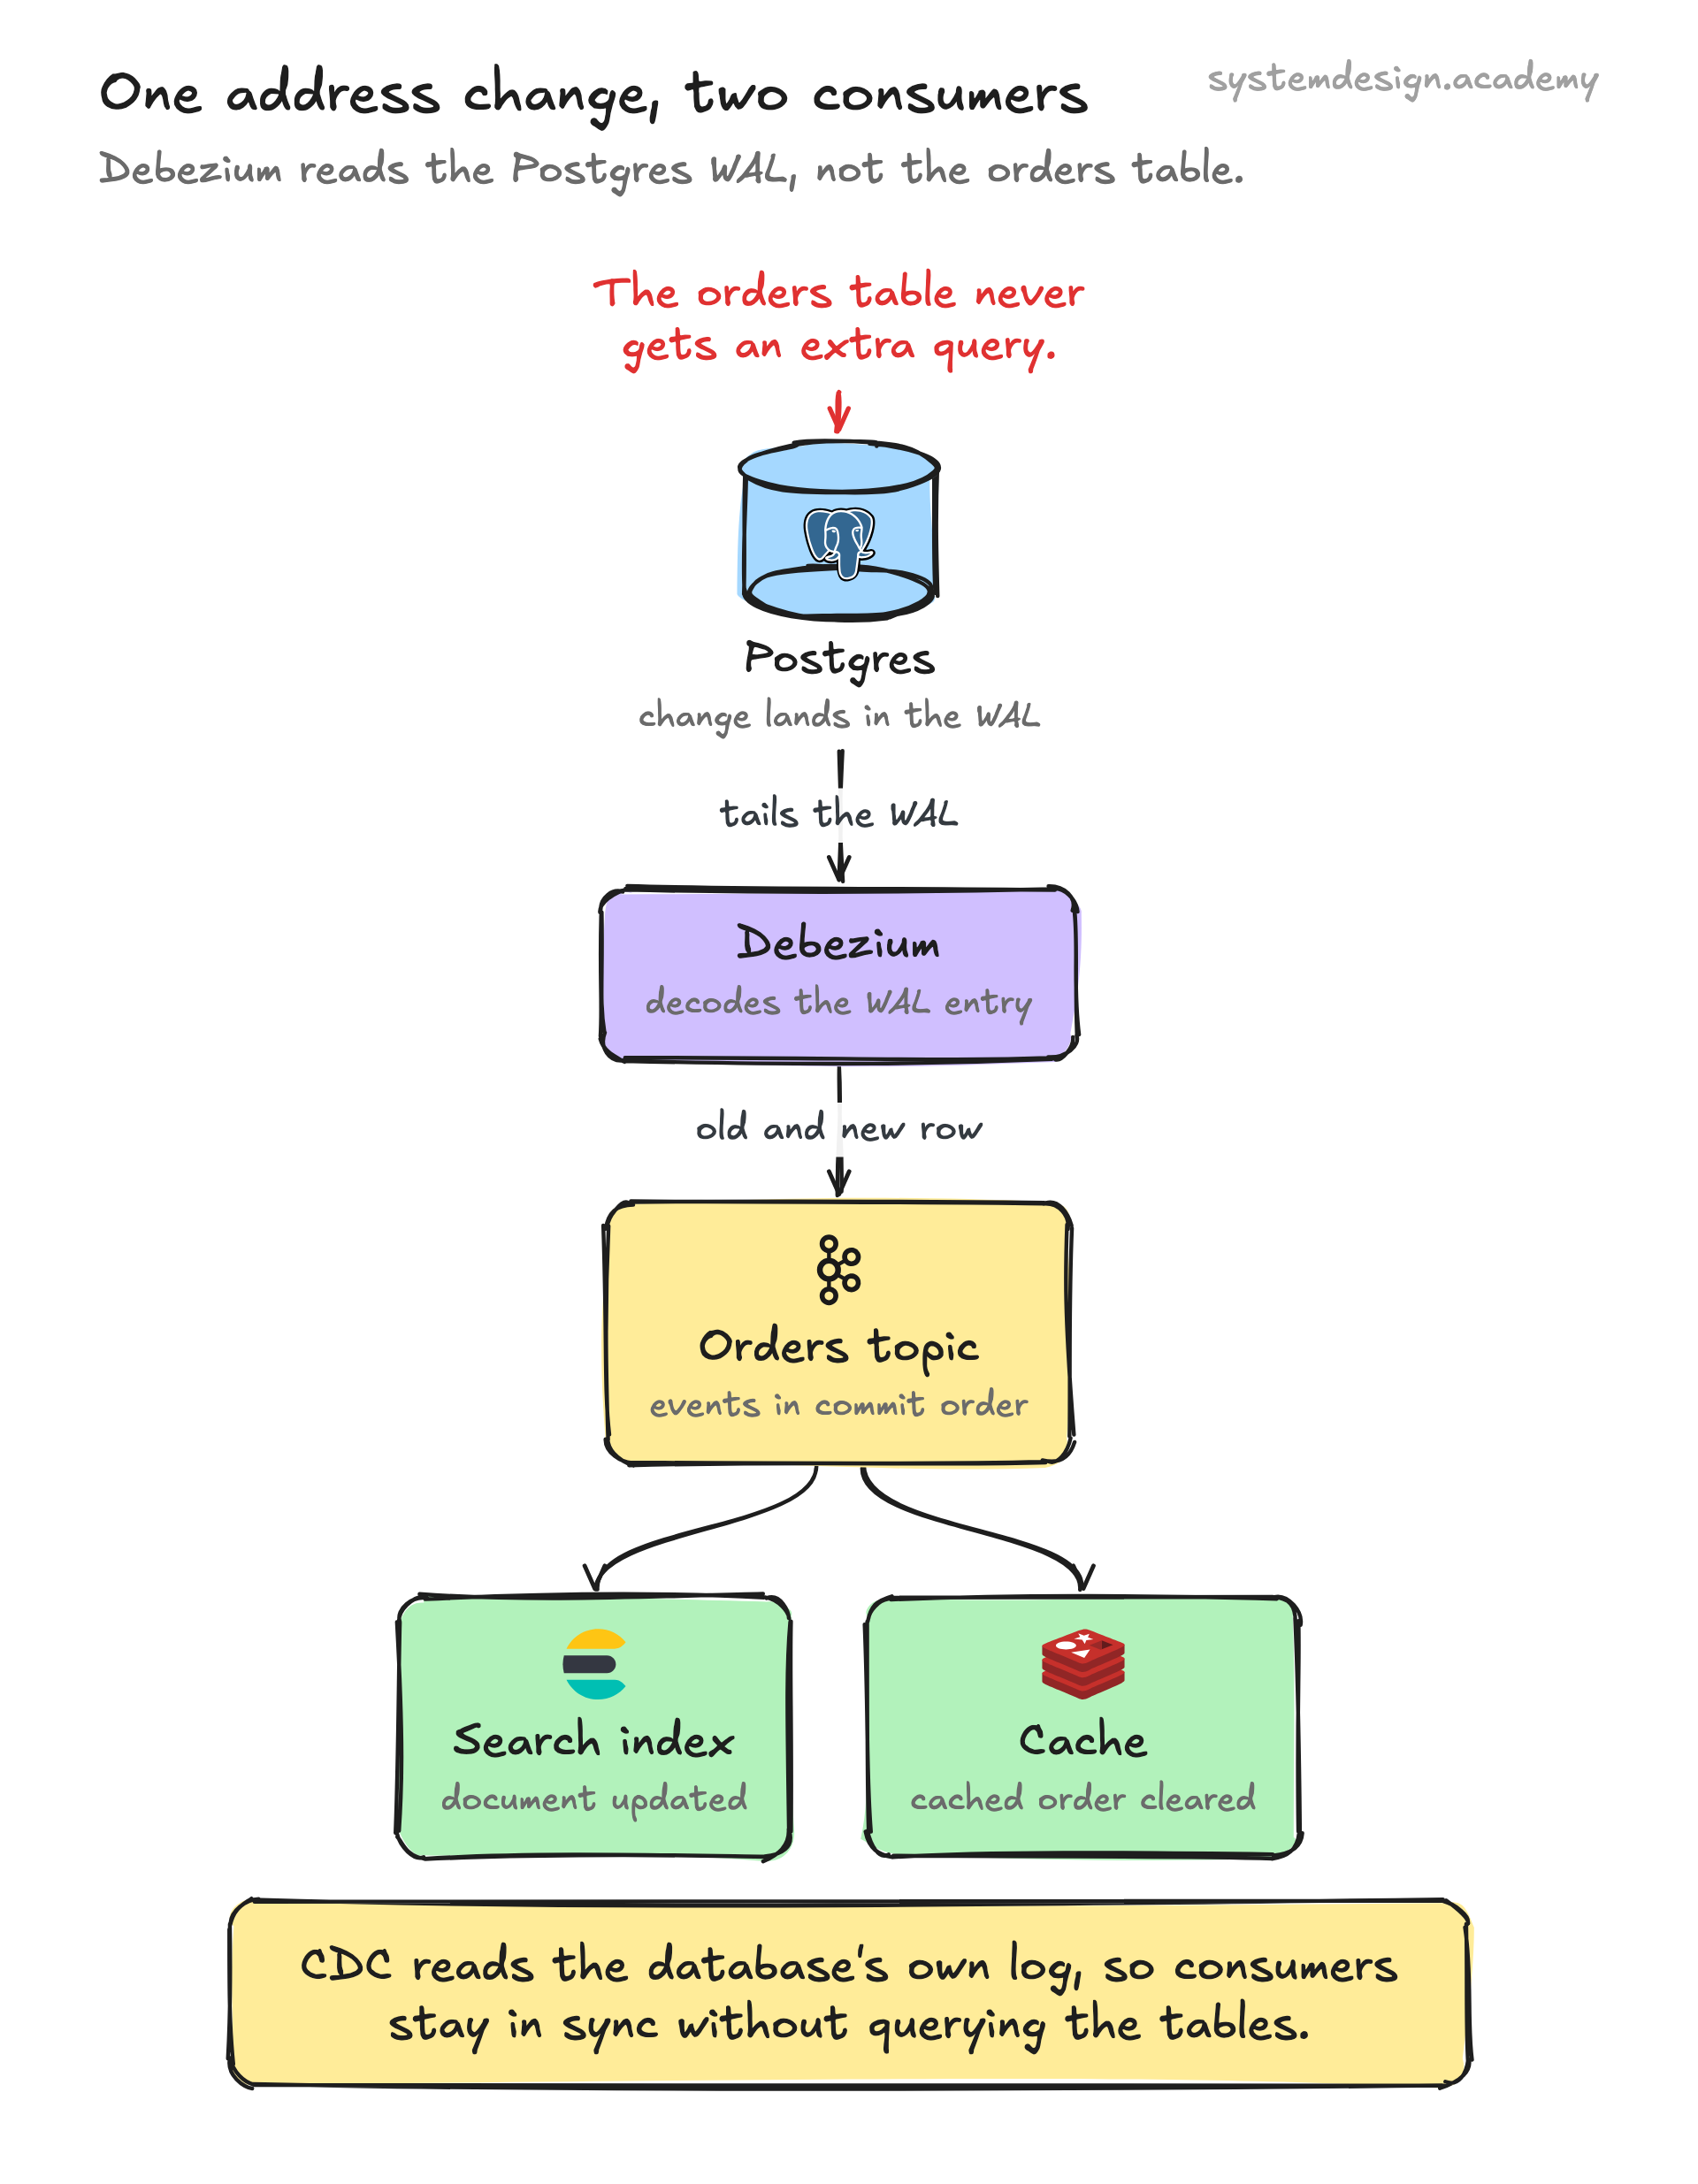
Most production CDC reads the database's write-ahead log. Postgres calls it the WAL, MySQL calls it the binlog, MongoDB exposes the oplog, and SQL Server has its own transaction log. Every committed change is appended to this log before the data files are updated, so the log is a complete, ordered history of writes.
A CDC connector connects as if it were a replication client. In Postgres it creates a logical replication slot and decodes WAL entries into structured row events; in MySQL it registers as a replica and reads the binlog. Because it only tails an append-only log, it adds almost no load to the source and never blocks application writes.
Tools like Debezium take those decoded events and publish them to Kafka, one topic per table, with the changes in commit order. Each event includes a position marker (LSN in Postgres, binlog offset in MySQL) so a consumer that restarts knows exactly where to resume without losing or duplicating data.
There are simpler approaches that do not read the log. Query-based CDC polls an updated_at column on a timer, and trigger-based CDC writes a row into an audit table on every change. Both work but they miss deletes (query-based) or add write overhead and complexity (trigger-based), which is why log-based CDC has become the default.