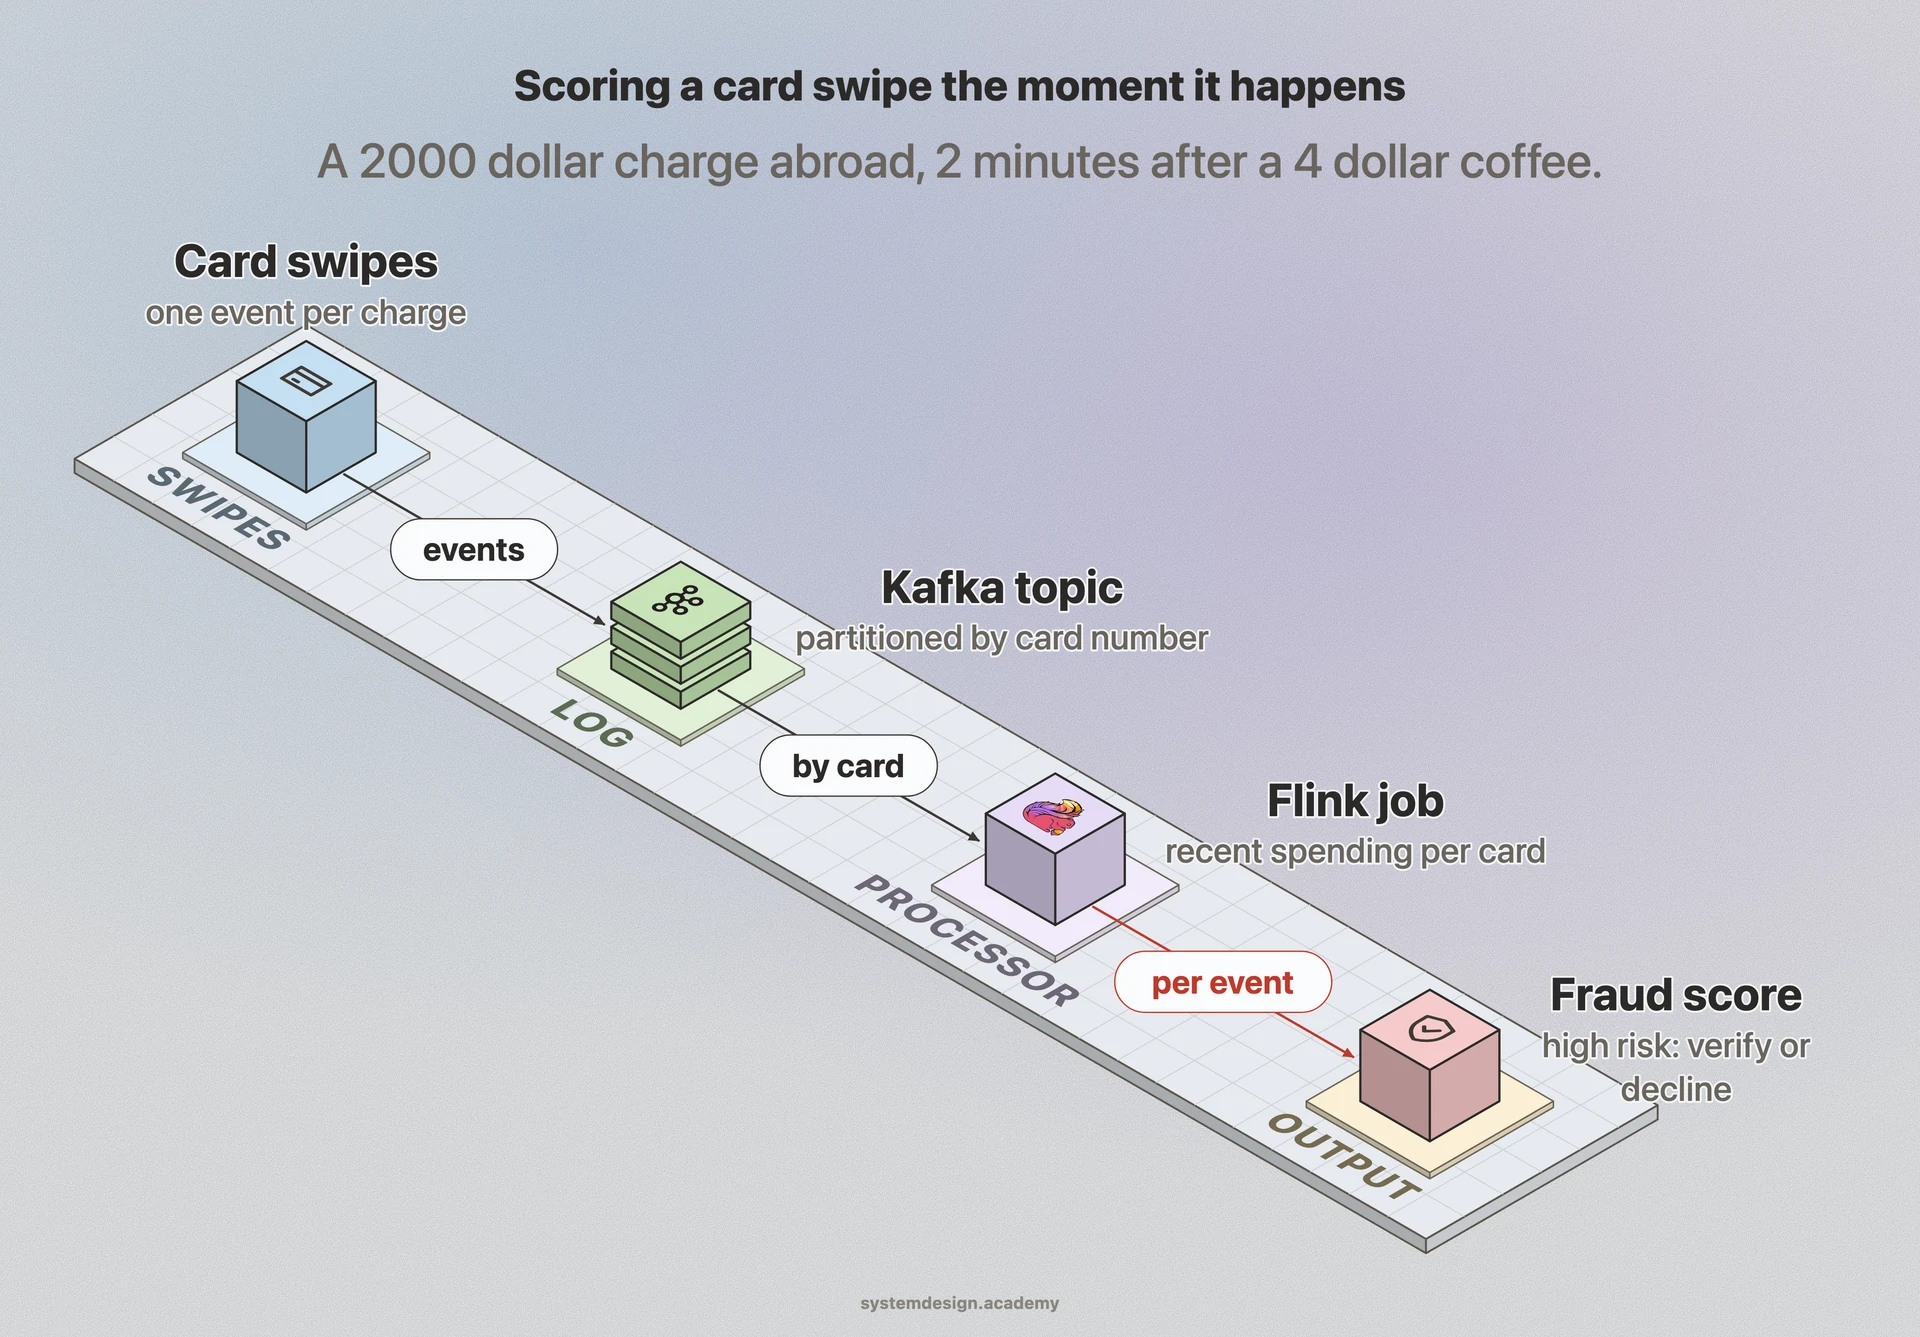
Reach for stream processing when the value of an answer decays fast. Blocking a stolen credit card is worthless an hour later, so fraud scoring has to happen in the few hundred milliseconds before the charge clears. Same logic applies to live dashboards, alerting on error spikes, dynamic pricing, and feeding fresh features to a recommendation model.
The cost is real complexity. A batch job that fails just gets rerun tomorrow. A streaming job runs forever, so you have to design for late data, out-of-order events, state that grows without bound, schema changes on a live pipeline, and the question of what exactly-once even means when results have already been sent to an external system. Debugging a continuous job is harder than rerunning a script over yesterday's file.
If you do not need an answer in seconds, batch is usually cheaper, simpler, and easier to reason about. Many teams run both: a batch pipeline computes the slow, fully accurate numbers overnight, while a stream pipeline serves the fast, approximate numbers in real time. That hybrid is common enough to have a name, the Lambda architecture. The Kappa architecture is the opposite choice: it drops the batch layer and runs everything, including reprocessing, as a stream.