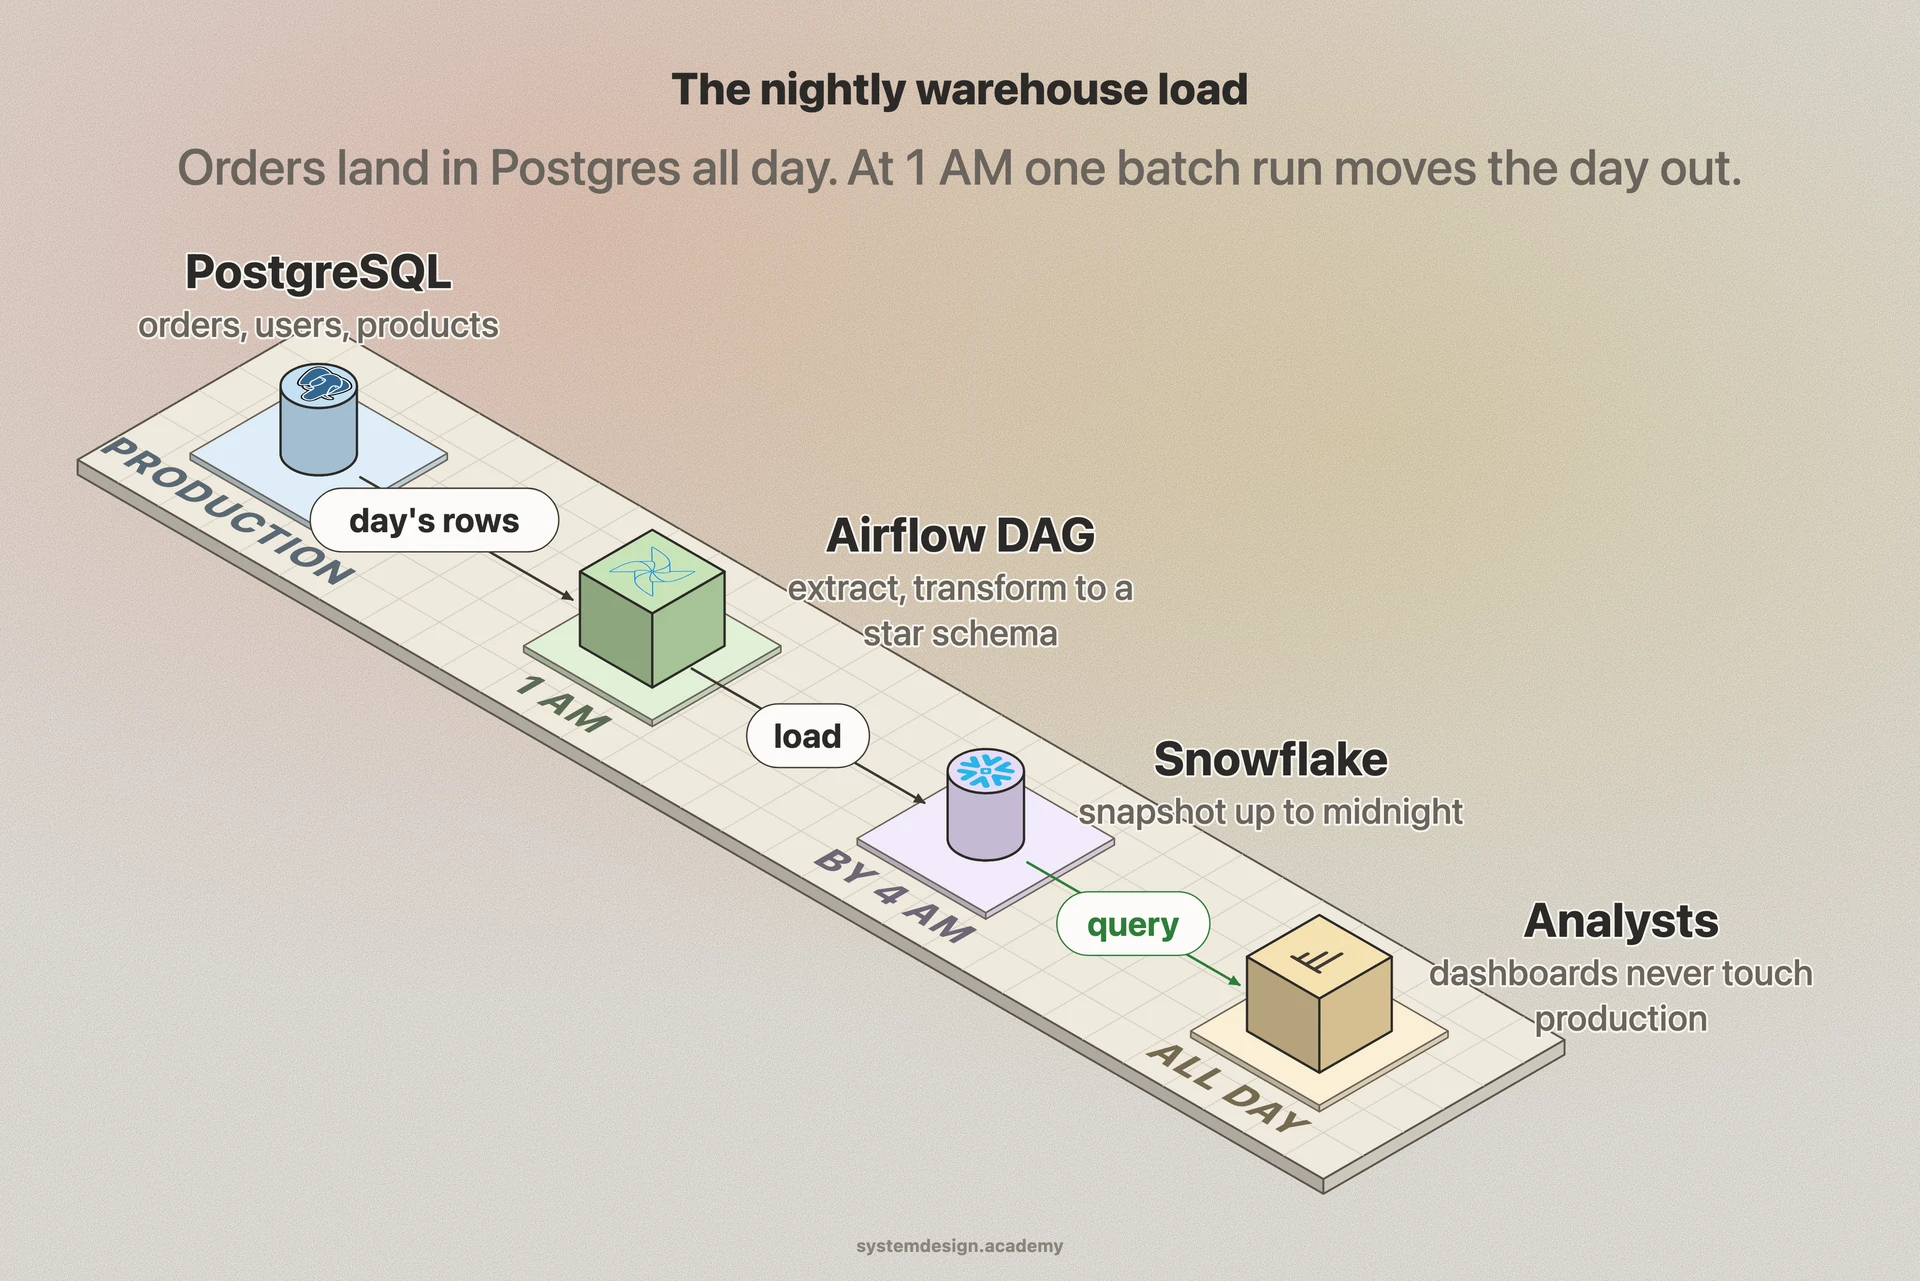
A batch job moves through three stages: read the input, transform it, write the output. This is the classic ETL pattern, extract then transform then load. The reader pulls from a source like a database table, a pile of CSV or Parquet files in S3, or yesterday's log files. The processor applies the business logic. The writer lands the result in a warehouse, another table, or a report.
For large data the work is split across many machines. A framework like Apache Spark or Hadoop MapReduce partitions the input, hands each partition to a worker, runs the transform in parallel, then combines the results. A 2 TB dataset that would take hours on one machine finishes in minutes across 100 workers.
Two properties matter a lot. First, restartability: if a job dies halfway, you want to rerun it cleanly. Good batch jobs are idempotent, meaning running the same job twice on the same input produces the same output, often by writing to a fresh partition and swapping it in at the end. Second, checkpointing: long jobs save progress so a failure does not throw away six hours of work.