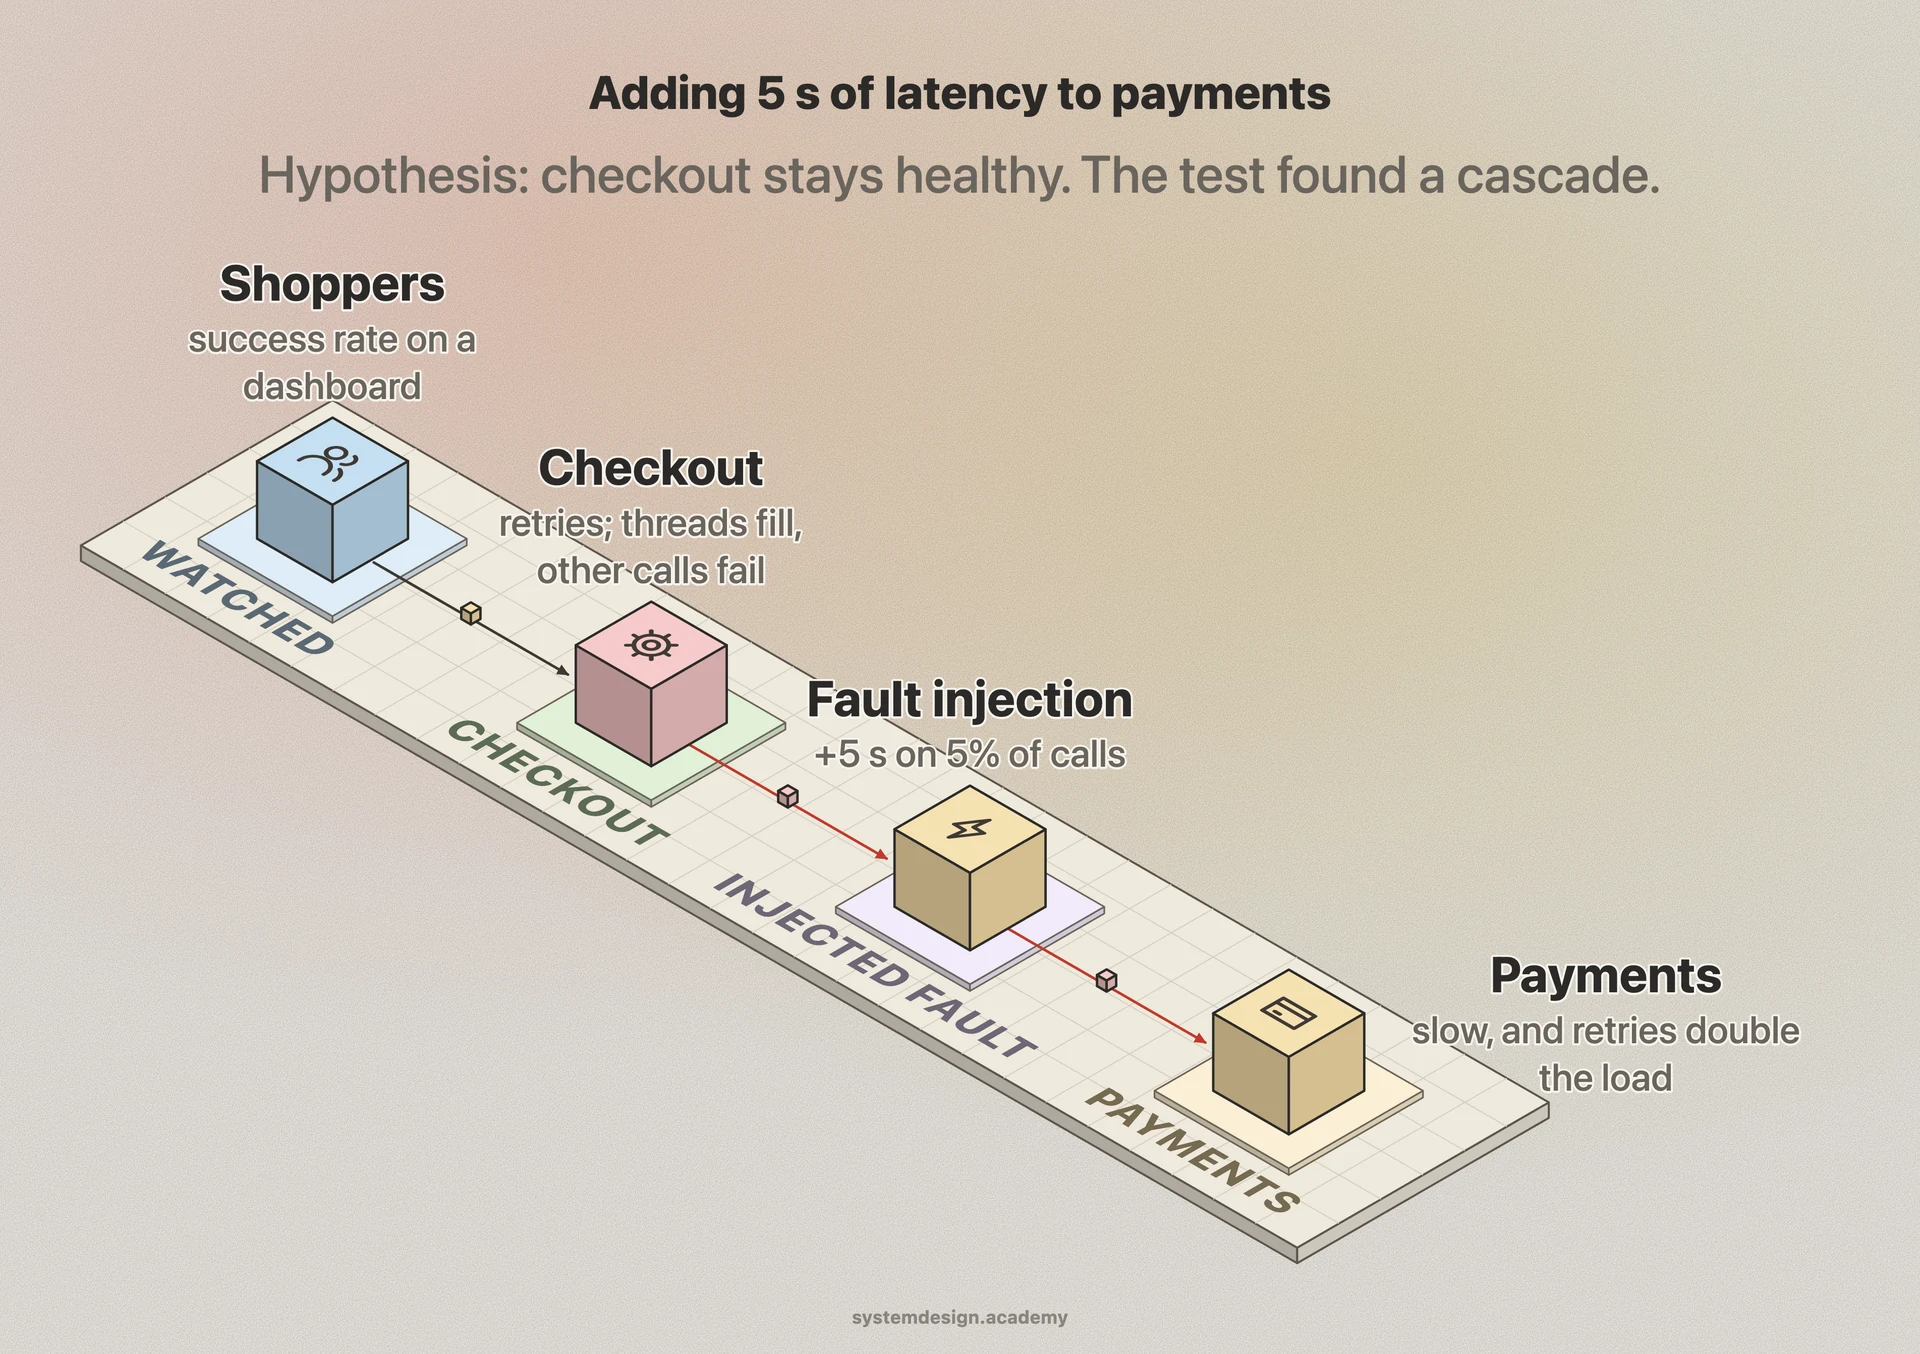
Most reliability work assumes you already know how your system fails. Chaos engineering flips that around. You break things on purpose, watch what happens, and learn where the gaps are. The point is not to cause damage. The point is to surface the surprises while you are watching, instead of at 3 AM when a customer reports it.
The discipline was formalized at Netflix around 2010 when they moved to AWS. They could not assume any single server would stay alive, so they built Chaos Monkey, a tool that randomly terminates production instances during business hours. If killing a random server took the site down, that was a bug in the architecture, and engineers fixed it. Over time the team forced every service to tolerate the loss of any instance at any time.
A chaos experiment has four parts. First, define the steady state, a measurable signal that means the system is healthy, like requests per second or checkout success rate. Second, write a hypothesis, for example the steady state holds even if one availability zone goes dark. Third, inject the failure. Fourth, compare. If the steady state held, your confidence goes up. If it broke, you found work to do.