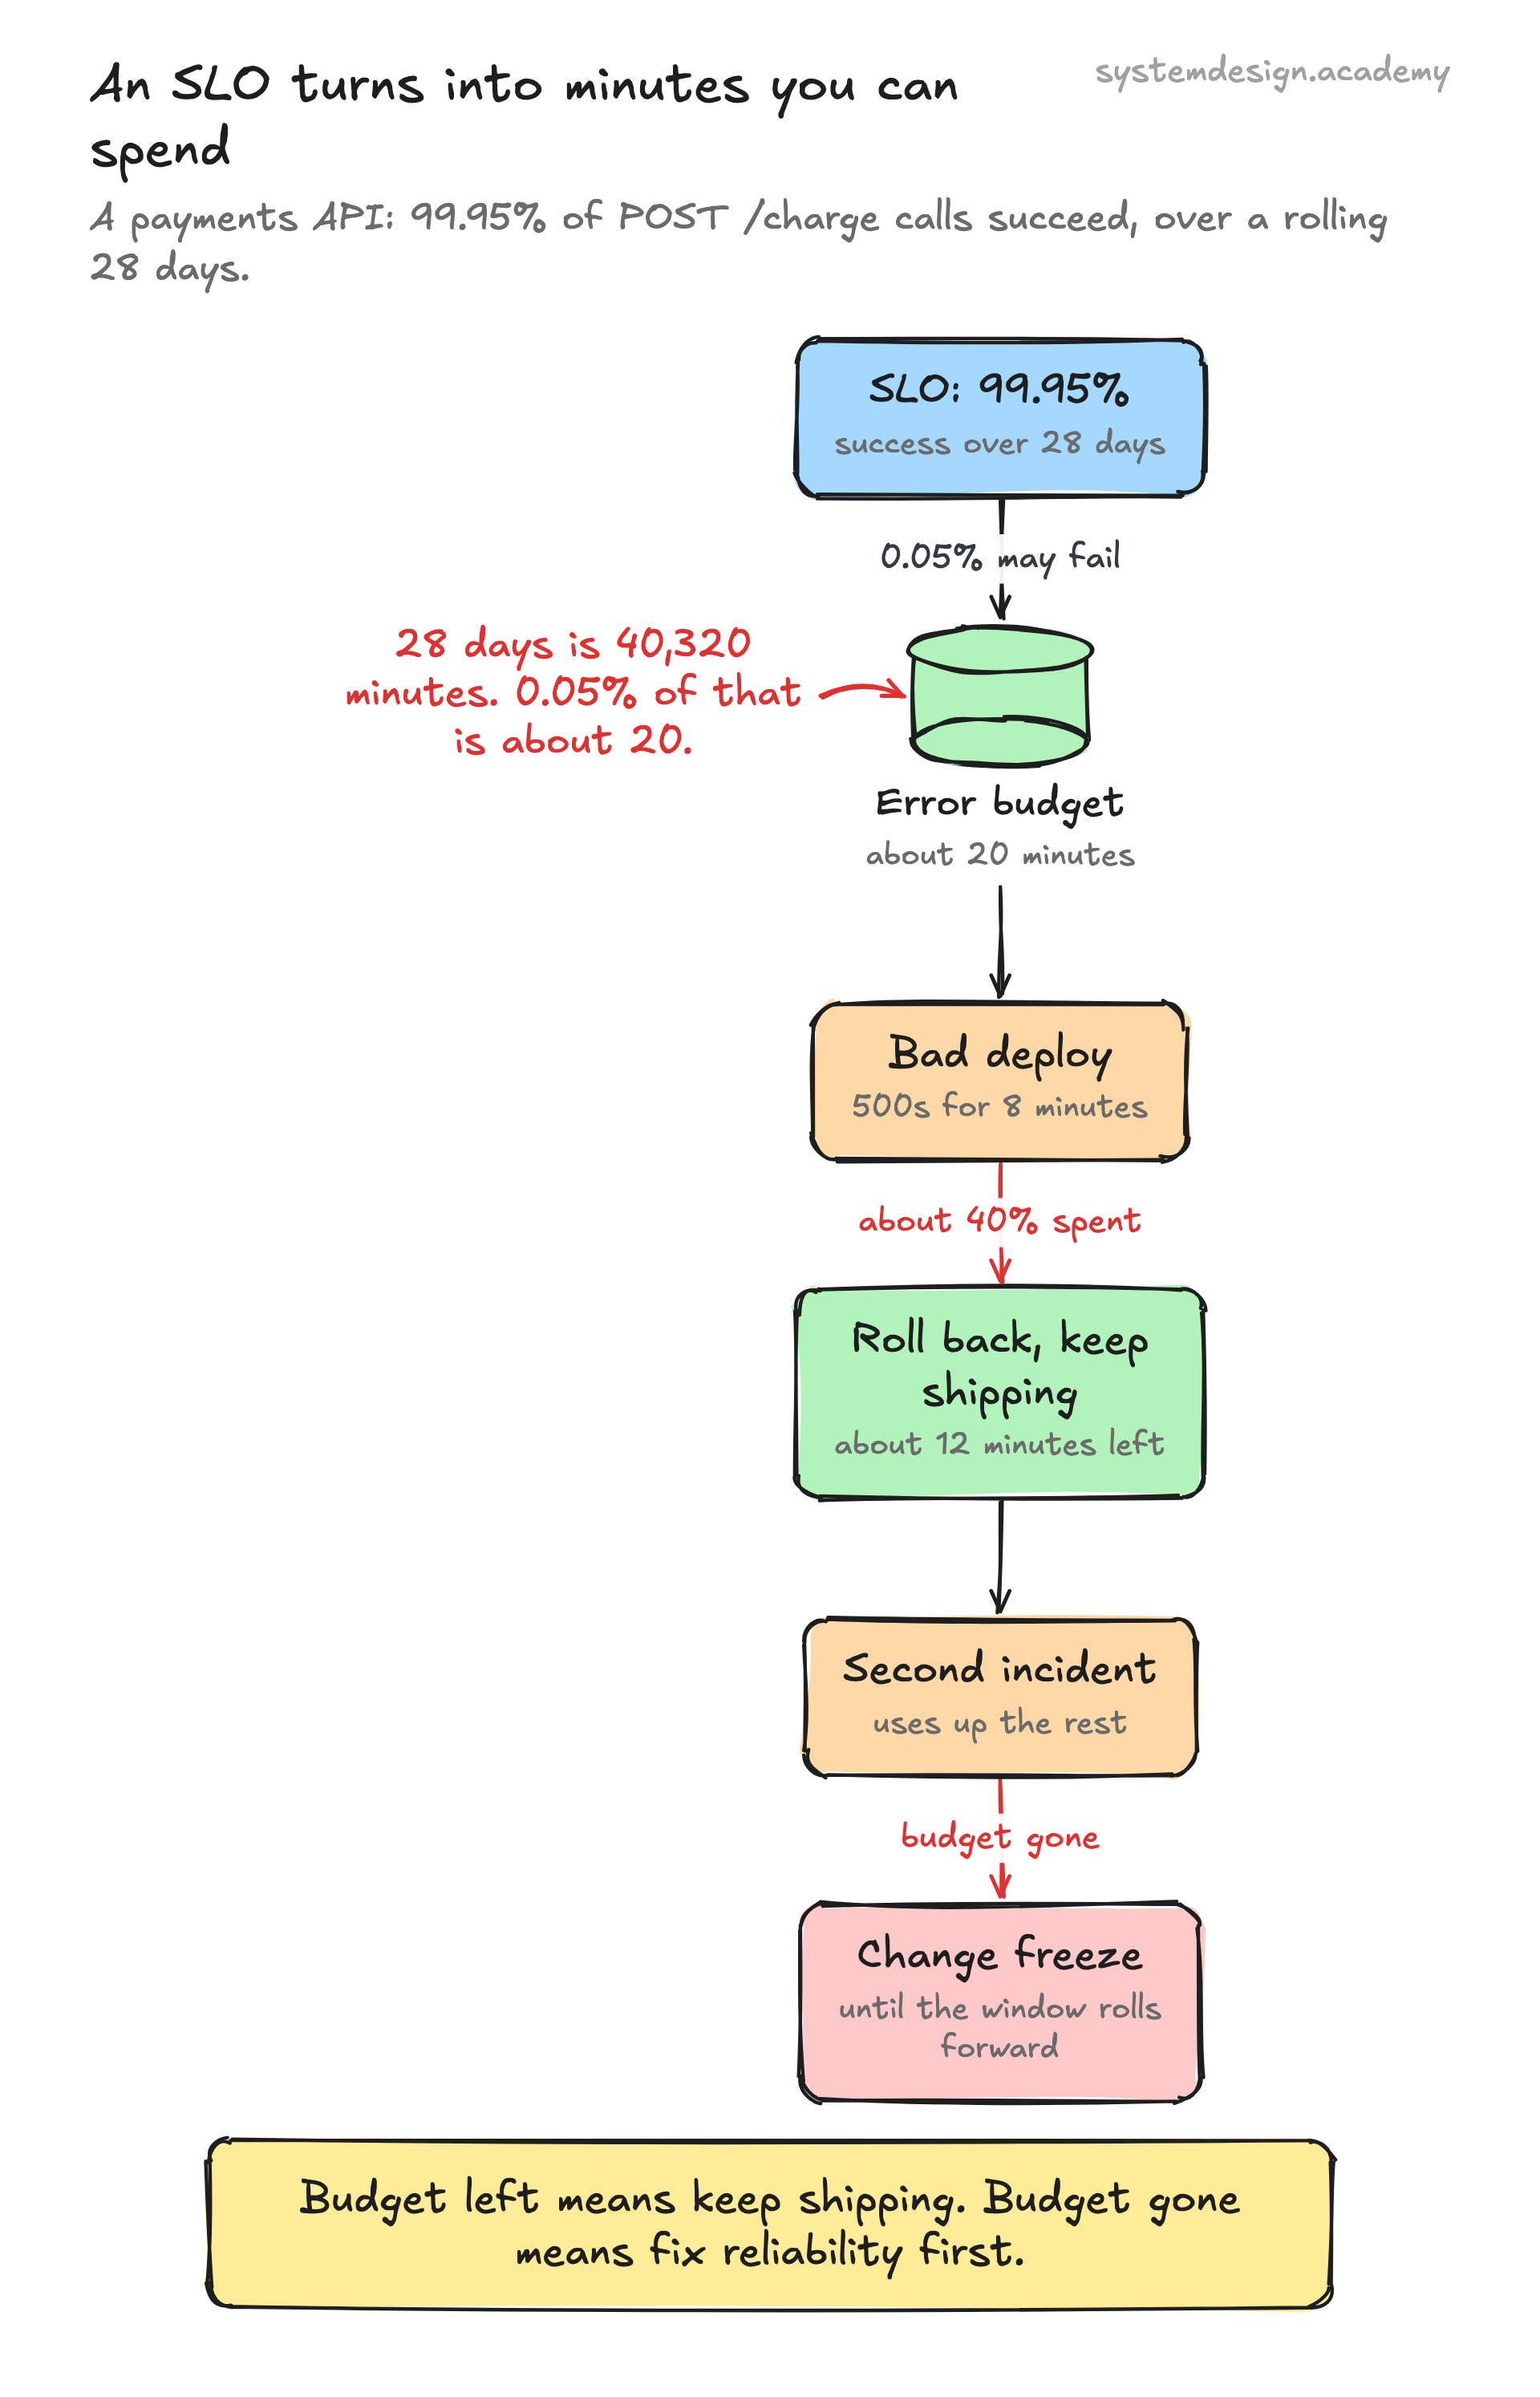
The number behind an SLO directly produces an error budget. If your availability SLO is 99.9% over 30 days, you are allowed to be unavailable for 0.1% of that window, which is about 43 minutes per month. That 0.1% is the budget you get to spend on bugs, bad deploys, and risky experiments.
You compute the SLI continuously, usually from request logs or metrics in Prometheus, Datadog, or a similar system. For an availability SLO that is good_requests / total_requests. You then track how much of the error budget is left. Burning the budget slowly is fine. Burning it fast, say half the month's budget in one hour, should page someone.
Teams use multi-window, multi-burn-rate alerts so they page on real problems instead of on every single failed request. A fast burn rate triggers an urgent page, a slow steady burn opens a ticket. This is how Google's SRE practice ties alerting to user-facing impact rather than to arbitrary CPU or memory thresholds.