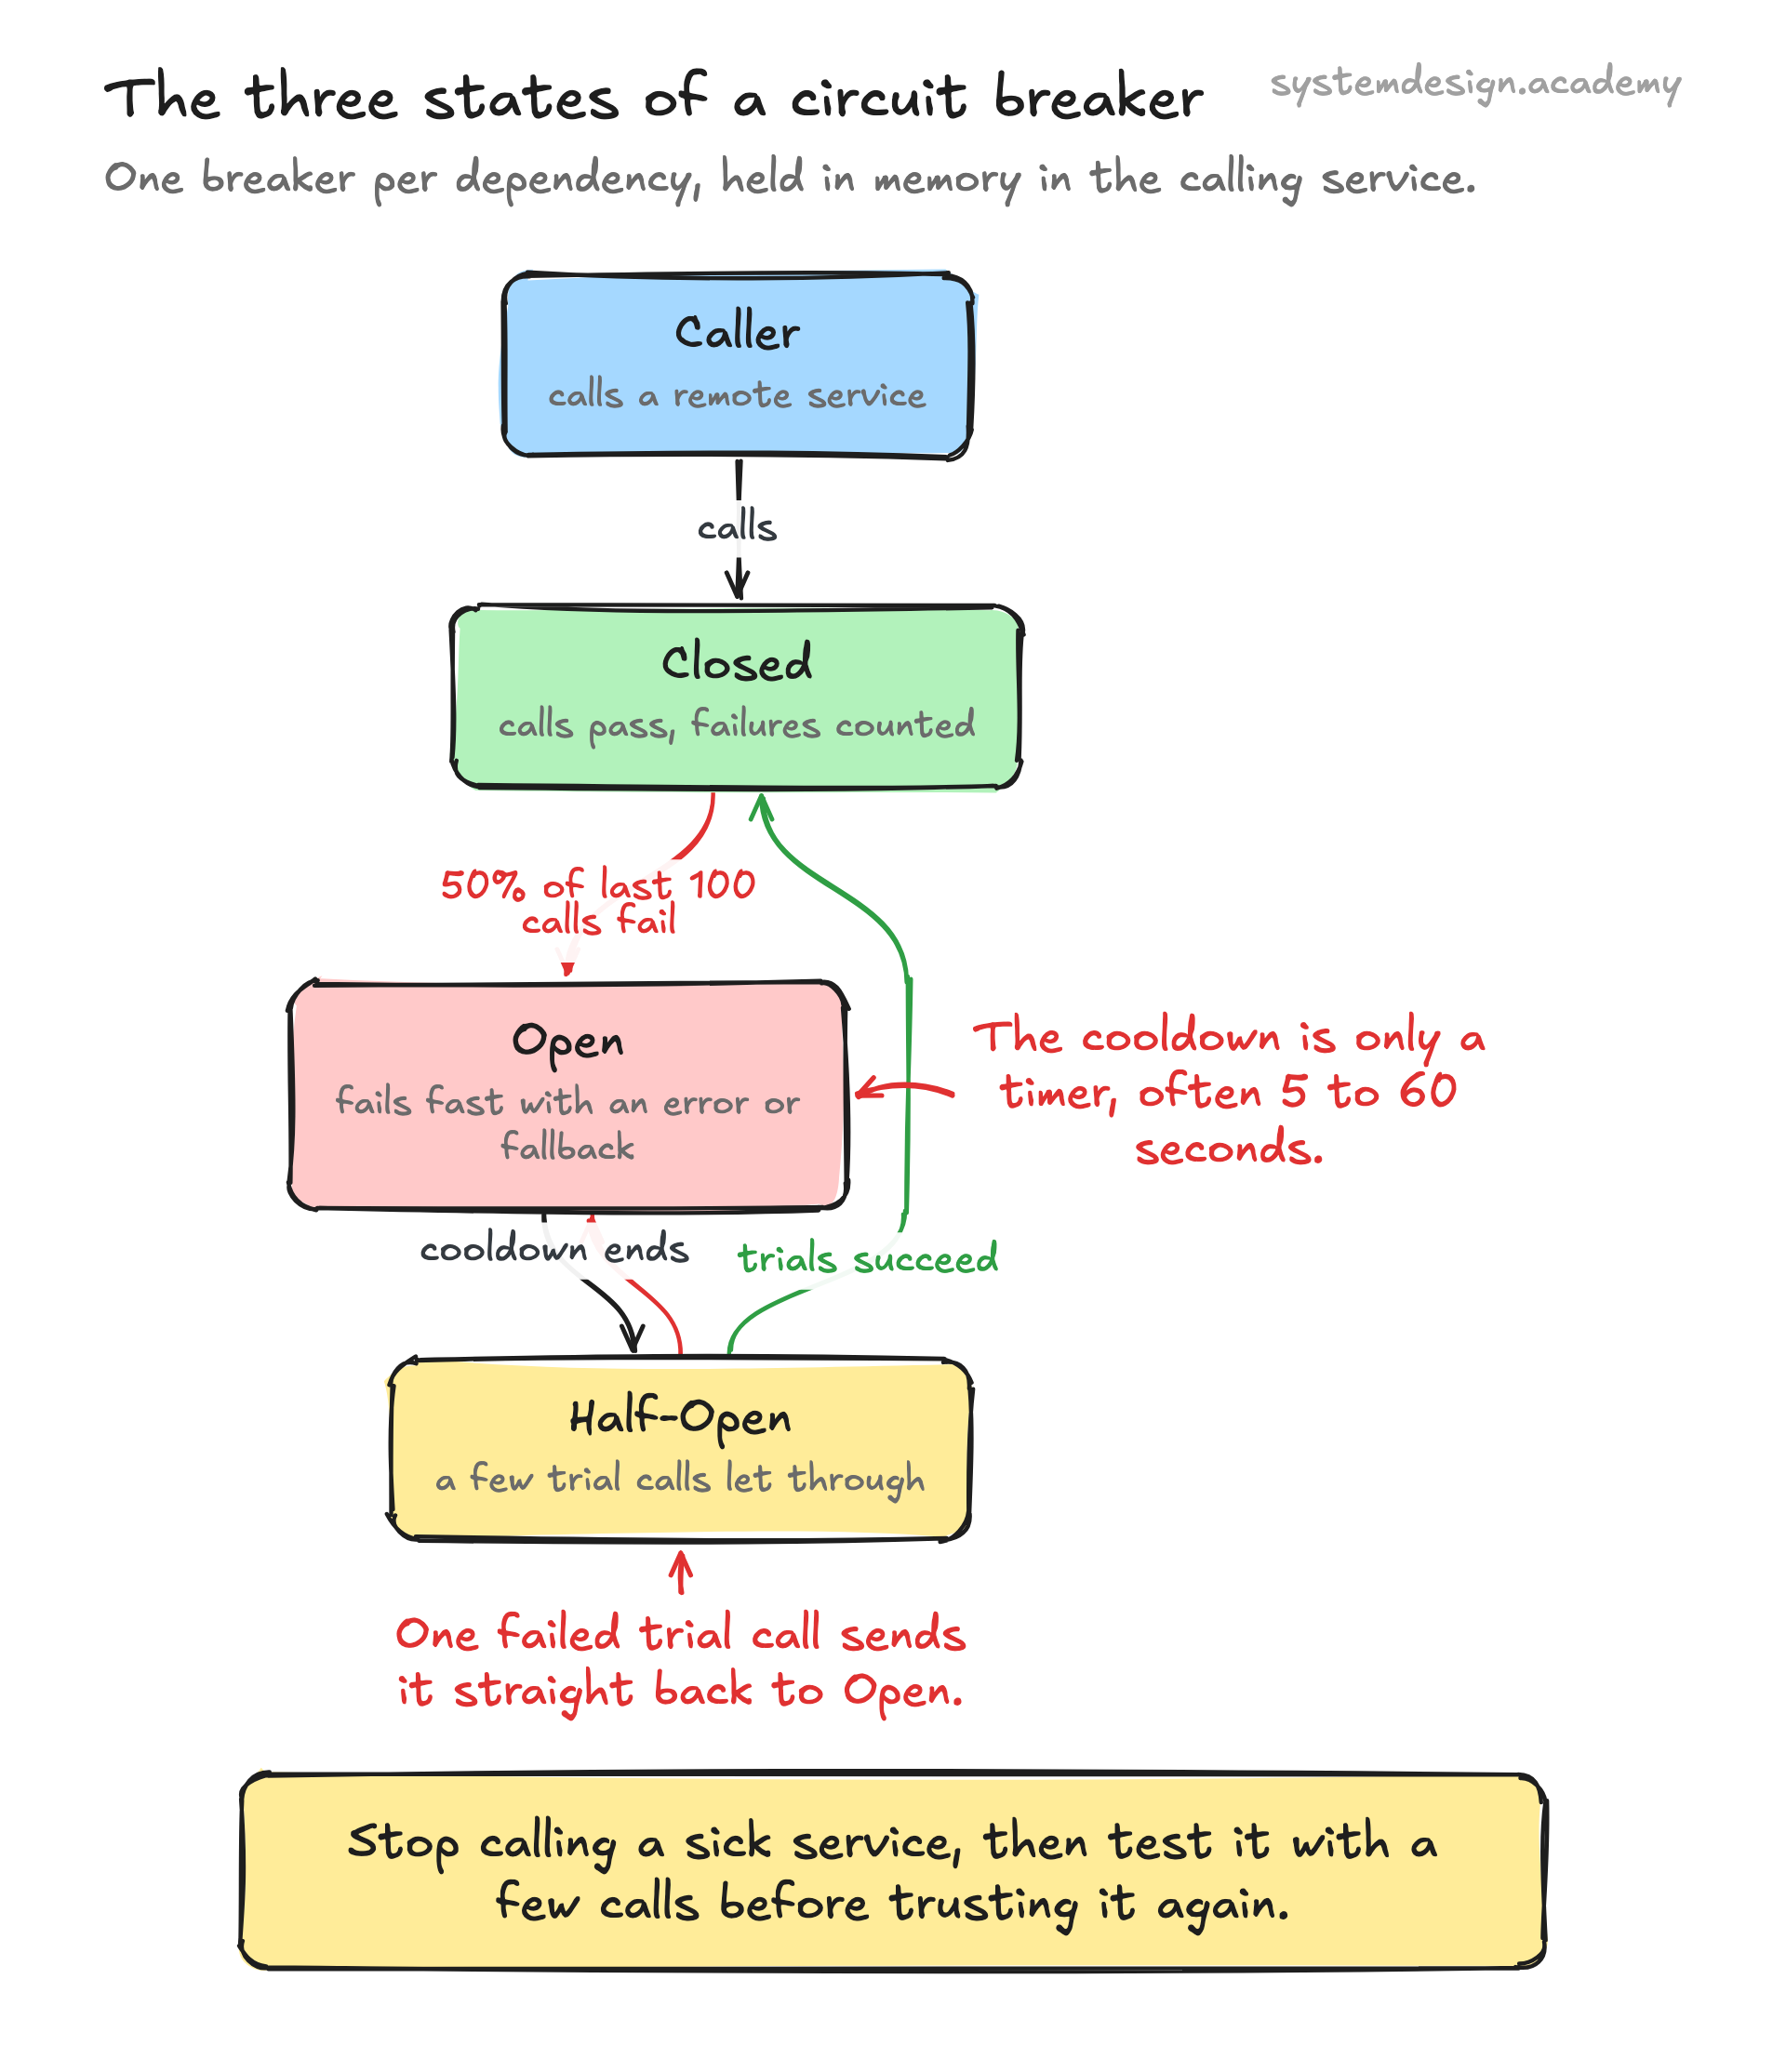
Use a circuit breaker on any synchronous network call to a dependency that can fail or slow down: a third-party API, a microservice, a cache, a database behind a connection pool. The core benefit is fail-fast behavior. Without it, a slow downstream service causes callers to pile up on timeouts, exhaust thread pools and connections, and drag down the whole system in a cascading failure.
The main trade-off is that an open breaker rejects requests that might have succeeded. During the Open state you are trading some availability for stability of the overall system. Pairing the breaker with a fallback (cached data, a default value, a degraded feature) softens this for the user.
Tuning is the hard part. Set the failure threshold too low and the breaker trips on normal blips, hurting availability. Set it too high and it never protects you. The cooldown also matters: too short and you keep slamming a recovering service, too long and you stay degraded after it is healthy. These values need to be tuned against real traffic and timeout settings.
One caveat: because state is per instance, a fleet of 50 pods has 50 independent breakers. They will not trip in lockstep, which is usually fine but means recovery probing is distributed rather than coordinated.