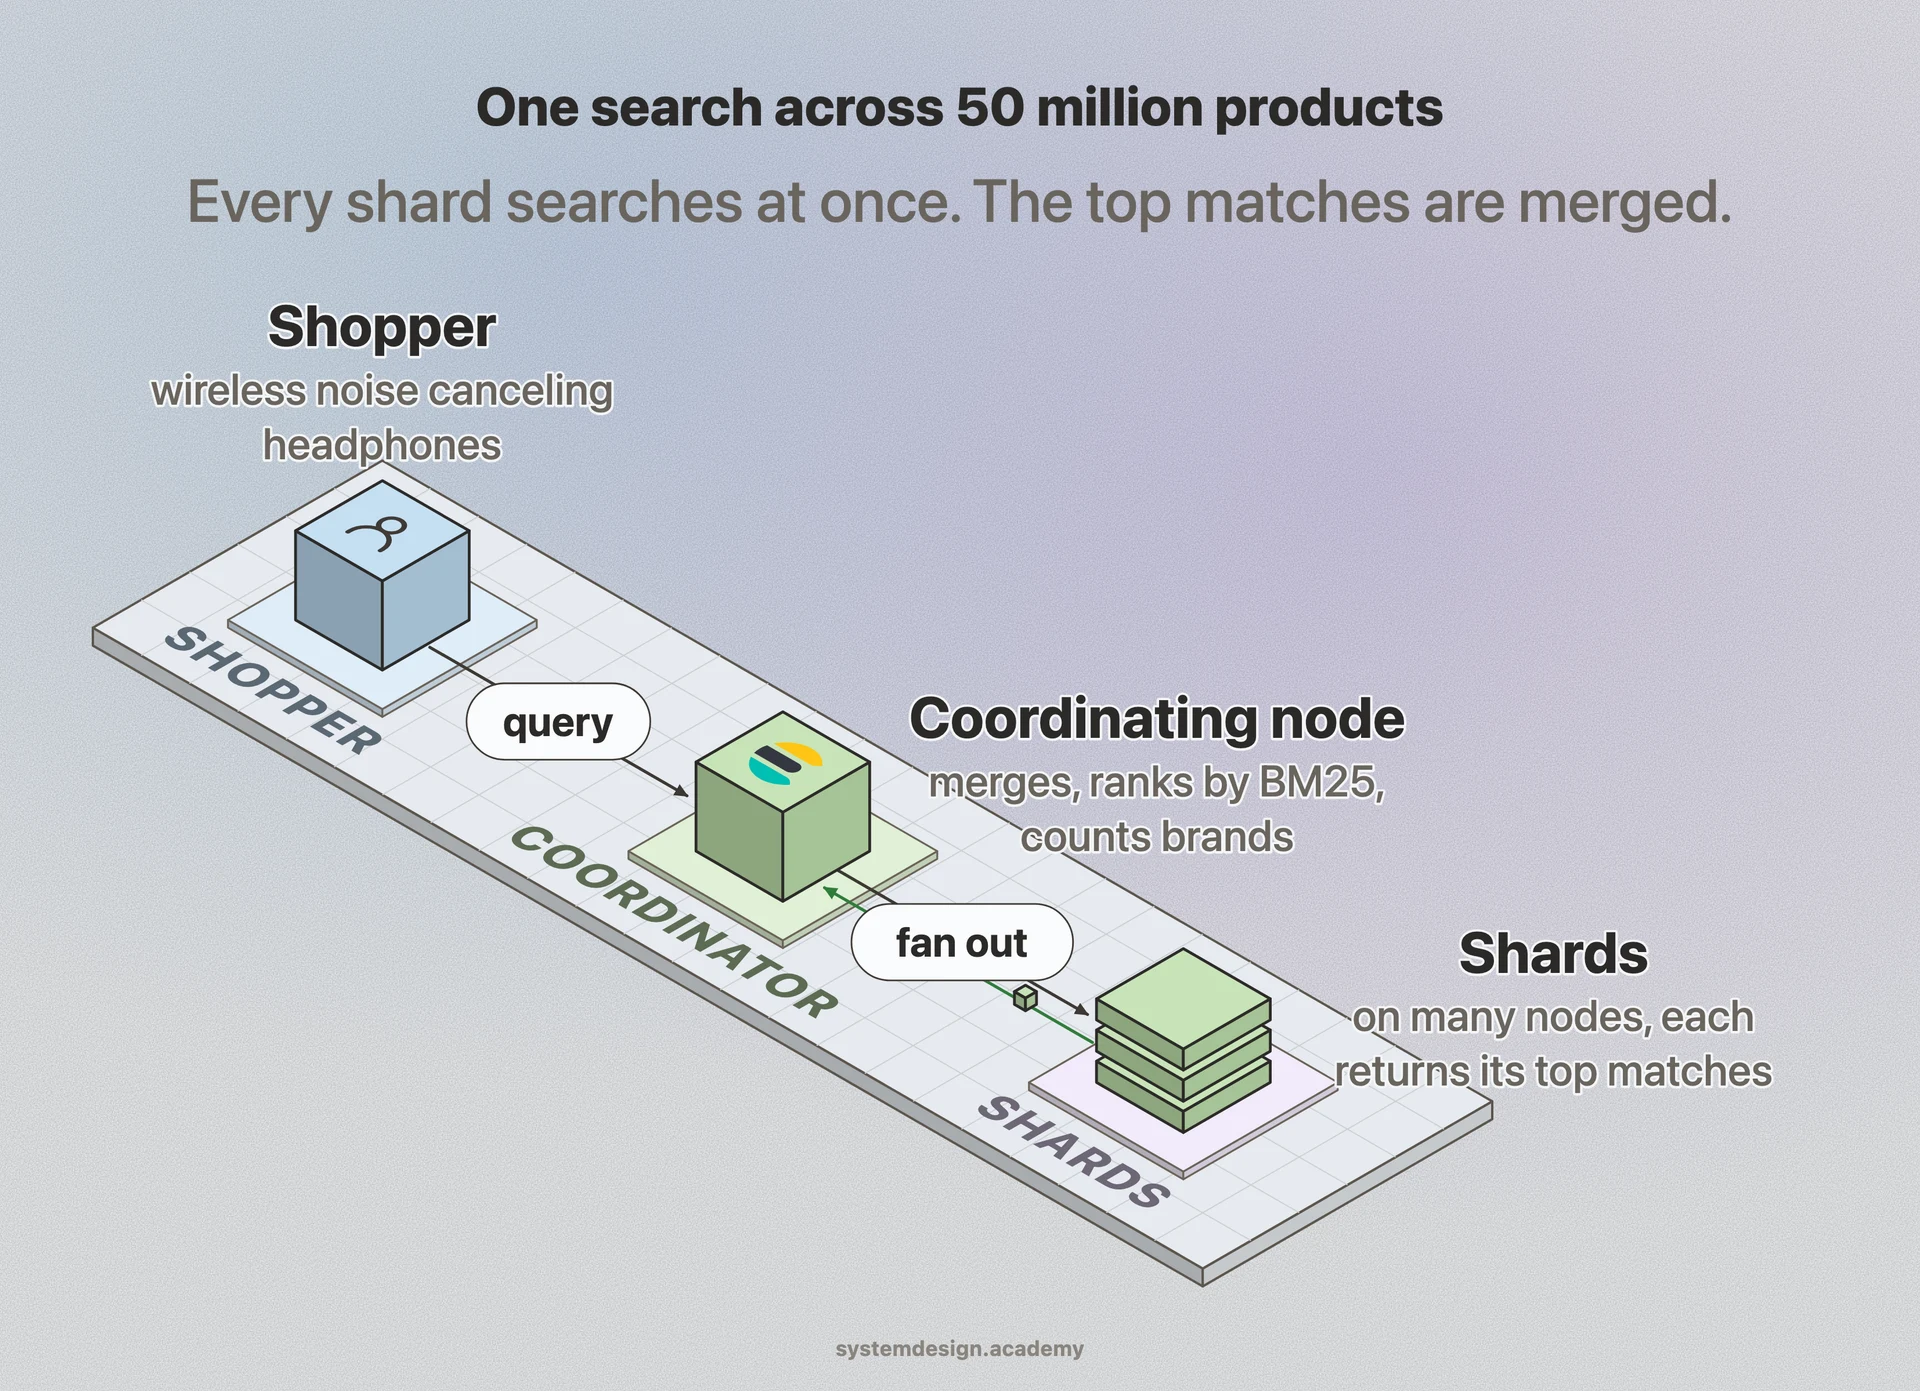
Each Elasticsearch index is divided into shards. A shard is a complete, self contained Lucene index. When you index a document, Elasticsearch hashes the document id to pick a shard, so writes spread evenly across nodes. When you search, the query fans out to every shard in parallel, each shard returns its top matches, and a coordinating node merges the results. This scatter gather pattern is why search stays fast as data grows: you add nodes and shards rather than making one machine bigger.
The inverted index is the heart of it. For every term in your text, Lucene keeps a sorted list of which documents contain it and where. Searching for a word becomes a lookup in that list rather than a scan. Numeric and date fields use a different structure called BKD trees for range queries, and exact match fields use doc values stored column wise for fast sorting and aggregation.
Writes are not immediately searchable. New documents go into an in memory buffer plus a translog for durability, and Elasticsearch flushes them into a new searchable segment on a refresh interval, which defaults to one second. This is called near real time search. Segments are immutable, so deletes are just tombstones and updates are delete plus reindex, with a background merge process compacting small segments into larger ones.
Replicas serve two jobs. They protect against a node dying, and they also serve read traffic, so adding replicas increases search throughput. A write must succeed on the primary shard and is then copied to its replicas before it is acknowledged.