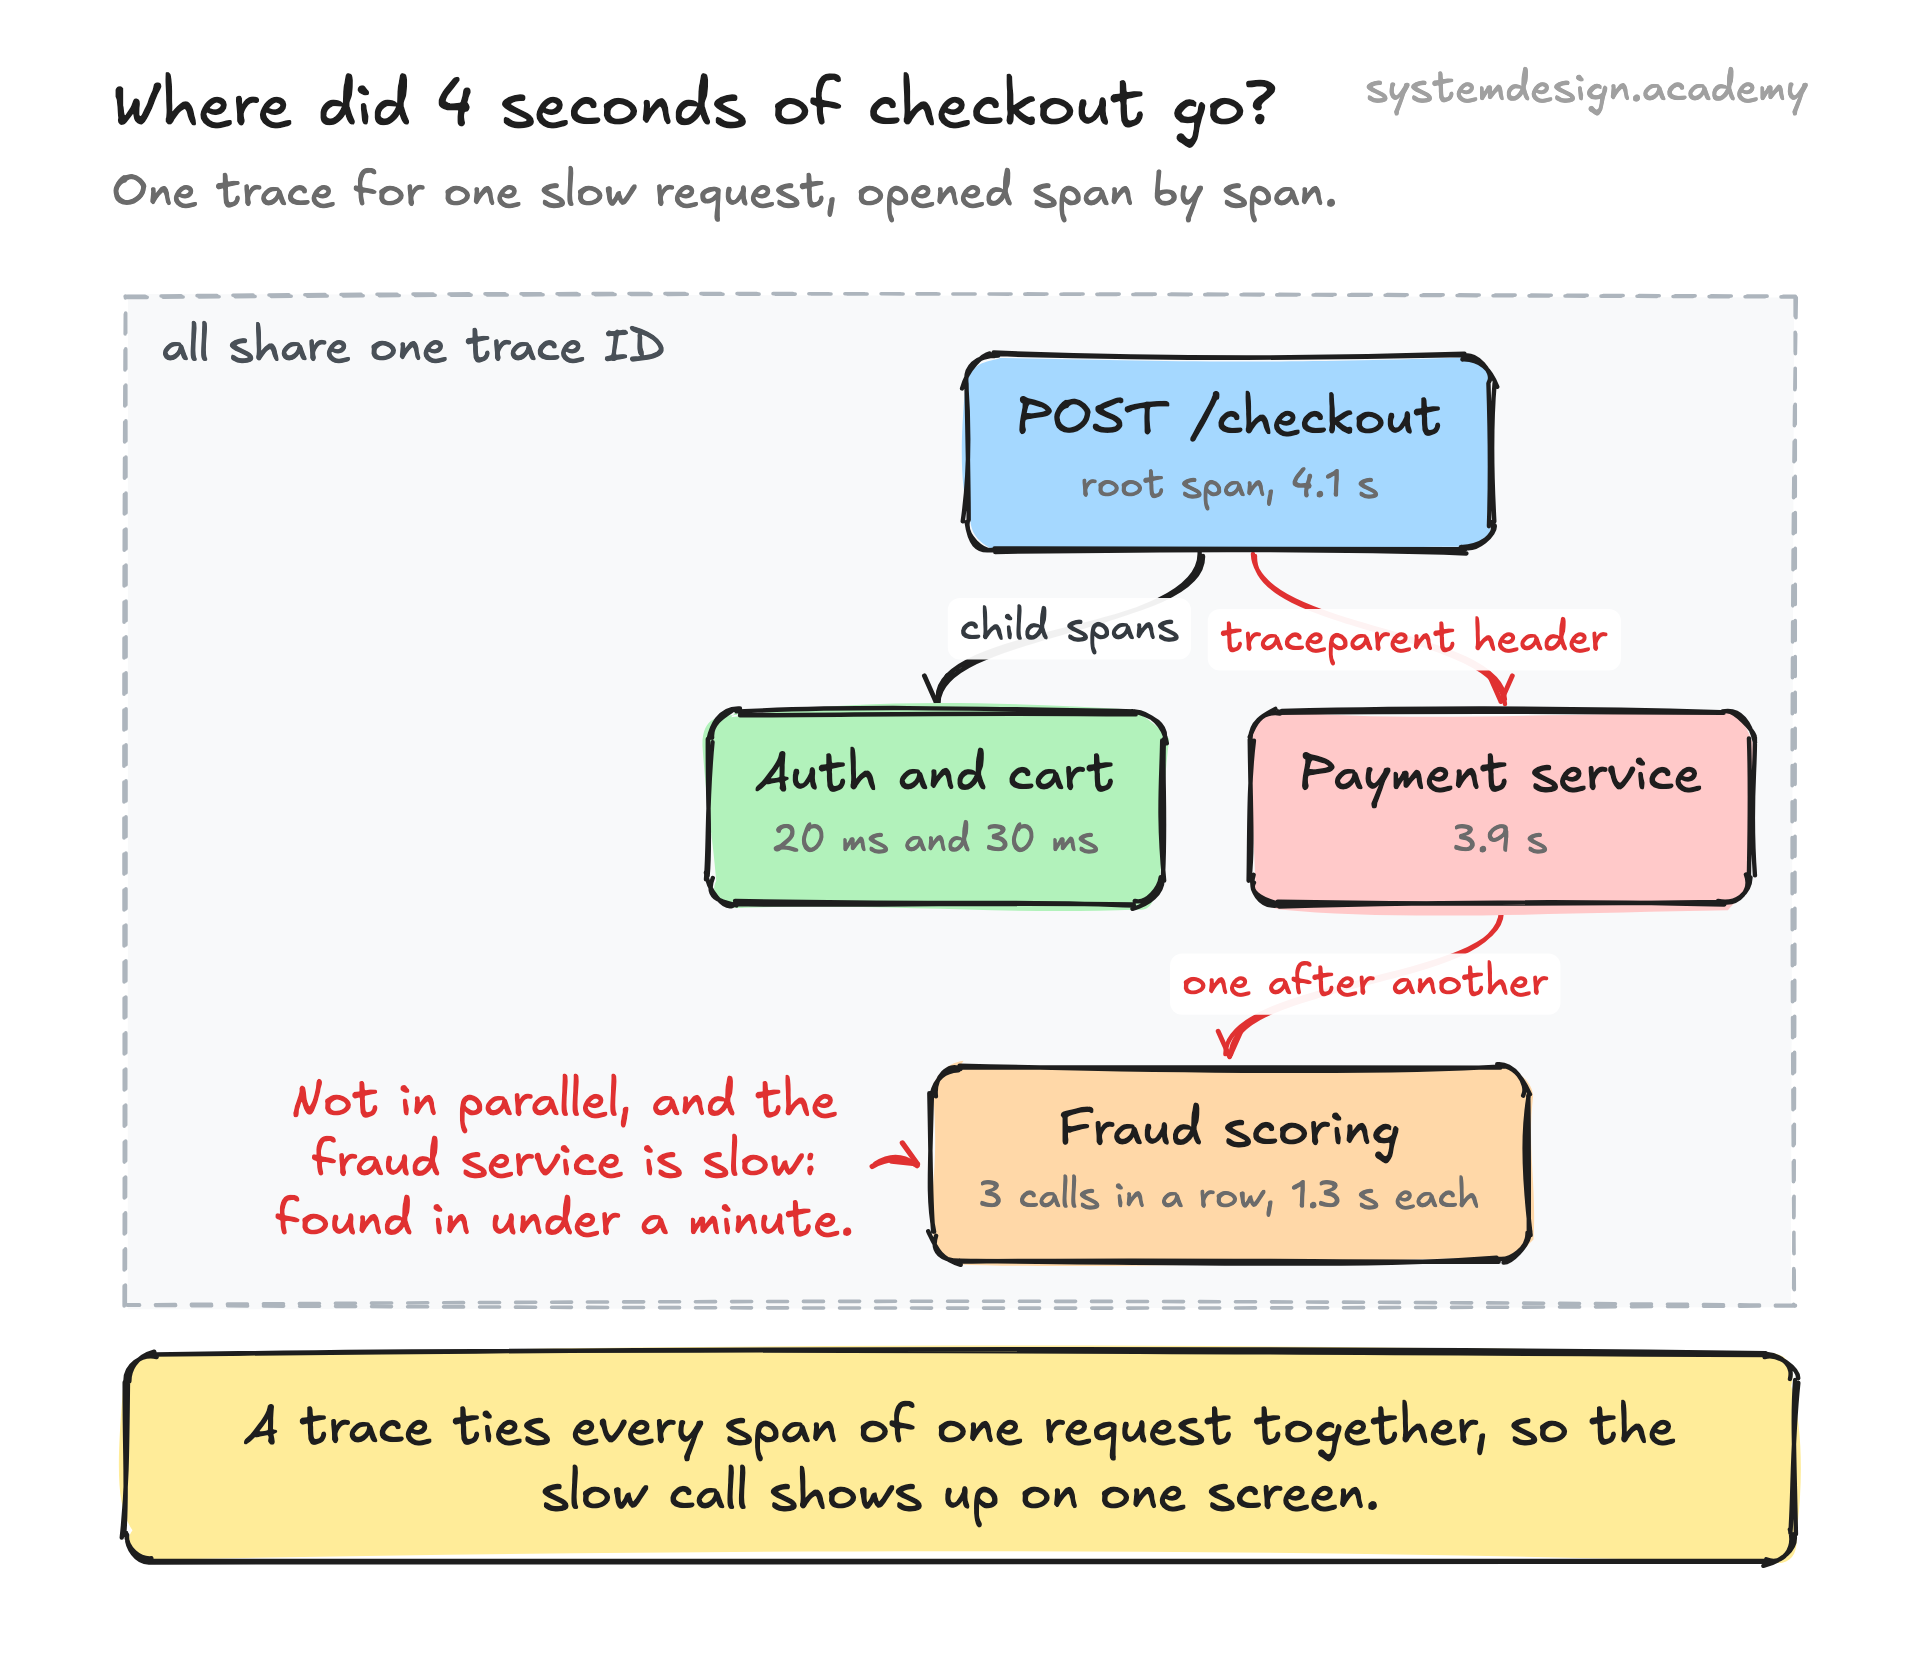
In a monolith, when a request is slow you read one log file and one stack trace. In a system built from 30 microservices, a single click might touch an API gateway, an auth service, a product service, a pricing service, a cache, and three databases. A normal log line tells you that one service was slow, but not which downstream call caused it. Distributed tracing fixes that by stitching all of those steps into one record.
A trace represents the full journey of one request. It is made up of spans. A span is one unit of work, like an HTTP call, a database query, or a function execution. Each span has a start time, a duration, a name, and a set of tags such as the HTTP status code or the SQL statement. Spans link to a parent span, so the whole trace forms a tree that mirrors how services called each other.
The piece that makes it work across machines is context propagation. The first service generates a trace ID and a span ID, then passes them in the request headers to the next service. Every service reuses the same trace ID and creates a new span underneath. When all the spans are sent to a central backend and joined on the trace ID, you get one connected picture instead of dozens of disconnected logs.