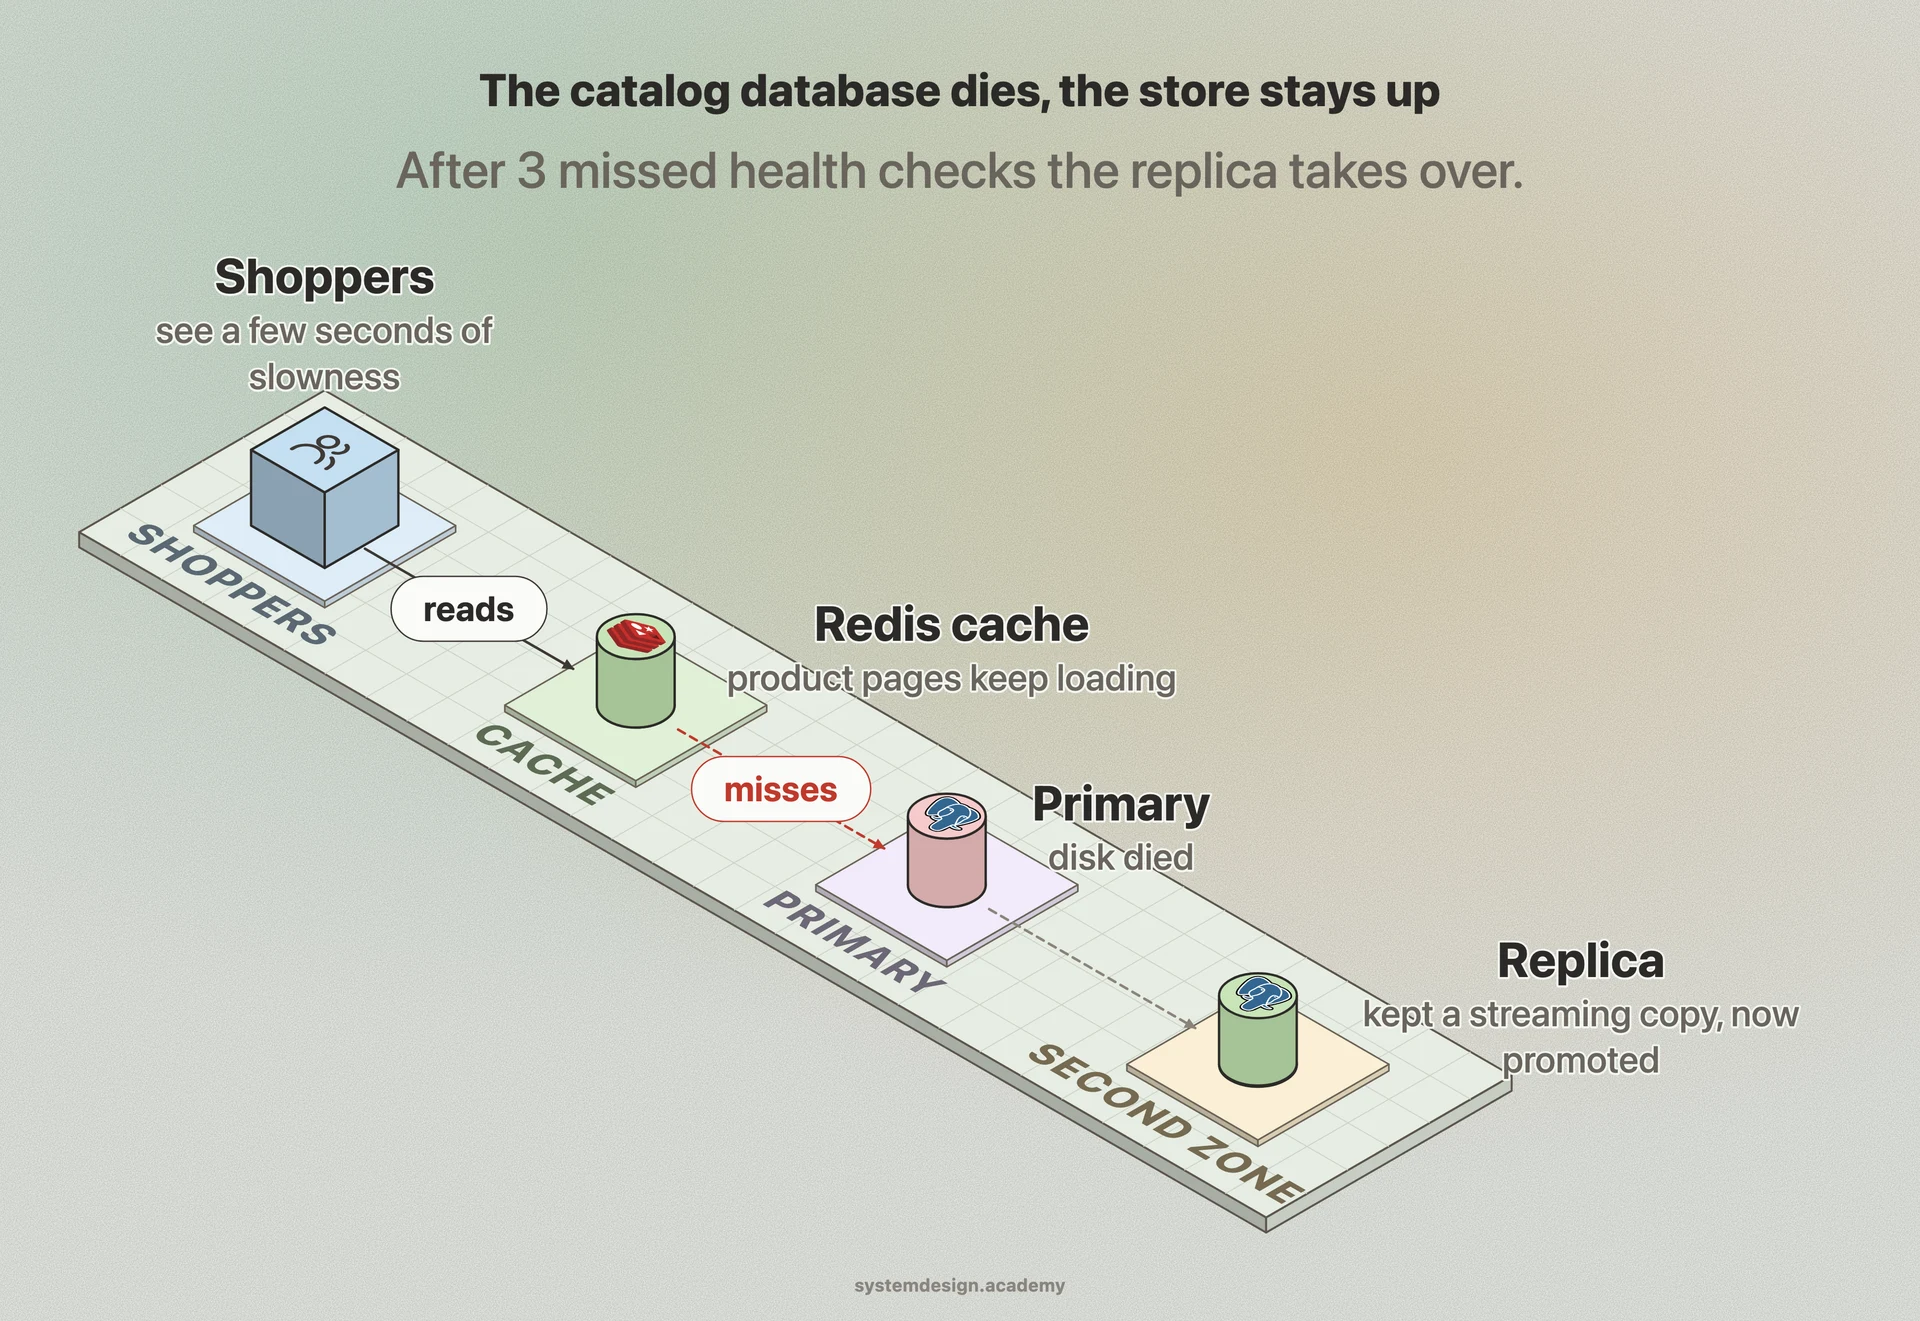
The foundation is redundancy: never have exactly one of anything on the critical path. Run multiple application servers behind a load balancer, store data on multiple disks (RAID), and replicate that data across multiple machines and availability zones. If one copy dies, another takes over.
Redundancy is useless without failure detection. Systems use health checks and heartbeats: a load balancer pings each server every few seconds, and a node that misses several heartbeats in a row is marked dead and removed from rotation. Timeouts catch the case where a component is slow rather than crashed.
Once a failure is detected, the system has to recover. Failover promotes a standby to take over (a replica database is promoted to primary). Retries with exponential backoff handle transient errors. Circuit breakers stop hammering a dependency that is already down. Graceful degradation means shedding non-essential features so the core keeps working, for example serving stale cached data when the database is unreachable.
Distributed systems add a hard constraint: to tolerate the failure of N nodes through consensus, you typically need 2N plus 1 replicas so a majority can still agree. Protocols like Raft and Paxos use this quorum rule to keep data consistent even while some nodes are down.