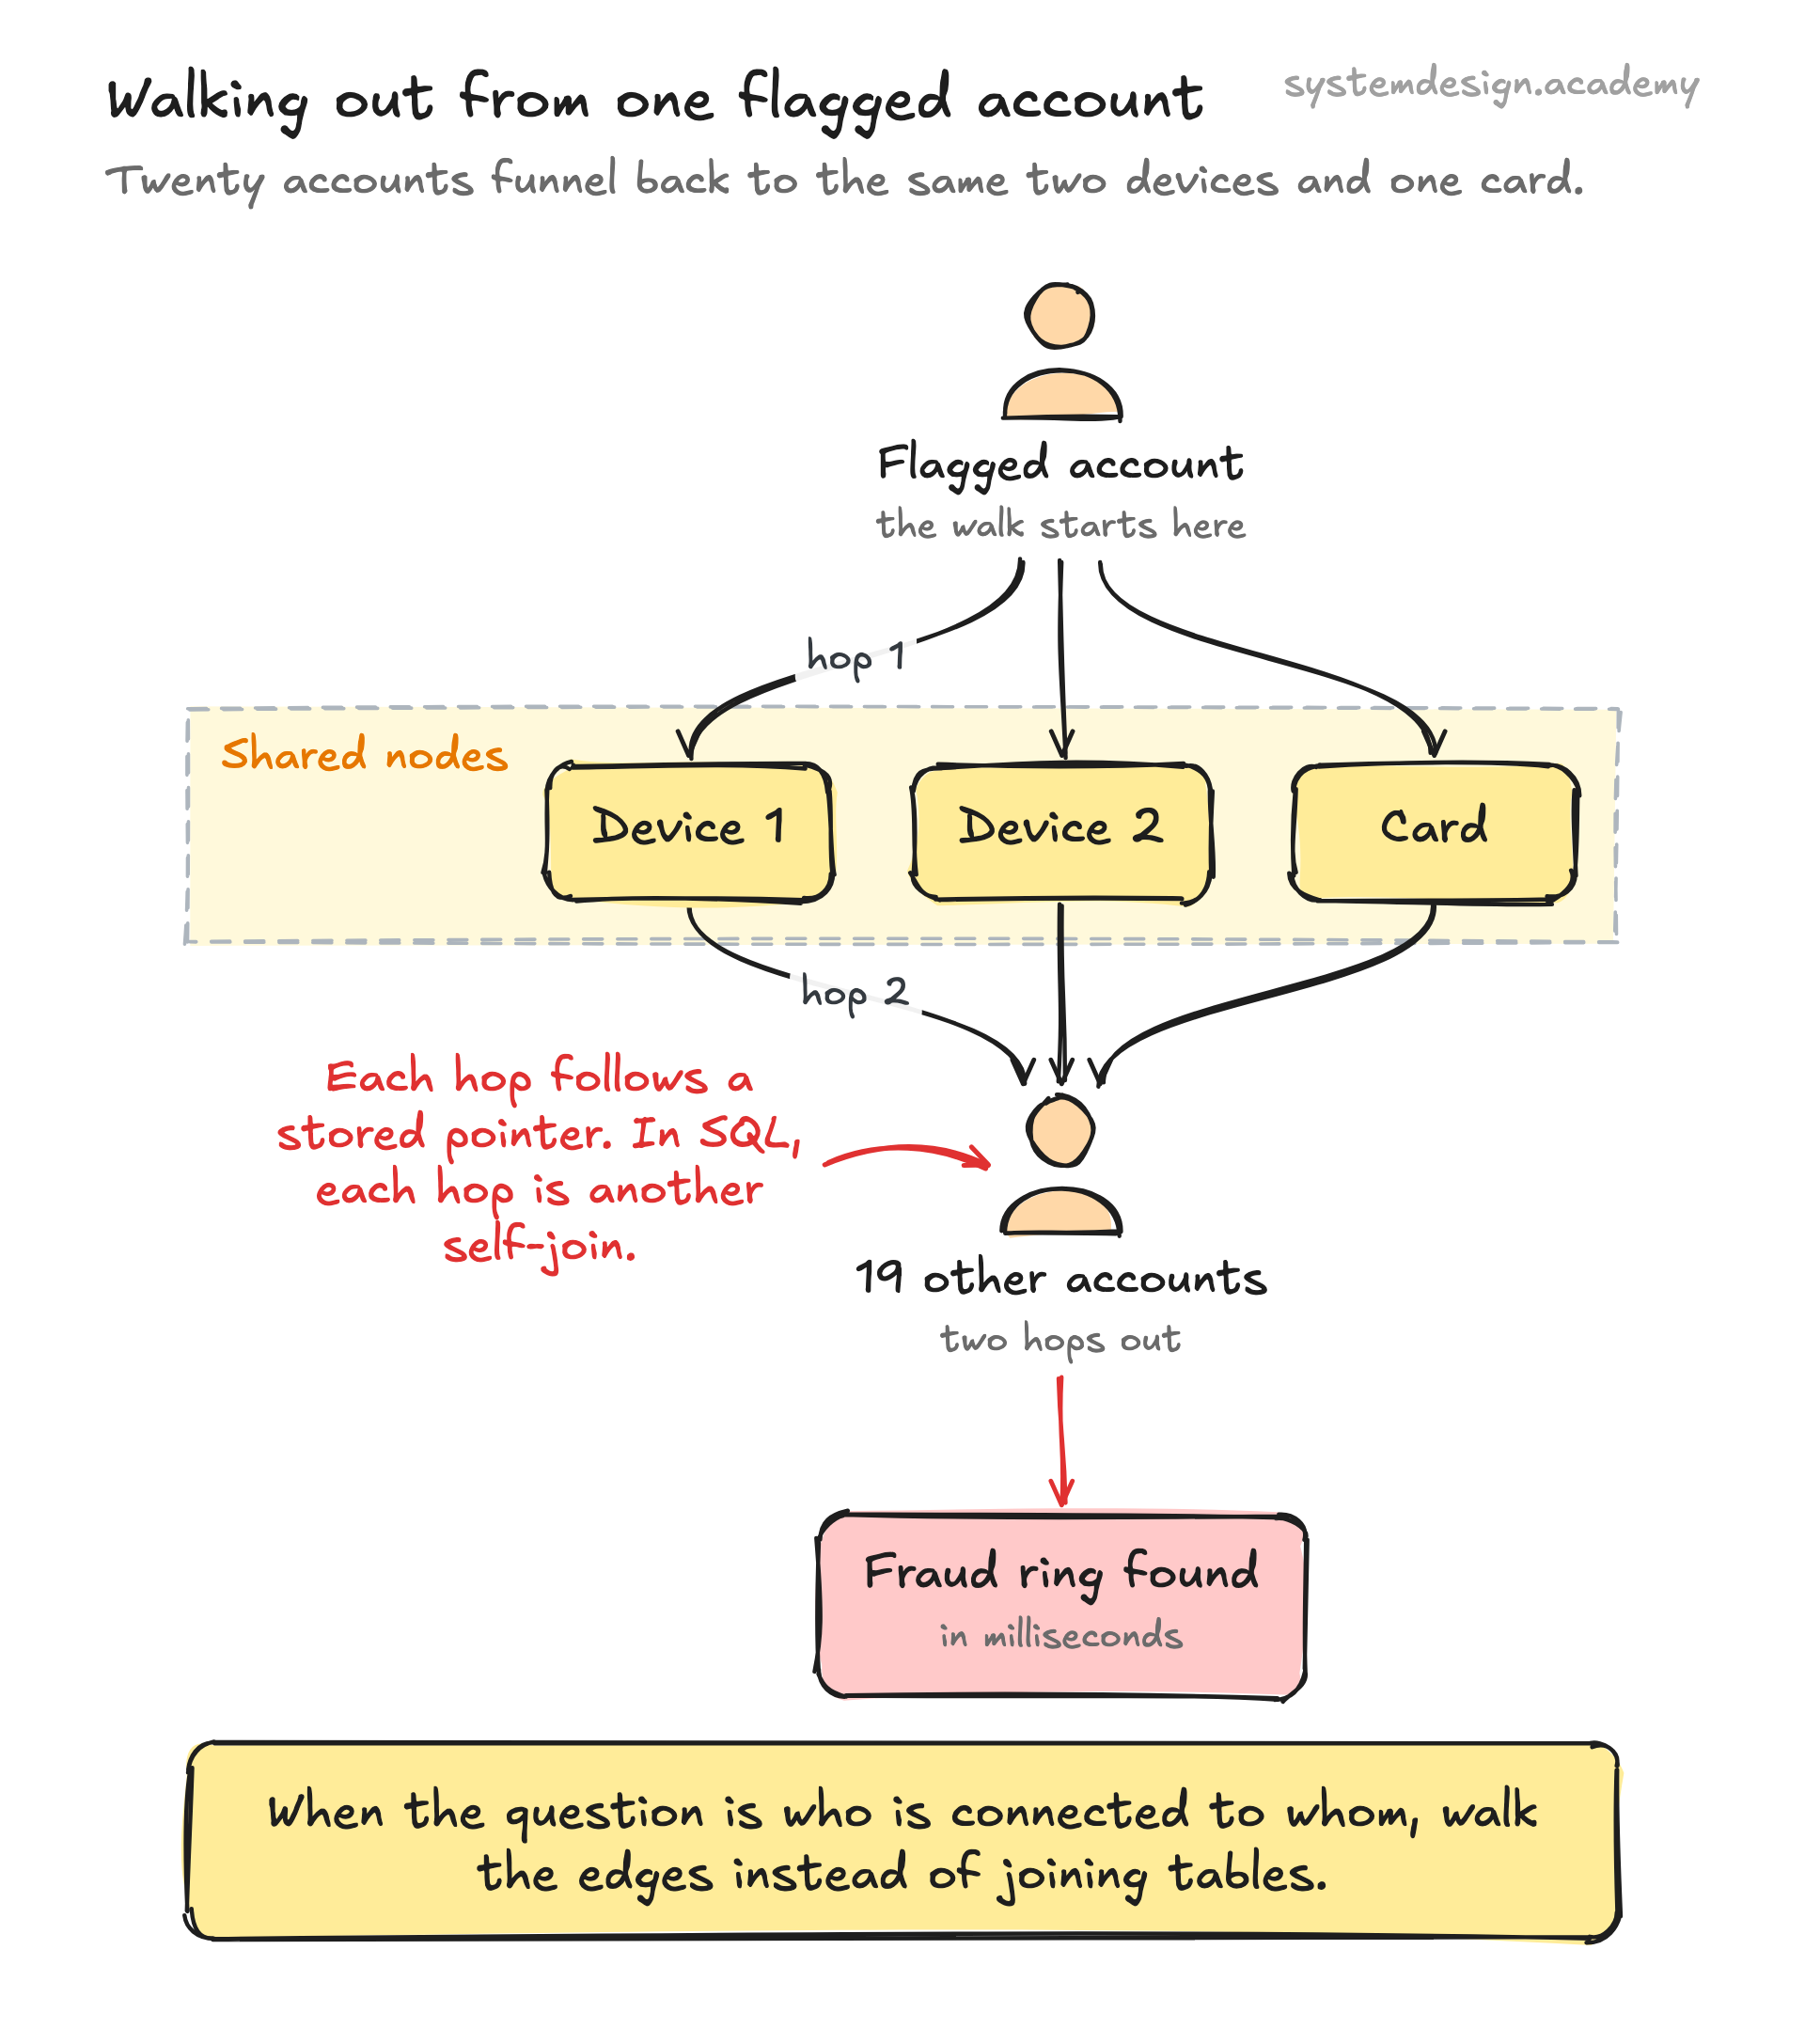
A graph database models data the way you would draw it on a whiteboard. Each thing is a node: a person, an account, a product, a server. Each connection between two things is an edge: FOLLOWS, PAID, BOUGHT, DEPENDS_ON. Both nodes and edges can carry properties, so a Person node holds name and age, and a PAID edge holds amount and timestamp.
The defining feature is how relationships are stored. In a relational database, a relationship between two rows is implied by matching a foreign key, and you reconstruct it at query time with a JOIN. In a native graph database, each edge is stored physically next to the nodes it connects, with a direct pointer. The engine calls this index-free adjacency: to walk from a node to its neighbors, it follows pointers rather than scanning or indexing a join table.
Most graph databases use one of two models. The property graph model (Neo4j, Amazon Neptune, Memgraph) uses labeled nodes and edges with key-value properties. The RDF triple model (used in semantic web and knowledge graphs) stores facts as subject-predicate-object triples. Property graphs dominate application development today.