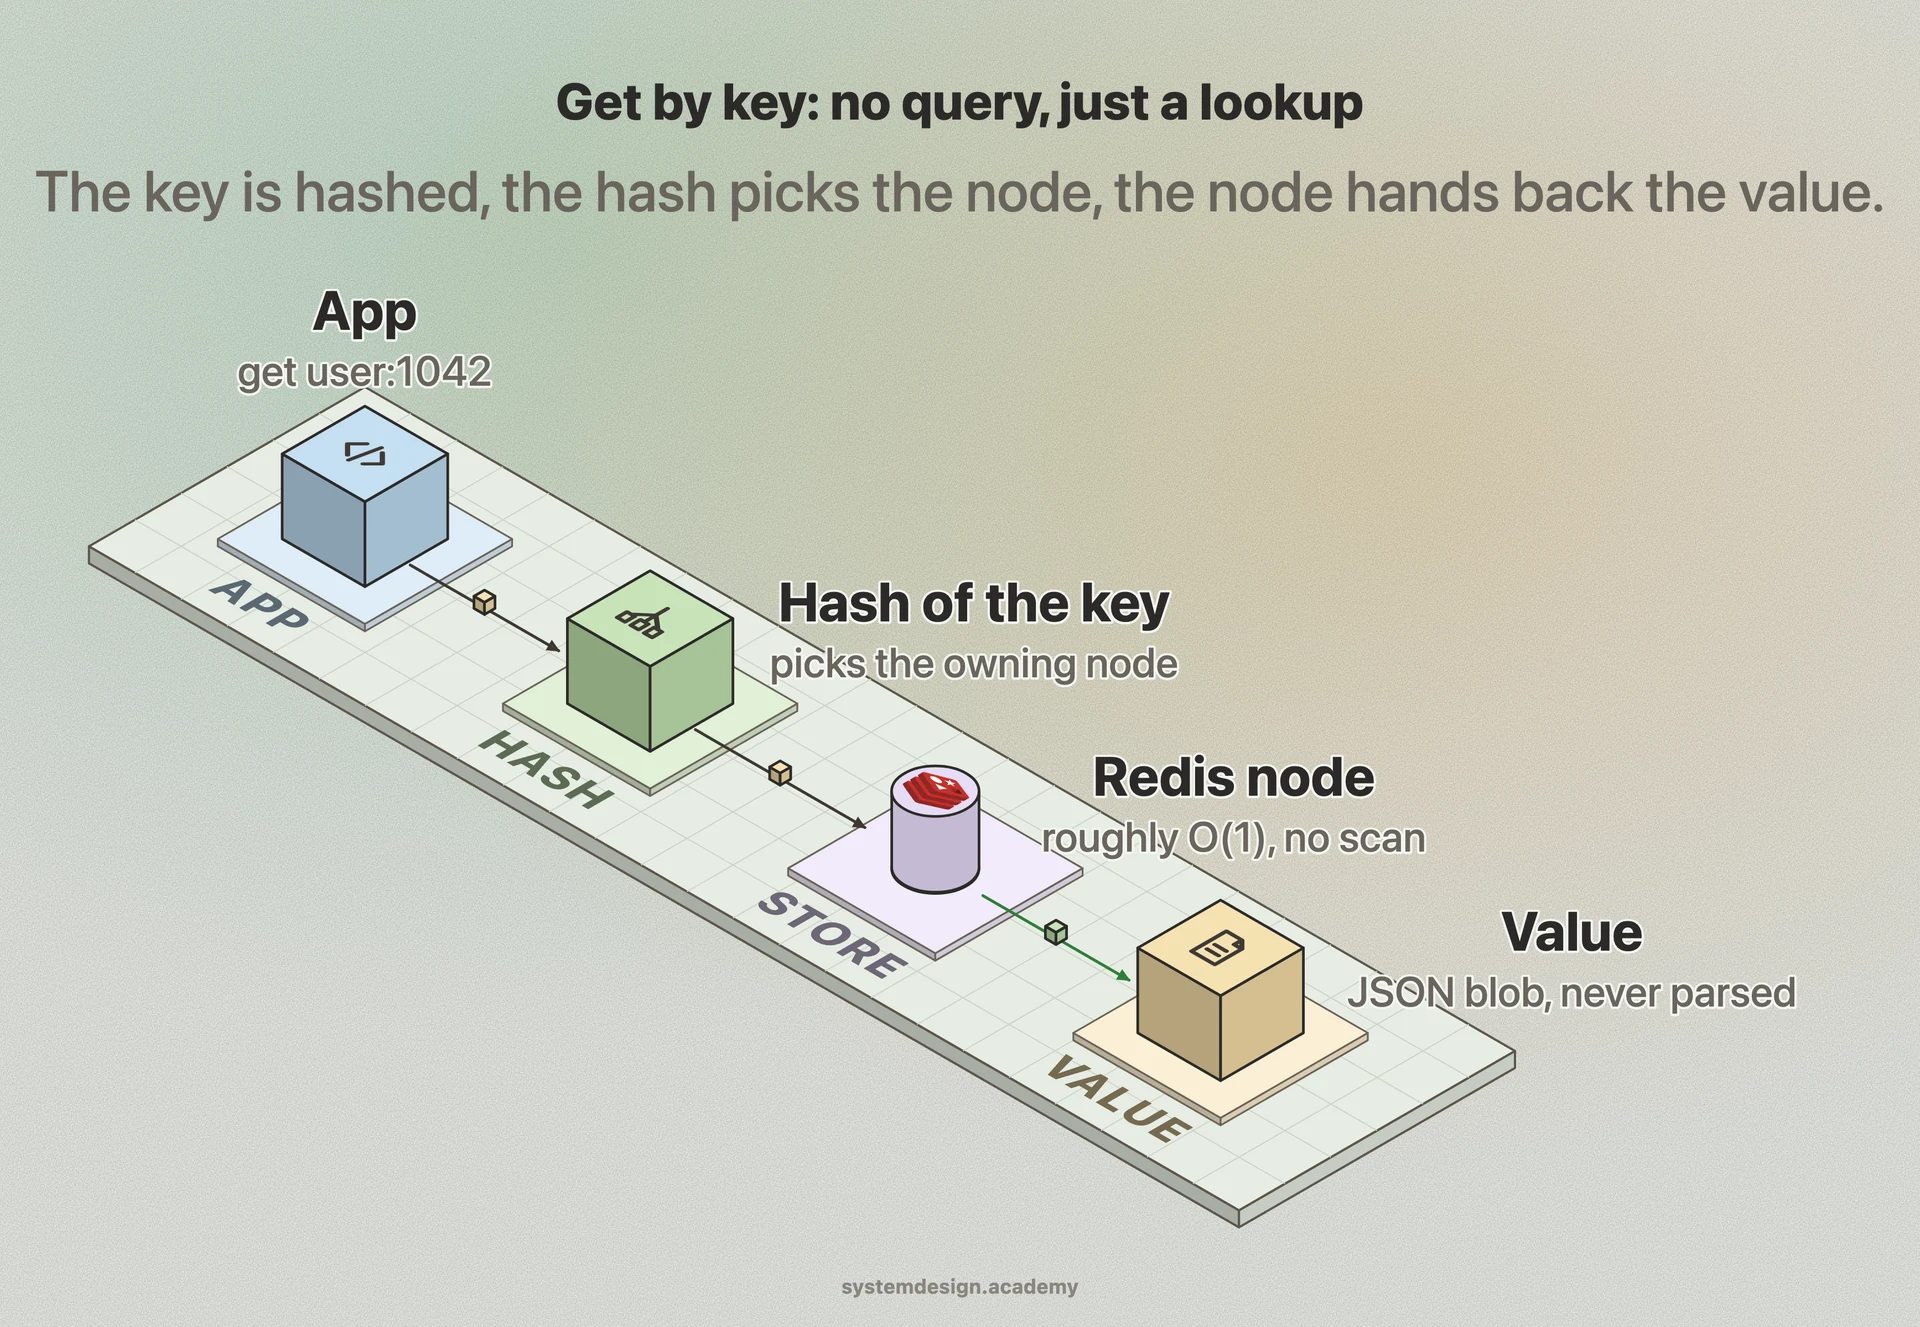
Reach for a key-value store when your access pattern is known in advance and is almost always by primary key. Session storage, user profiles fetched by id, shopping carts, feature flags, rate-limit counters, and caching layers in front of a slower database are the classic fits. If you can always answer with the key, this model is hard to beat on speed and scale.
The cost is query flexibility. You cannot say find all users in London who signed up last week unless you have built a separate index keyed on that question. There are no joins, no GROUP BY, and usually weak or no support for range scans across arbitrary fields. Every new access pattern means designing a new key or maintaining a secondary index yourself.
Many real systems use a key-value store alongside a relational database rather than instead of one. Postgres or MySQL holds the source of truth and supports rich queries, while Redis or DynamoDB serves the hot, high-volume reads. The other common gotcha is that in-memory stores are bounded by RAM, so you must set eviction policies and accept that data can be lost on a crash unless persistence or replication is configured.