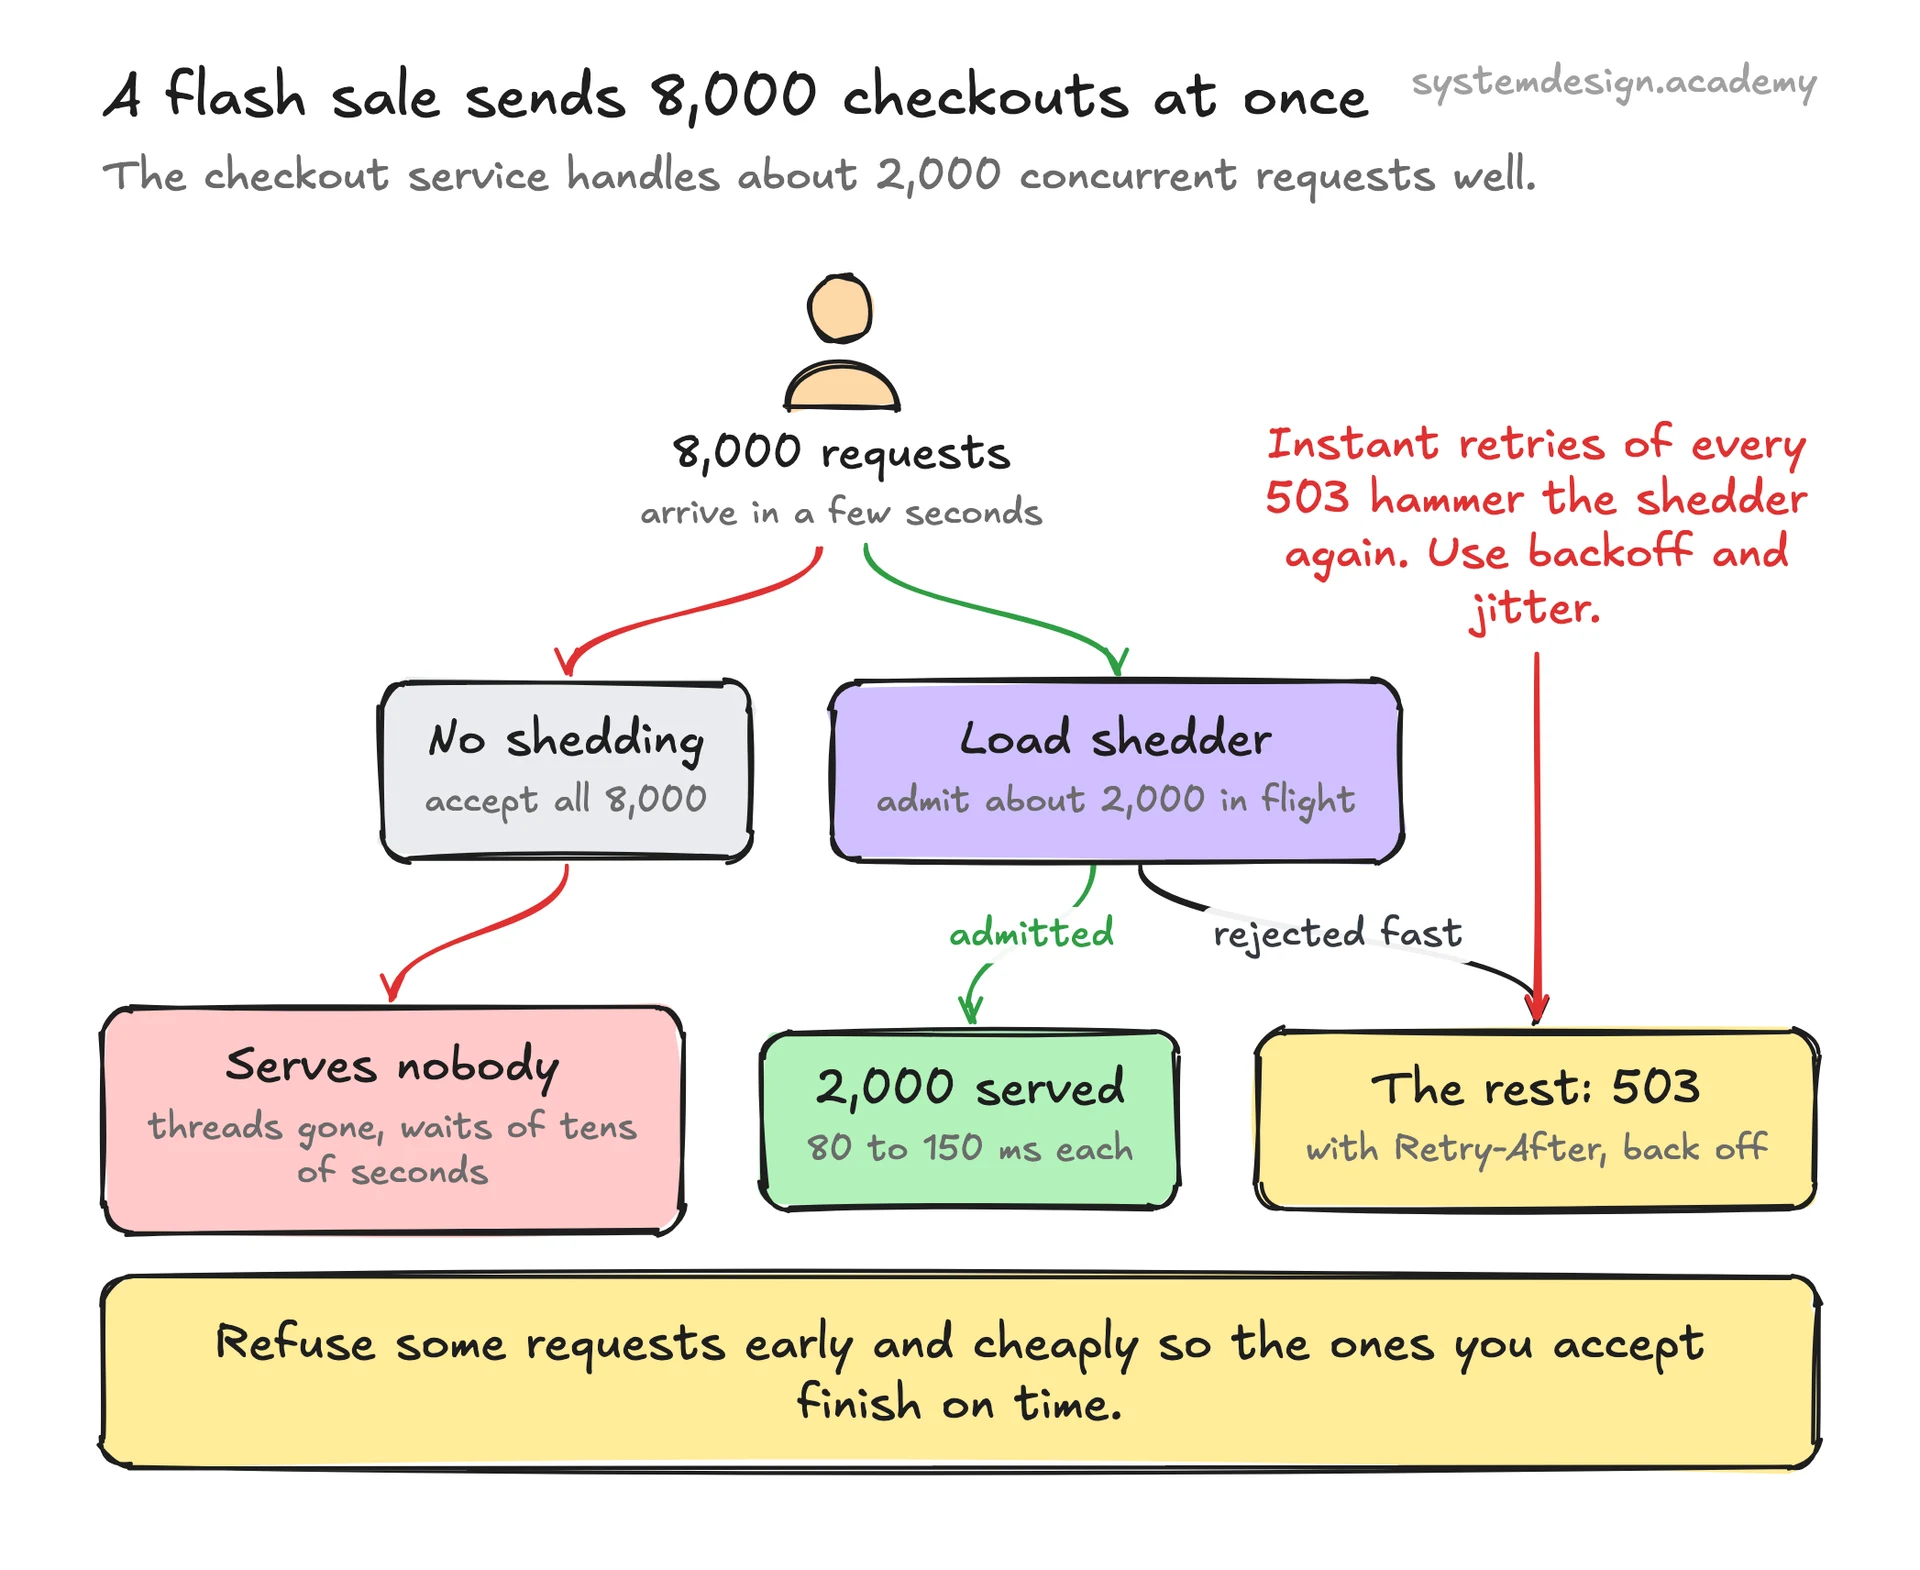
Imagine a checkout service that can comfortably handle 2,000 concurrent requests and starts degrading past that. On a flash sale, traffic jumps to 8,000 concurrent requests in a few seconds. Without shedding, all 8,000 requests get accepted, the thread pool exhausts, queue latency climbs to tens of seconds, downstream timeouts fire, and the service effectively serves nobody.
With load shedding, the server admits roughly 2,000 in-flight requests and immediately returns 503 with Retry-After to the rest. Those 2,000 complete in normal time, around 80 to 150 milliseconds. The shed clients back off and retry a moment later, and as the surge passes they get through. The service stays up the entire time and processes far more successful checkouts than it would have if it had tried to accept everything.
AWS describes this pattern in its Builders' Library: shed work at the edge, prioritize by request type, and measure goodput rather than raw request count. The lesson from production is consistent across companies. A service that gracefully refuses excess load survives spikes that would otherwise turn into multi-hour outages.