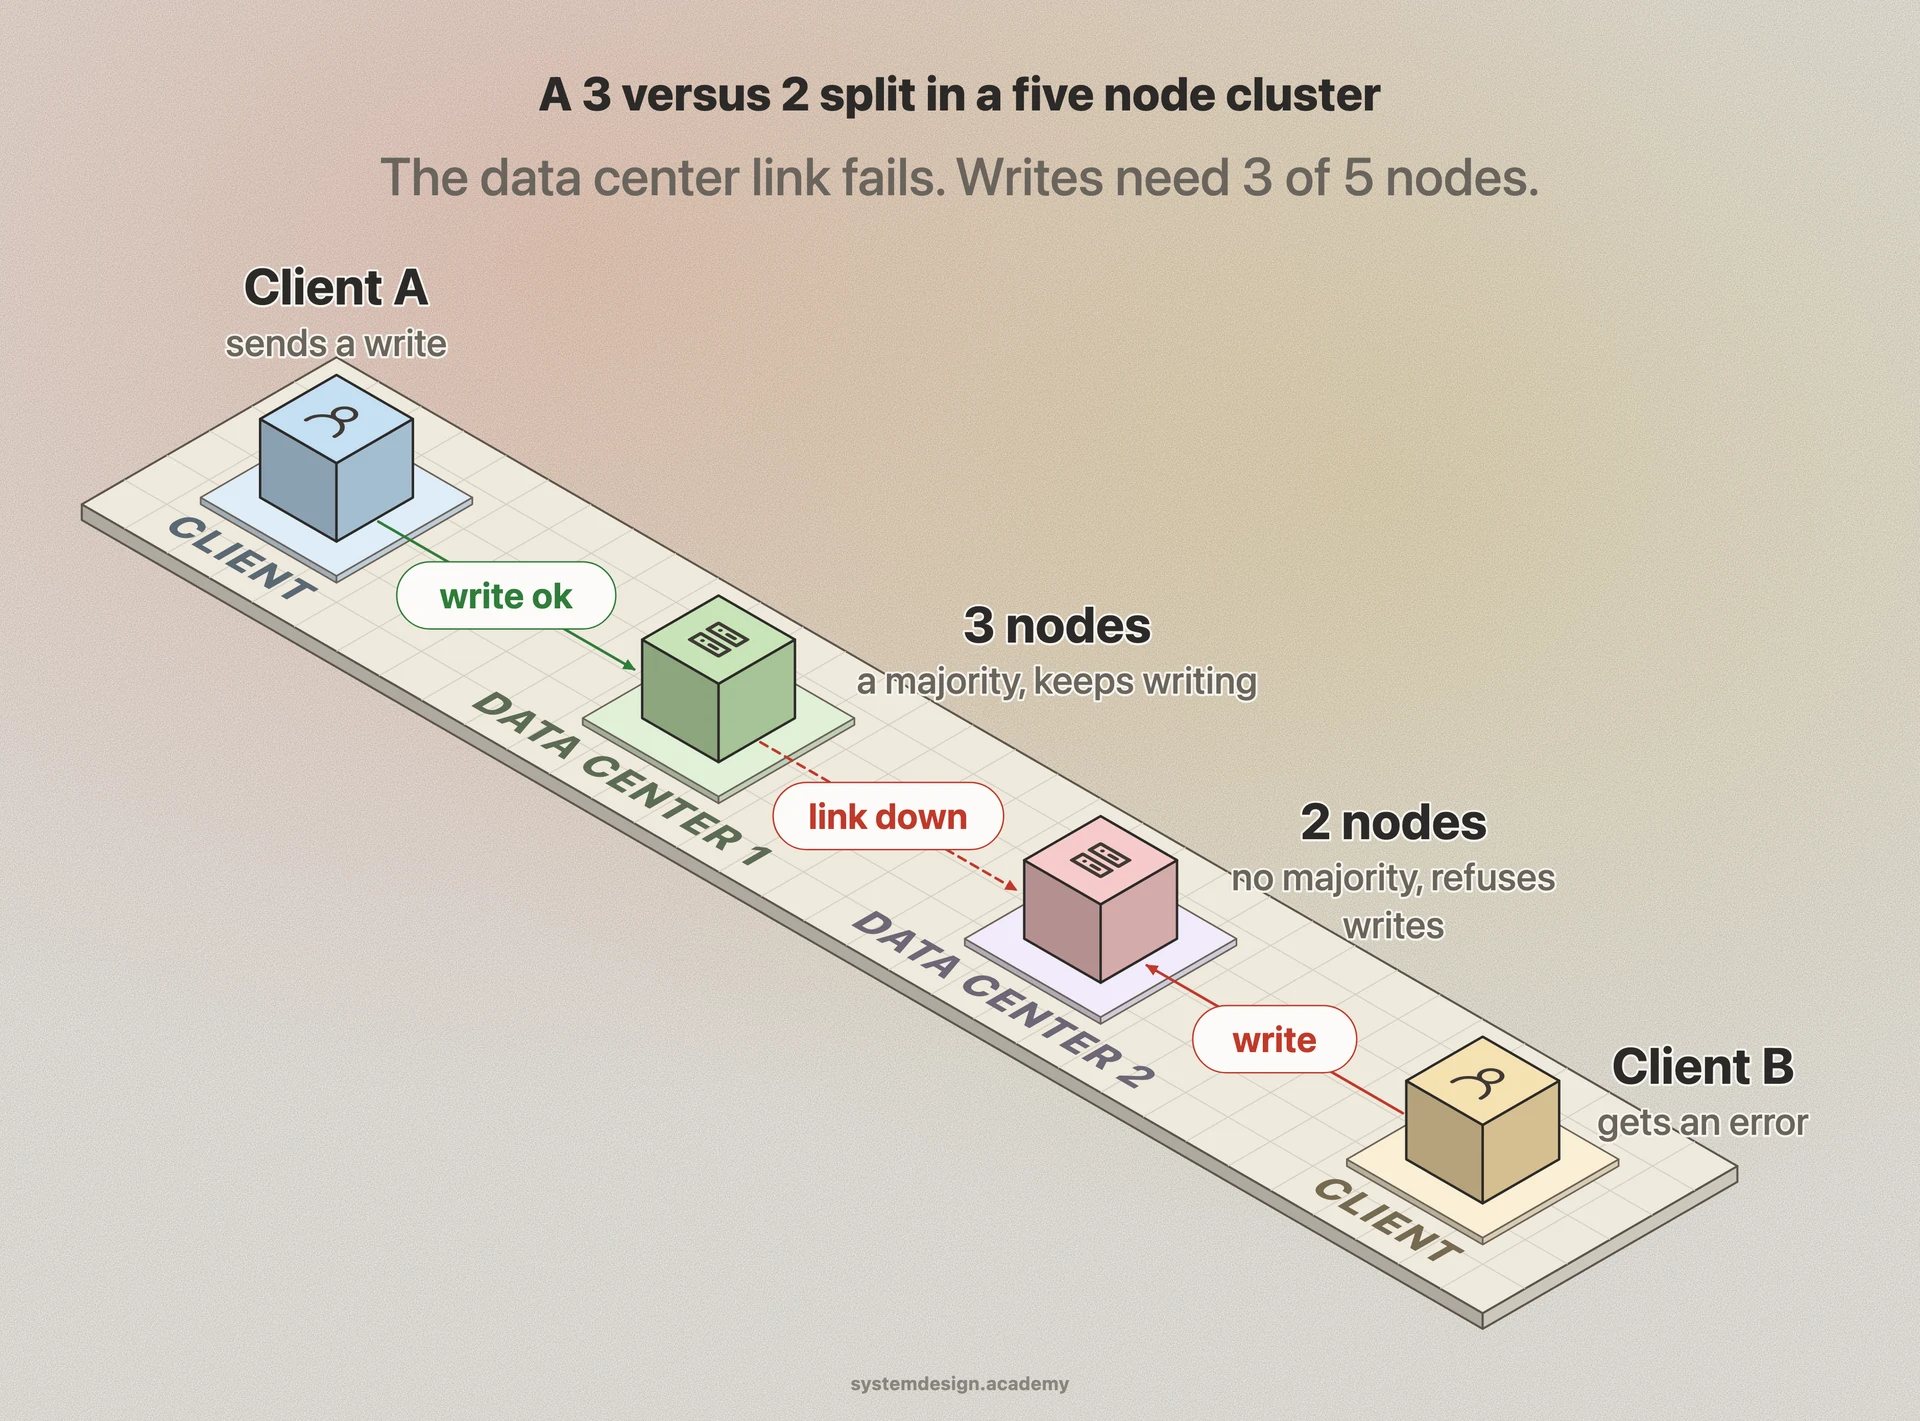
Picture a cluster of five database servers spread across two data centers, three in one and two in the other. They normally talk over the network constantly: replicating writes, running health checks, electing a leader. Now imagine the link between the two data centers goes down. The three nodes on one side can still talk to each other, the two nodes on the other side can still talk to each other, but the two groups cannot reach across. That is a network partition. The cluster is split into islands.
The important and counterintuitive part is that none of the nodes have crashed. Every server is up, healthy, and serving requests. From inside each island the rest of the cluster simply looks dead, because a node that does not respond looks identical to a node that is unreachable. A server cannot tell the difference between a peer that has failed and a peer it just cannot reach.
Partitions are not exotic. They come from a switch reboot, a misconfigured firewall rule, a cut fiber line, a cloud availability zone losing connectivity, or even a garbage collection pause long enough that a node stops answering heartbeats. Anything that interrupts communication between nodes for long enough counts.