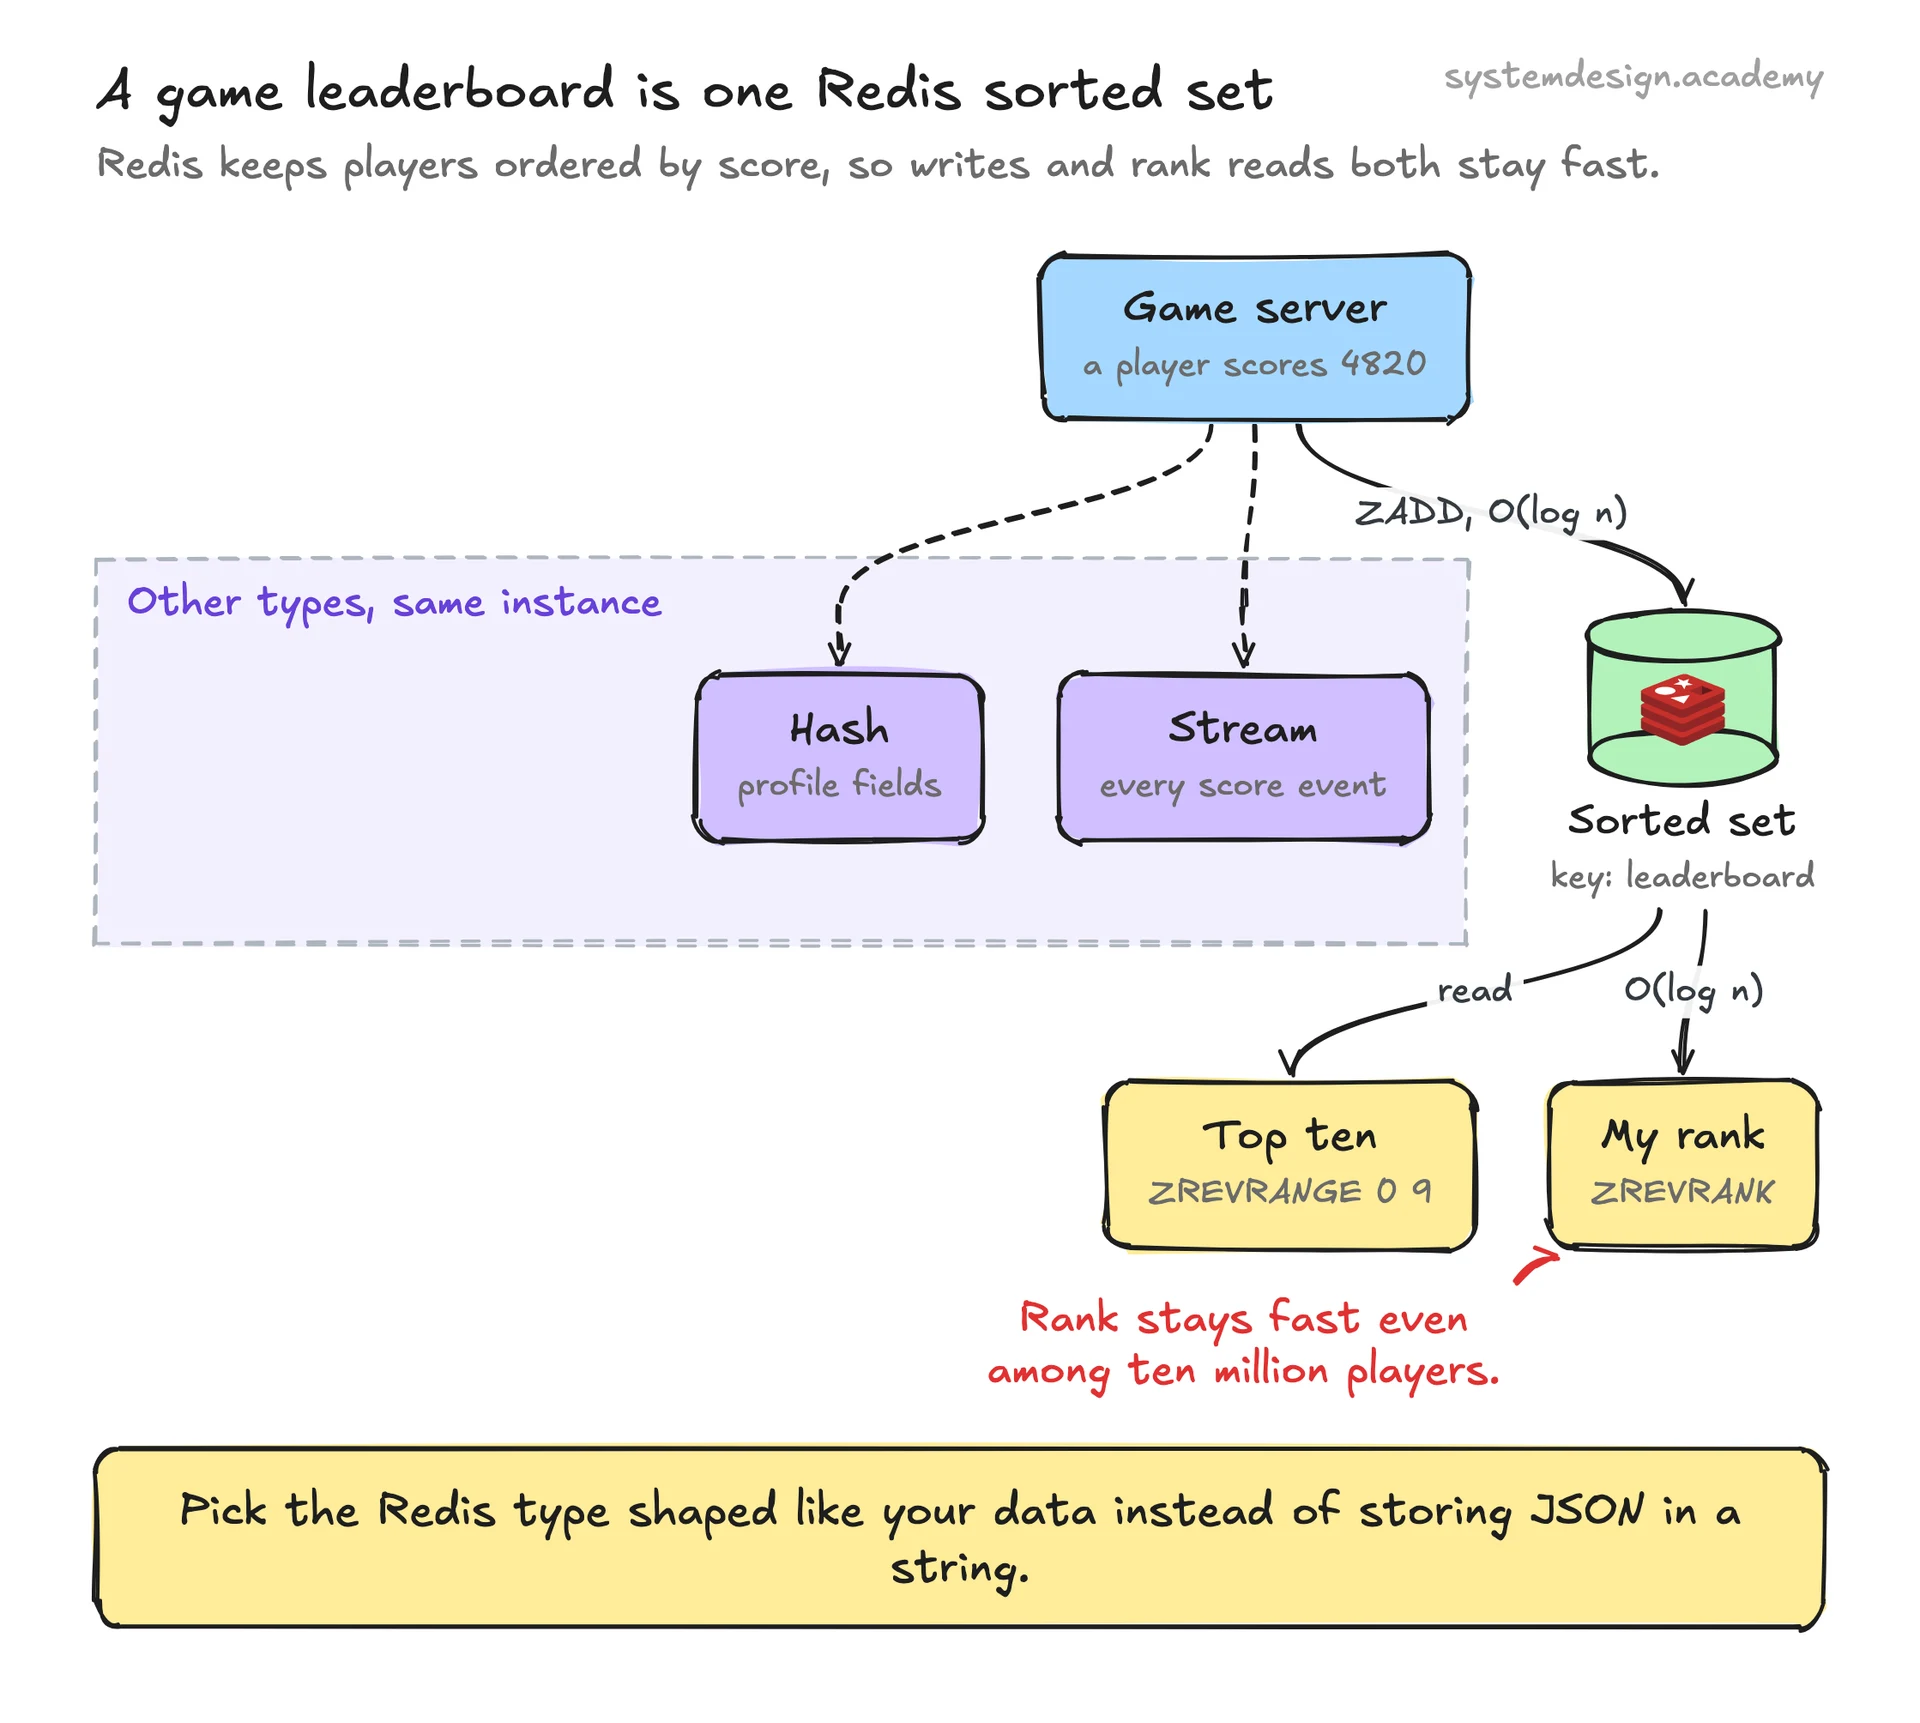
Reach for the matching type instead of serializing JSON into a string. Use a hash for an object you update field by field, like a user session, so you can HSET one field without rewriting the whole thing. Use a sorted set for anything ranked or time-ordered: leaderboards, rate limiters keyed by timestamp, priority queues. Use a list for simple queues and recent-activity feeds. Use a set for membership and tags, and SINTER or SUNION for things like mutual followers. Use a stream when you need a durable event log with multiple consumers that each track their own position.
The hard limit is memory. Everything lives in RAM, so a 50 GB dataset needs roughly 50 GB plus overhead, which is far more expensive than disk. Persistence with RDB snapshots or the AOF log protects against restarts but does not change the working set size. Watch out for big collections too: a command like ZRANGE over a million-member set, or KEYS in production, can block the single thread and stall every other client.
HyperLogLog is the classic trade-off example. It estimates the number of unique items in about 12 KB regardless of cardinality, with roughly 0.81 percent error. You give up exact counts and the ability to list members, and in return you count billions of uniques in a fixed tiny space.