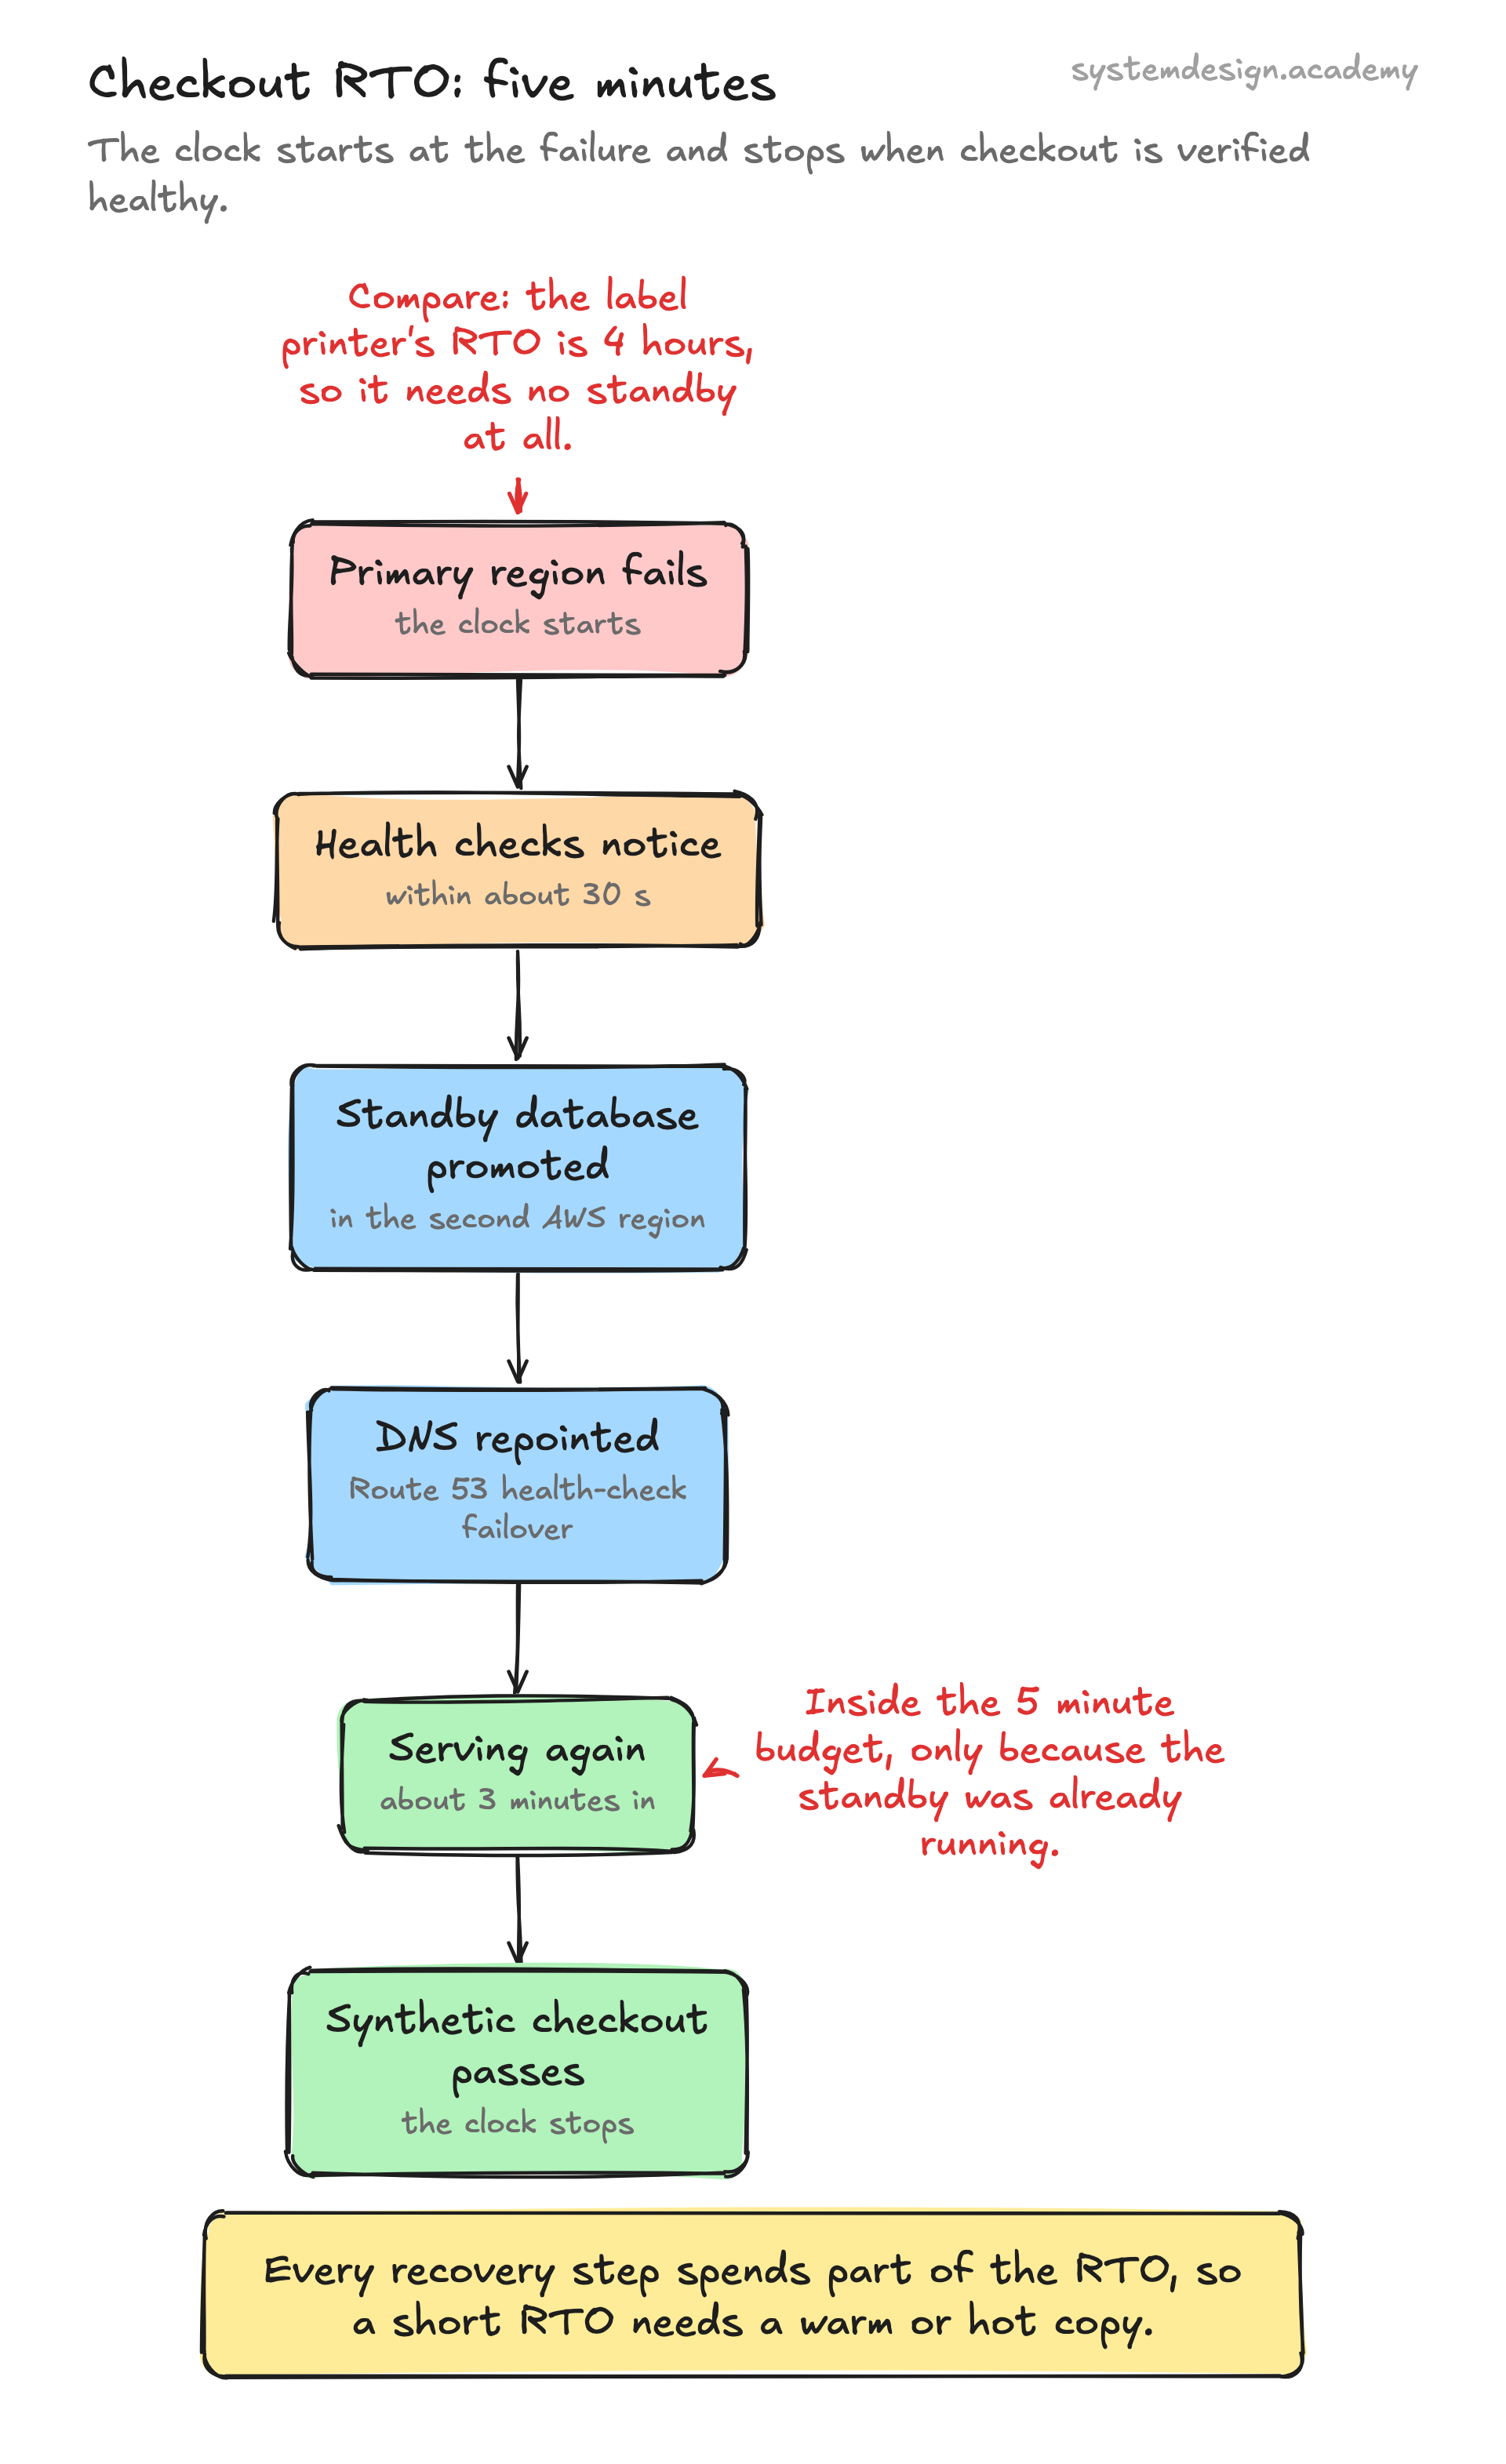
The recovery clock starts at the moment of failure and stops when the service is verified healthy again. Every step in between eats into the budget: detecting the outage, deciding to fail over, spinning up replacement capacity, restoring or promoting a database, repointing DNS or load balancers, and running smoke tests before declaring success.
A short RTO forces you toward hot standby. You keep a fully running copy of the system in another availability zone or region, replicating data continuously, ready to take traffic in seconds. This is the most expensive option because you pay for idle duplicate capacity, but it is how you reach an RTO measured in seconds or low minutes.
A longer RTO lets you use cheaper patterns. Warm standby keeps a scaled-down copy running that you scale up on failover, giving RTO in minutes to low tens of minutes. Pilot light keeps only the core data replicated and provisions compute on demand. Backup and restore, where you rebuild from snapshots, is cheapest but can mean an RTO of hours.
RTO is not real until you test it. A documented 15-minute RTO that has never survived a game day or a chaos drill is a guess. Teams run scheduled failover exercises and measure the wall-clock recovery time, then fix whatever step blew the budget.