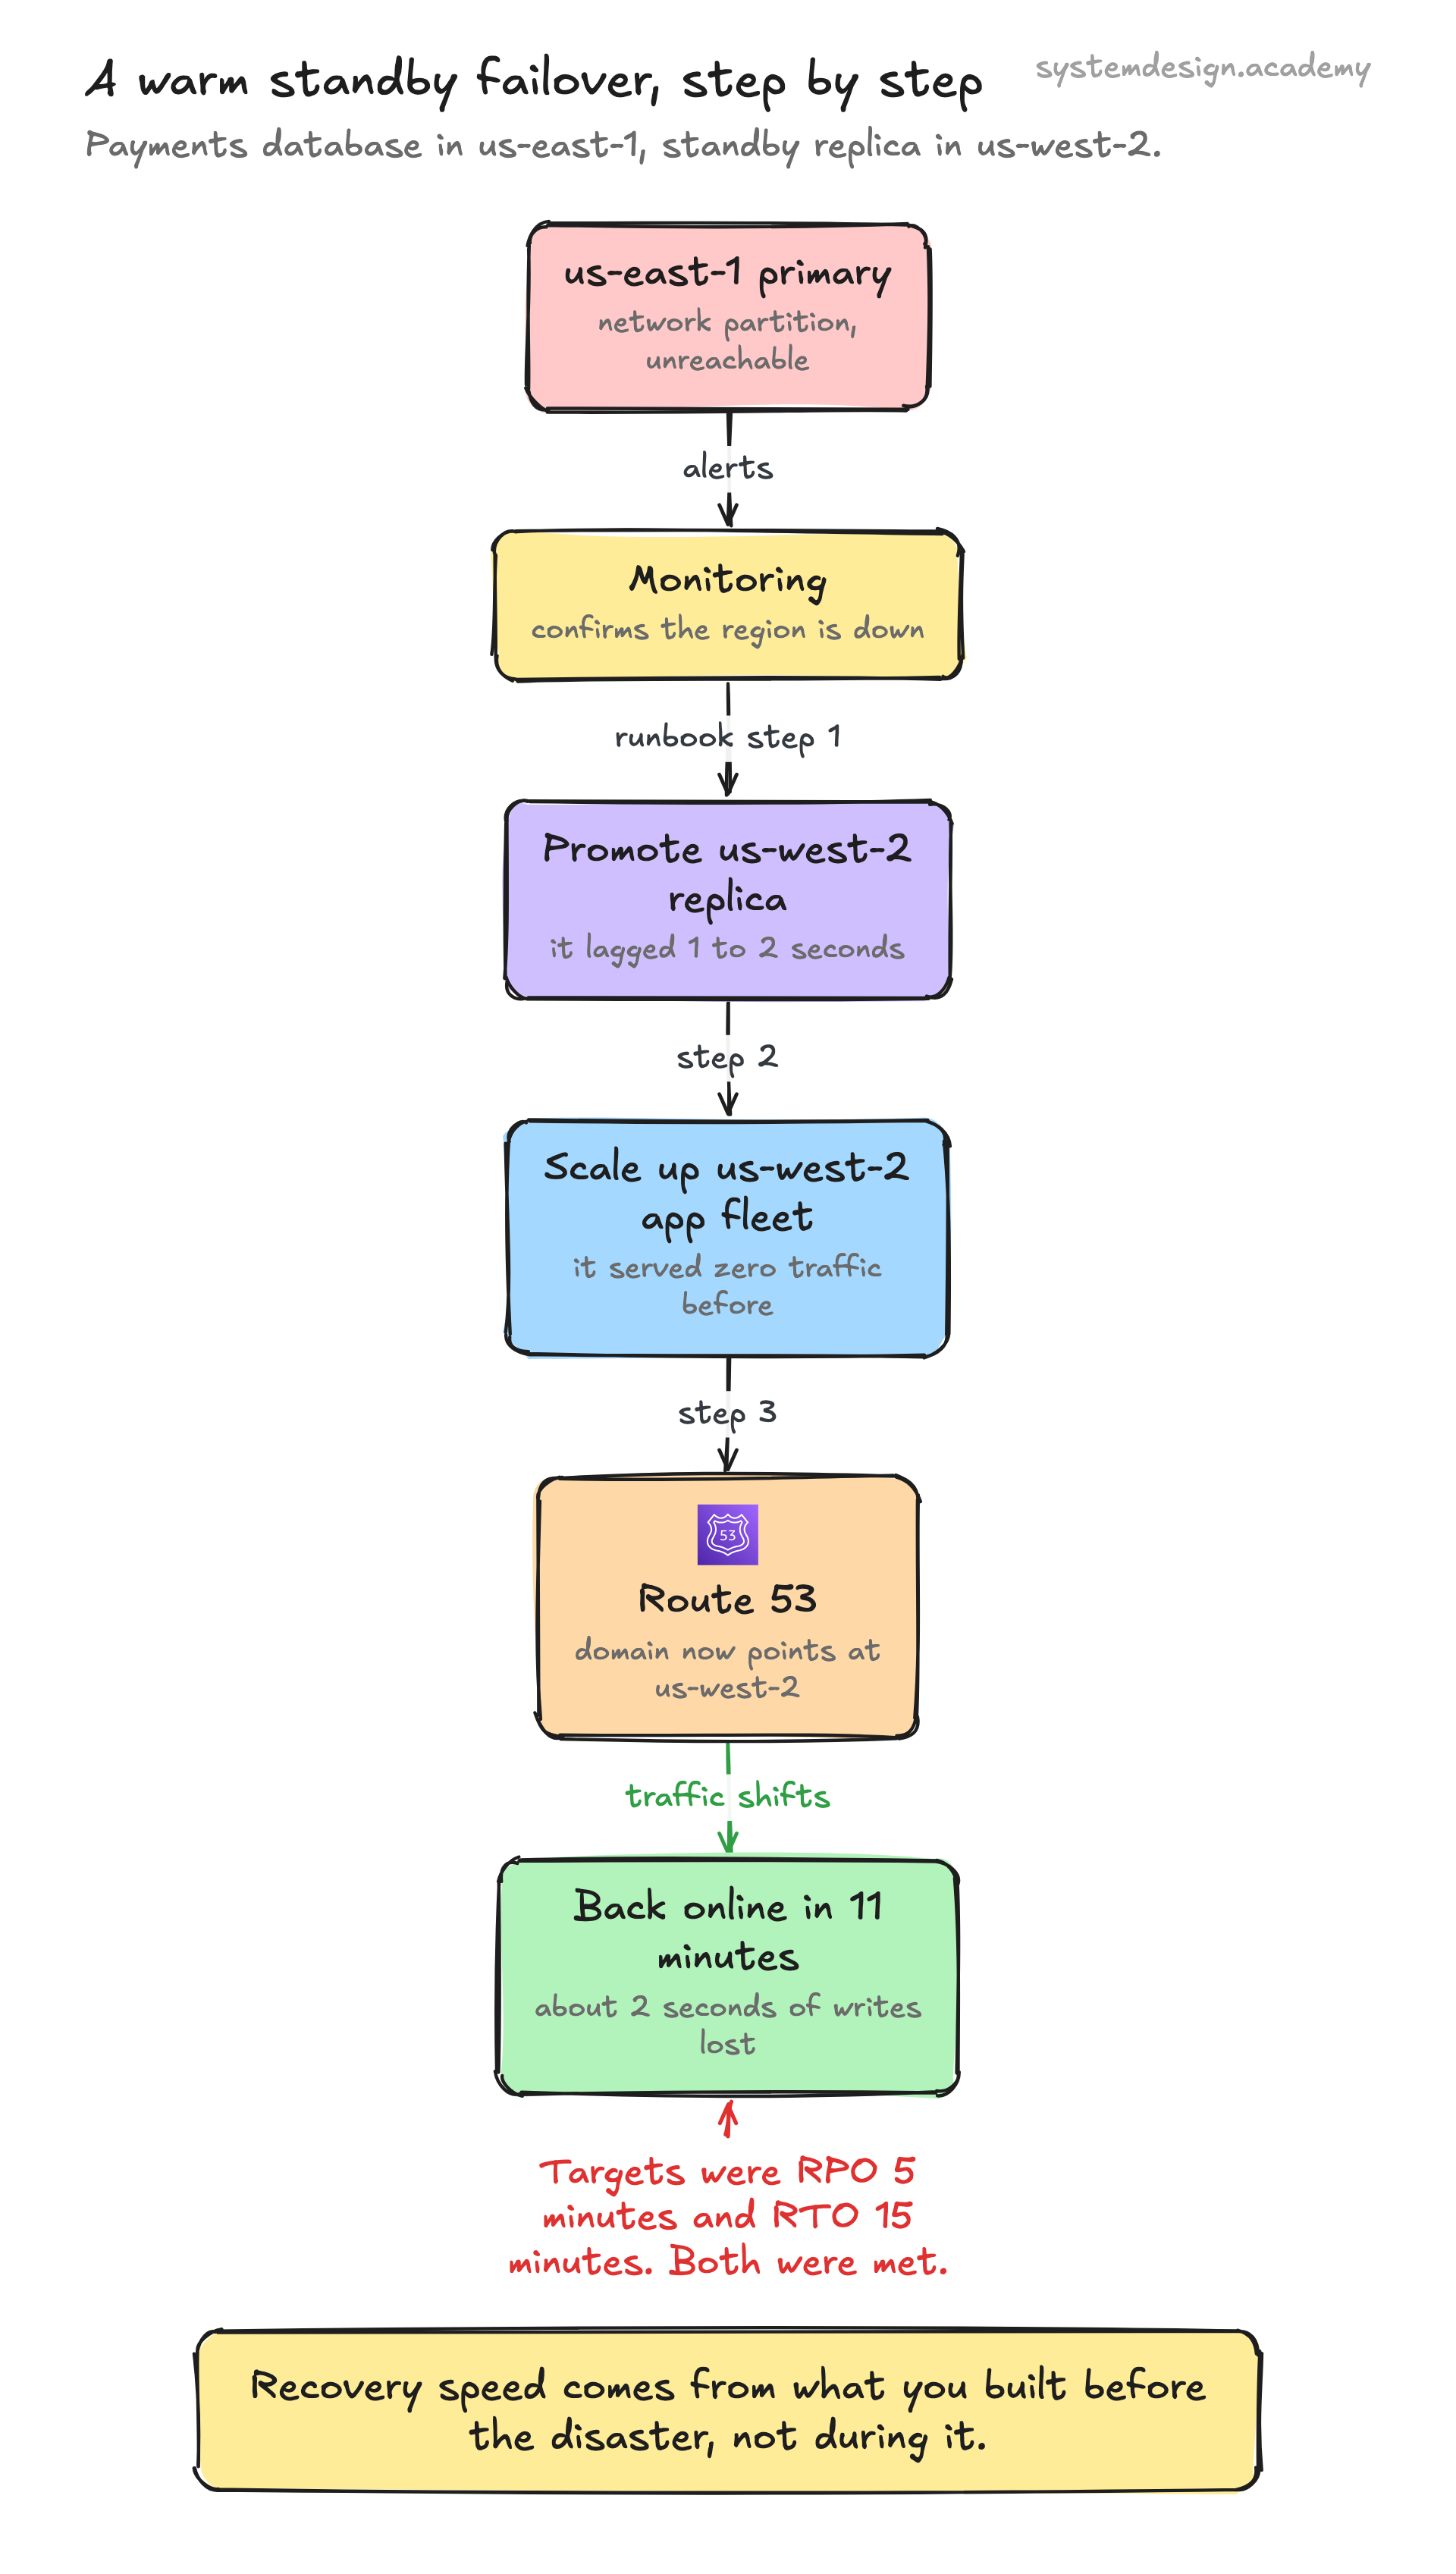
Disaster recovery, often shortened to DR, is what you do when an entire system goes down hard and normal failover is not enough. A single crashed server is handled by redundancy and health checks. A disaster is bigger: an AWS region becomes unreachable, a database gets corrupted and replicates the corruption everywhere, a fire takes out a datacenter, or someone runs DROP TABLE on production. DR is the deliberate plan to bring service back from a known-good copy.
Two numbers define every DR plan. RPO, the Recovery Point Objective, is how far back in time you are willing to lose data. An RPO of 15 minutes means your last backup or replica can be at most 15 minutes behind, so a disaster loses at most 15 minutes of writes. RTO, the Recovery Time Objective, is how long the business can tolerate being down. An RTO of 1 hour means service must be fully restored within an hour of the incident.
RPO and RTO are business decisions before they are technical ones. A bank's payment ledger might demand an RPO of zero and an RTO of minutes. An internal analytics dashboard might happily accept an RPO of 24 hours and an RTO of a day. The cost of the DR setup scales steeply with how close to zero you push both numbers.