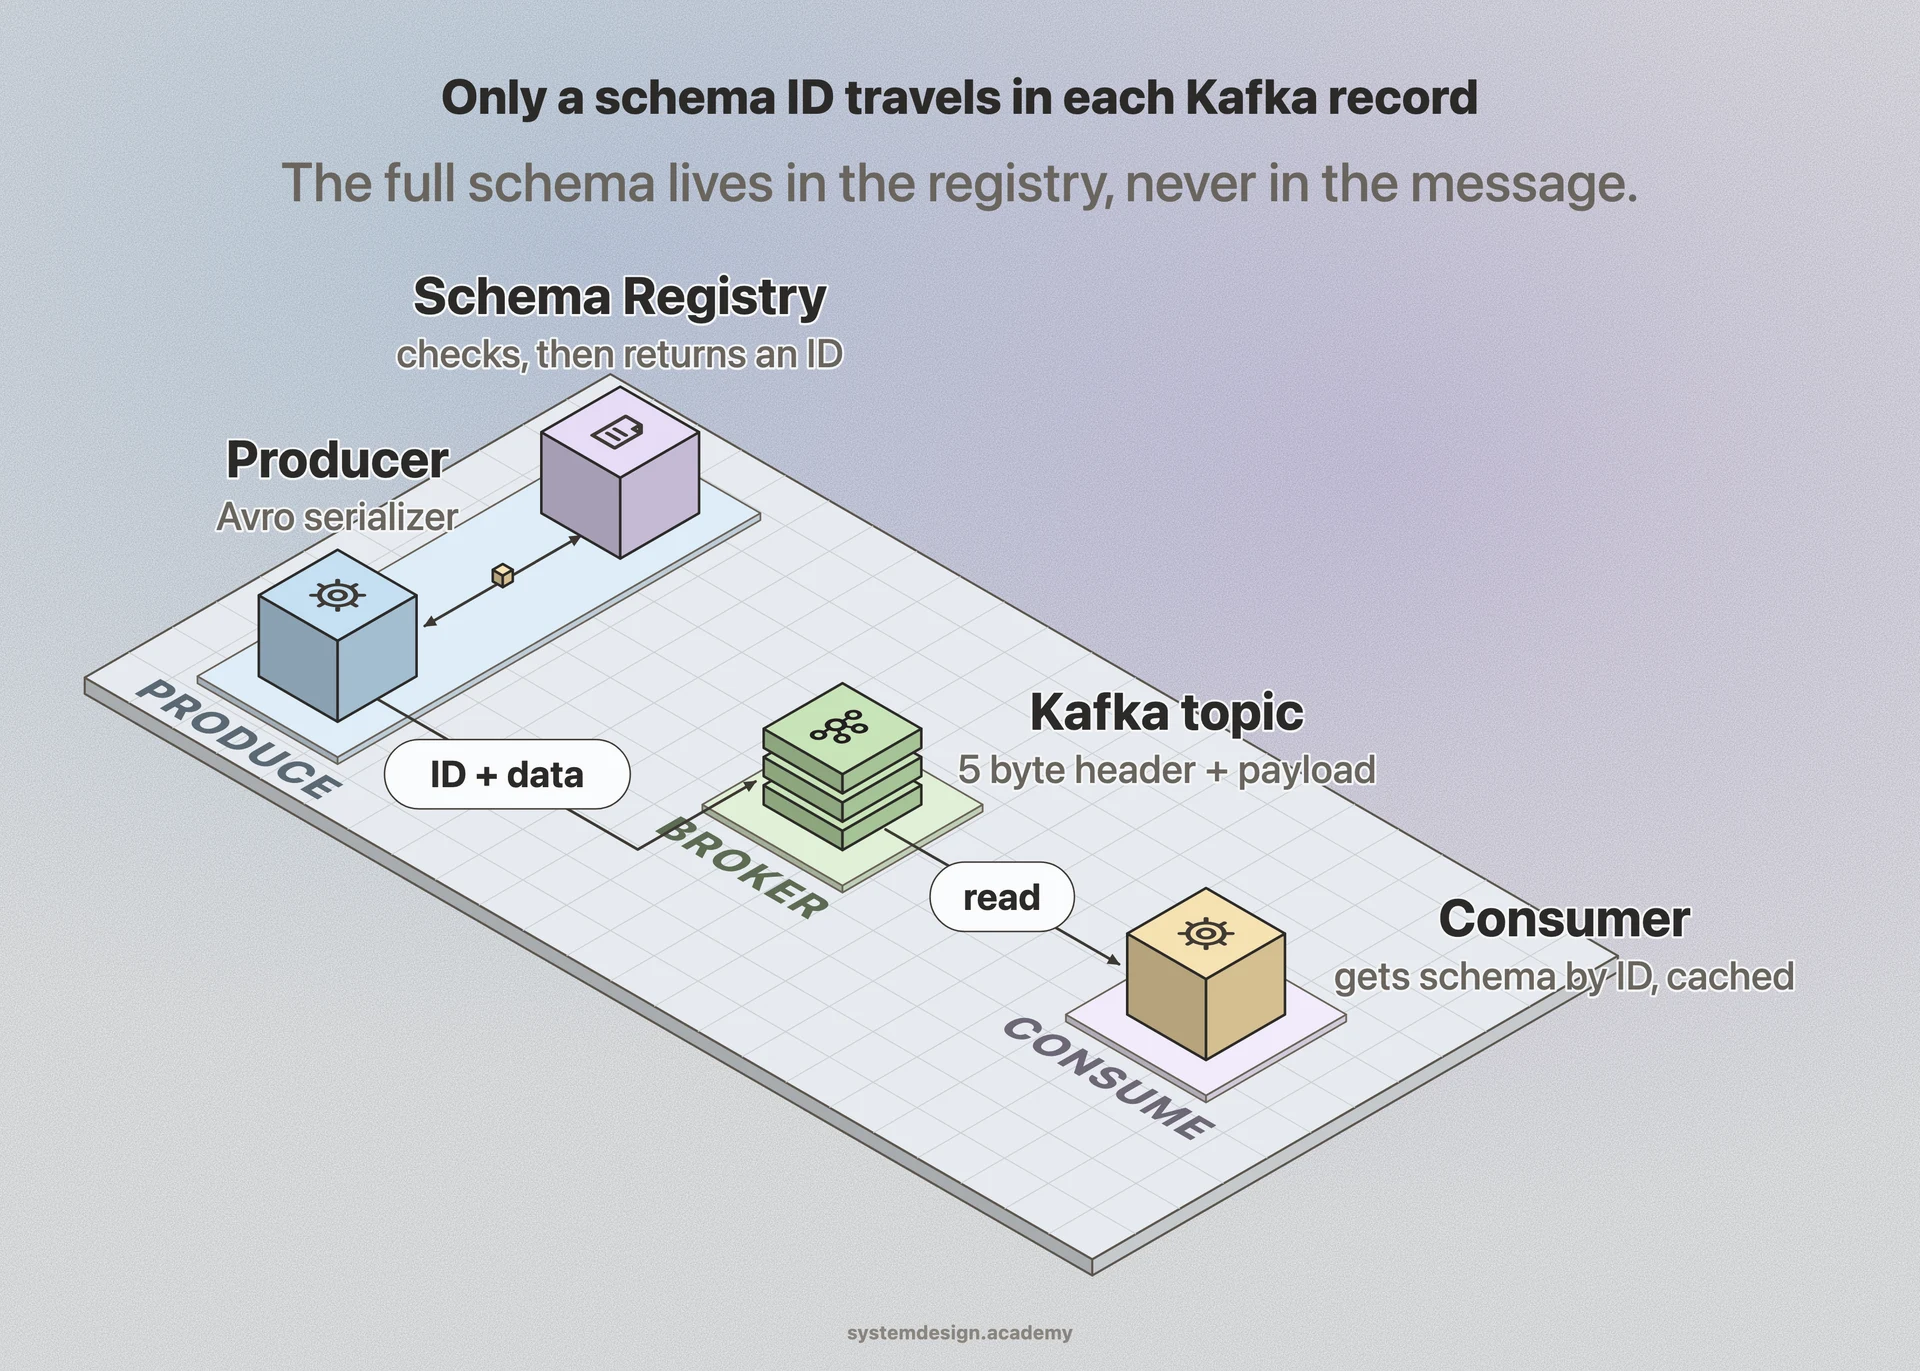
Take the Confluent Schema Registry, the most common implementation. It runs as a REST service and stores all schemas in a special compacted Kafka topic called _schemas, so the registry itself has no separate database and survives restarts by replaying that topic.
On the produce side, the serializer first asks the registry: is this exact schema already registered for this subject? If yes, it gets the cached ID back. If no, the registry runs a compatibility check against existing versions, and if it passes, stores the new version and returns a fresh ID. The serializer then writes a 5 byte header (a magic byte plus the 4 byte schema ID) followed by the binary-encoded payload. The full schema text is never in the message.
On the consume side, the deserializer reads those first 5 bytes, extracts the ID, and fetches the schema from the registry over HTTP, caching it locally so the lookup happens once per ID, not once per message. With Avro it can decode using the writer schema while resolving fields against the reader schema, which is how a consumer on an old version still reads records written with a newer one.
Compatibility is the core safety feature. You set a mode per subject. BACKWARD (the default) means new consumers can read old data, so you may add optional fields or remove fields. FORWARD means old consumers can read new data. FULL requires both. NONE turns checking off. The registry rejects any registration that violates the rule, which stops a bad schema from ever reaching production.