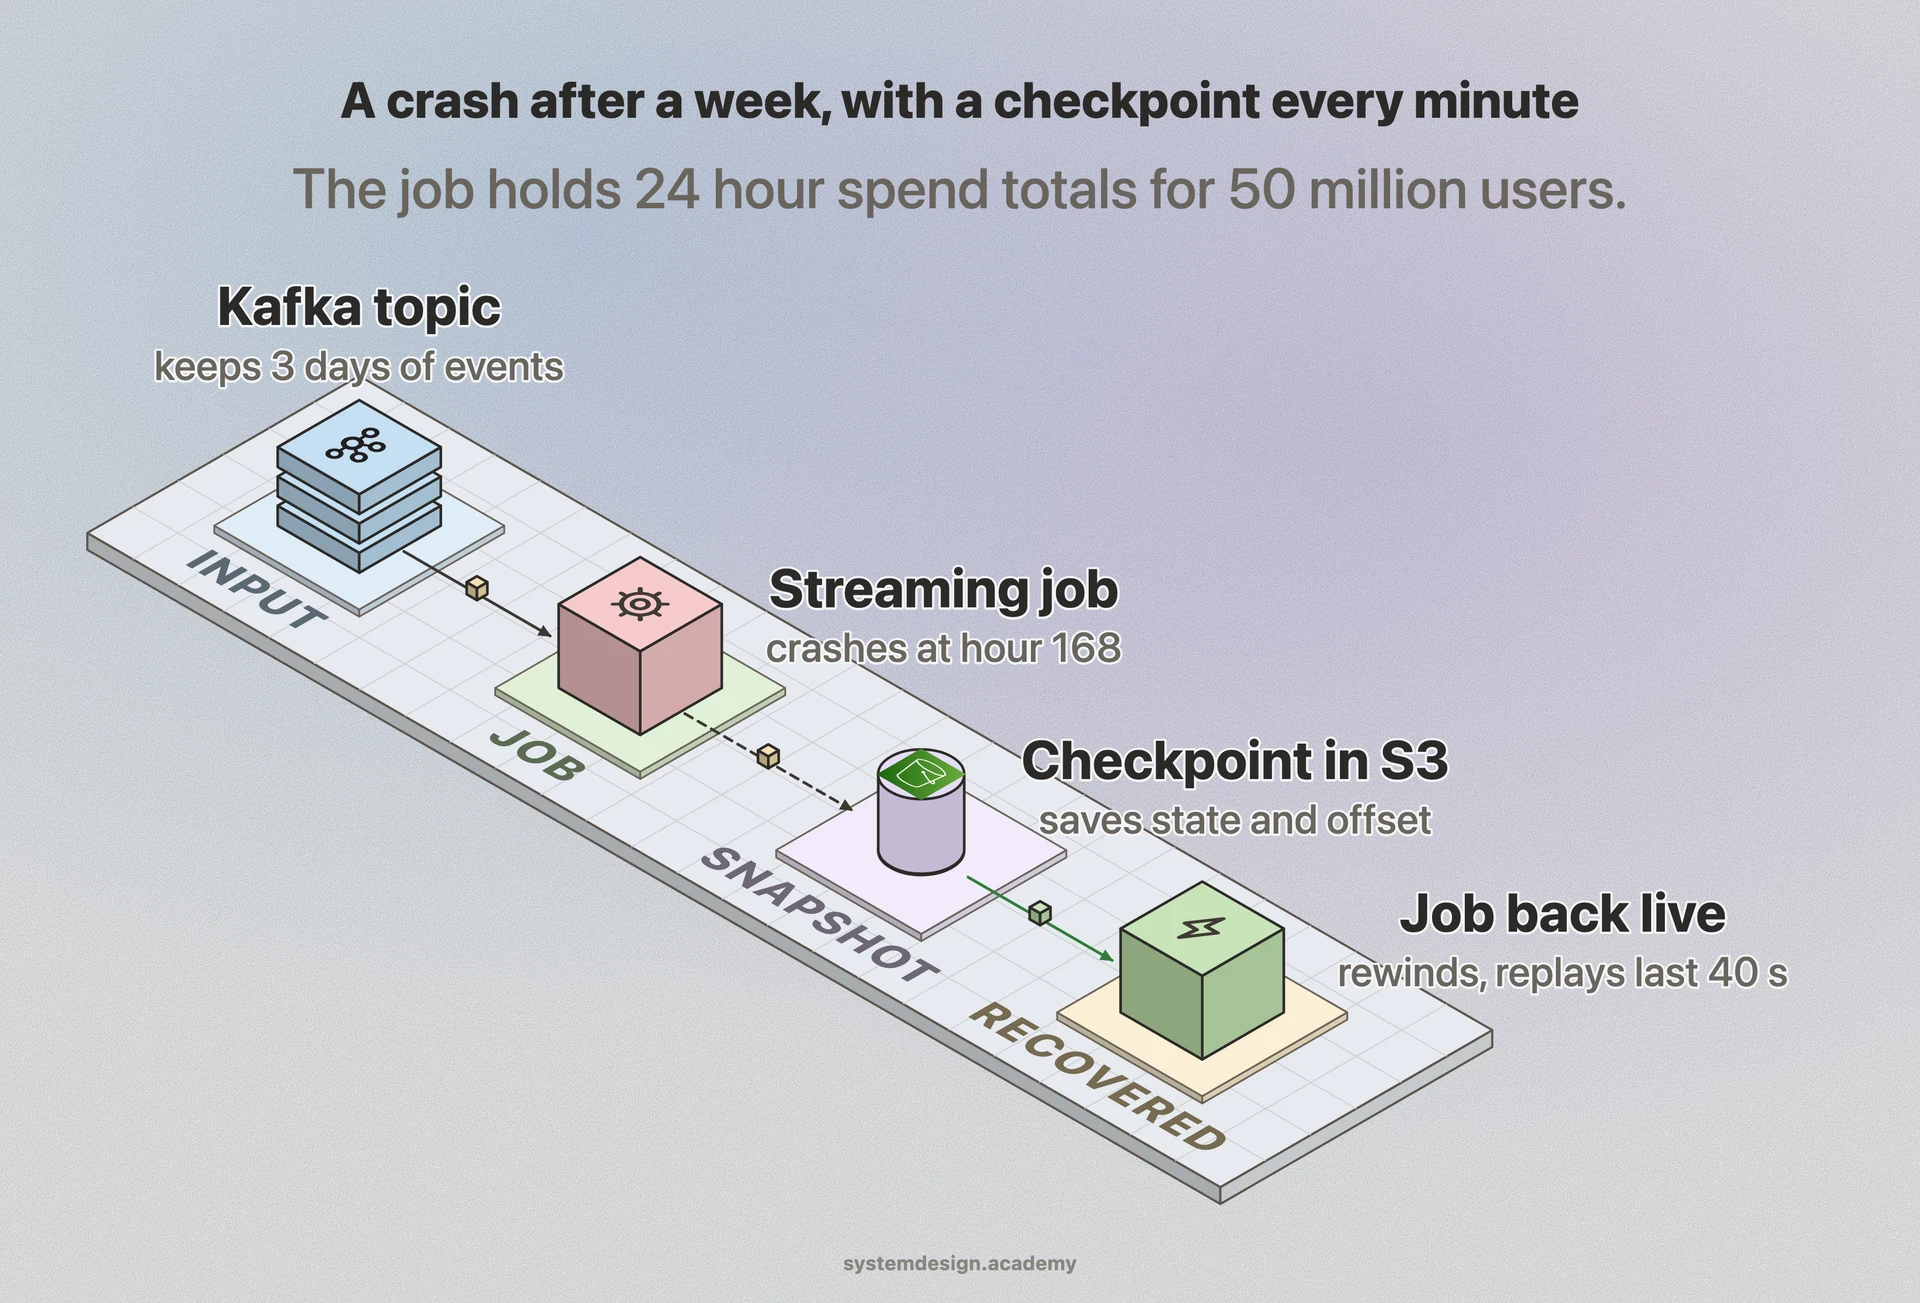
A streaming job runs for days or weeks and builds up state as it processes data: running counts, windowed aggregates, join buffers, machine learning model weights, deduplication sets. If the machine running that job dies, all of that in-memory state is gone. Without a way to recover it, you would have to reprocess every event from the start of time, which is often impossible or takes hours.
A checkpoint is a consistent snapshot of that state plus a marker of how far the job has read its input. The framework writes it to durable storage such as Amazon S3, HDFS, or a distributed filesystem on a fixed interval, for example every 30 seconds or every minute. When the job restarts, it loads the most recent checkpoint and resumes reading the input from the recorded position.
The key word is consistent. In a distributed job with dozens of parallel operators, you cannot just freeze each one at a random moment, because their states would reflect different points in the stream. A correct checkpoint captures a state that corresponds to one exact cut across all inputs.