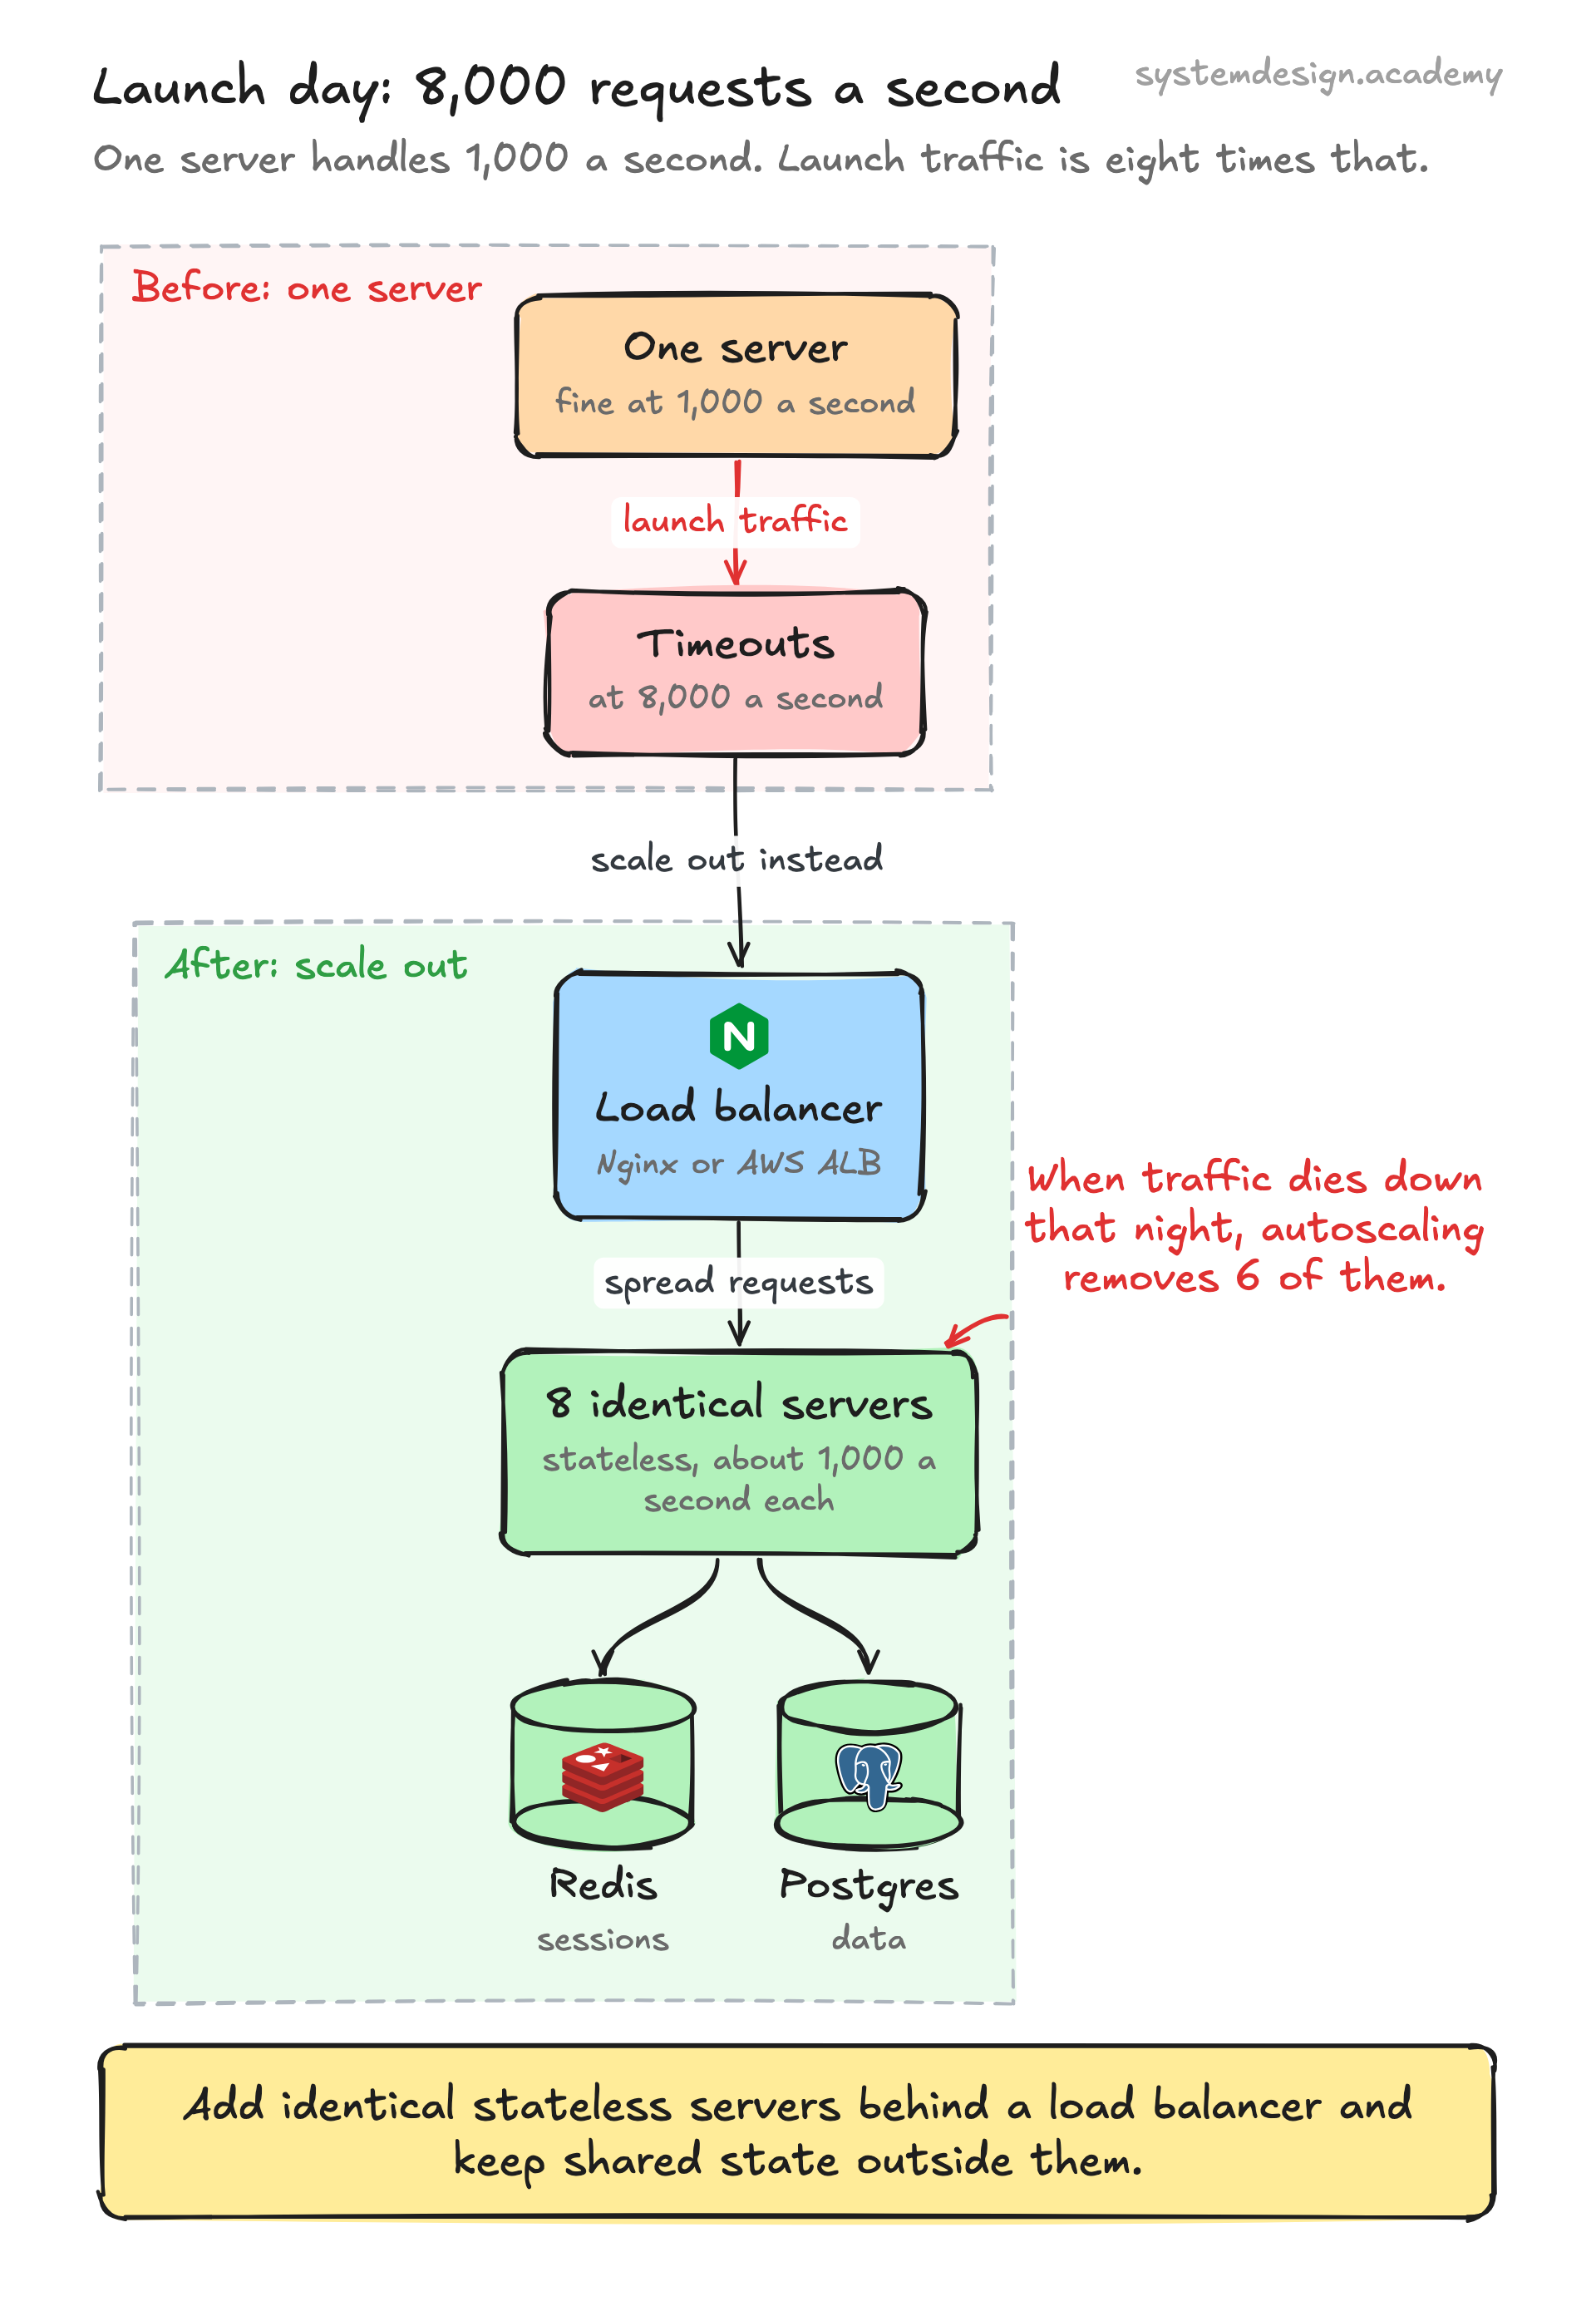
Reach for horizontal scaling when load is variable or growing, when you need high availability, or when one machine simply is not big enough. Because there are many machines, the loss of one does not take the service down, and you can add capacity for a traffic spike then remove it afterward, which is exactly what autoscaling on Kubernetes or AWS Auto Scaling Groups does.
The cost is complexity. You now need a load balancer, health checks, service discovery, and a strategy for shared state and deployments across many nodes. Distributed systems also introduce failure modes a single box never has, such as network partitions and the consistency-versus-availability trade-offs described by the CAP theorem.
Vertical scaling is often the right first move precisely because it is simple. Doubling a server's RAM requires no code changes. A common pattern is to scale up until it gets costly or risky, then scale out once the architecture is ready, since stateless services and a shared data tier are what make scaling out cheap later.