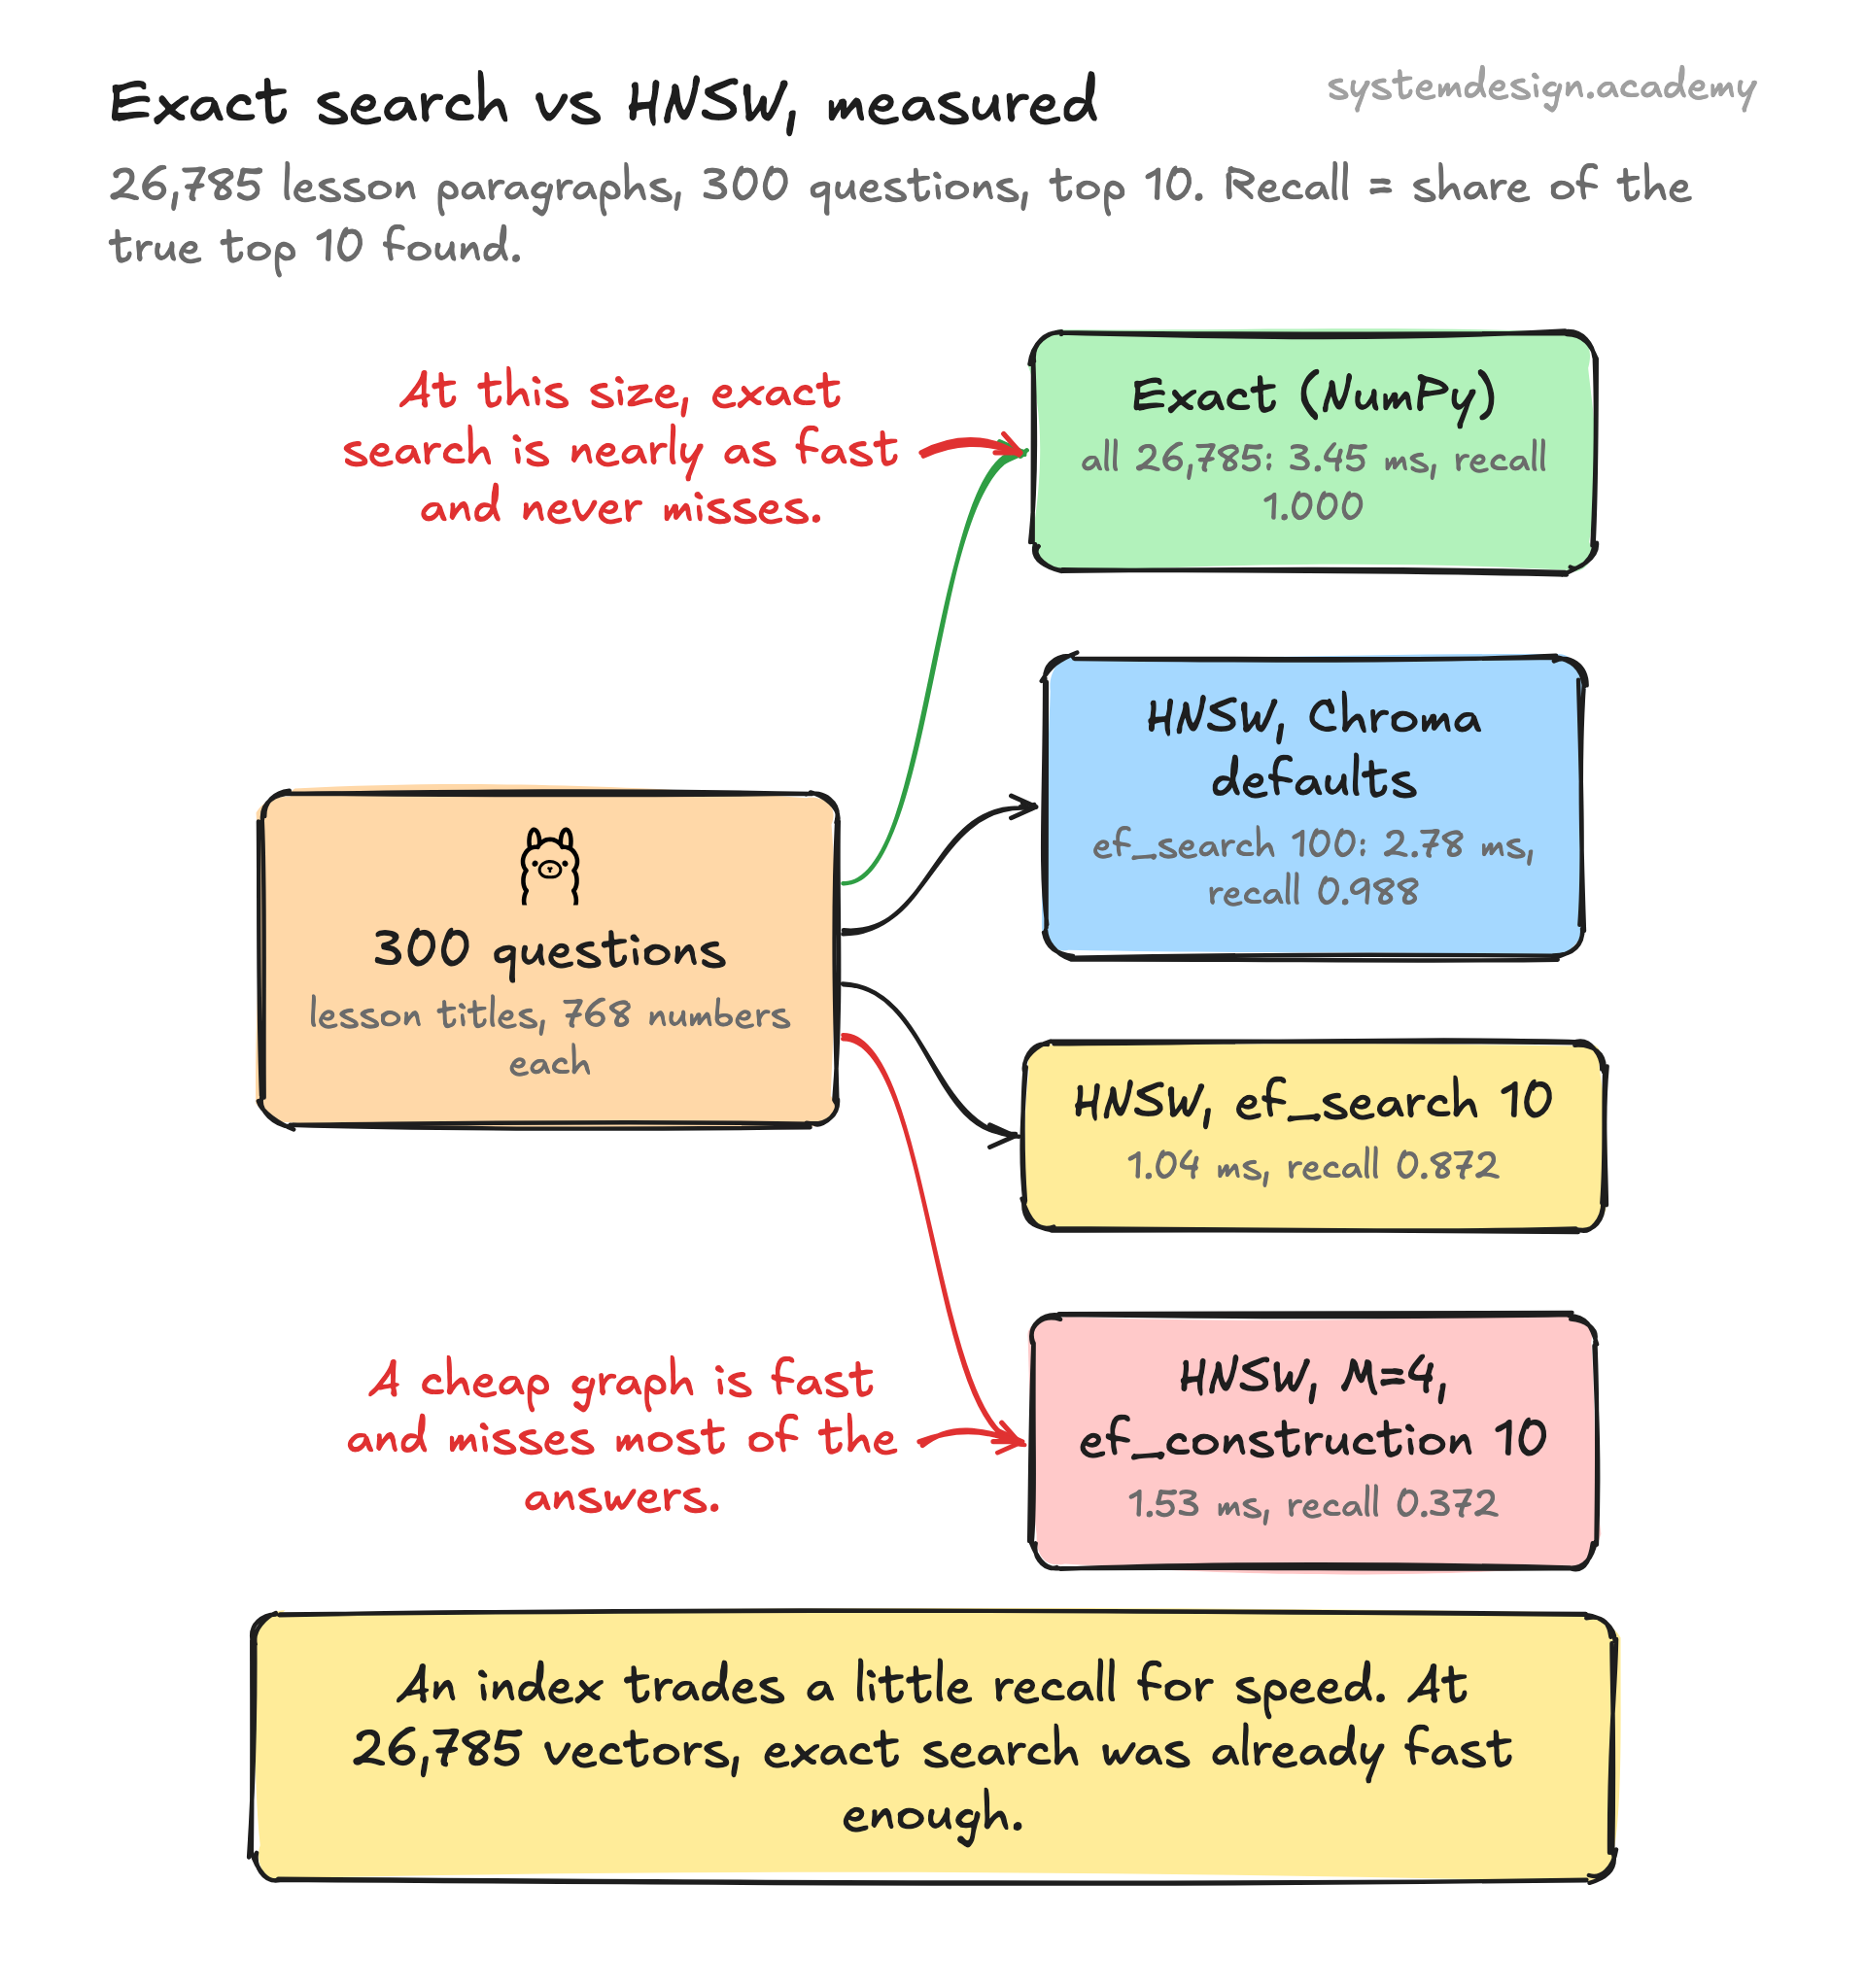
The simplest way to find the nearest vectors is to compare the question with every stored vector and keep the best. That is exact search, also called brute force or flat search, and it never misses. Its cost grows with the number of vectors: ten times the data, about ten times the work.
Approximate nearest neighbour search, ANN, builds an index that looks at a small part of the data and usually finds the true nearest items, but not always. Recall measures how often: recall@10 is the share of the true top 10 that the index actually returned. Production systems commonly run at around 95 to 99% recall.
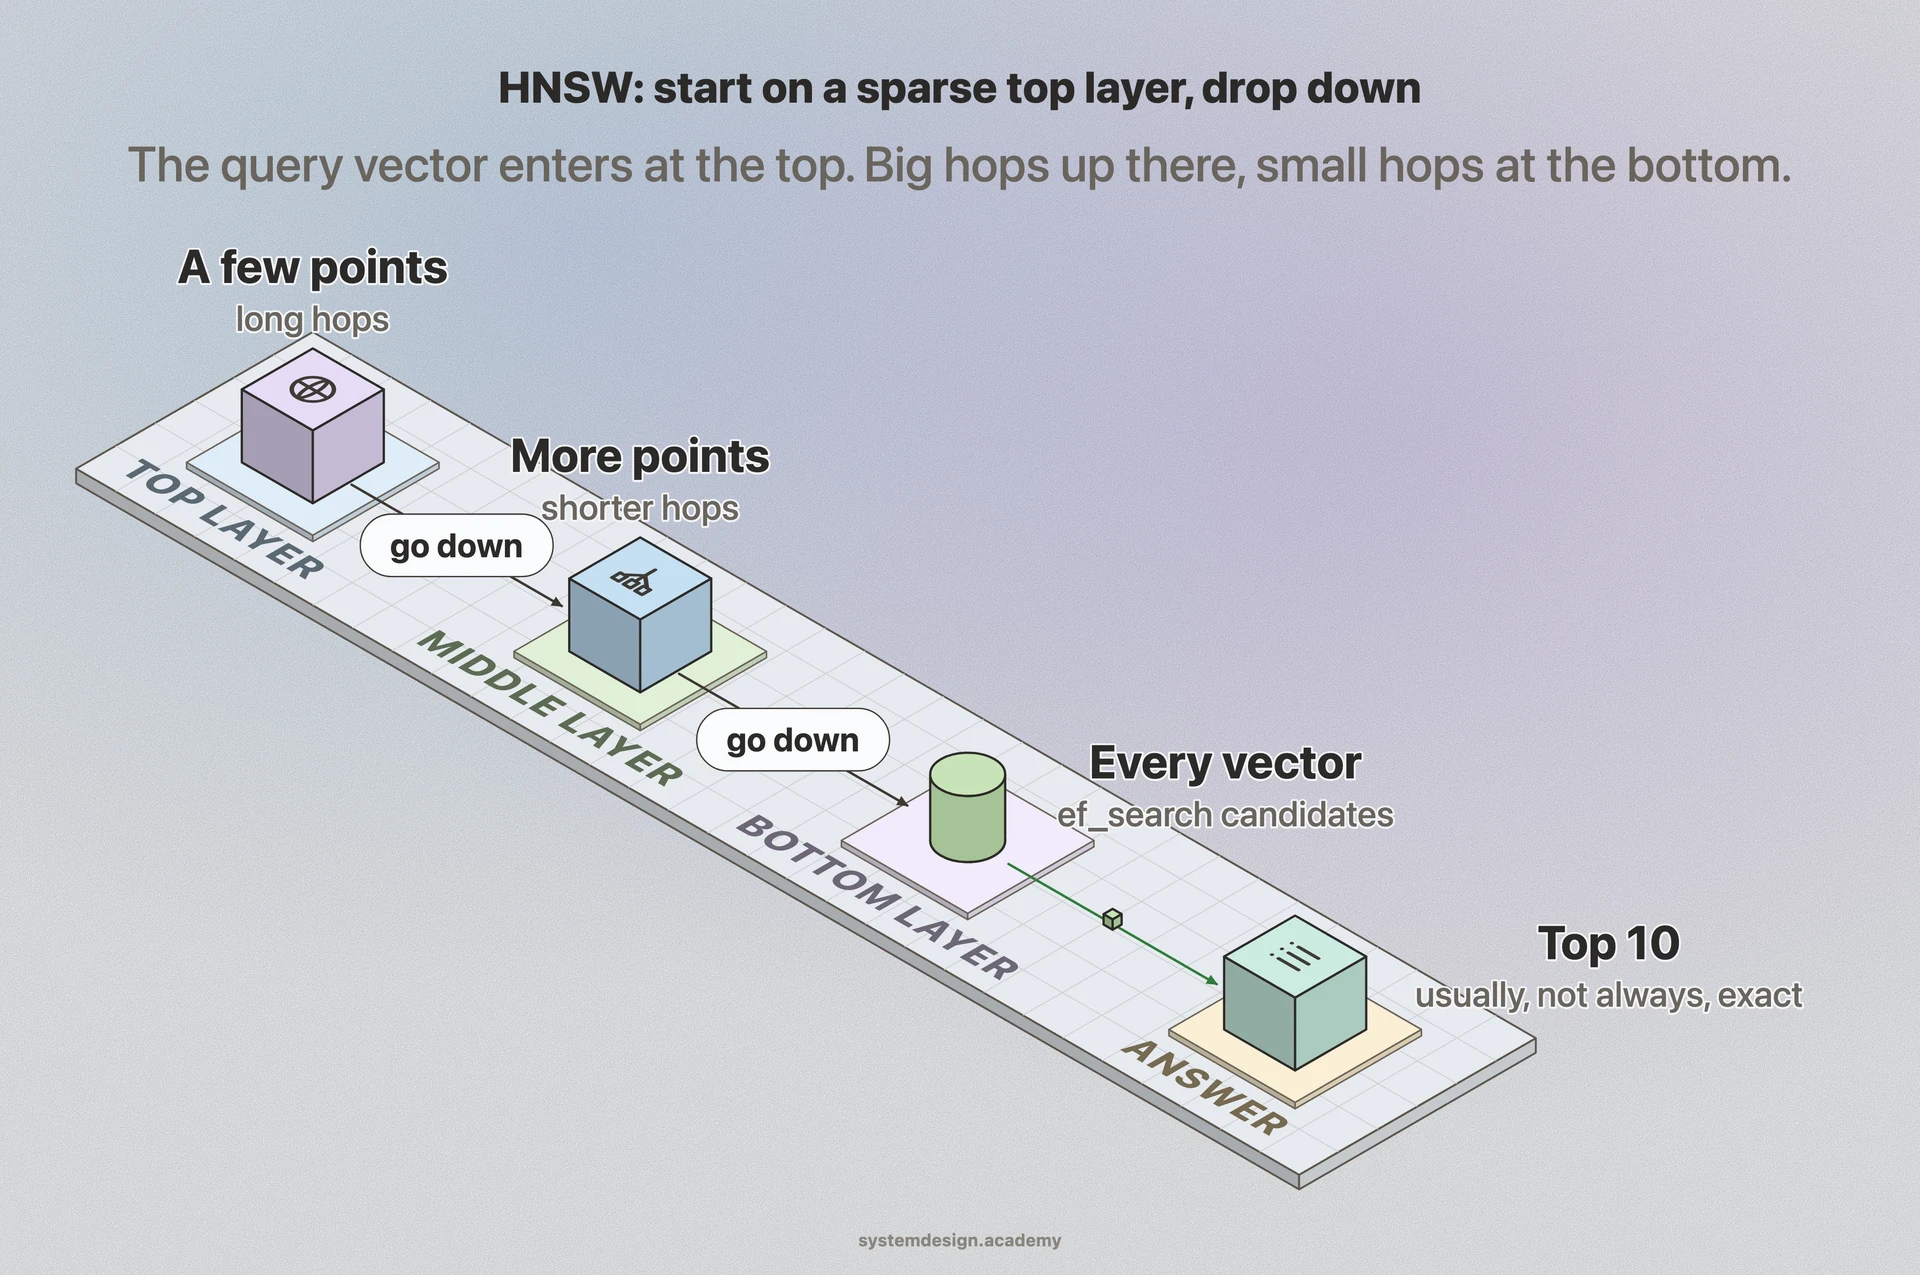
The most widely used ANN index is HNSW, Hierarchical Navigable Small World, published by Malkov and Yashunin in 2016. It links every vector to a few of its near neighbours, forming a graph, and stacks a few thinner copies of that graph on top. A search starts on the sparse top layer, takes long hops toward the question, drops a layer, takes shorter hops, and finishes on the bottom layer, which holds every vector.
- M (Chroma calls it max_neighbors): how many links each vector keeps. More links, better recall, more memory. Chroma's default is 16, the same as pgvector's.
- ef_construction: how hard the builder searches for good links when adding a vector. Higher builds a better graph, more slowly. Chroma's default is 100; pgvector's is 64.
- ef_search: how many candidates a query keeps while it walks the bottom layer. Higher means better recall and slower queries. Chroma's default is 100; pgvector's hnsw.ef_search is 40. This is the one you tune at query time.