Think of two people on a customer service desk. The first one started today. She has a thick printed rule book, and before she writes up each customer's problem she opens it and reads the whole thing again: which team gets which problem, how to write the product name, what counts as urgent. She is careful, and she follows most of it. But reading the full book for every single customer is slow, and some rules still slip past her, because a rule you have only read is not the same as a habit.
The second person has been on the desk for months. She has written up hundreds of these problems, and her manager corrected the ones she got wrong. Her rule book is on the shelf behind her. She does not need it, because the rules are now in how she works. She will still make mistakes. They will just be different mistakes from the new starter's.
The last lesson was the first person. Four models were handed the full house rules with every message, and I checked which rules they kept and which they dropped. This lesson is the second person. I took three small models, showed each of them the 500 training examples from lesson 2 three times, and then gave them only one short line of instructions. The rules were never shown to them in words. They had to learn the rules from the examples.
Then I asked the same question as the manager: is the experienced one better? The answer turned out to be more interesting than yes or no. The smallest trained model scored exactly the same as the biggest prompted one, and they did not get the same tickets right.
Nine Words for This Lesson
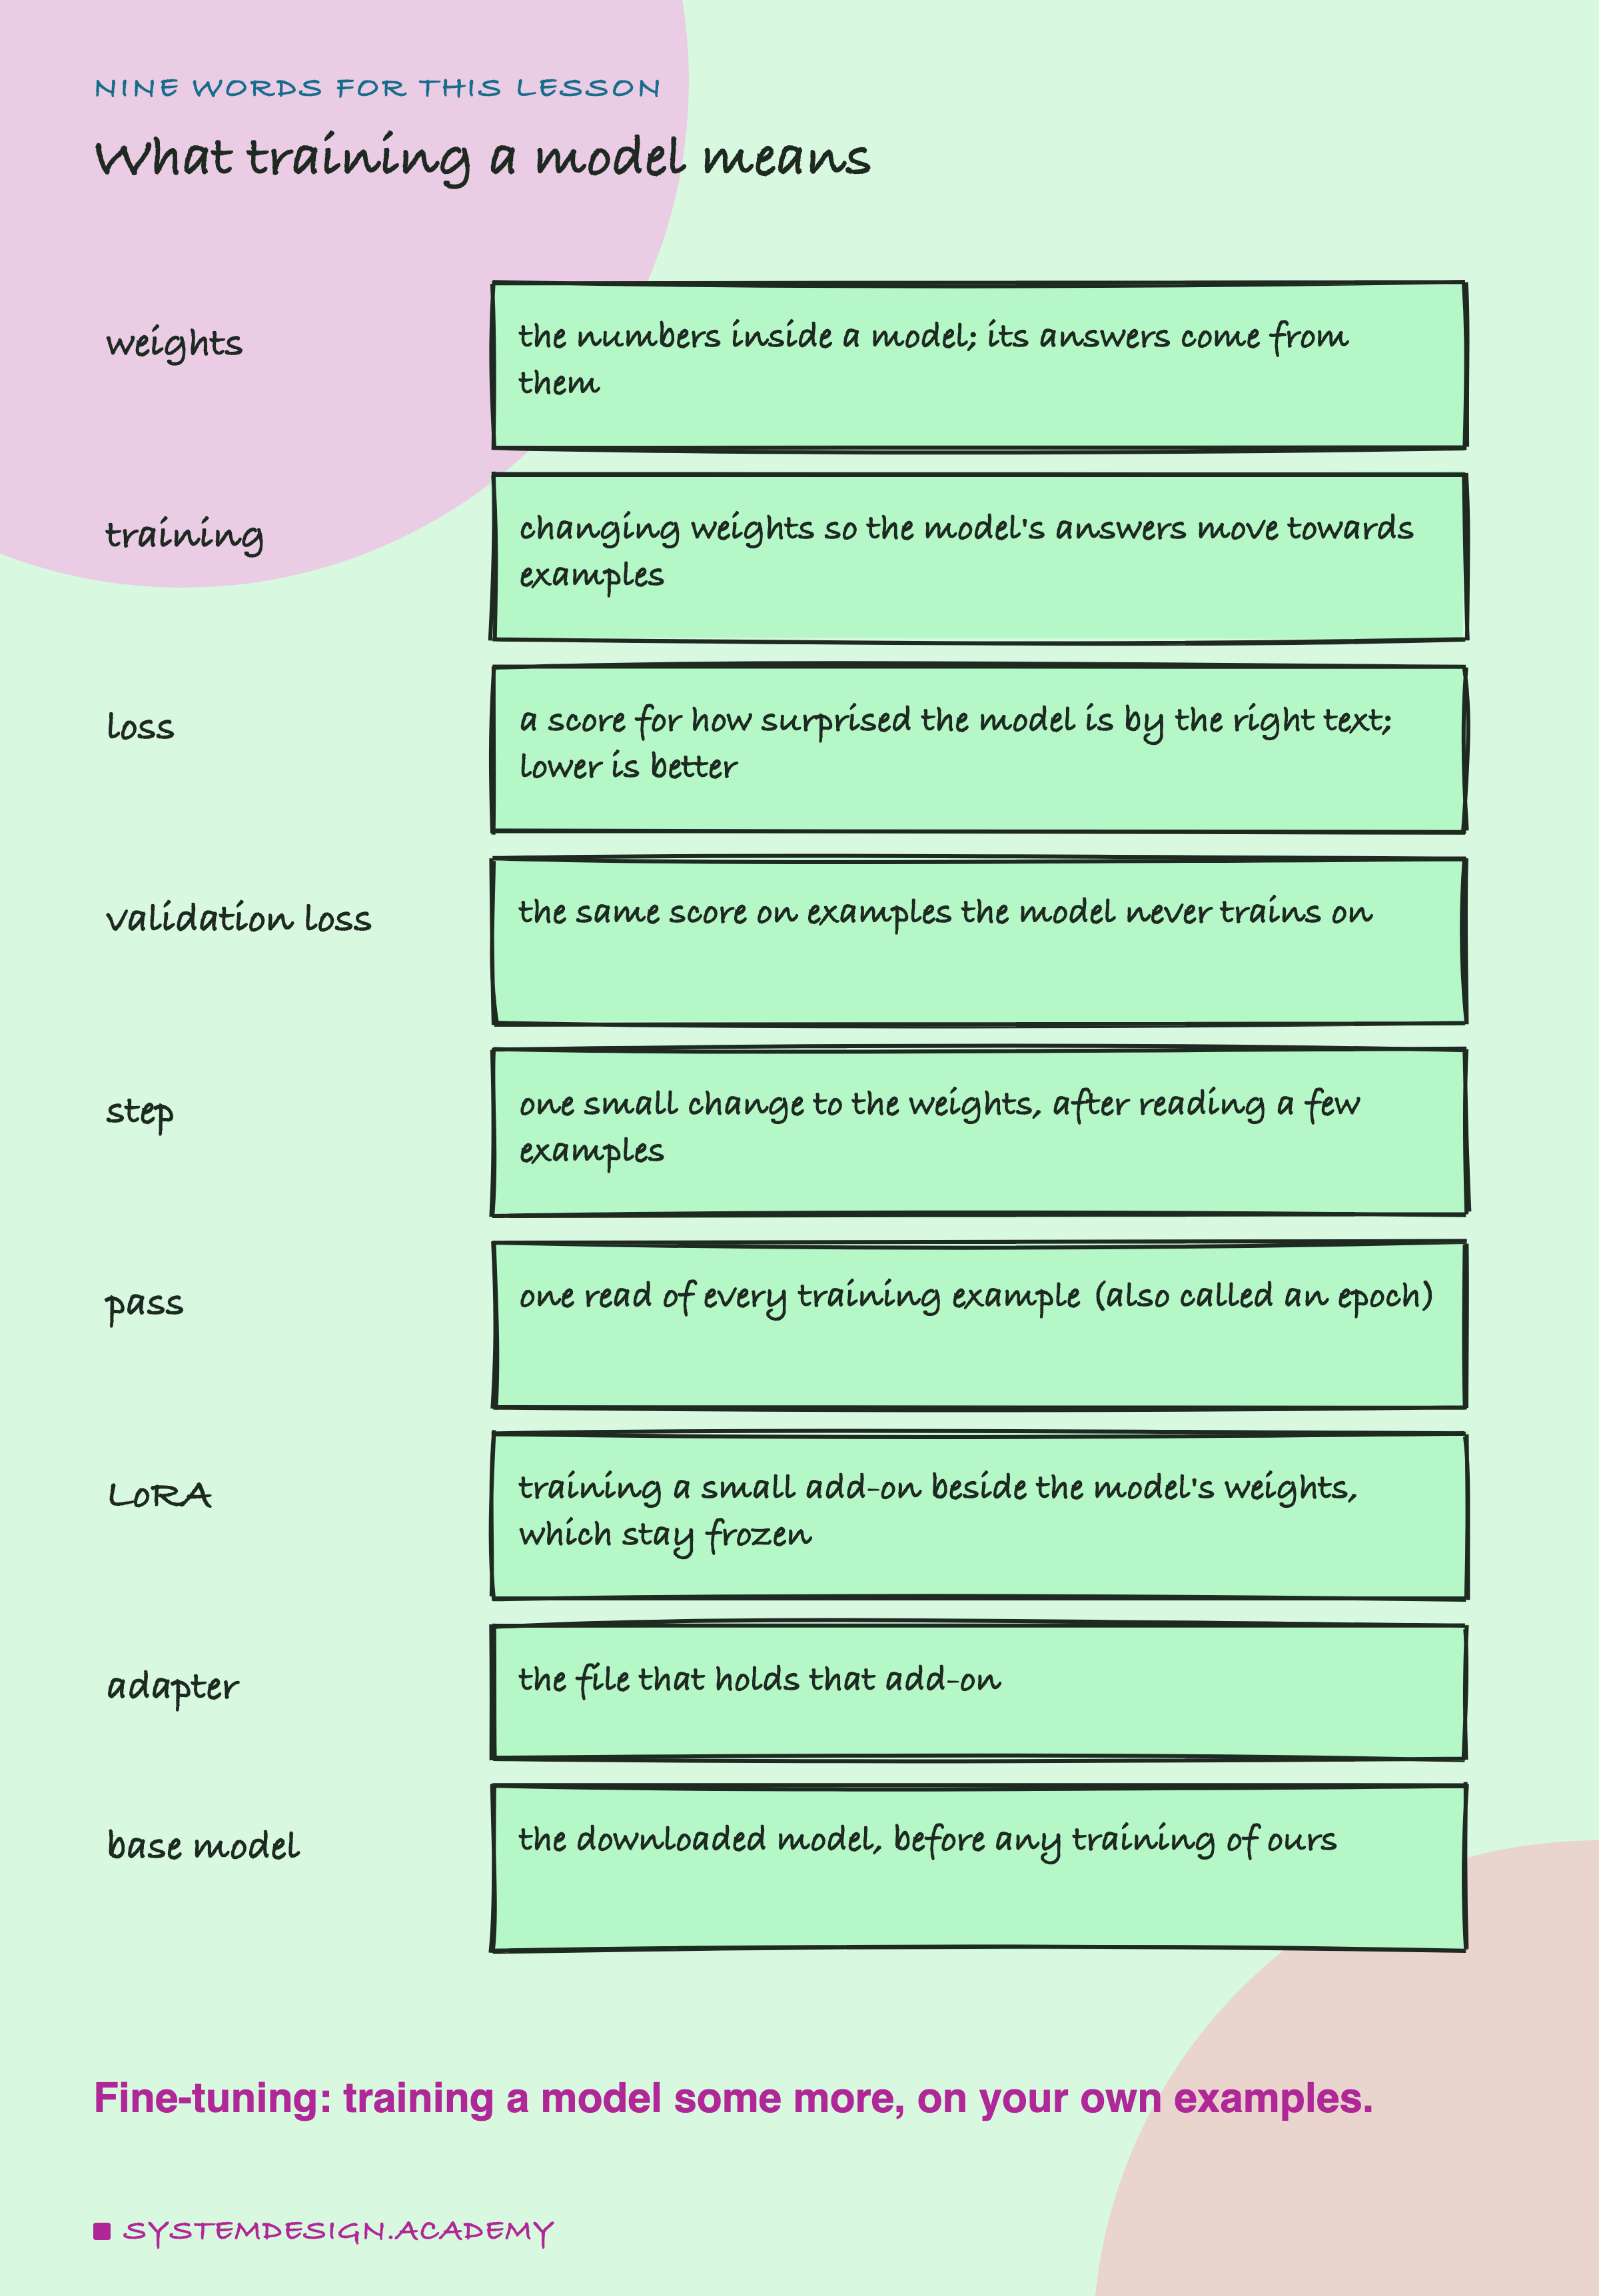
Weights. A language model is, underneath, a very large collection of numbers. When it reads your text, it does a long chain of multiplications with these numbers, and what comes out is its guess for the next piece of text. The numbers are called weights. A "0.5B" model has about half a billion of them.
Training means changing the weights a little at a time so that the model's answers move towards examples you show it. is training a model that has already been trained by its makers, some more, on your own examples.
Loss is the score training tries to make smaller. It measures how surprised the model was by the right text. The next slide shows how it is worked out. Validation loss is the same score on a separate set of examples the model is never trained on. It tells you whether what the model learned also works on examples it has not seen.
A step is one small change to the weights, made after reading a few examples. A pass, also called an epoch, is one read through every training example.
, short for low-rank adaptation, is a way to fine-tune without changing the original weights at all. They stay frozen, and a small new set of weights is trained beside them. The file that holds those new weights is called an adapter. The base model is the model as downloaded, before any of our training.
What Training Actually Changes
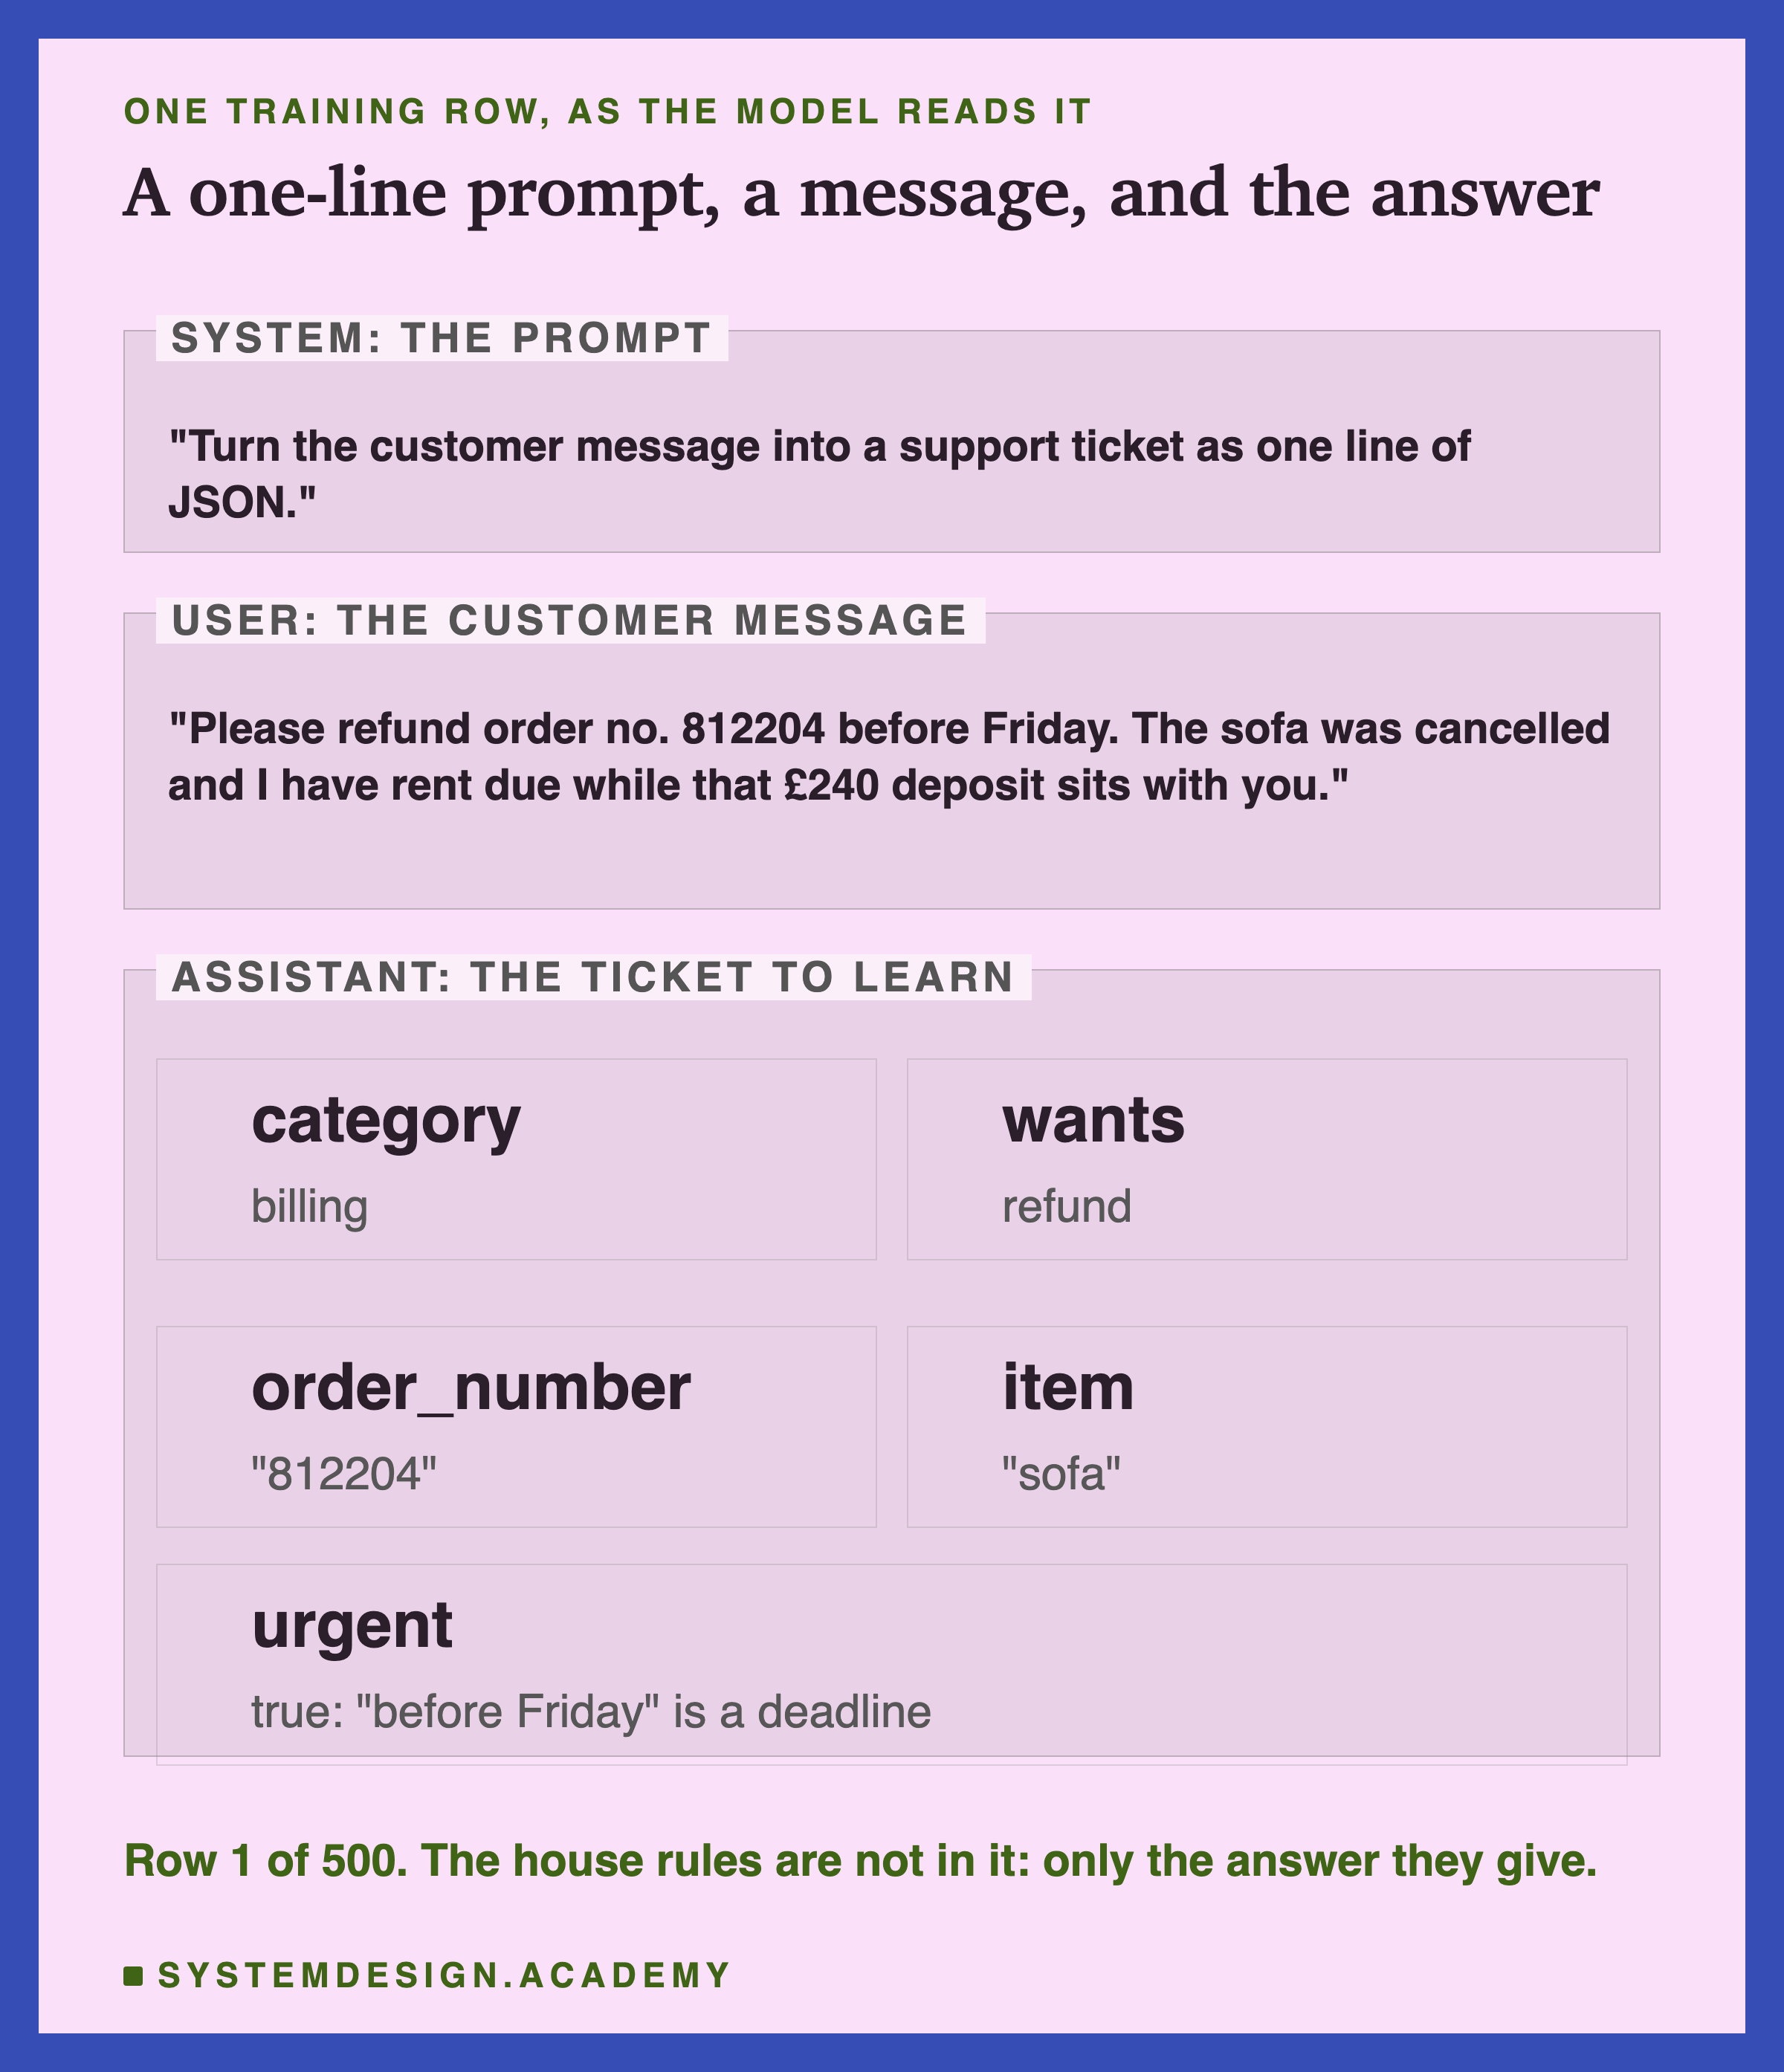
Lesson 2 built 500 training examples. Each one is a small conversation of three parts, in the same format a chat model reads: a short instruction, the customer's message, and the ticket we want back. Here is the first of the 500, exactly as the model reads it.
Notice what is missing. The house rules from lesson 2 (401 words) are nowhere in the example. The instruction is one line: "Turn the customer message into a support ticket as one line of JSON." The model only ever sees the answers the rules produce. If it is going to follow the rules, it has to work them out from 500 answers.
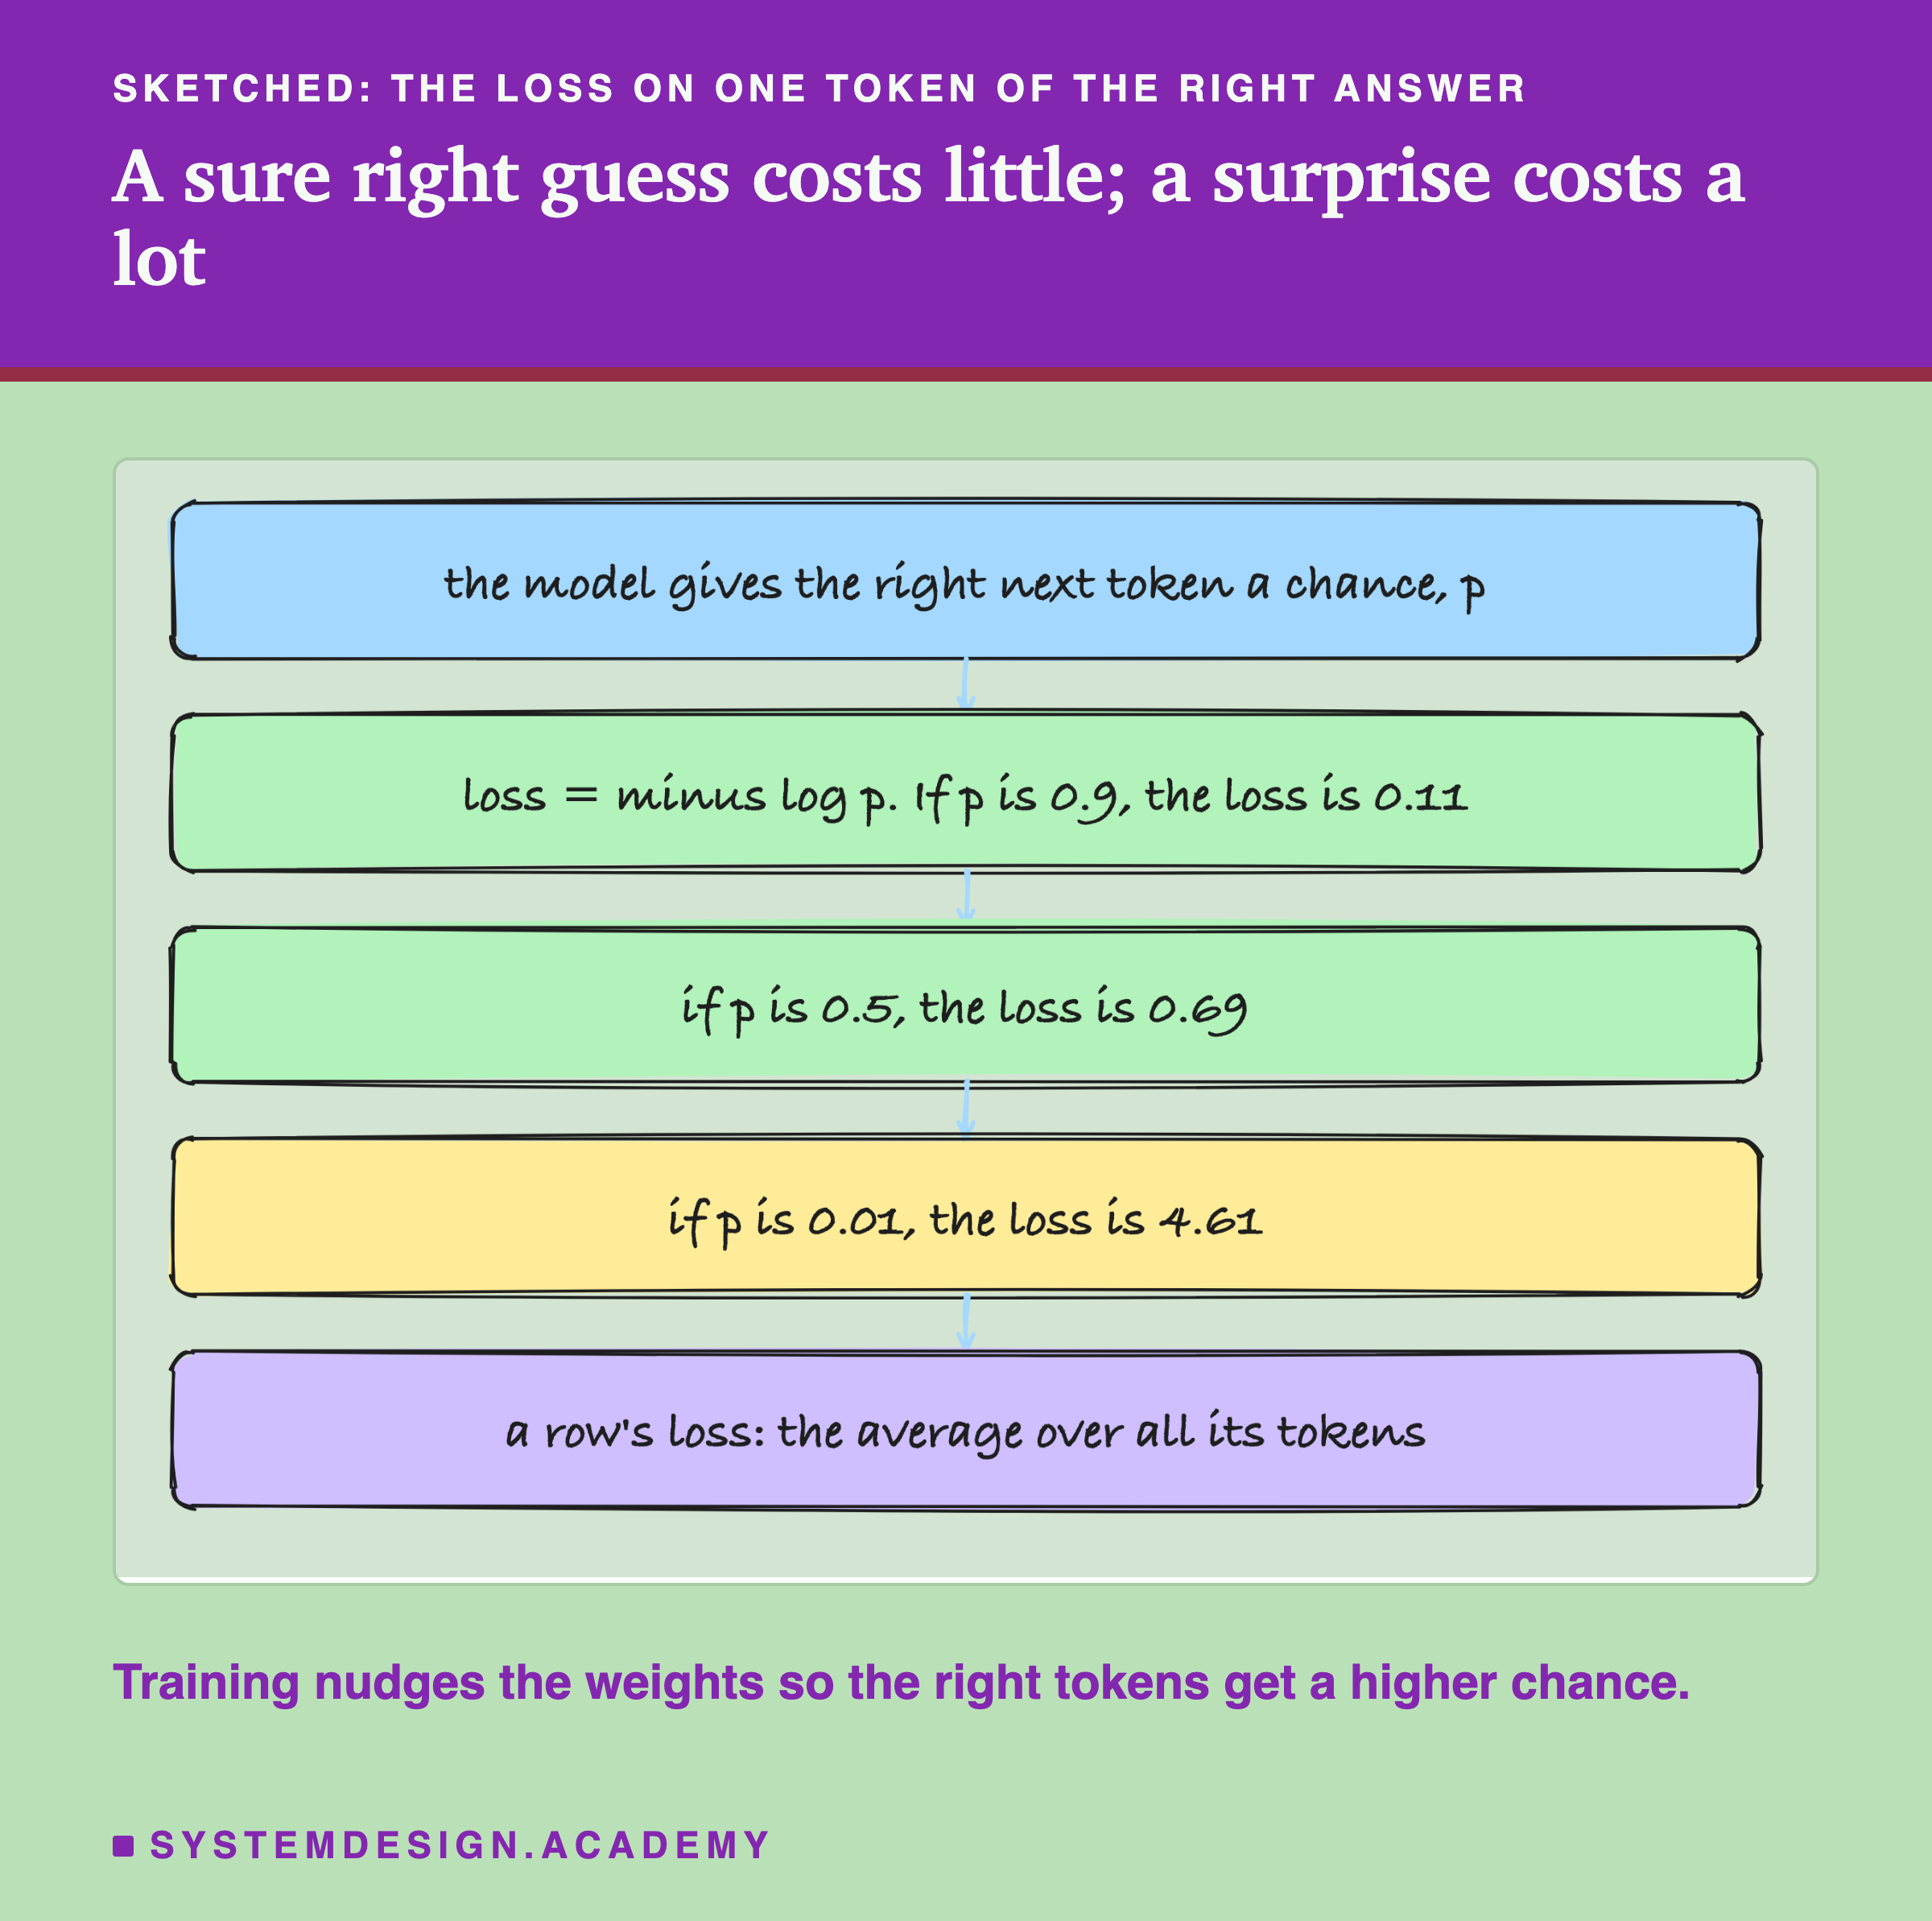
How does a model learn from an example? A language model writes text one token at a time. A token is a small piece of text, often part of a word. For every position in the example, the model gives each possible next token a chance, a number between 0 and 1. The loss looks at the chance it gave the token that really comes next.
If the model was nearly sure of the right token, with a chance of 0.9, the loss for that token is small, 0.11. If it gave the right token a chance of only 0.01, it was badly surprised, and the loss is 4.61. The formula is minus the logarithm of the chance, which is what makes a confident mistake cost so much. The loss for a whole example is the average over all its tokens.
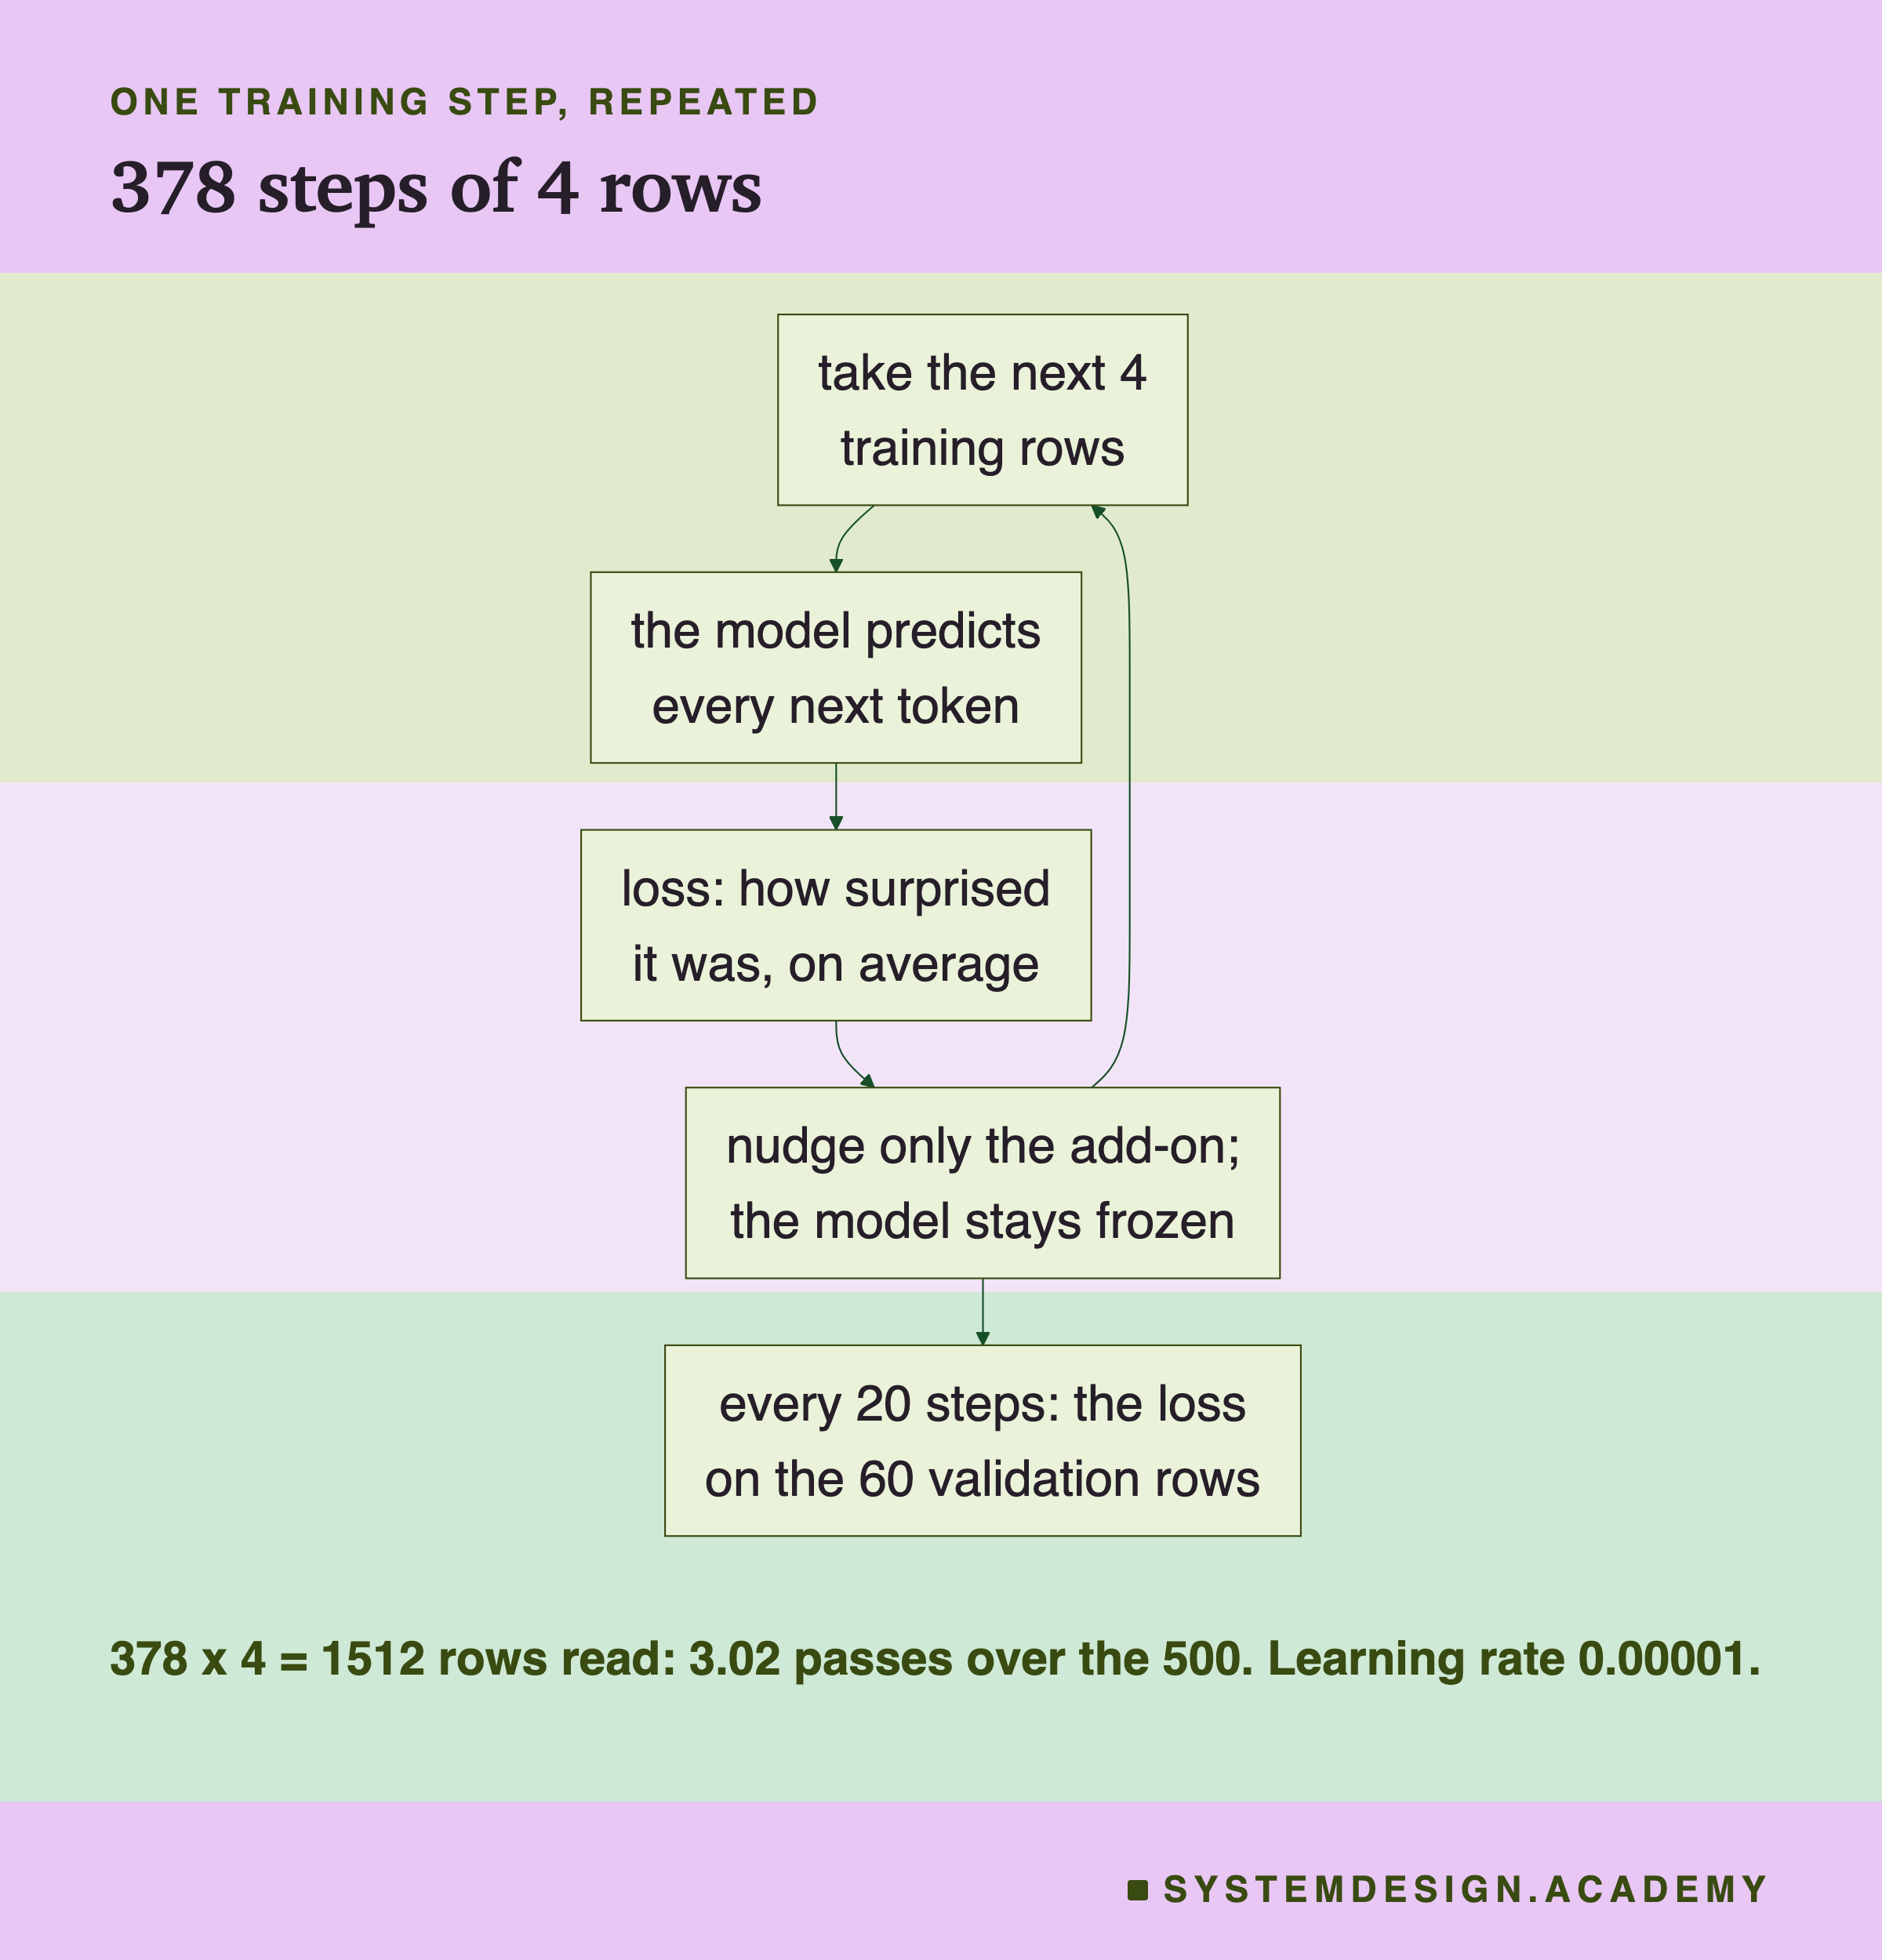
One training step takes four examples, works out the loss, and then changes the trainable weights a tiny amount in the direction that would have made the loss smaller. How big that change is depends on the learning rate, here 0.00001. I ran 378 steps of 4 examples, which is 1,512 examples read, or just over three passes through the 500. Every 20 steps the training program also measured the loss on the 60 validation examples, without learning from them.
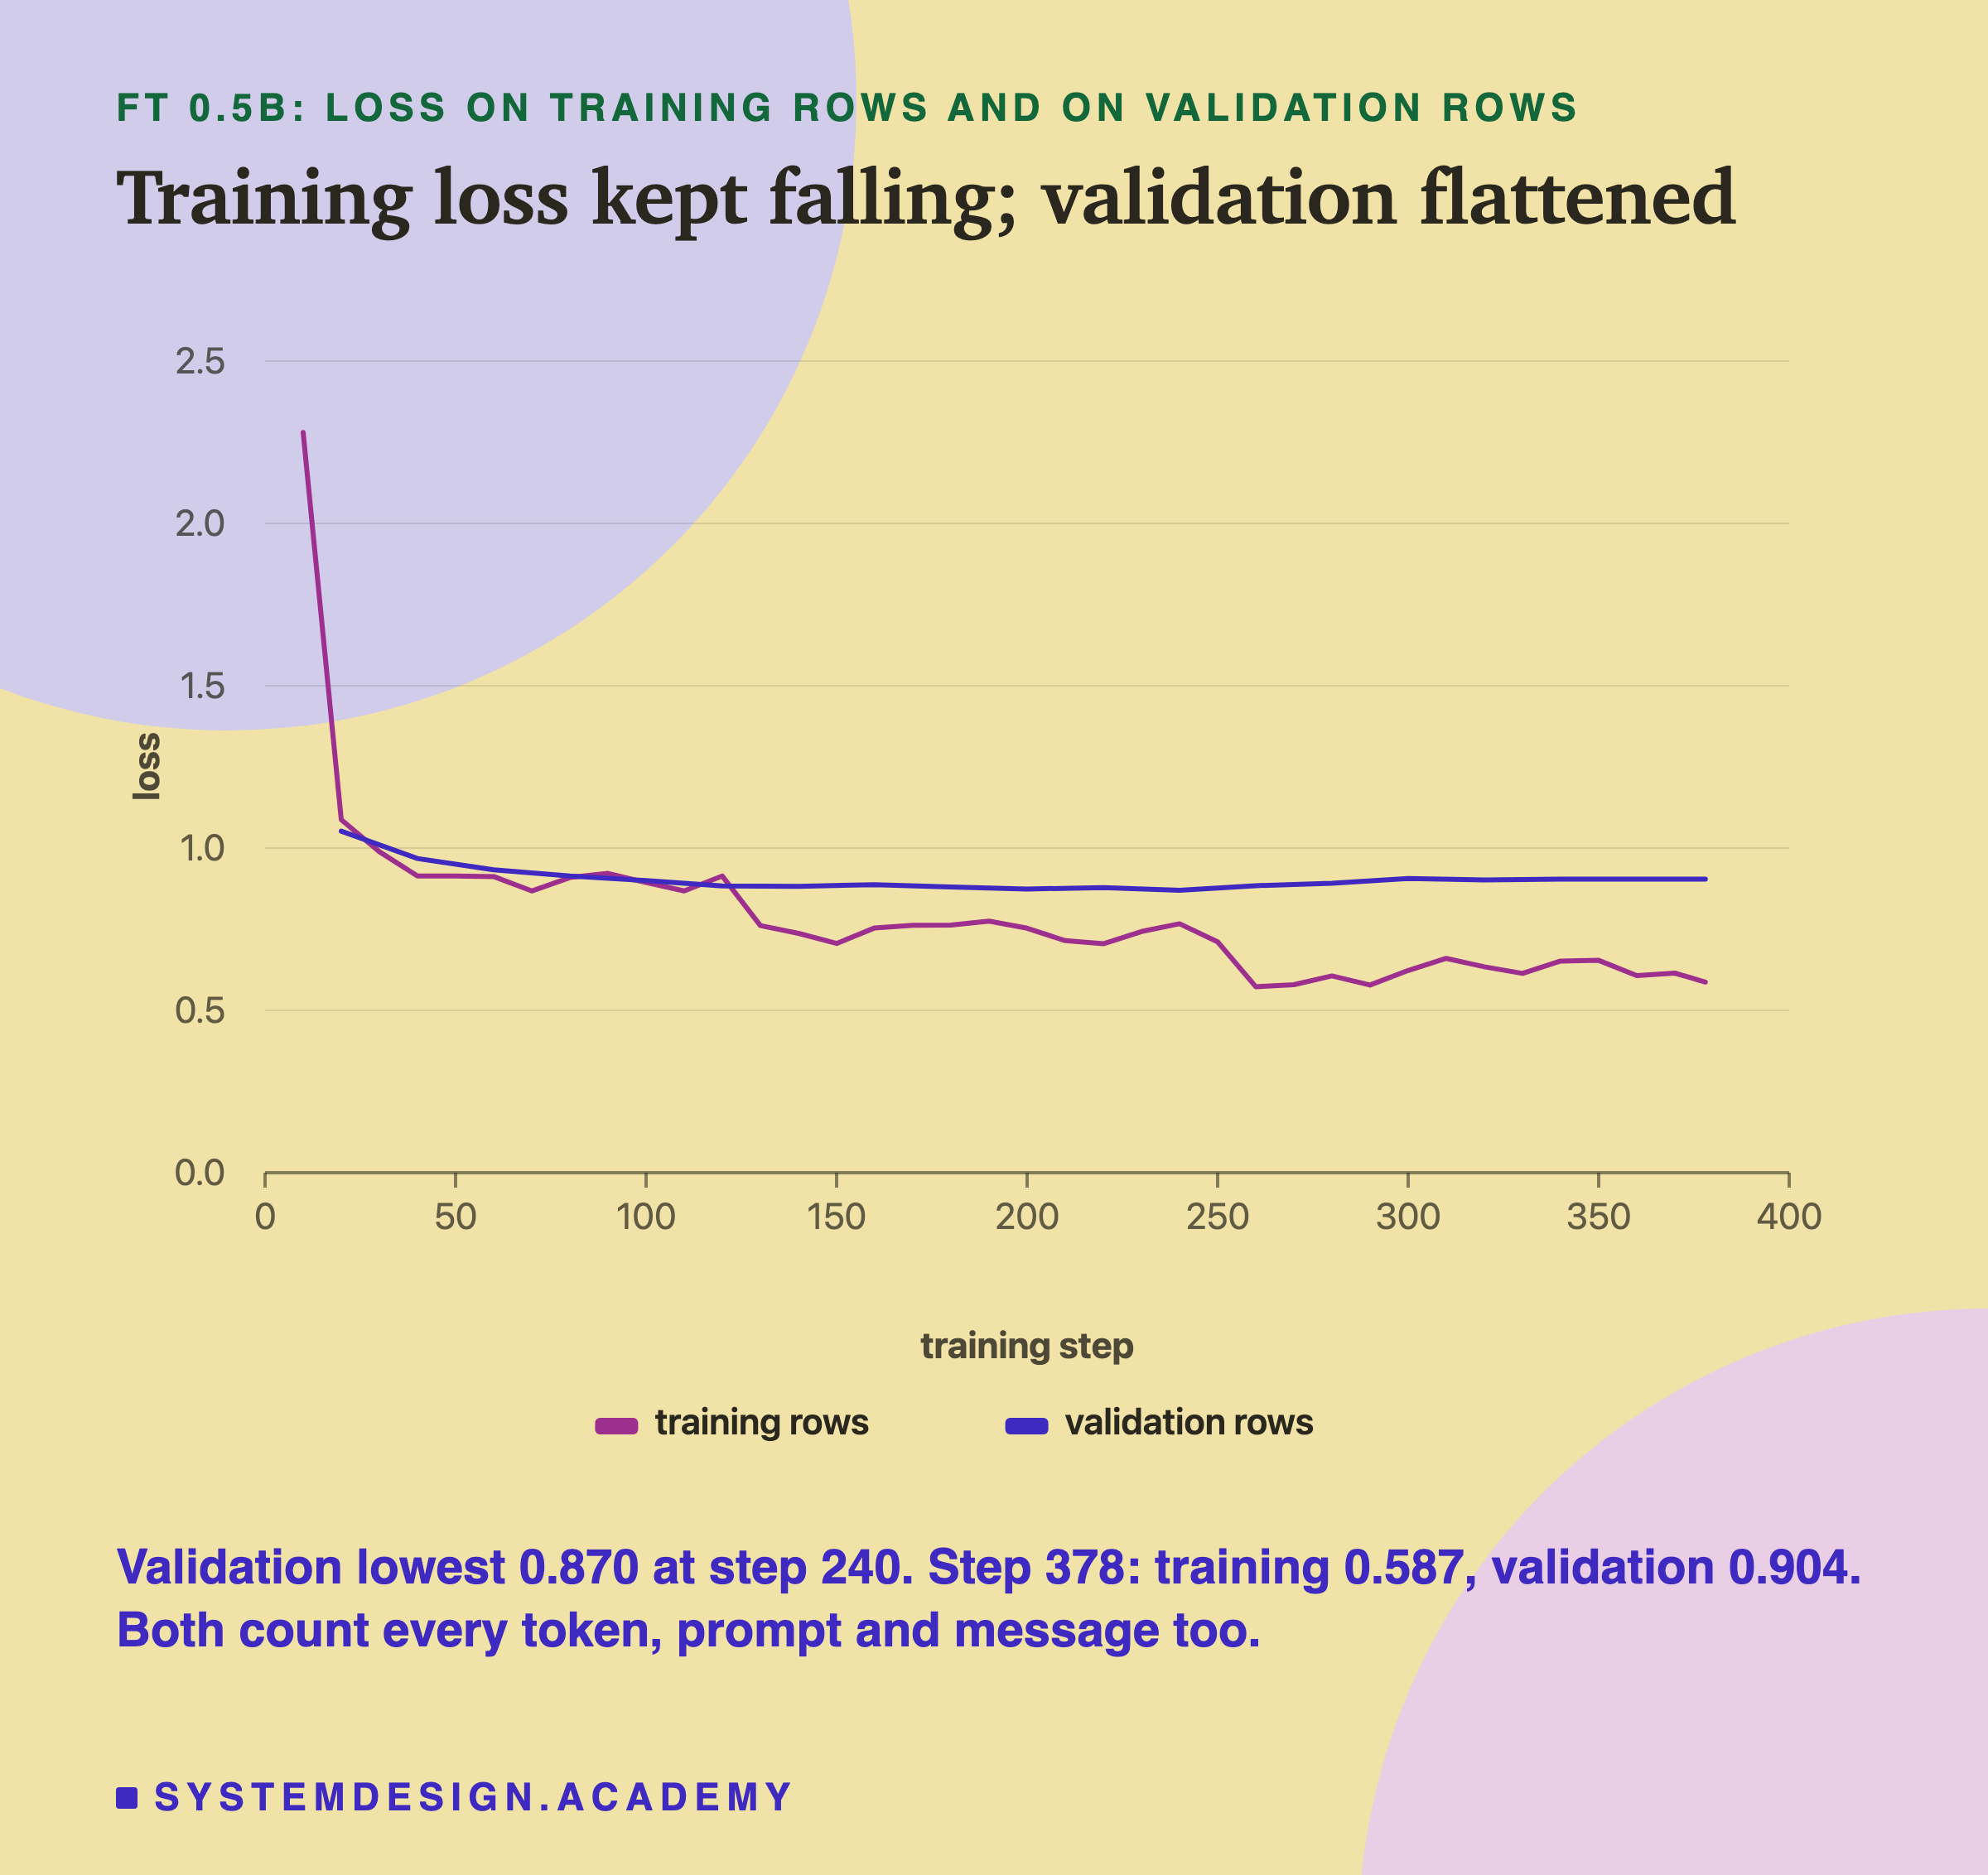
One detail matters for reading the numbers later. With the settings I used, the loss counts every token of the example: the one-line instruction and the customer's message as well as the ticket. The model is being scored partly on guessing what the customer will type, which nobody can guess well. So the loss will never get close to zero, however good the tickets become. A later lesson changes this setting and scores only the ticket.
LoRA: A Small Add-On Beside Frozen Weights
Changing all half a billion weights of even the smallest model would need a lot of memory, and the result would be a full new copy of the model for every task. avoids both. It leaves every original weight exactly as it was and trains a small add-on next to some of the model's layers.
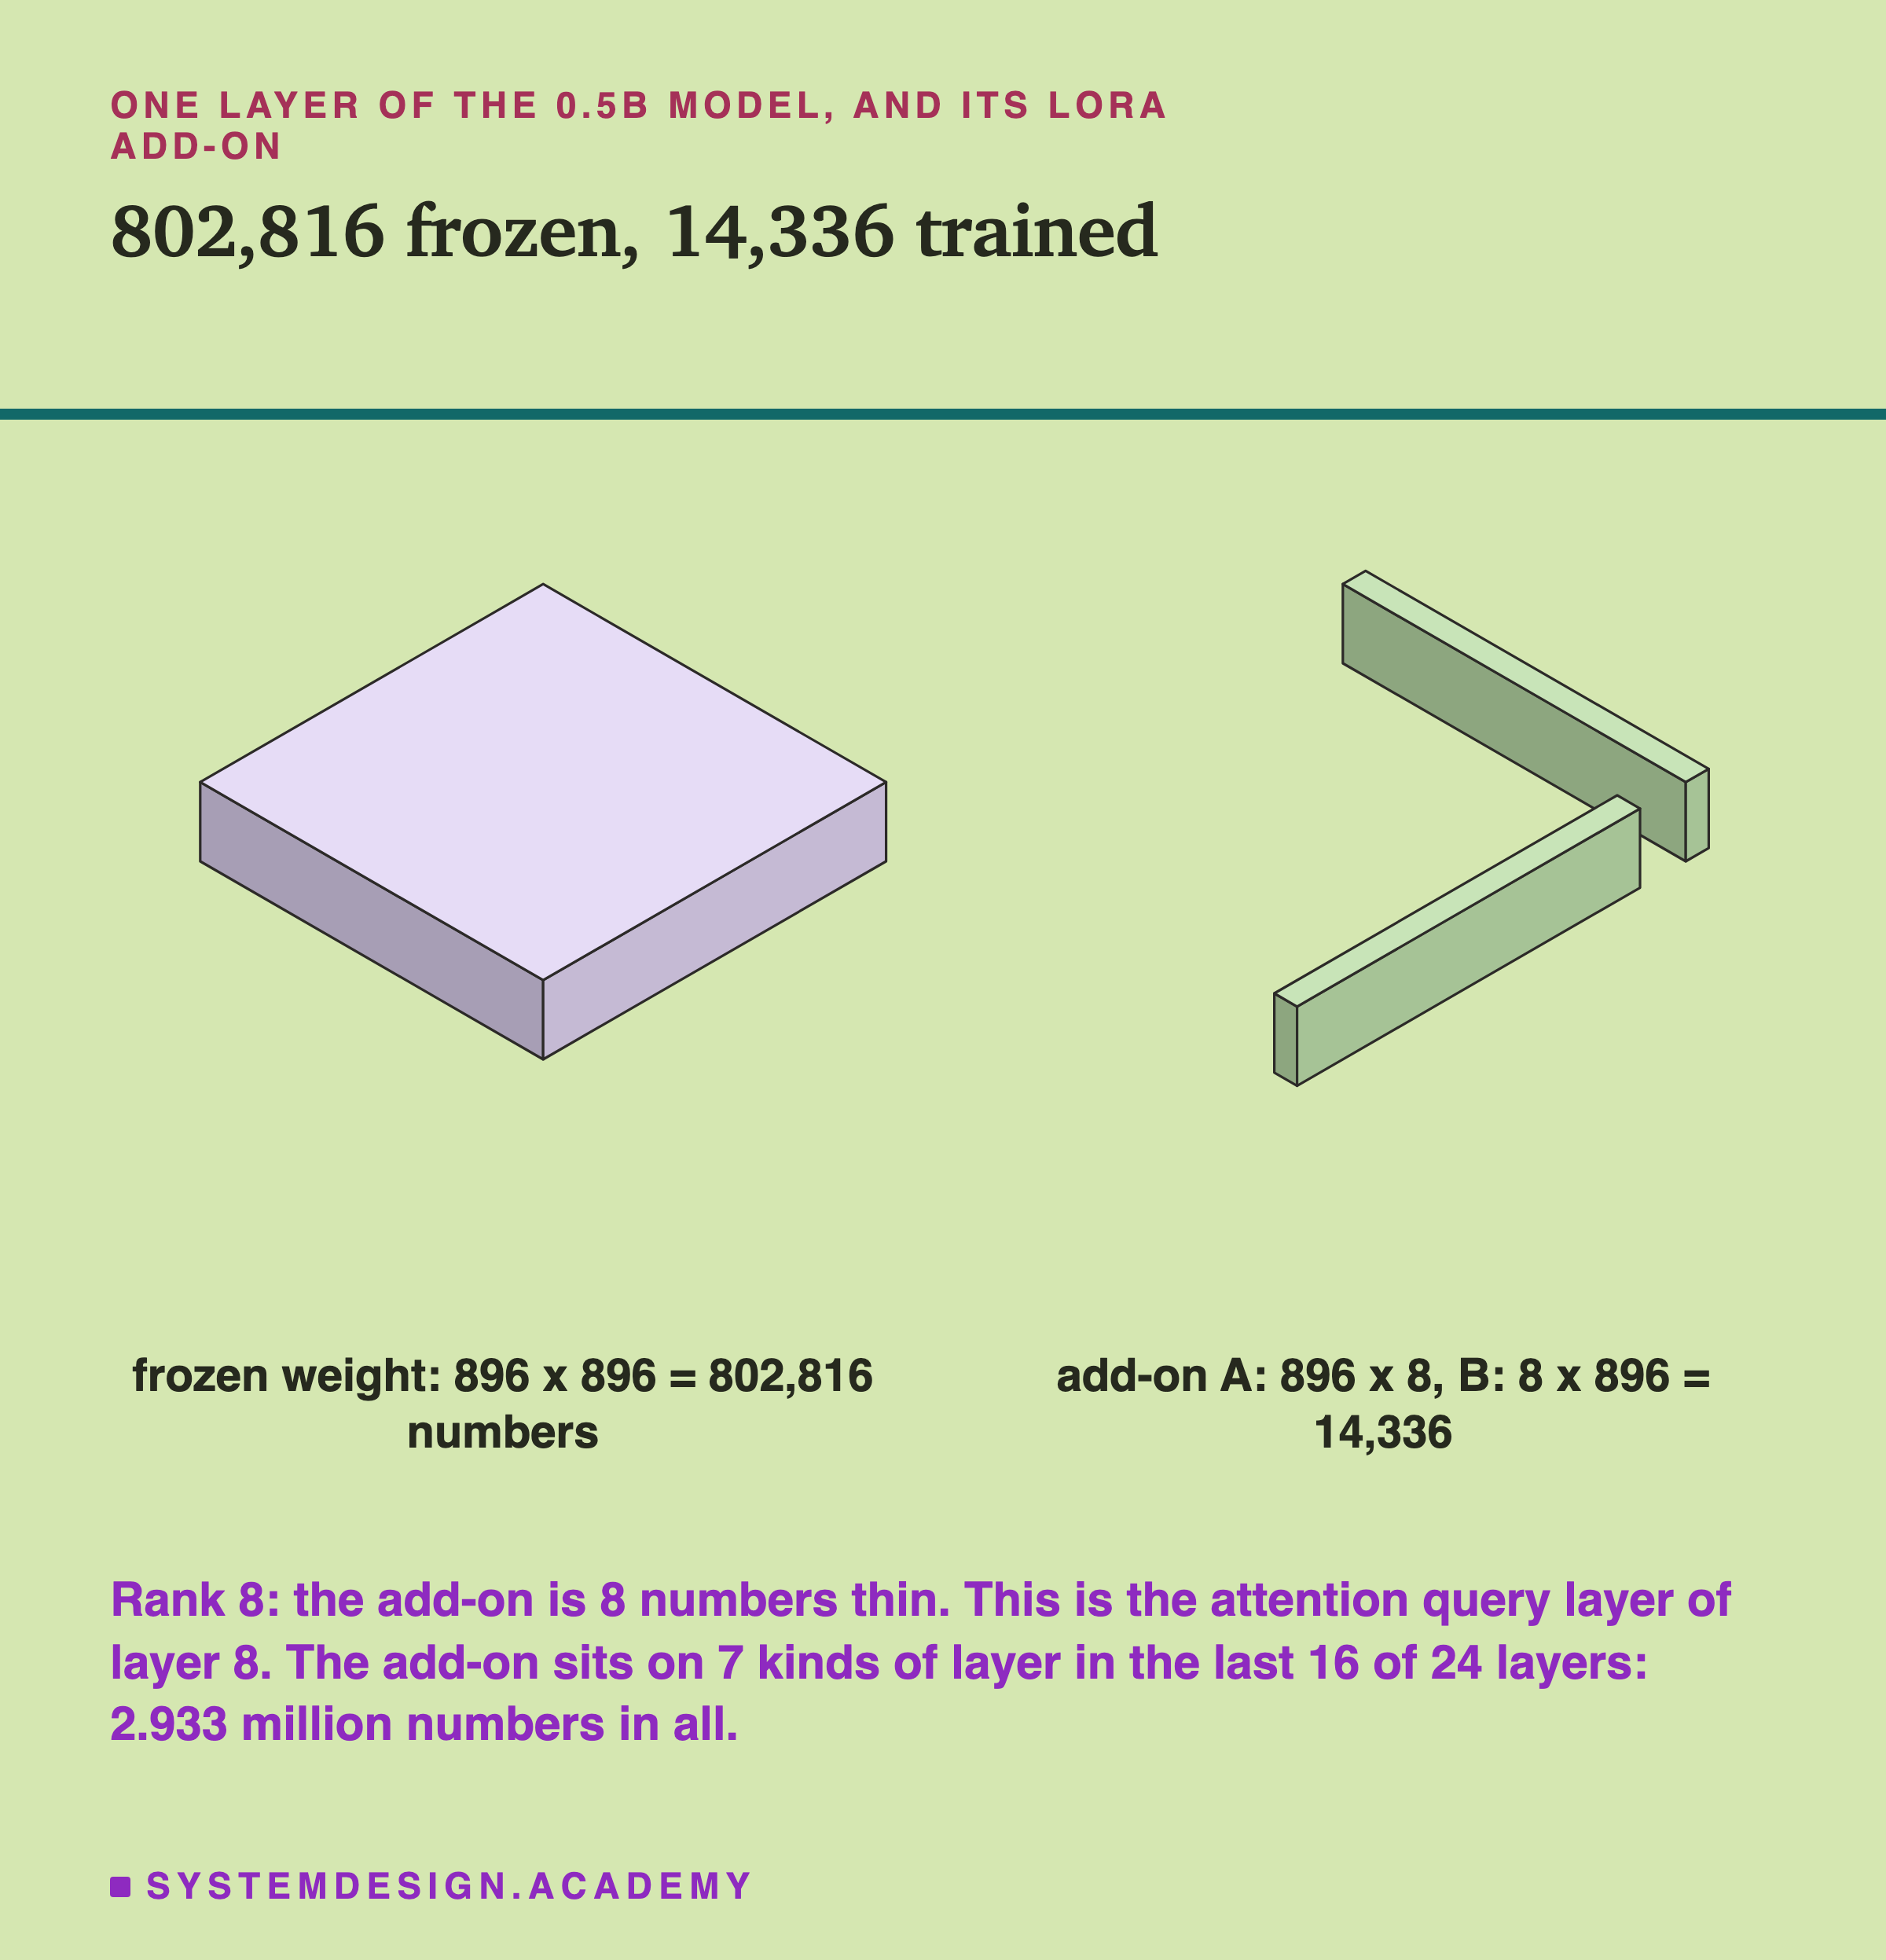
Inside a model, most weights sit in large square or rectangular tables of numbers. Take one table of weights in the 0.5B model, from layer 8. It has 896 rows and 896 columns, which is 802,816 numbers. LoRA puts two thin tables beside it. The first, called A, has 896 rows and only 8 columns. The second, B, has 8 rows and 896 columns. Multiplied together they make a full 896 by 896 correction to add to the frozen table, but they hold only 14,336 numbers between them, under 2% of the table they correct. The 8 is called the rank: it is how thin the add-on is.
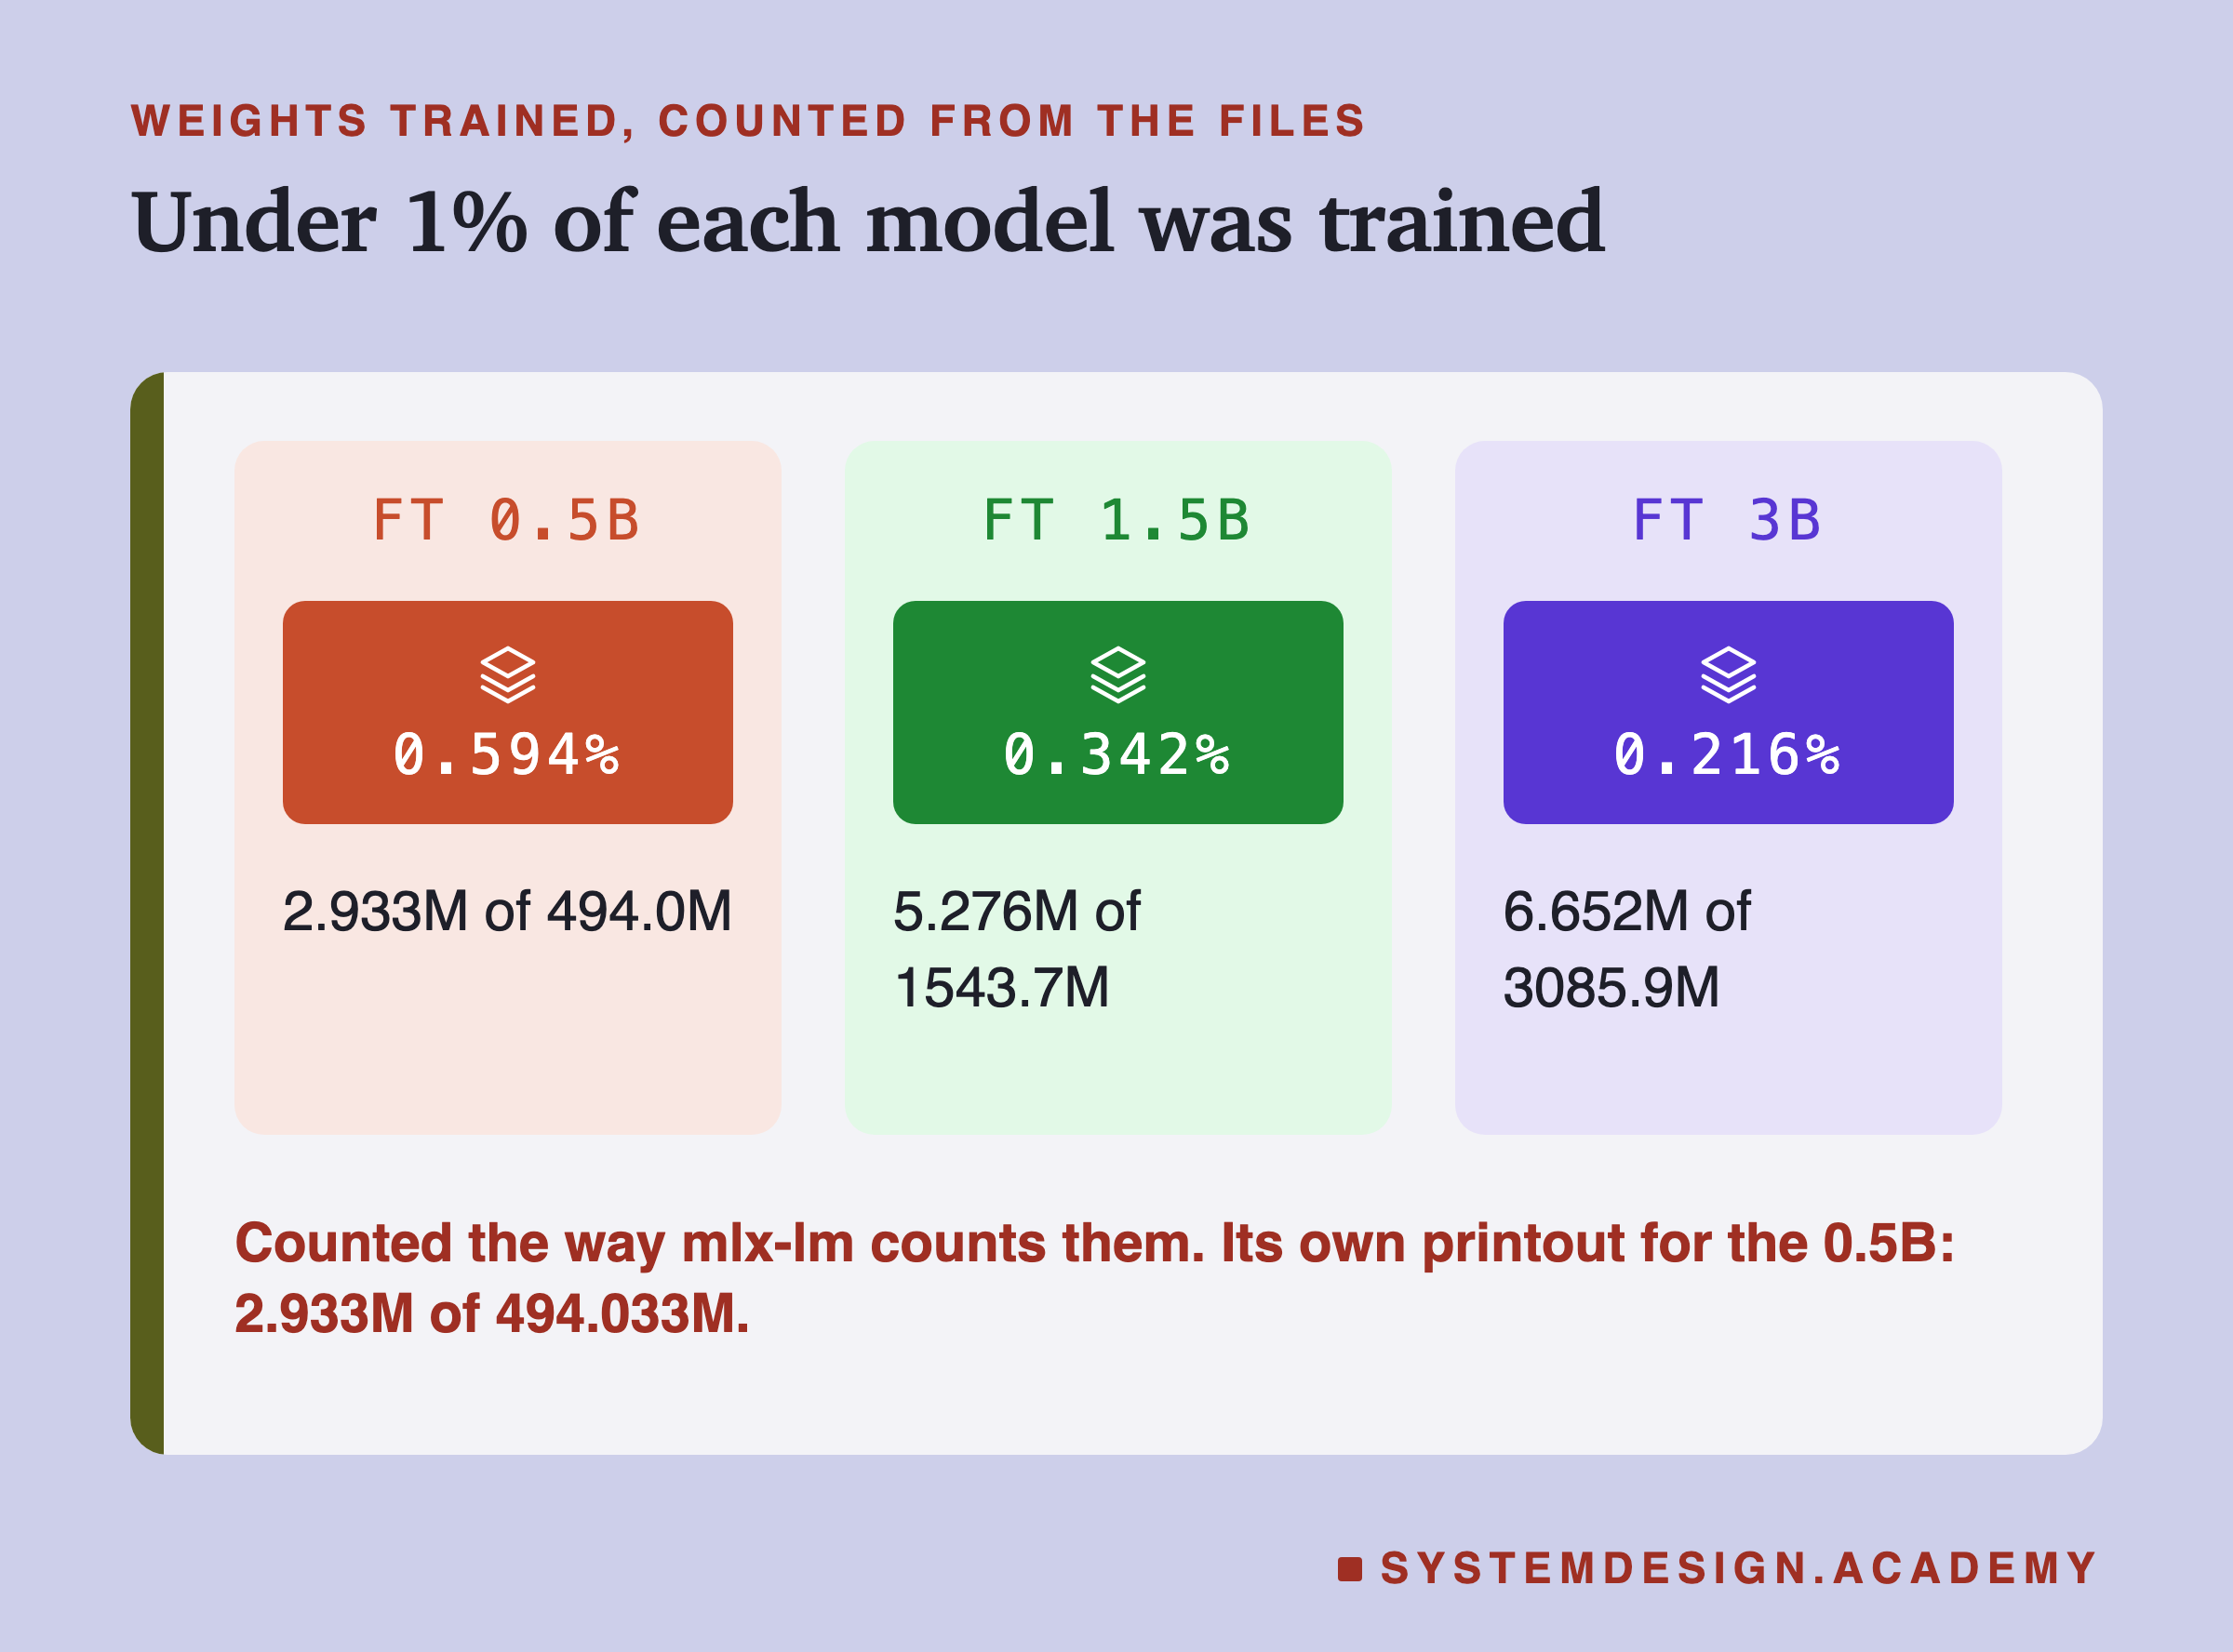
The training program, mlx-lm, puts such an add-on on seven kinds of layer, in the last 16 of the model's layers. For the 0.5B model, that is layers 8 to 23 of its 24. Add them all up and 2.933 million numbers are trained. The model as a whole has 494.0 million, so only 0.594% of it is trained.
I trained three sizes of the same model family: Qwen2.5 Instruct at 0.5B, 1.5B and 3B. The bigger models have more layers and wider tables, so their add-ons are bigger in numbers but smaller as a share: 5.276 million of 1,543.7 million for the 1.5B (0.342%), and 6.652 million of 3,085.9 million for the 3B (0.216%). I counted these from the files themselves, the same way mlx-lm counts them, and when the demo later in this lesson ran, mlx-lm printed the same 2.933 million for the 0.5B.
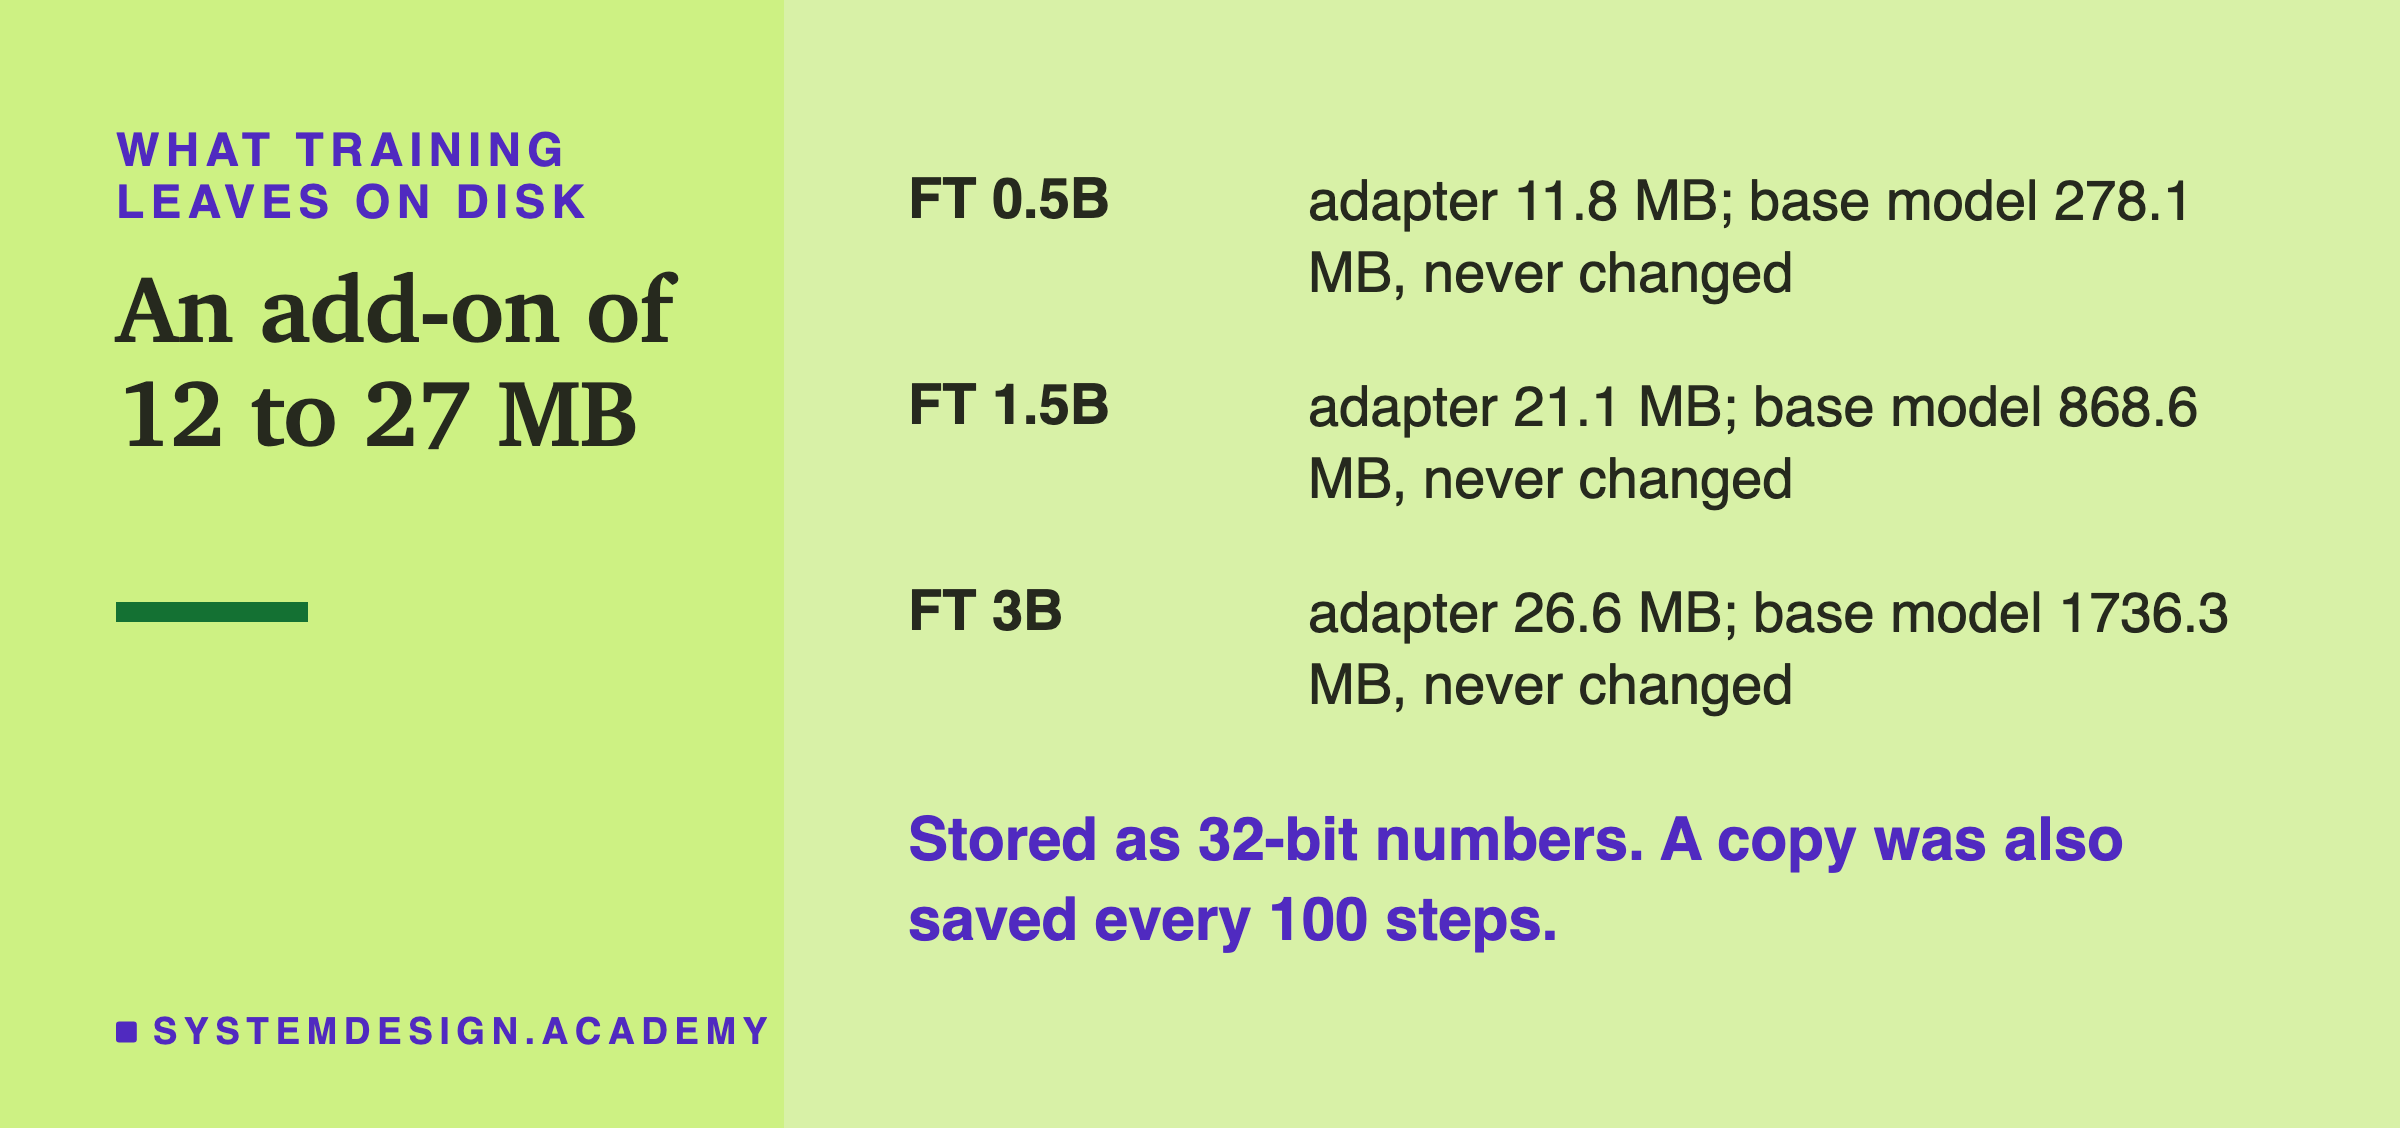
On disk, the result of all the training is the adapter file: 11.8 MB for the 0.5B, 21.1 MB for the 1.5B and 26.6 MB for the 3B. The base models are much larger, 278.1 MB to 1,736.3 MB, and they are not changed at all. That is the practical point of LoRA. You download a base model once, and each task gets its own small file on top. To use the fine-tune, you load the base model and then the adapter.
Two Ways to Give a Model the House Rules
There are now two ways the same rules reach a model. The prompted models from lesson 3 read the full house rules on every single call. The fine-tuned models read one line, because the rules are meant to be inside their add-on.
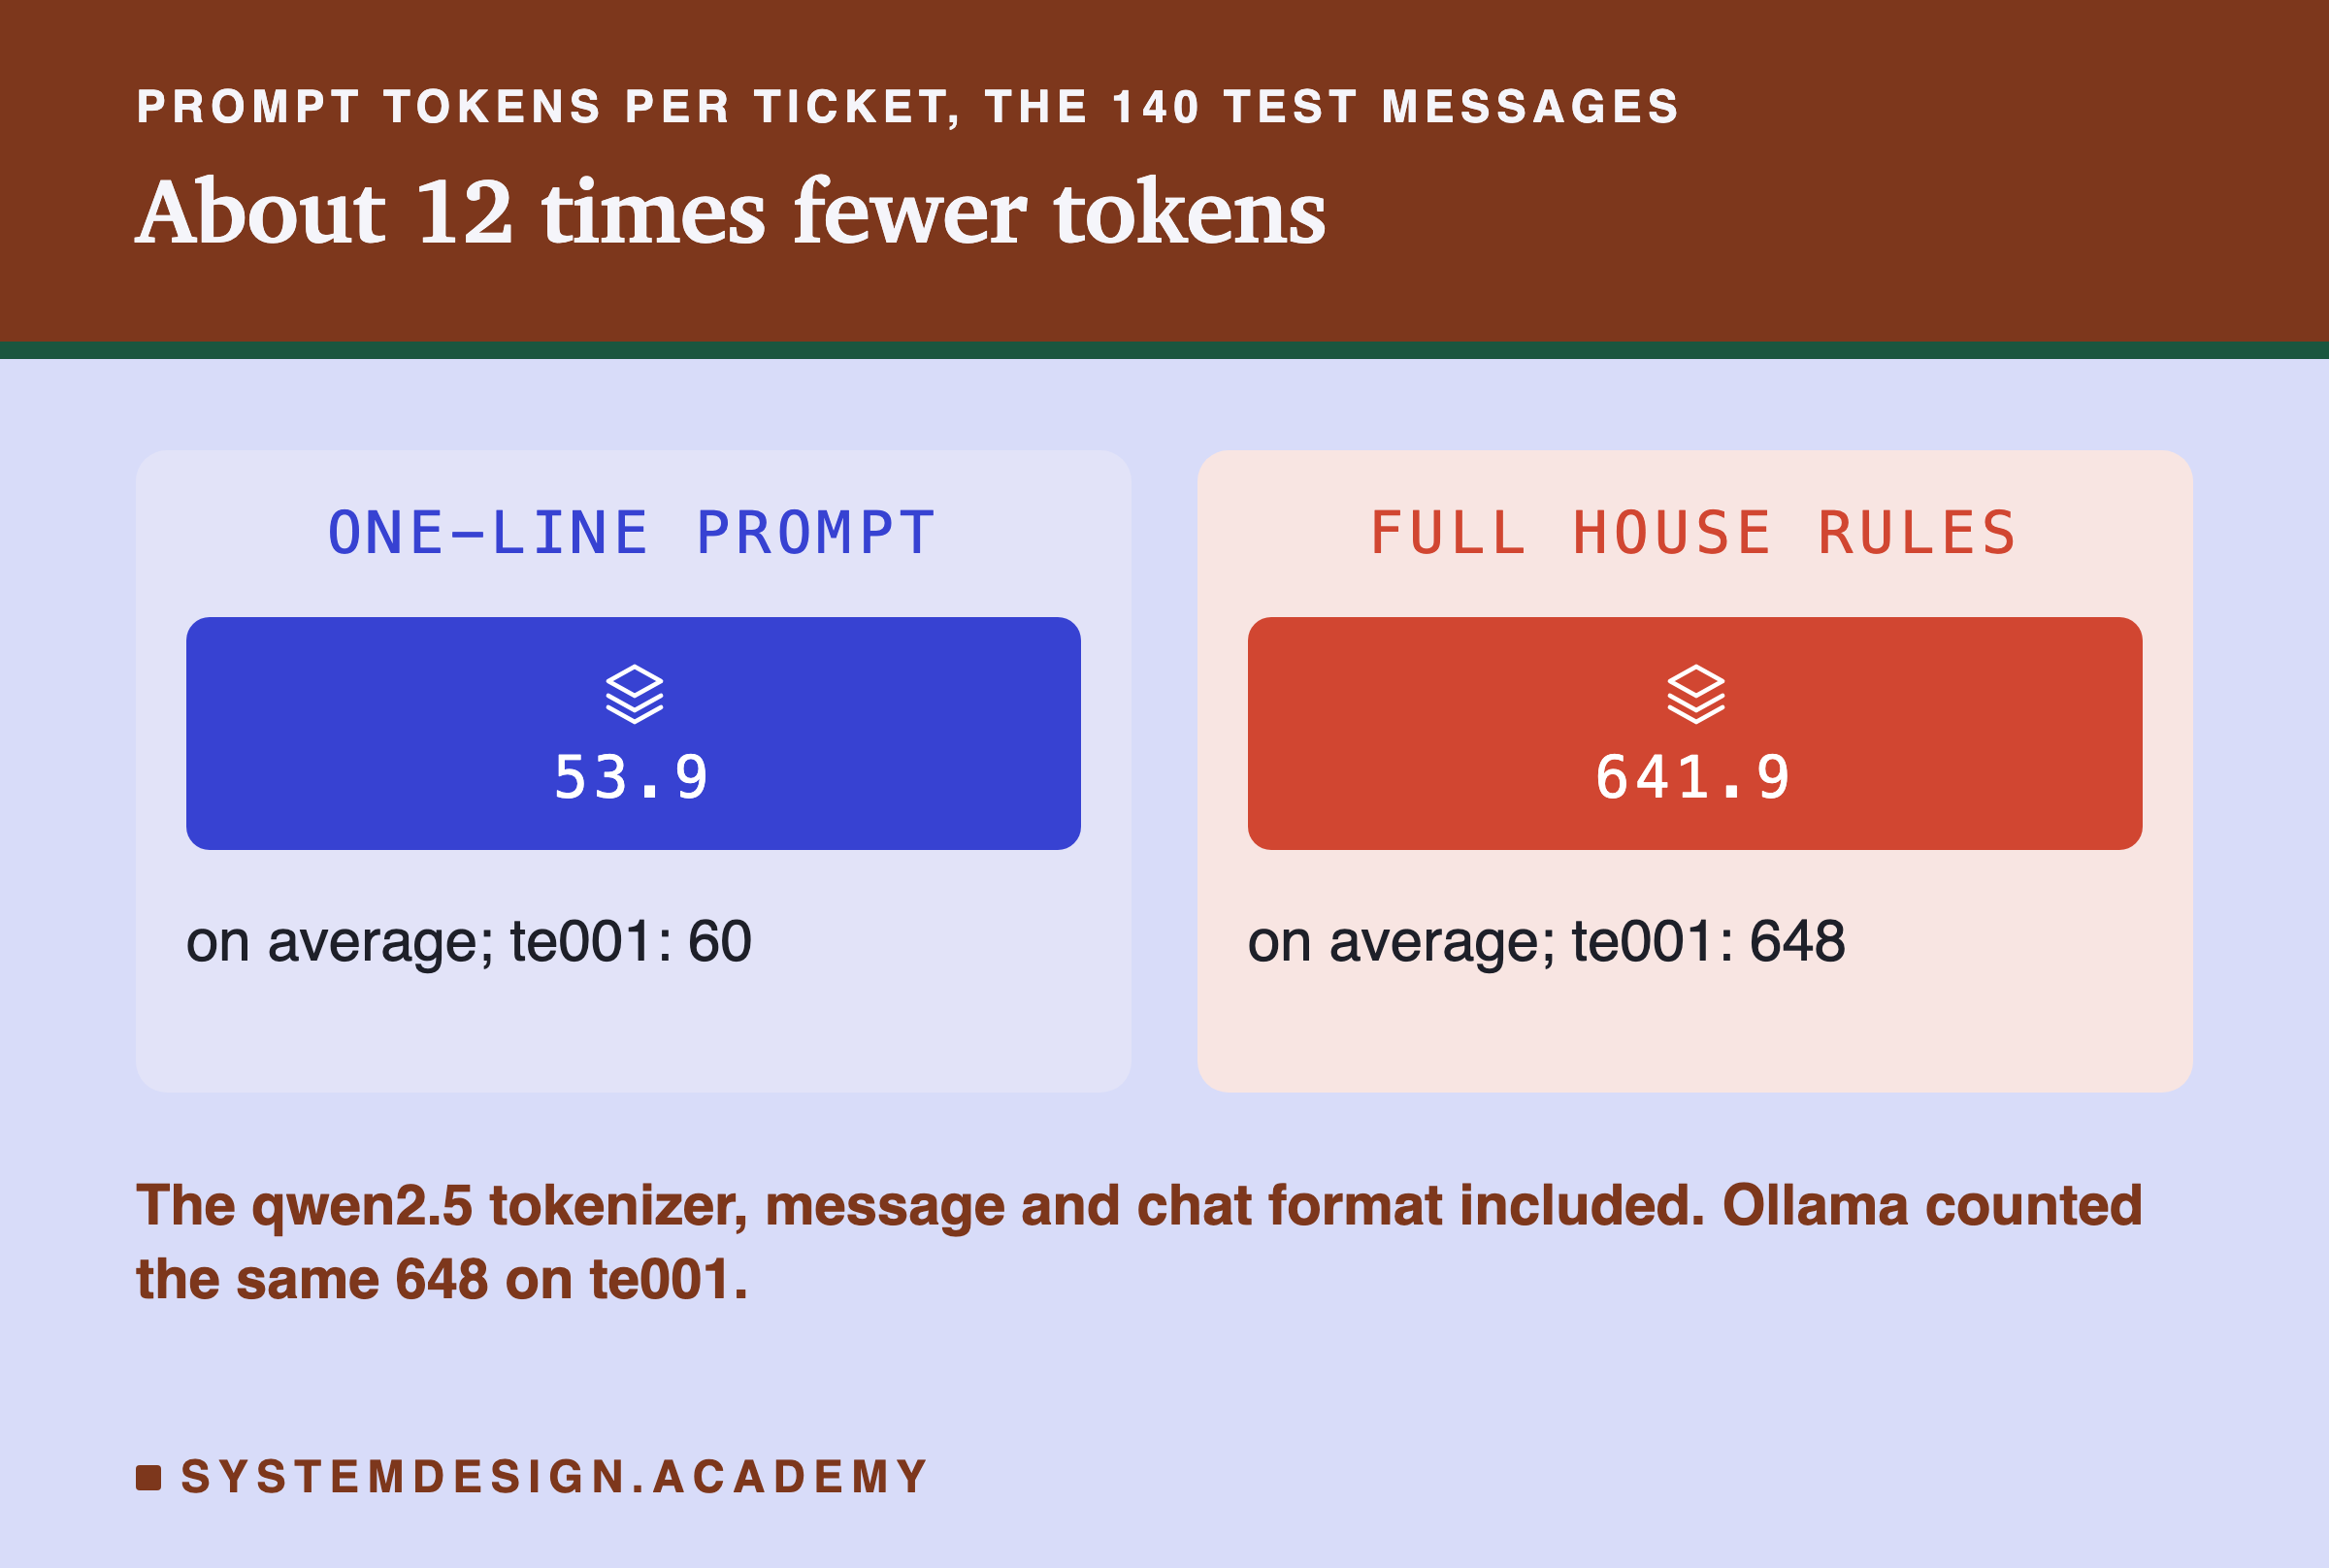
That difference has a cost you can count. I counted the tokens of each prompt with the qwen2.5 tokenizer (the program that splits text into tokens), including the customer's message and the few tokens of chat formatting.
Over the 140 test messages, the one-line prompt came to 53.9 tokens on average and the full rules to 641.9, about 12 times more. On the first test message the counts were 60 and 648, and Ollama's own count for the same prompt in lesson 3 was also 648, so the two ways of counting agree. A model has to read every one of those tokens before it writes anything, on every call.
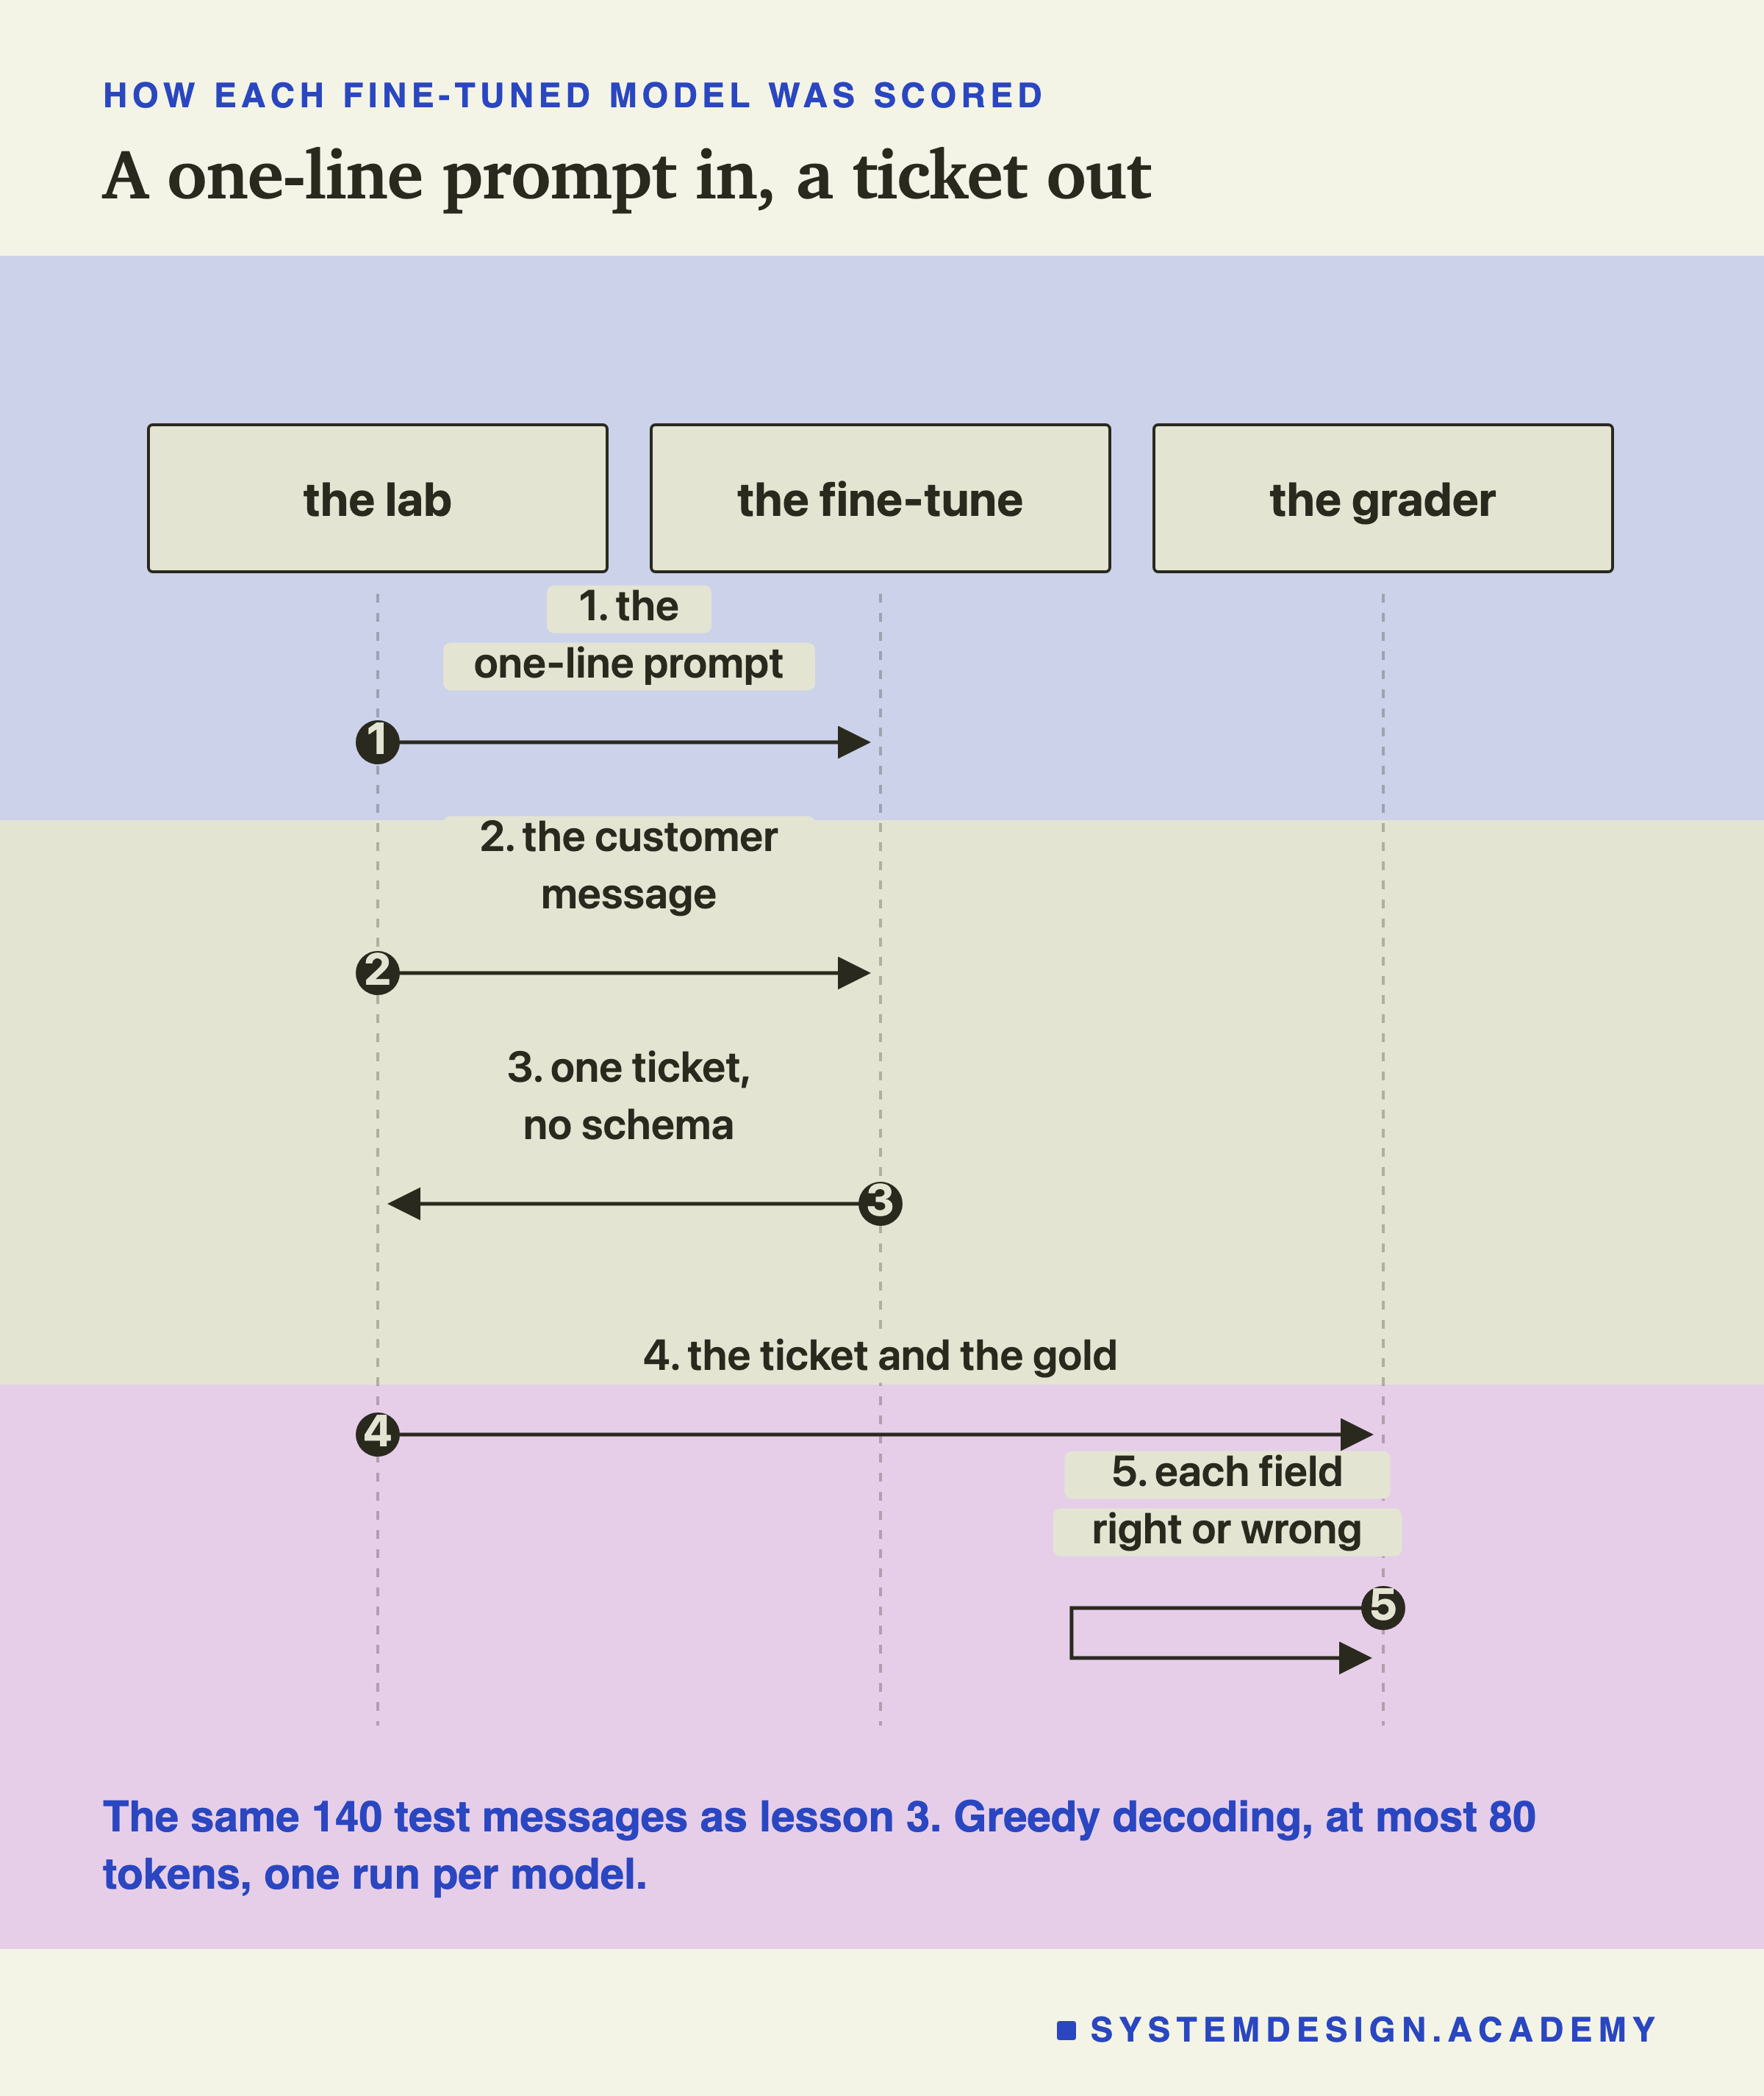
The scoring is the same as in lesson 3: the same 140 test messages, the same gold tickets, the same grader, a field counted only where both annotators agreed, and a whole ticket counted only on the 131 messages where all five fields are gold. Each fine-tune answered once, always taking its most likely next token (greedy decoding), with a limit of 80 tokens of reply; the prompted models, in lesson 3, had a limit of 120.
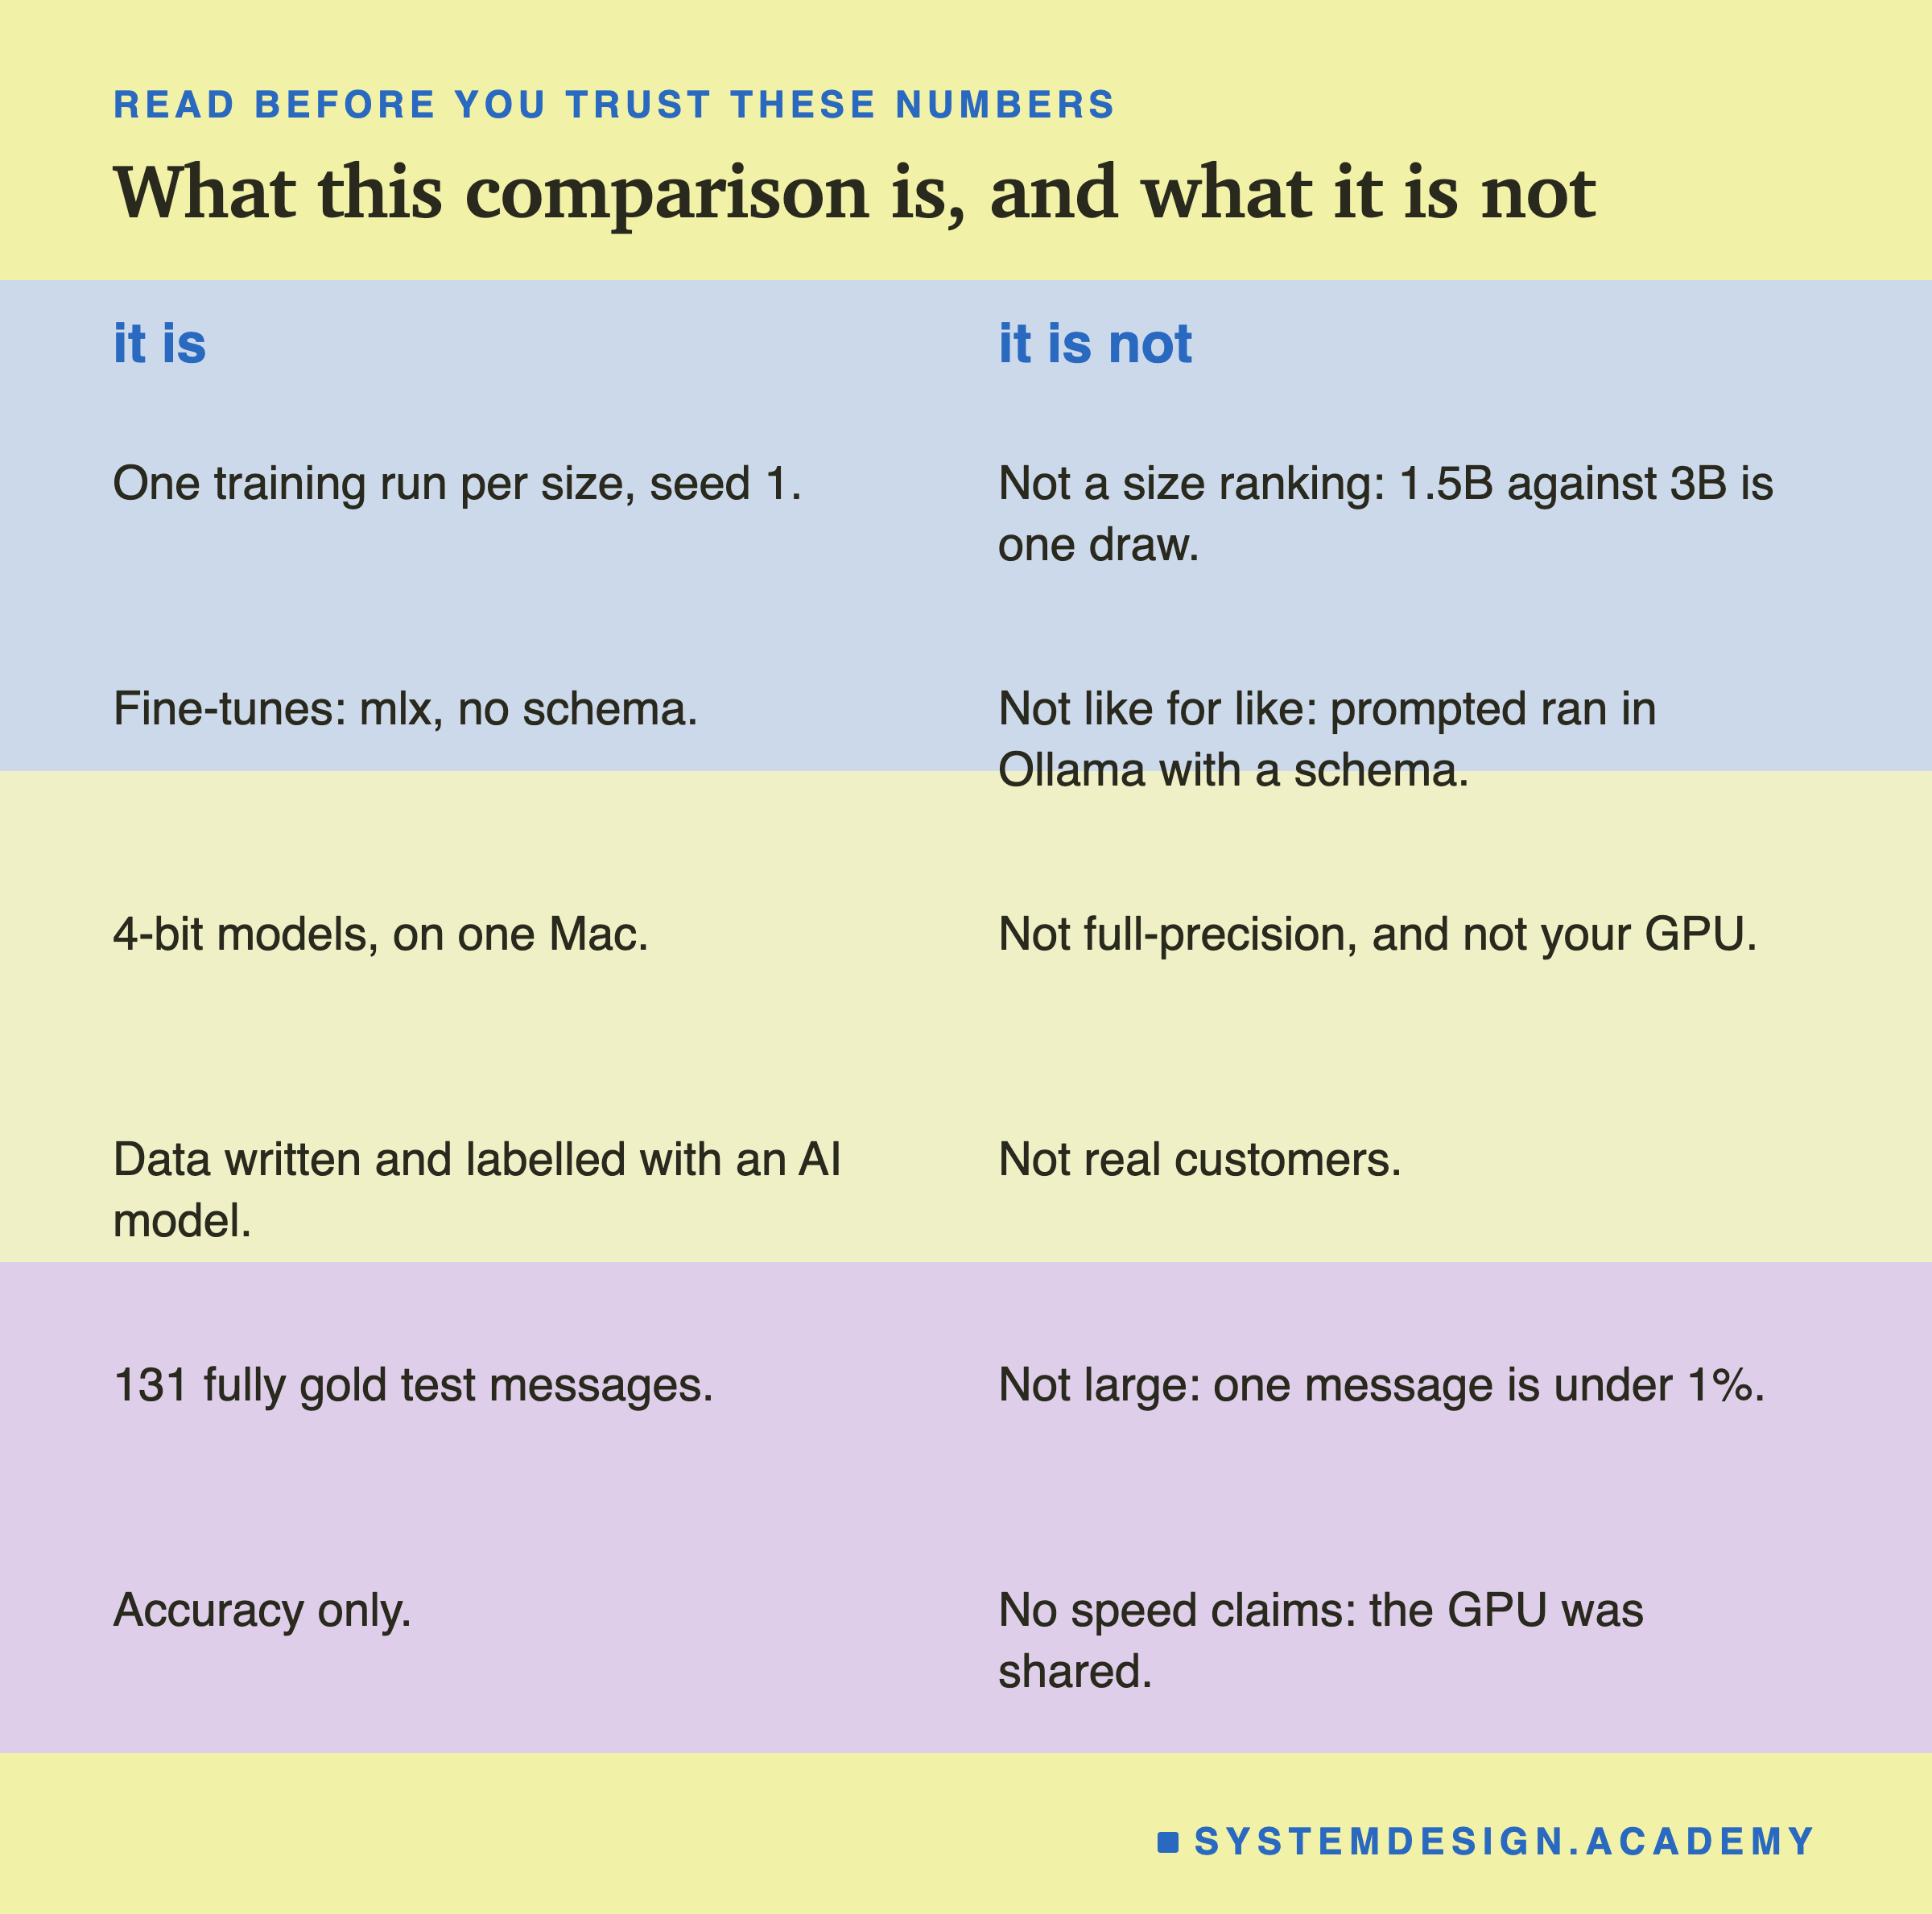
Several differences in the set-up are not fair either way, and you should keep them in mind for every number in this lesson. First, the fine-tunes ran in mlx, Apple's machine learning library, and mlx has no schema option, so nothing forced their replies into the right shape; the prompted models ran in Ollama with a JSON schema. Second, all seven models are 4-bit versions, where each weight is stored in 4 bits instead of 16, which saves memory and can cost a little accuracy. Third, the prompted numbers are the chapter's current ones, rerun with the current house rules; lesson 2 explained that the test labels were changed after prompted models had first been scored on them. Fourth, the reply limit was 80 tokens in mlx and 120 in Ollama; no reply here was a long one, but it is a difference. Fifth, and most important: the fine-tunes learned from 500 answers made by the same labelling process that made the test's gold answers, with the same habits, for example which words of a product name to keep and when to write "other". The prompted models never saw a single example of those habits. And no prompted model had examples in its prompt, which the prompting chapter showed can help, so this lesson cannot separate "examples beat written rules" from "examples in training beat examples in the prompt". It compares a prompt with written rules against a fine-tune, nothing more.
All the training messages, and their labels, were written with an AI model's help, as lesson 2 explained. They are not real customers' messages.
Reading the Loss Curves
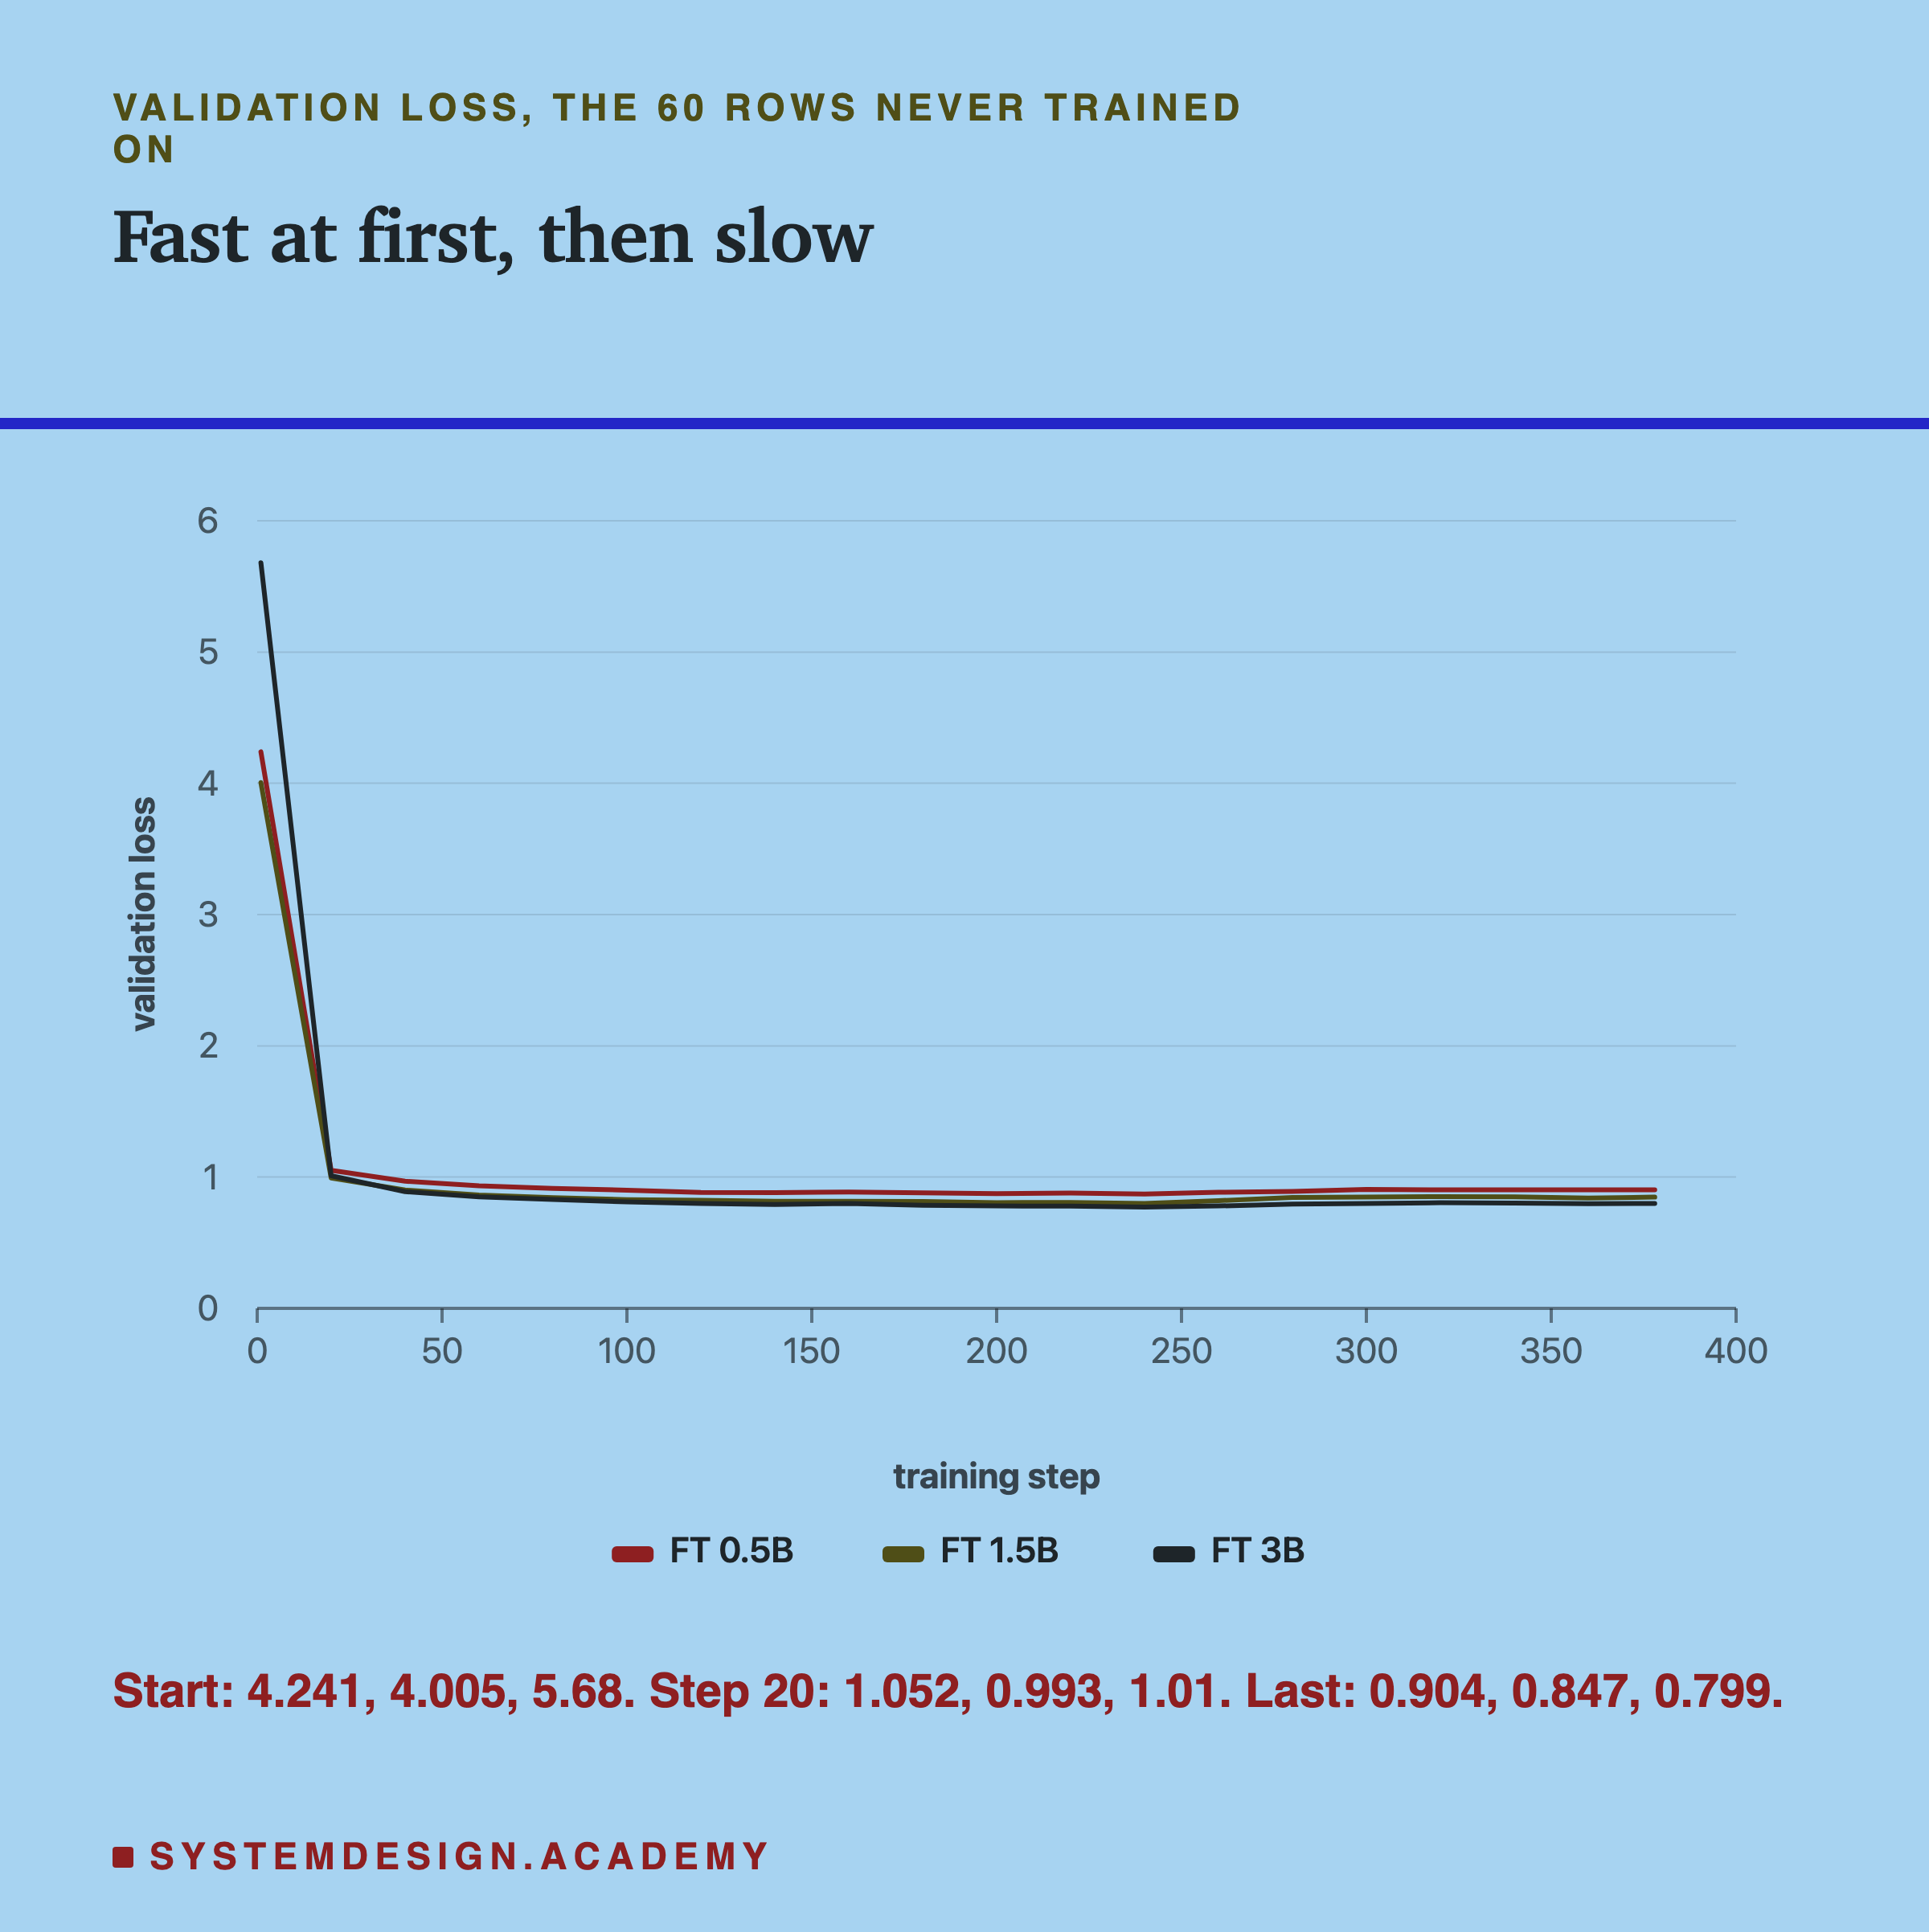
While training runs, mlx-lm prints the loss, and the lab kept every line. These are the curves.
All three models start with a high validation loss: 4.241 for the 0.5B, 4.005 for the 1.5B and 5.68 for the 3B. At that point the model has never seen a ticket in this format, and the one-line instruction tells it very little, so it is surprised by most of what follows. Then something happens very fast. By step 20, after only 80 examples, all three are close to 1. Most of what the loss measures is learned almost at once. Part of it is simply that every example starts with the same one-line instruction and the same chat format, which the model soon predicts almost perfectly; the rest is the shape of the reply: one line of JSON, with these five keys, in this order, with these kinds of values.
After that the curves are nearly flat. From step 20 to step 378 the validation loss of the 0.5B went from 1.052 to 0.904. That slow part is where the finer rules have to be learned, and a small change in the average can hide a large change on the few tokens that matter, such as one word of the "wants" field. That is why I never judge a fine-tune by its loss alone. The scores on the next slides are what count.
The second chart puts the 0.5B's two losses side by side. The loss on the training examples kept falling, to 0.587 at the last step. The loss on the validation examples fell slowly to its lowest, 0.870 at step 240, and then rose a little, ending at 0.904. When training loss keeps dropping while validation loss stops dropping or rises, the model is starting to learn things that are true of its 500 training examples but not of new ones, such as the exact wording of particular messages. With three passes this is still a small gap. I did not score the saved checkpoints on the test messages, so this lesson cannot say whether stopping earlier would have given better tickets. A later lesson trains for longer on purpose to see what happens when the gap grows.
The final validation loss was lower for bigger models: 0.904, 0.847 and 0.799. That is what you would expect, but remember what the loss contains. It is mostly about predicting the customers' own words, which a larger model does better anyway. It does not tell you which model writes better tickets.
Field by Field, Against the Prompts
Now the scores. The first thing to check is the shape of the replies, because the fine-tunes had no schema to hold them. All 140 replies from all three fine-tunes were valid JSON, with the five keys in order. In 140 times 3 replies, only one value was outside the allowed words: the 0.5B once wrote the category "address", which I come back to later.
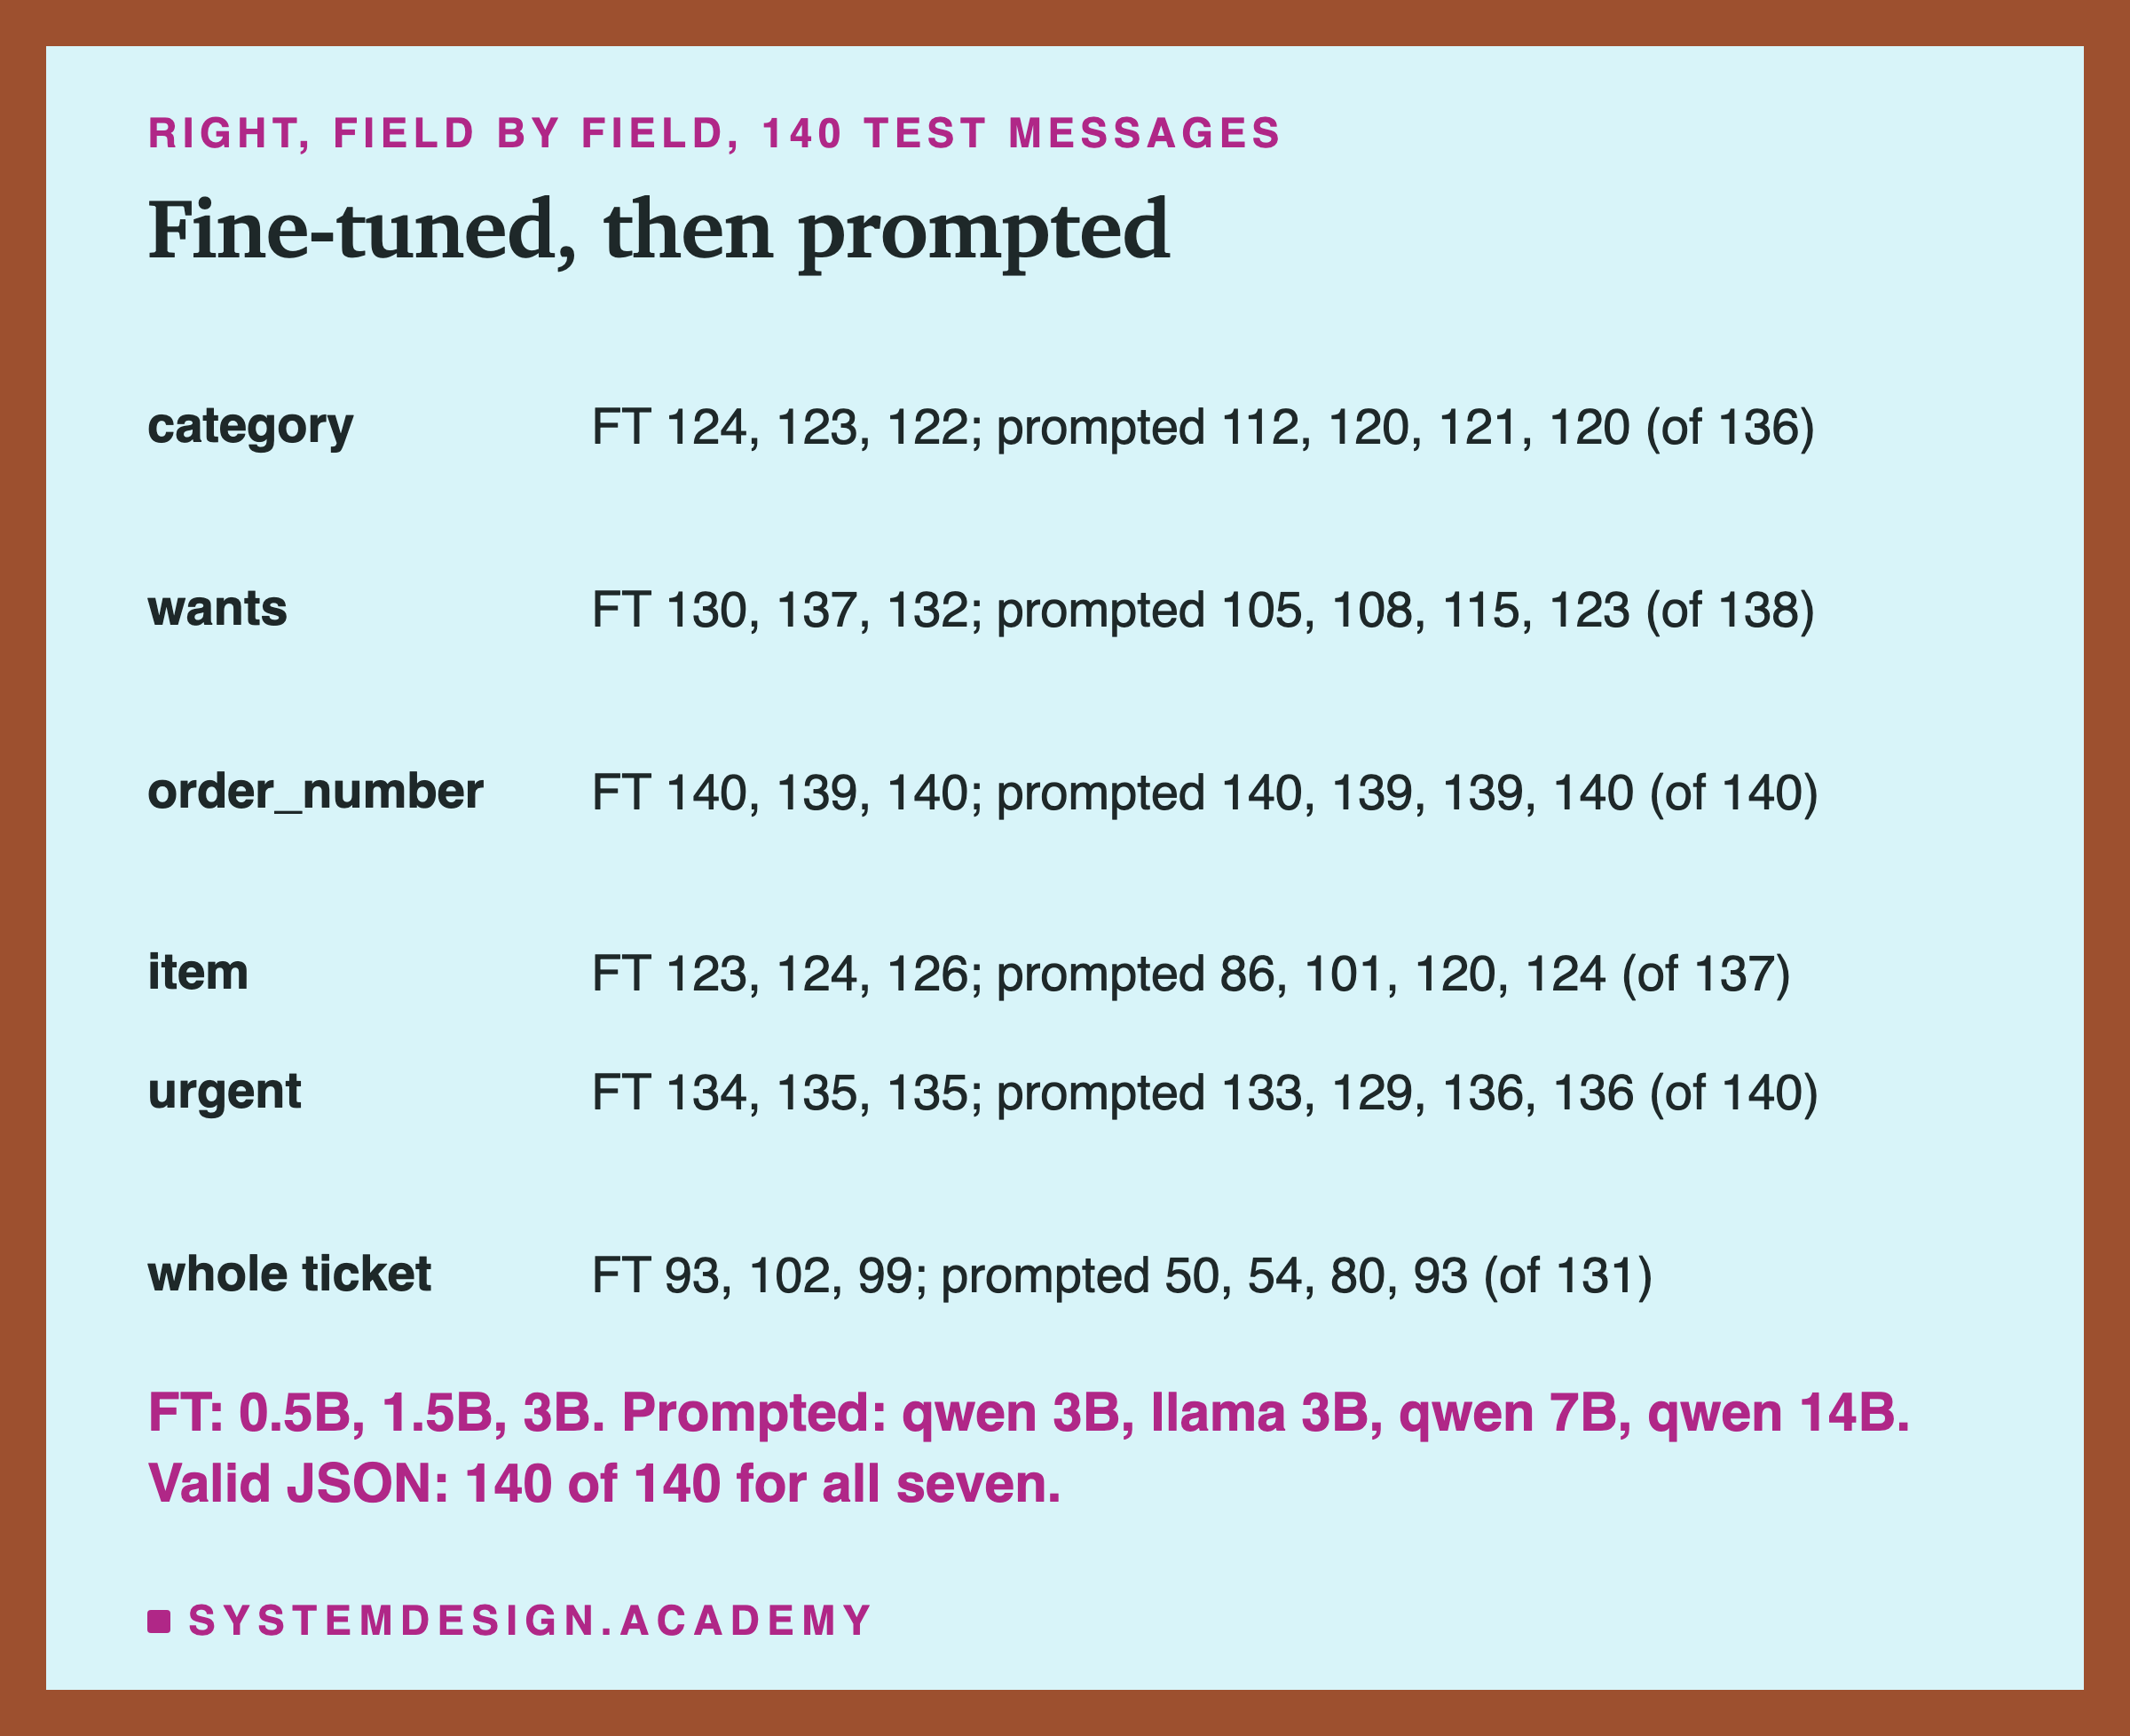
Field by field, the fine-tunes did as well as the best prompted model or better on almost everything. The order number was right on 139 or 140 of 140 for every model, trained or prompted; copying digits was never the hard part. On wants, the field the prompted models found hardest, the fine-tunes got 130, 137 and 132 of 138, against 105 to 123 for the prompted models. On category they got 122 to 124 of 136, against 112 to 121. On item they got 123 to 126 of 137, about the same as the prompted qwen2.5:7b and qwen2.5:14b. On urgent they got 134 or 135 of 140, about the same as the best prompted models.
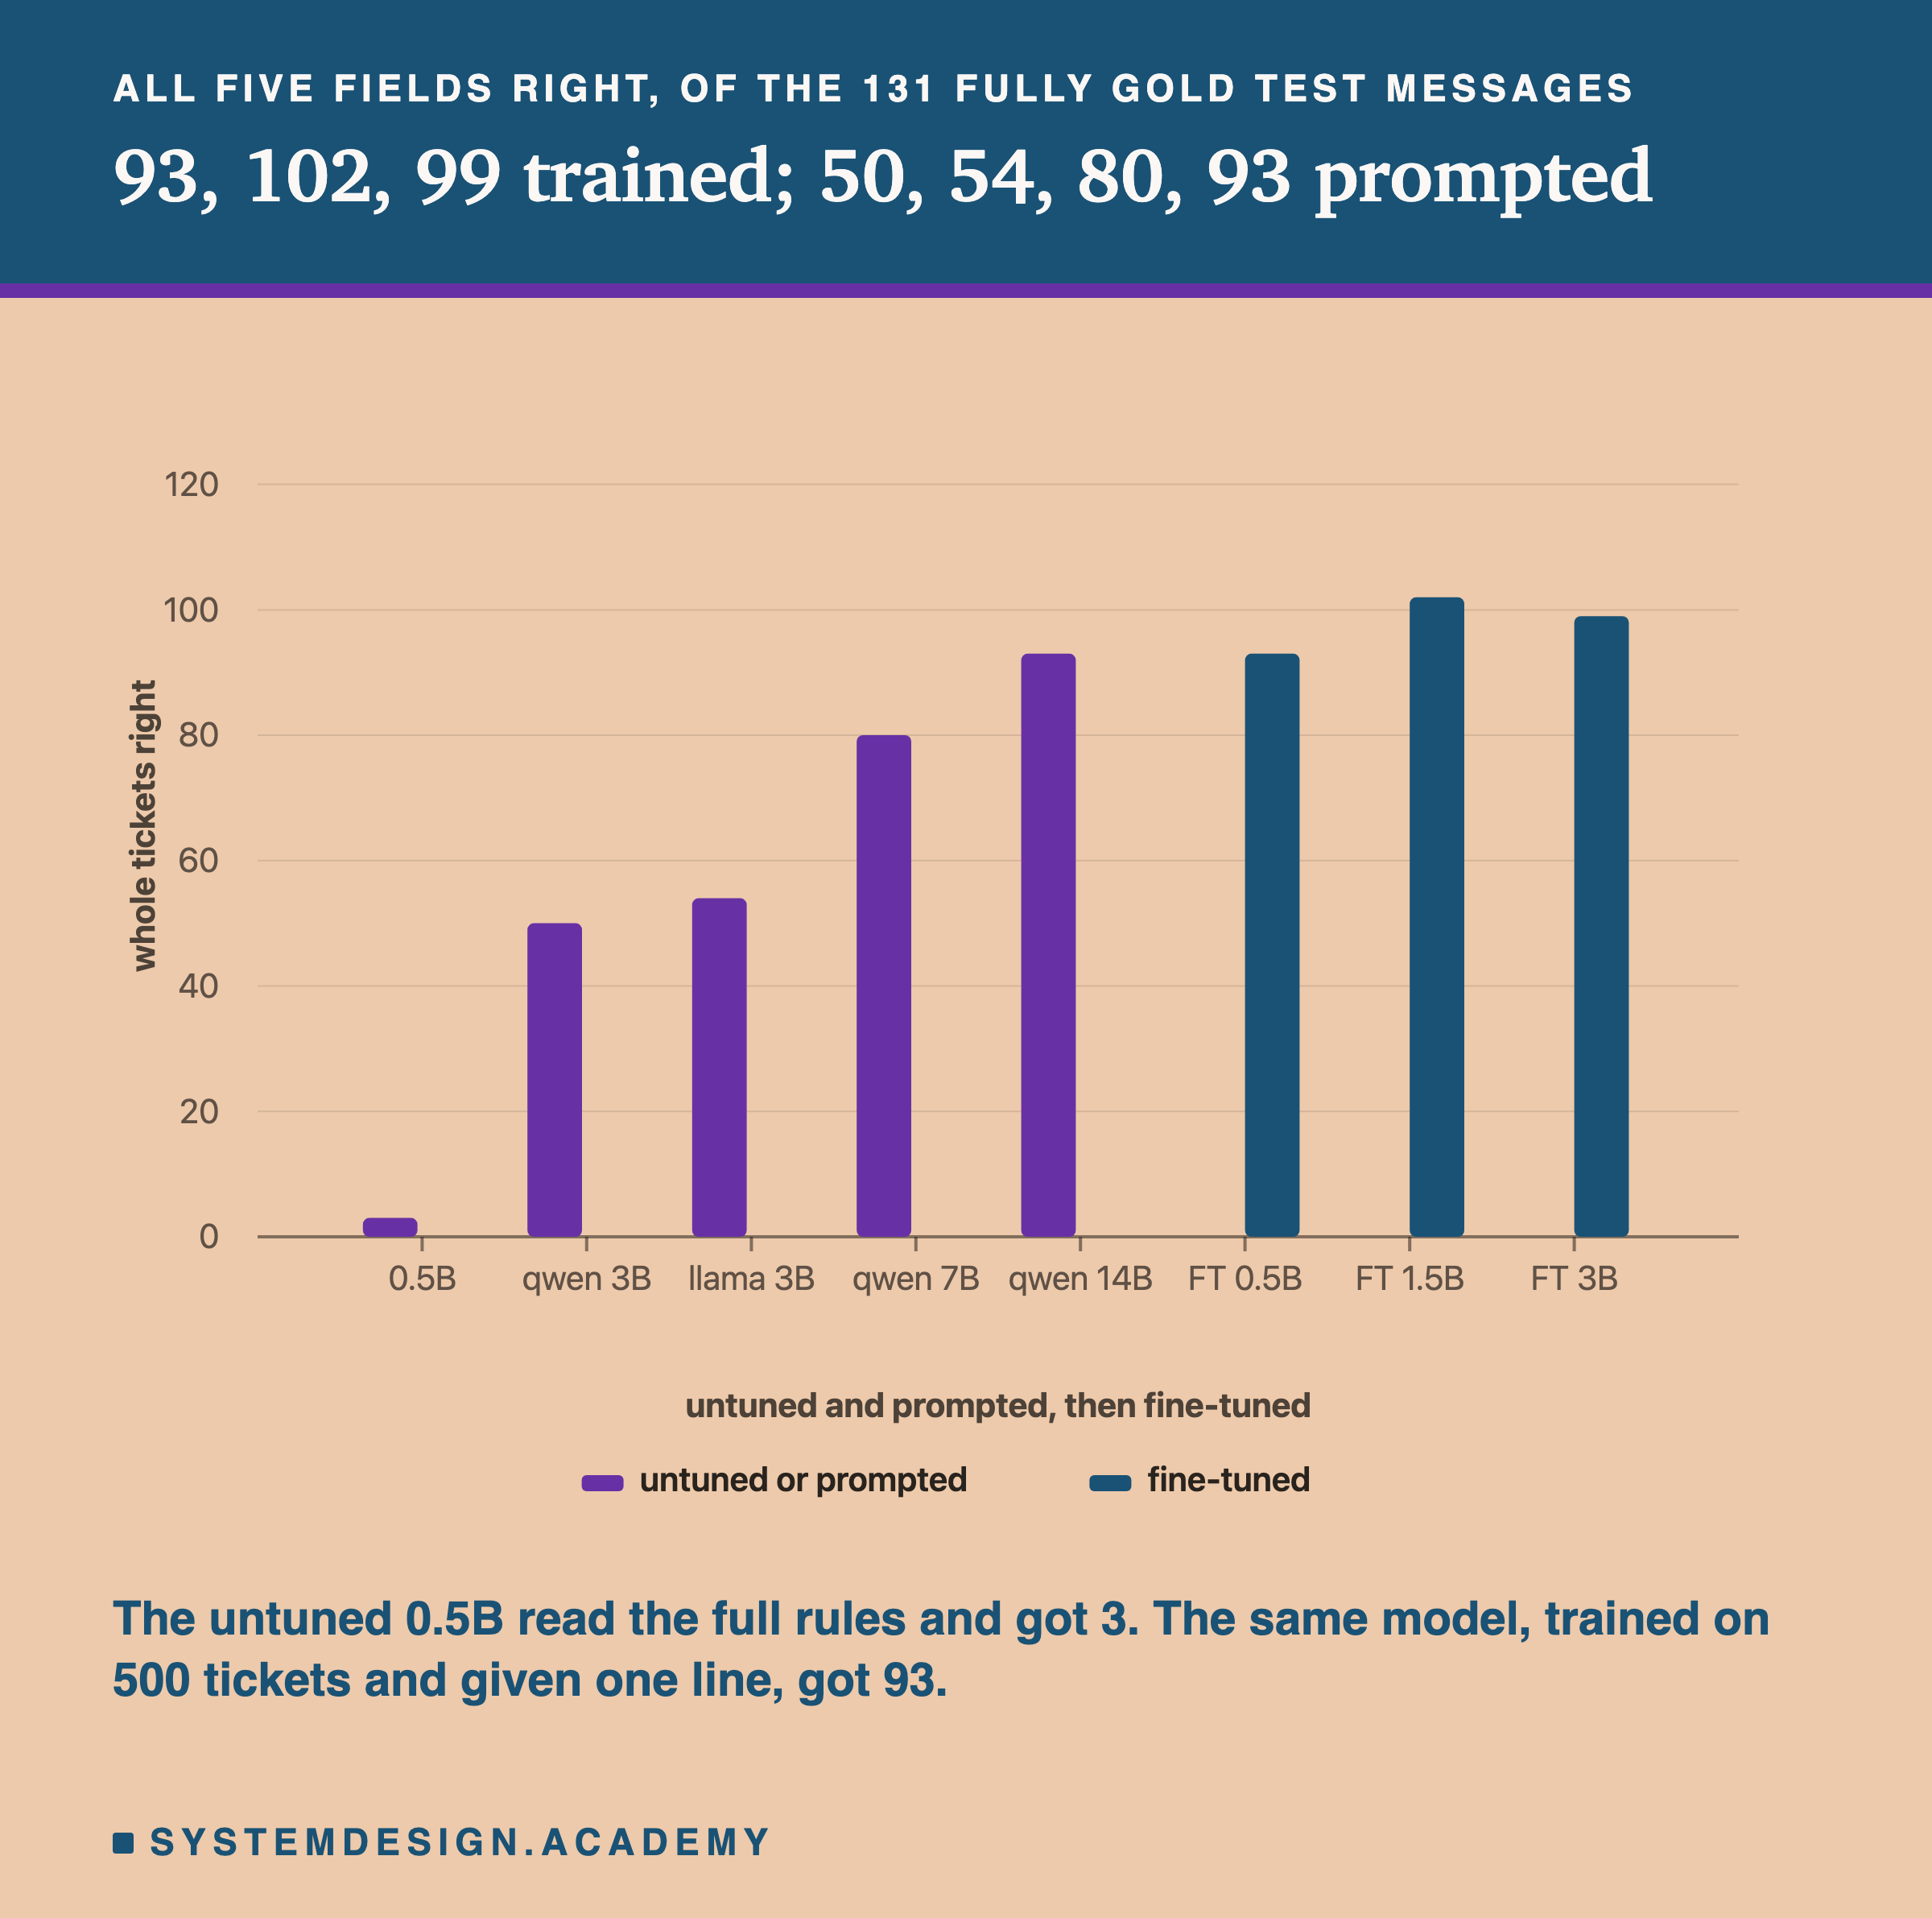
On the whole ticket, all five fields right on the same message, the fine-tuned 0.5B got 93 of 131, the 1.5B 102 and the 3B 99. The prompted models got 50 (qwen2.5:3b), 54 (llama3.2:3b), 80 (qwen2.5:7b) and 93 (qwen2.5:14b).
The first bar is the one to look at twice. It is the same 0.5B model before training, reading the full 401-word rules, and it got 3 whole tickets right. After training, with one line of instructions, it got 93. Be careful what that comparison says, though: two things changed at once, the weights and the prompt. It shows what the whole recipe did, not what either part did alone.
The smallest fine-tune tied the largest prompted model, which is many times its size. Before I believe that tie, or any other difference on this slide, I need to know which of them could be luck.
Which Differences Are More Than Luck
The sign test from the prompting chapter looks at the messages where two models disagree: "fixed" counts the messages the second model got right and the first got wrong, "broke" the reverse. If the two models were equally good, fixed and broke would be about even, and the p value says how likely a split at least this uneven would be if they were.
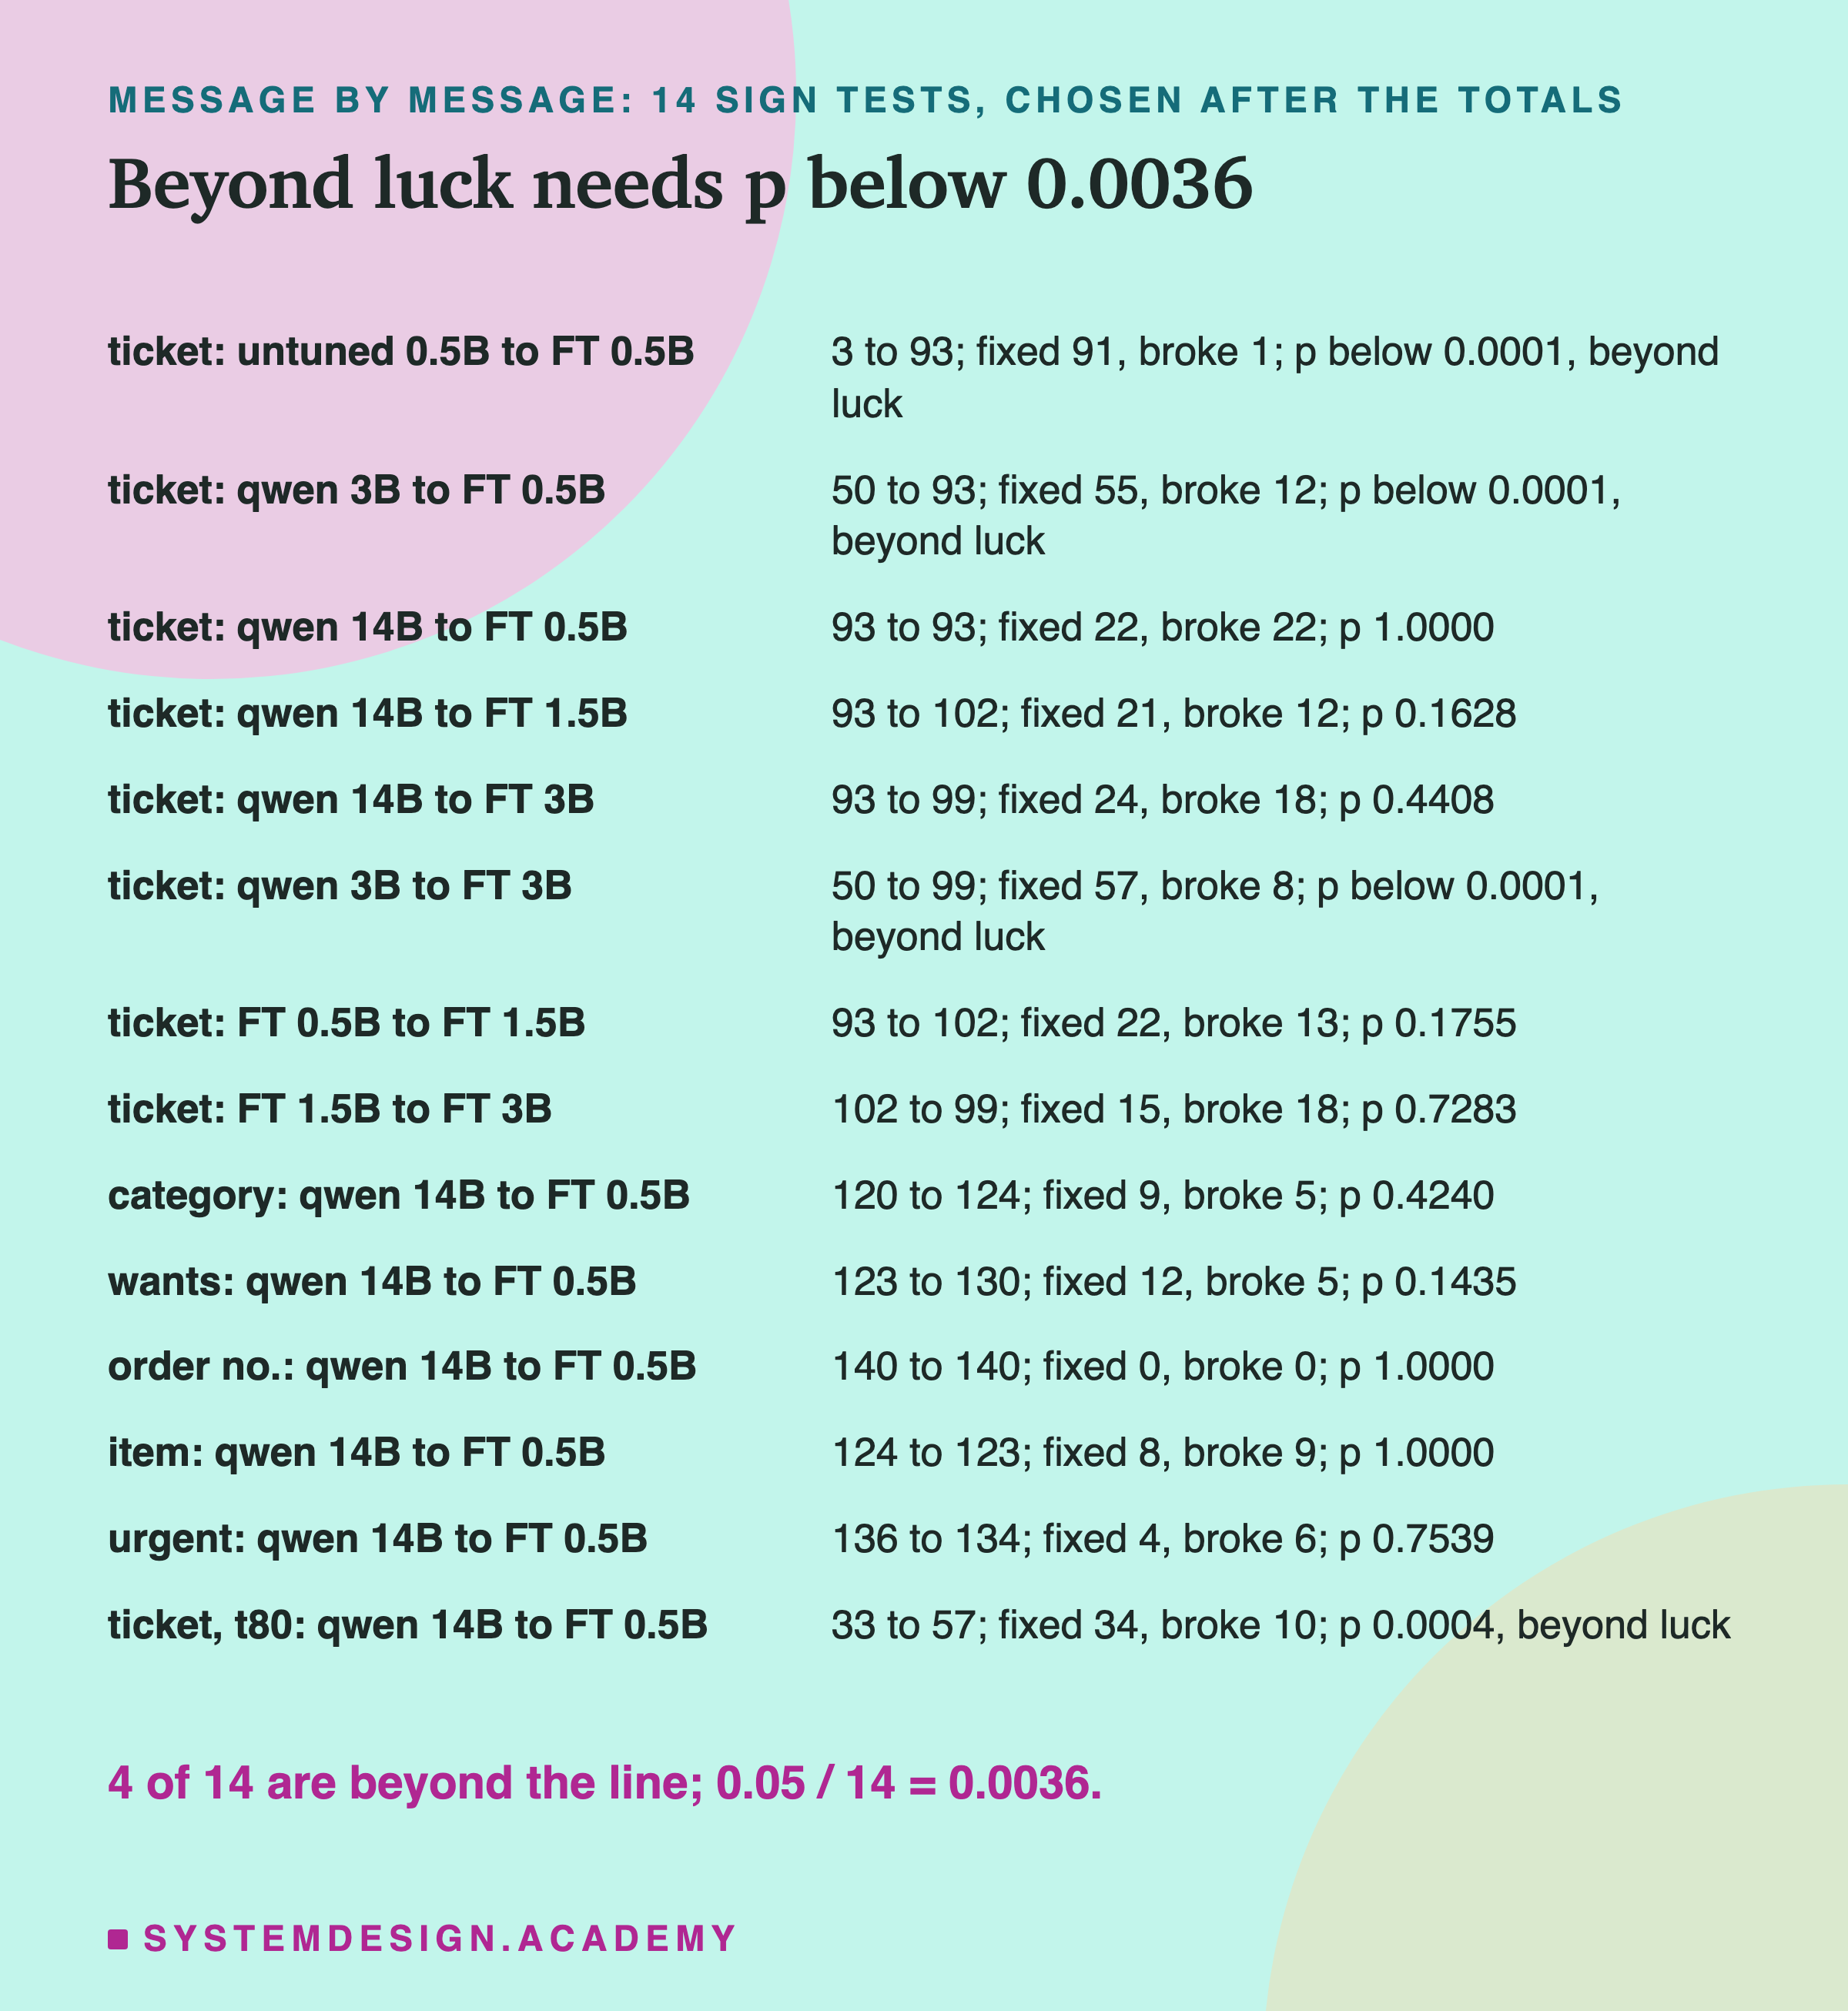
I chose these comparisons after the results were partly known, so treat them as a careful look at this data, not a plan made in advance. Before I wrote the list, the chapter's notes already recorded every whole-ticket total on both test sets, how many fields of each kind the fine-tuned 0.5B got wrong, and one message-by-message split: the fine-tuned 0.5B against the prompted 14B (23 against 23 then, on the 14B's earlier run with the older rules; 22 against 22 on the current run). The test on the chapter's 80 older messages was added after I had seen its totals, 29 and 28 against 19 and 14. The other pairs I had not counted message by message. There are 14: eight on the whole ticket, five on each field for the fine-tuned 0.5B against the prompted 14B, and one on the chapter's 80 older messages. With 14 tests, the Bonferroni correction says a result counts as more than luck only if p is below 0.05 divided by 14, which is 0.0036.
Four comparisons are beyond the line. Training the 0.5B took it from 3 to 93 (fixed 91, broke 1). The fine-tuned 0.5B beat the prompted qwen2.5:3b (fixed 55, broke 12), and so did the fine-tuned 3B, which is the same Qwen2.5 3B Instruct model in a different 4-bit version, trained instead of prompted (fixed 57, broke 8). And on the chapter's 80 older messages, the fine-tuned 0.5B beat the prompted 14B, 57 to 33 (fixed 34, broke 10, p 0.0004); a later slide looks at why.
Everything else cannot be told apart from luck on these messages. That includes all three fine-tunes against the prompted 14B on the 140: 93 against 93, 102 against 93 (p 0.1628), 99 against 93 (p 0.4408). It includes every single field of the 0.5B against the 14B. And it includes the sizes against each other. The 1.5B's 102 against the 0.5B's 93 gives p 0.1755, and the 3B's 99 against the 1.5B's 102 gives p 0.7283.
That last one needs a clear warning. The 3B scoring below the 1.5B does not tell you that a bigger model learned less. Each size was trained once, with one random seed (the number that decides the order the examples are shuffled into). A second run of the same model with a different seed may land higher or lower; how far, this lesson has not measured. Until that run-to-run spread is known, a difference of 3 tickets between two single runs cannot be read as a size effect, and the sign test agrees. The next lesson trains the same model several times to measure it.
93 and 93, on Different Messages
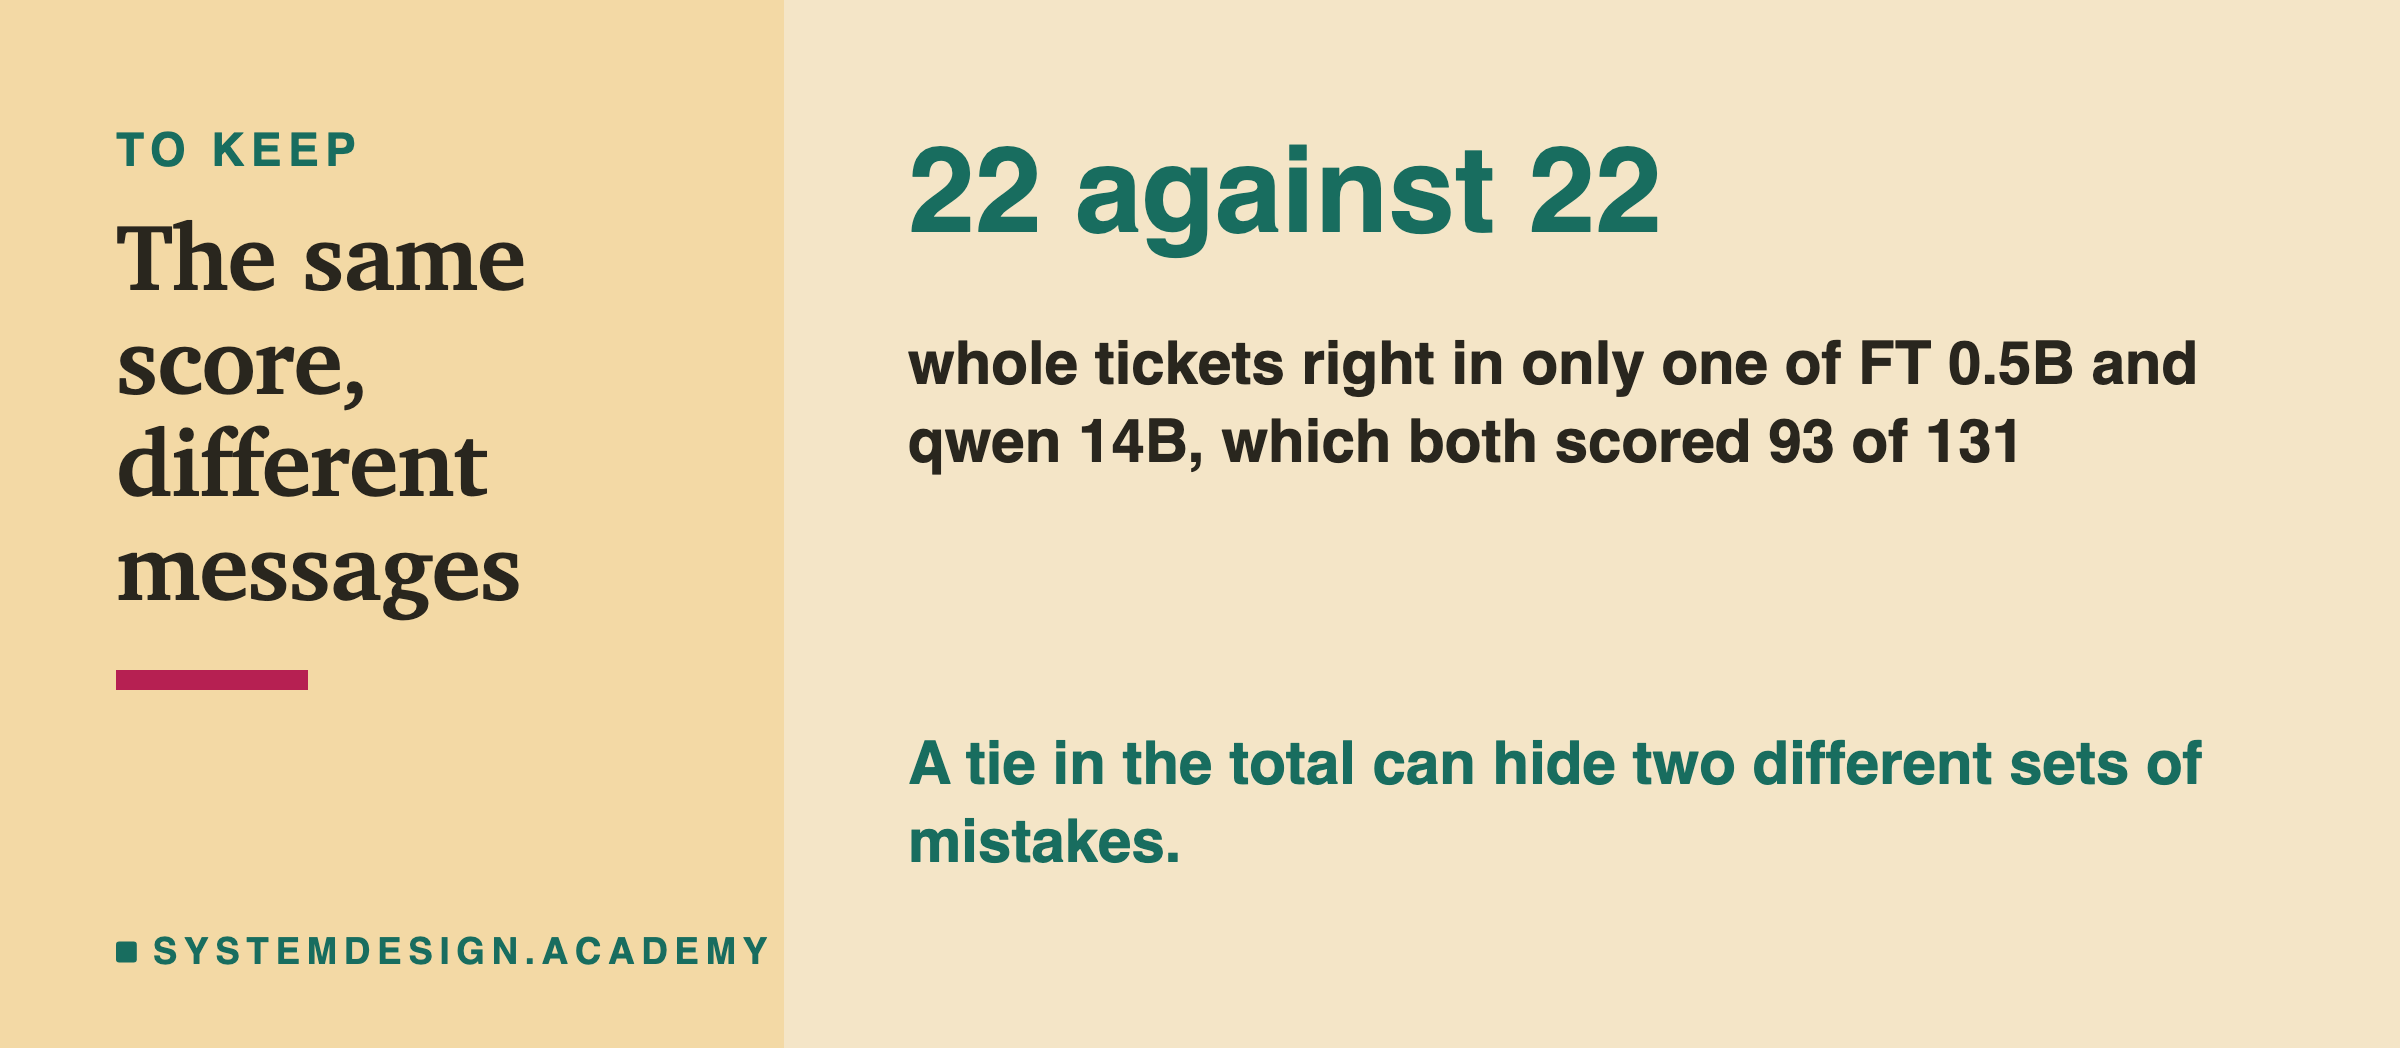
The tie between the fine-tuned 0.5B and the prompted 14B is the most useful result in this lesson, because it is not really a tie.
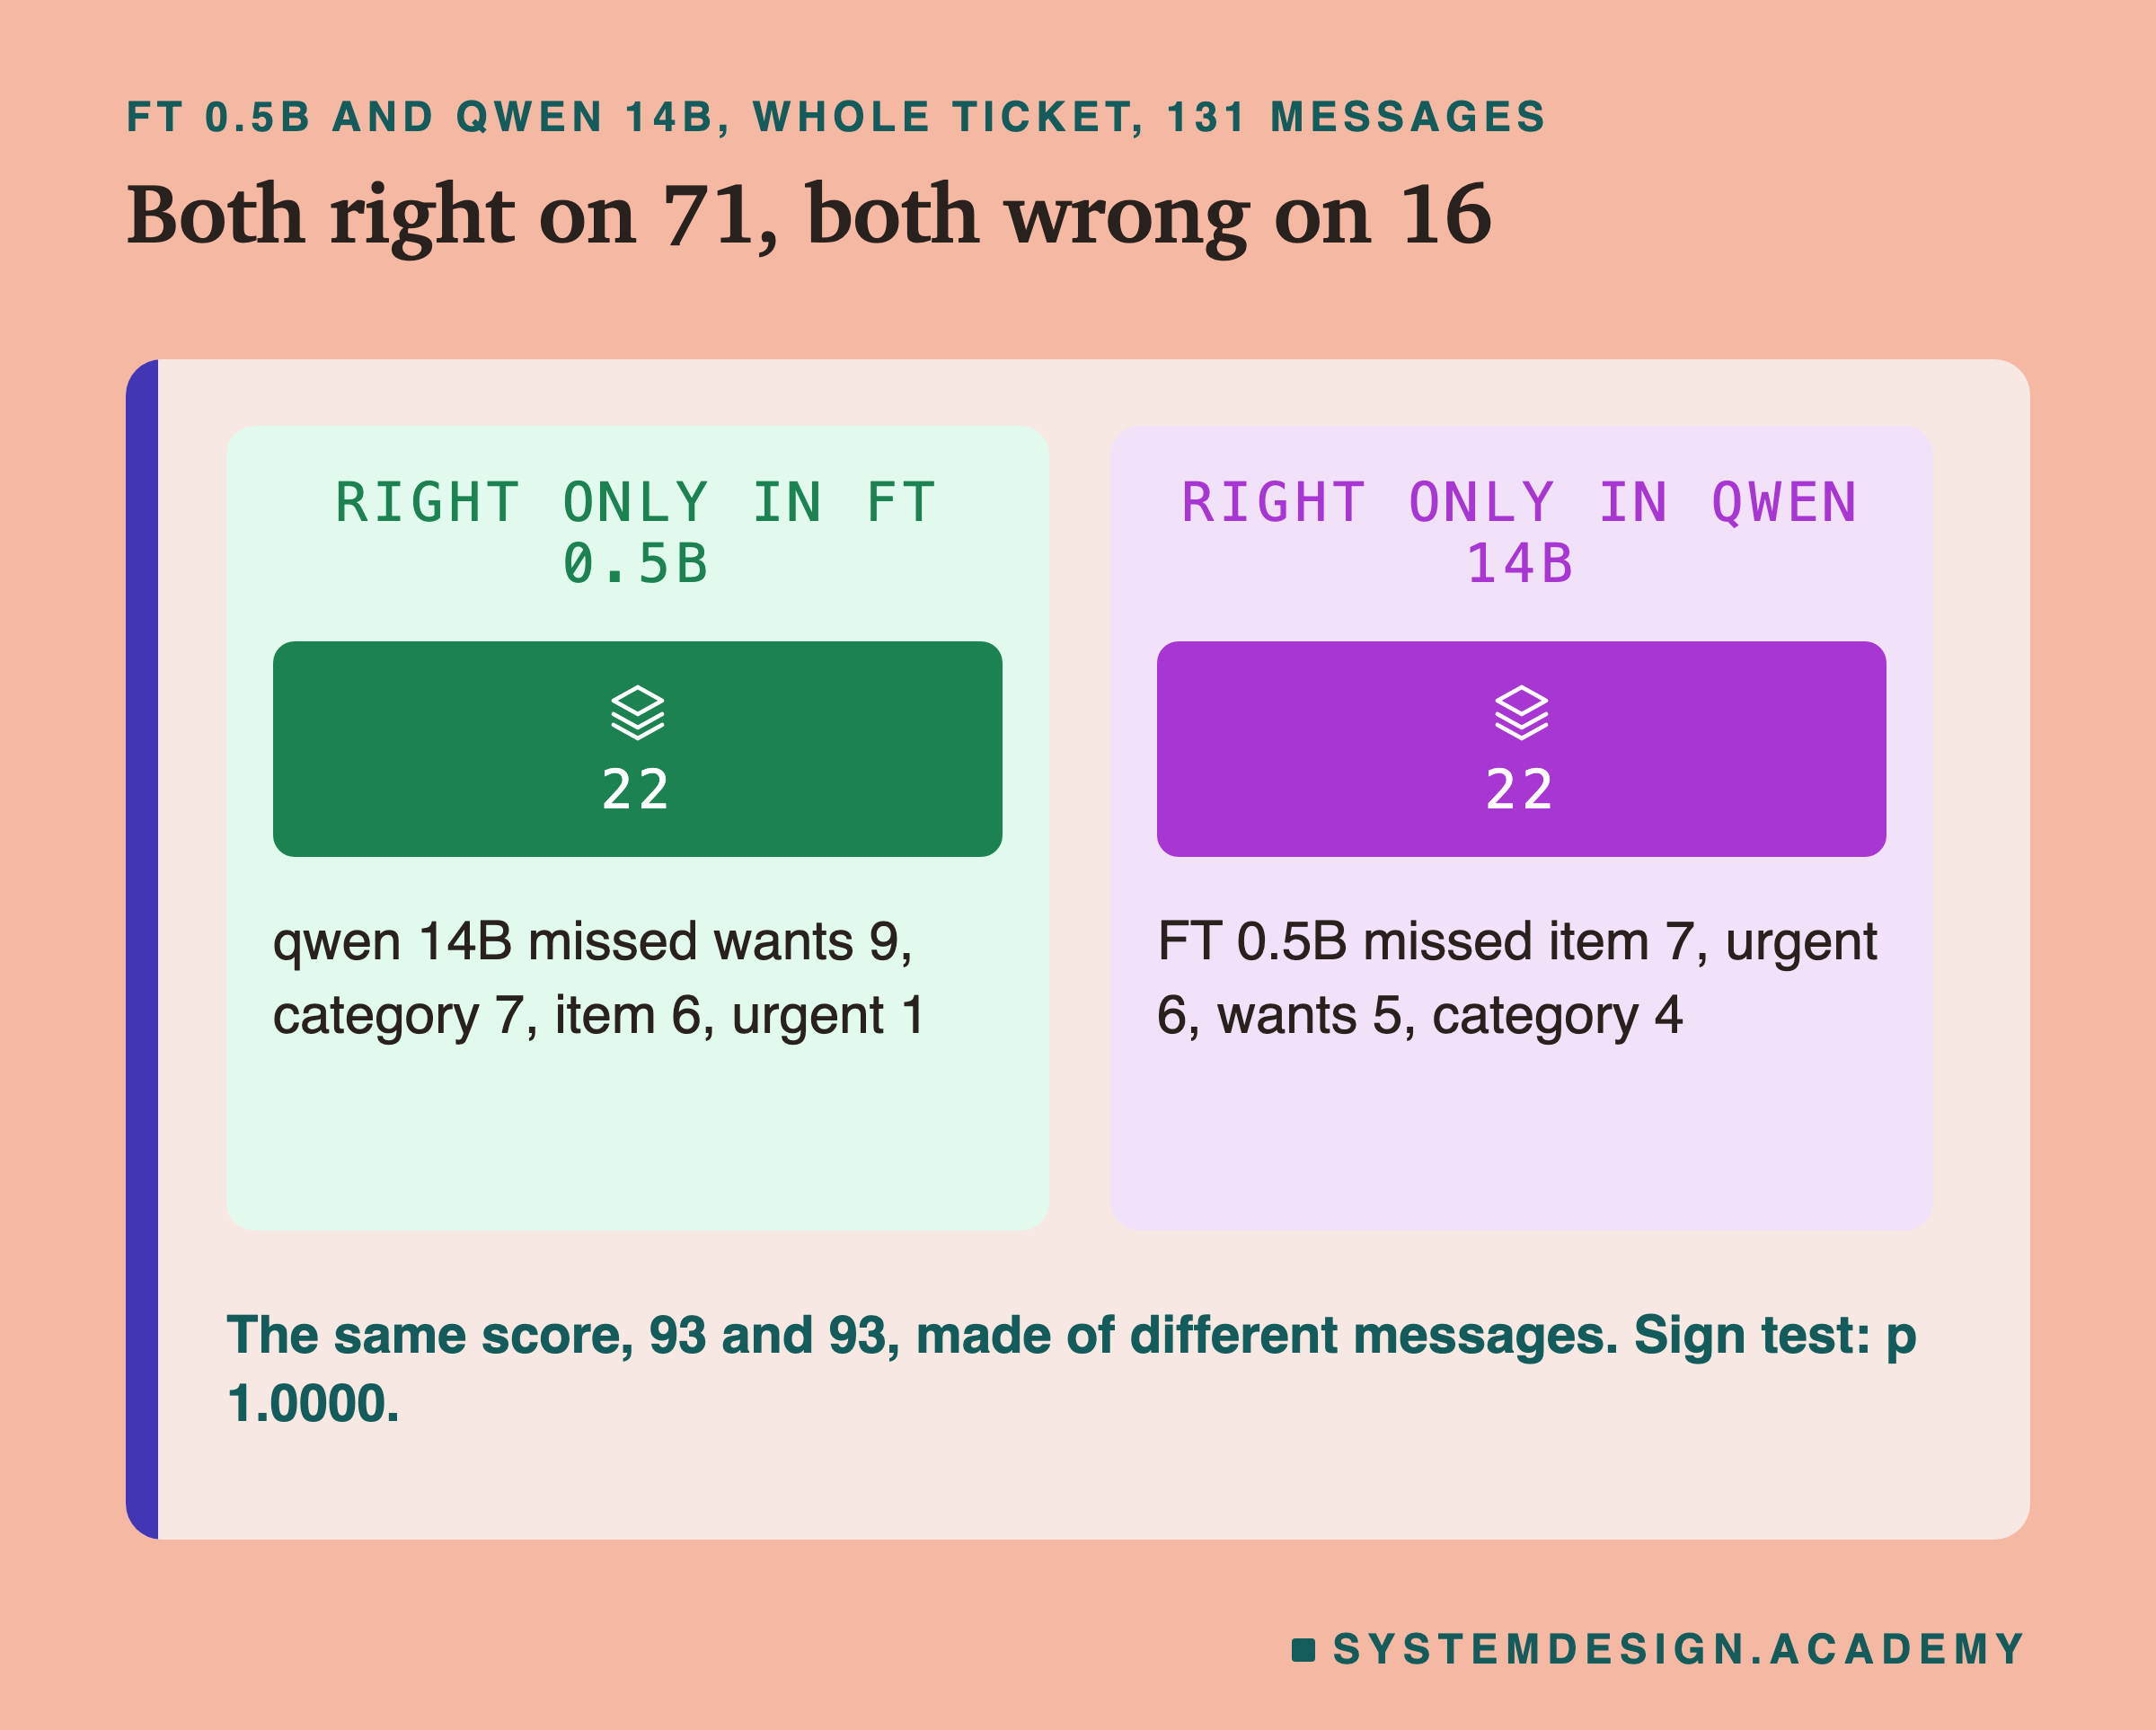
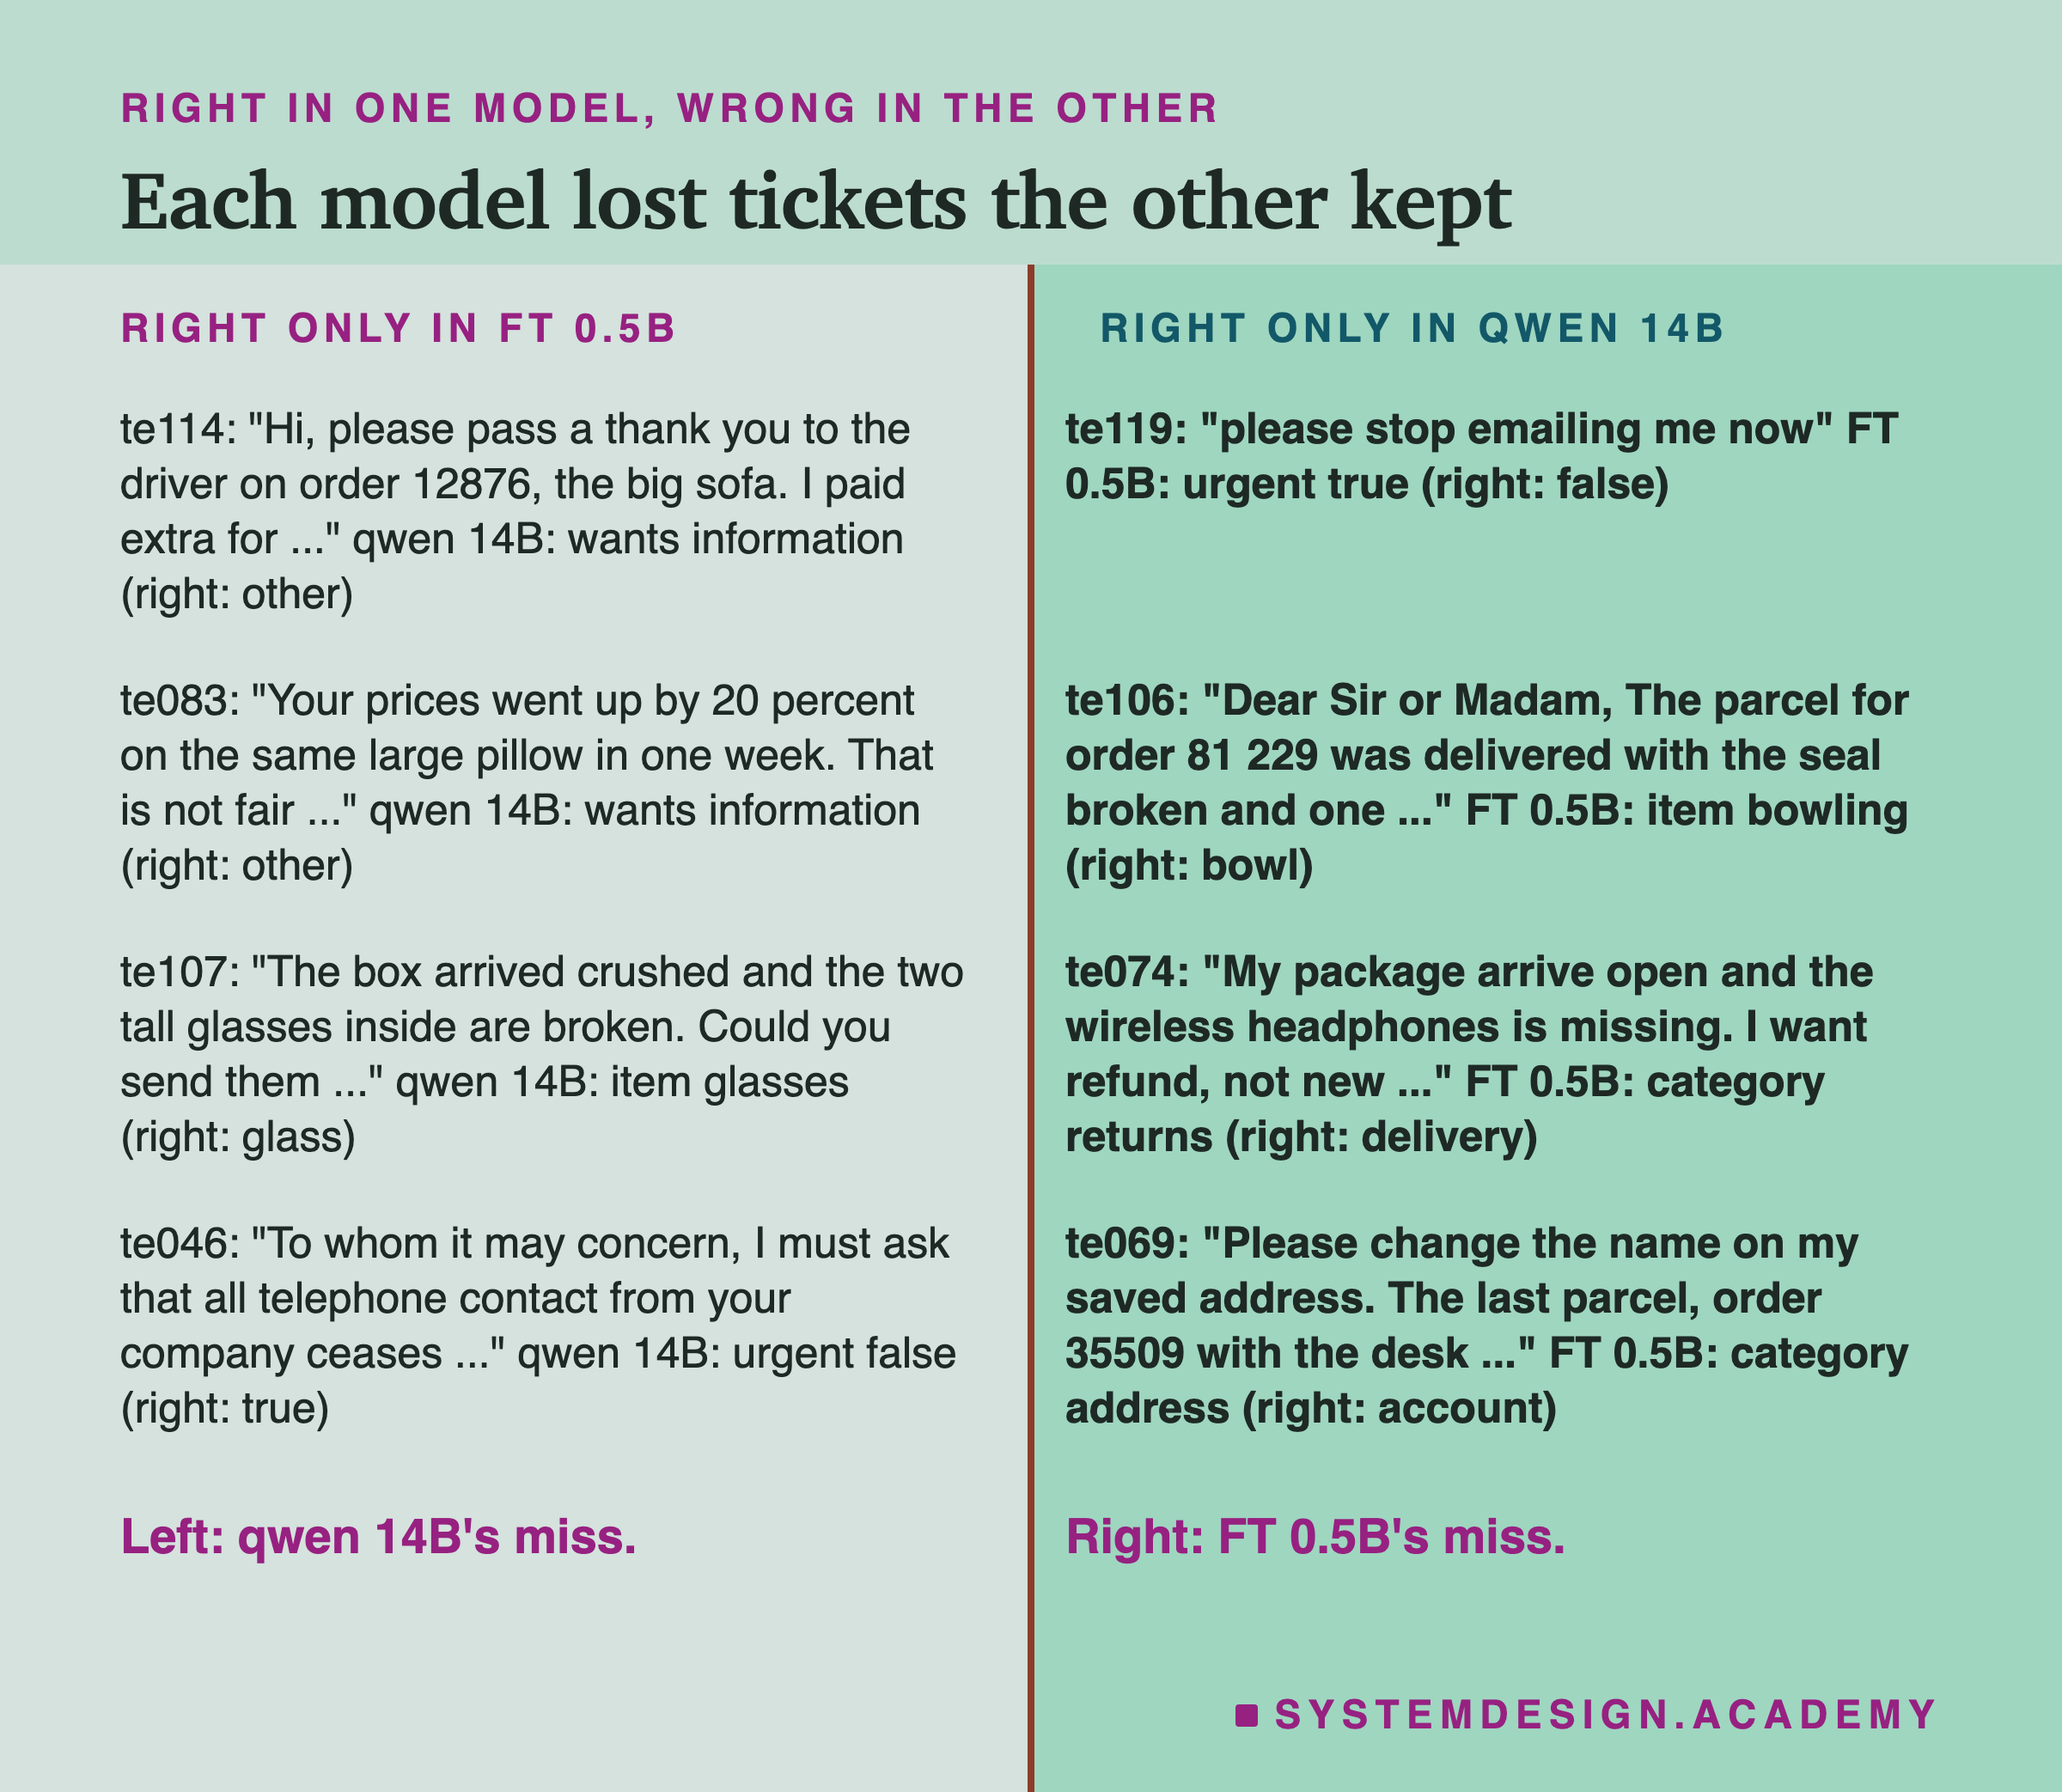
Both models got 71 of the same tickets right and both got 16 wrong. On the other 44 they split exactly in half: 22 tickets right only in the fine-tune and 22 right only in the prompted model. So the two models score the same while failing on different messages. A total of 93 says nothing about which 93.
The two groups of 22 are not alike, either. Where only the fine-tune was right, the 14B's mistakes were mostly wants (9 fields) and category (7). Where only the 14B was right, the fine-tune's mistakes were mostly item (7) and urgent (6). Reading them shows the pattern better than counting.
The 14B's misses on the left are the rules lesson 3 found hardest for prompted models: a thank-you note read as a question, a plural kept, the word "immediately" not treated as urgent. The fine-tune's misses on the right are of a different kind. "please stop emailing me now" was marked urgent, though "now" on its own is not one of the listed words. A bowl became "bowling", a word that is not in the message at all. A missing item with a refund went to returns. And one ticket got the category "address", which is not one of the four. These look less like a rule not followed and more like a small model that learned patterns from examples and sometimes applied them in the wrong place.
For a real team, that difference matters more than the total. If you can live with the 14B's kind of mistake but not the 0.5B's, or the other way round, the tie is not a tie for you.
What the Fine-Tunes Got Wrong
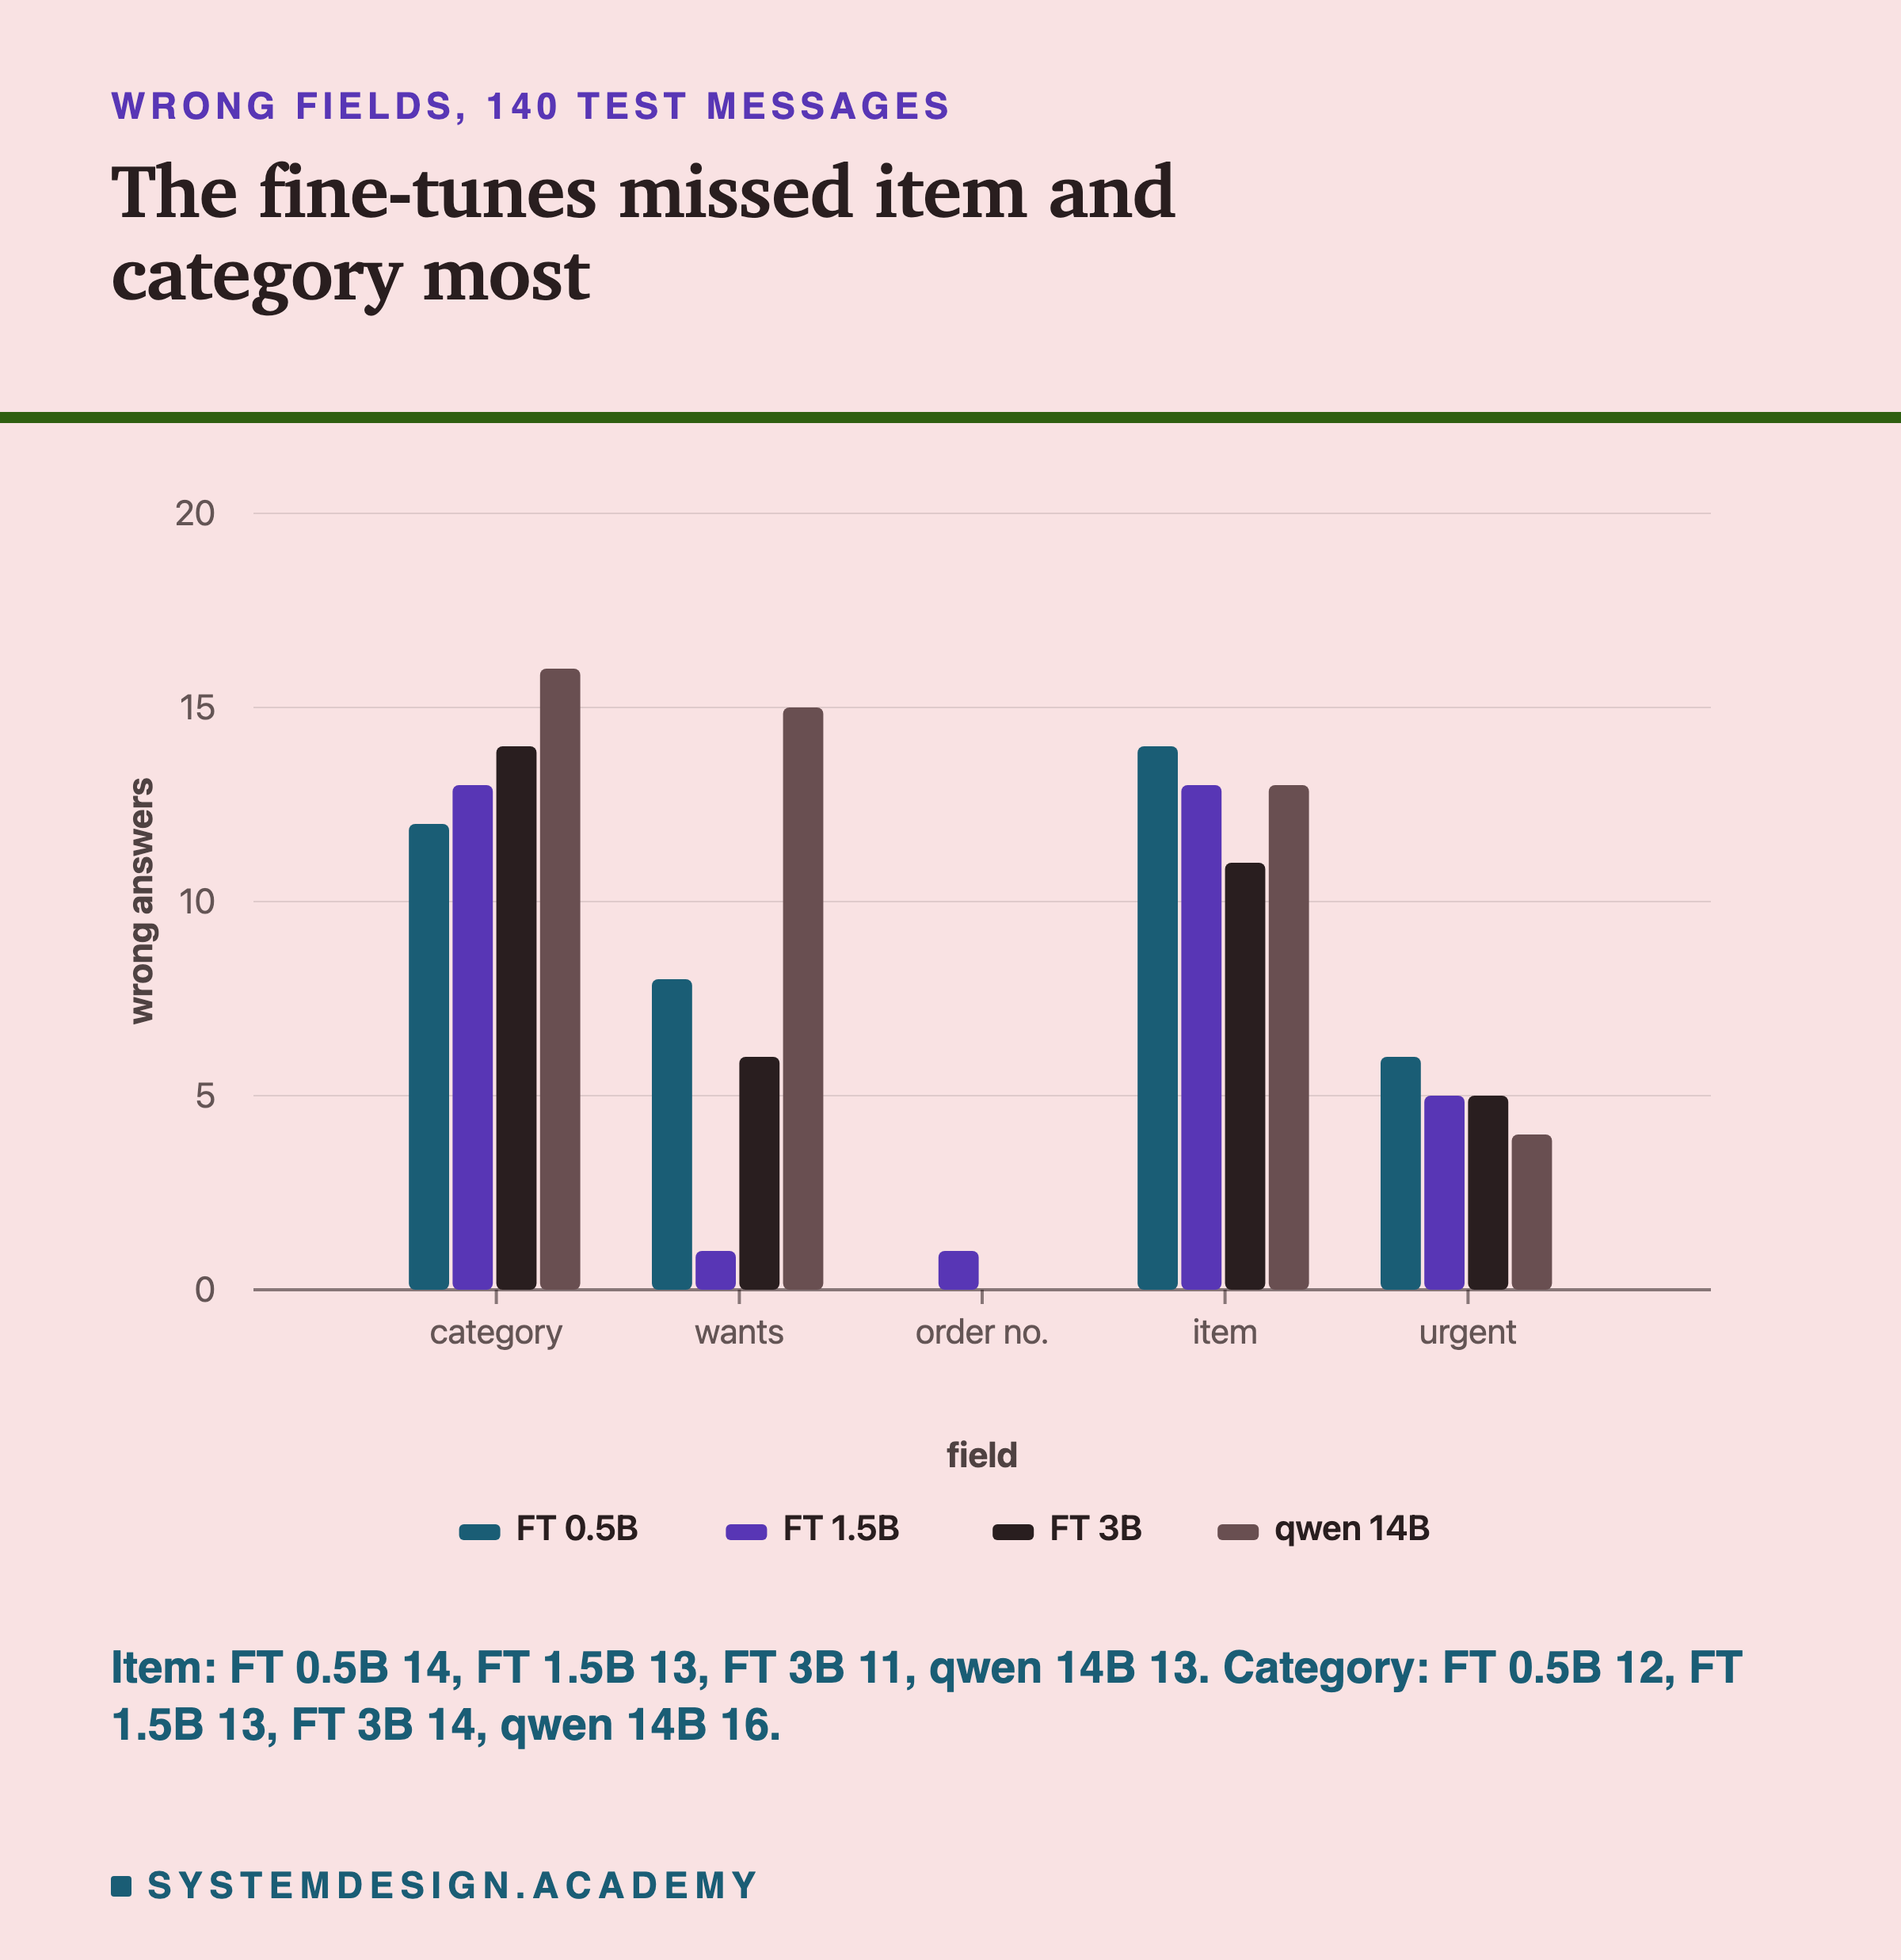
I read every wrong field of the three fine-tunes, 109 in all: 40 for the 0.5B, 33 for the 1.5B and 36 for the 3B. The lab sorts them by code, not by my reading: category and wants by the right answer and the wrong one, item and urgent by the same kinds as lesson 3, with two kinds added that the fine-tunes needed.
Item was the fine-tunes' biggest group, and here I sort it the same way lesson 3 now does, because one kind of "mistake" is really a gap in the rules. The rule bans colour, size, brand, quantity and adjectives, but says nothing about a noun used in front of another noun. When a fine-tune wrote "baby cot", "printer paper", "birthday banner" or "salad bowl" where the gold says cot, paper, banner or bowl, it kept part of a compound name. The gold itself is not consistent there: it keeps "baby monitor", "chopping board" and "bar stool" whole. So I count those as a rule gap, using the same list of name words as lesson 3: 5 for the 0.5B, 3 for the 1.5B and 2 for the 3B (4 for the 14B). Keeping a real adjective or material word, such as "blue sweater", "big mirror", "oak bookshelf" or "leather jacket", is a model error: 2 for the 0.5B, 1 for the 1.5B and 5 for the 3B (1 for the 14B). One of the 3B's five, "office chair", is arguably a compound name too; "office" is not on lesson 3's list, so it counts here as an adjective. Two kinds were new. Twice a fine-tune wrote a word that was a broken piece of the right one: "bowling" and "bow" for bowl. And twice one named something that is not a product, such as "printer" in a complaint about the returns process needing a printer.
Category mistakes fell mostly on the line between returns and the other two teams: a right answer of returns written as billing (4, 5 and 3 times), mostly refunds for an item sent back and cancelled exchanges, and a lost or damaged parcel with money back written as returns. Urgent was mostly false alarms: the 0.5B raised 5, the 1.5B 4 and the 3B 3, against the 14B's 3. Wants was the fine-tunes' best field: the 1.5B got it wrong once in 138.
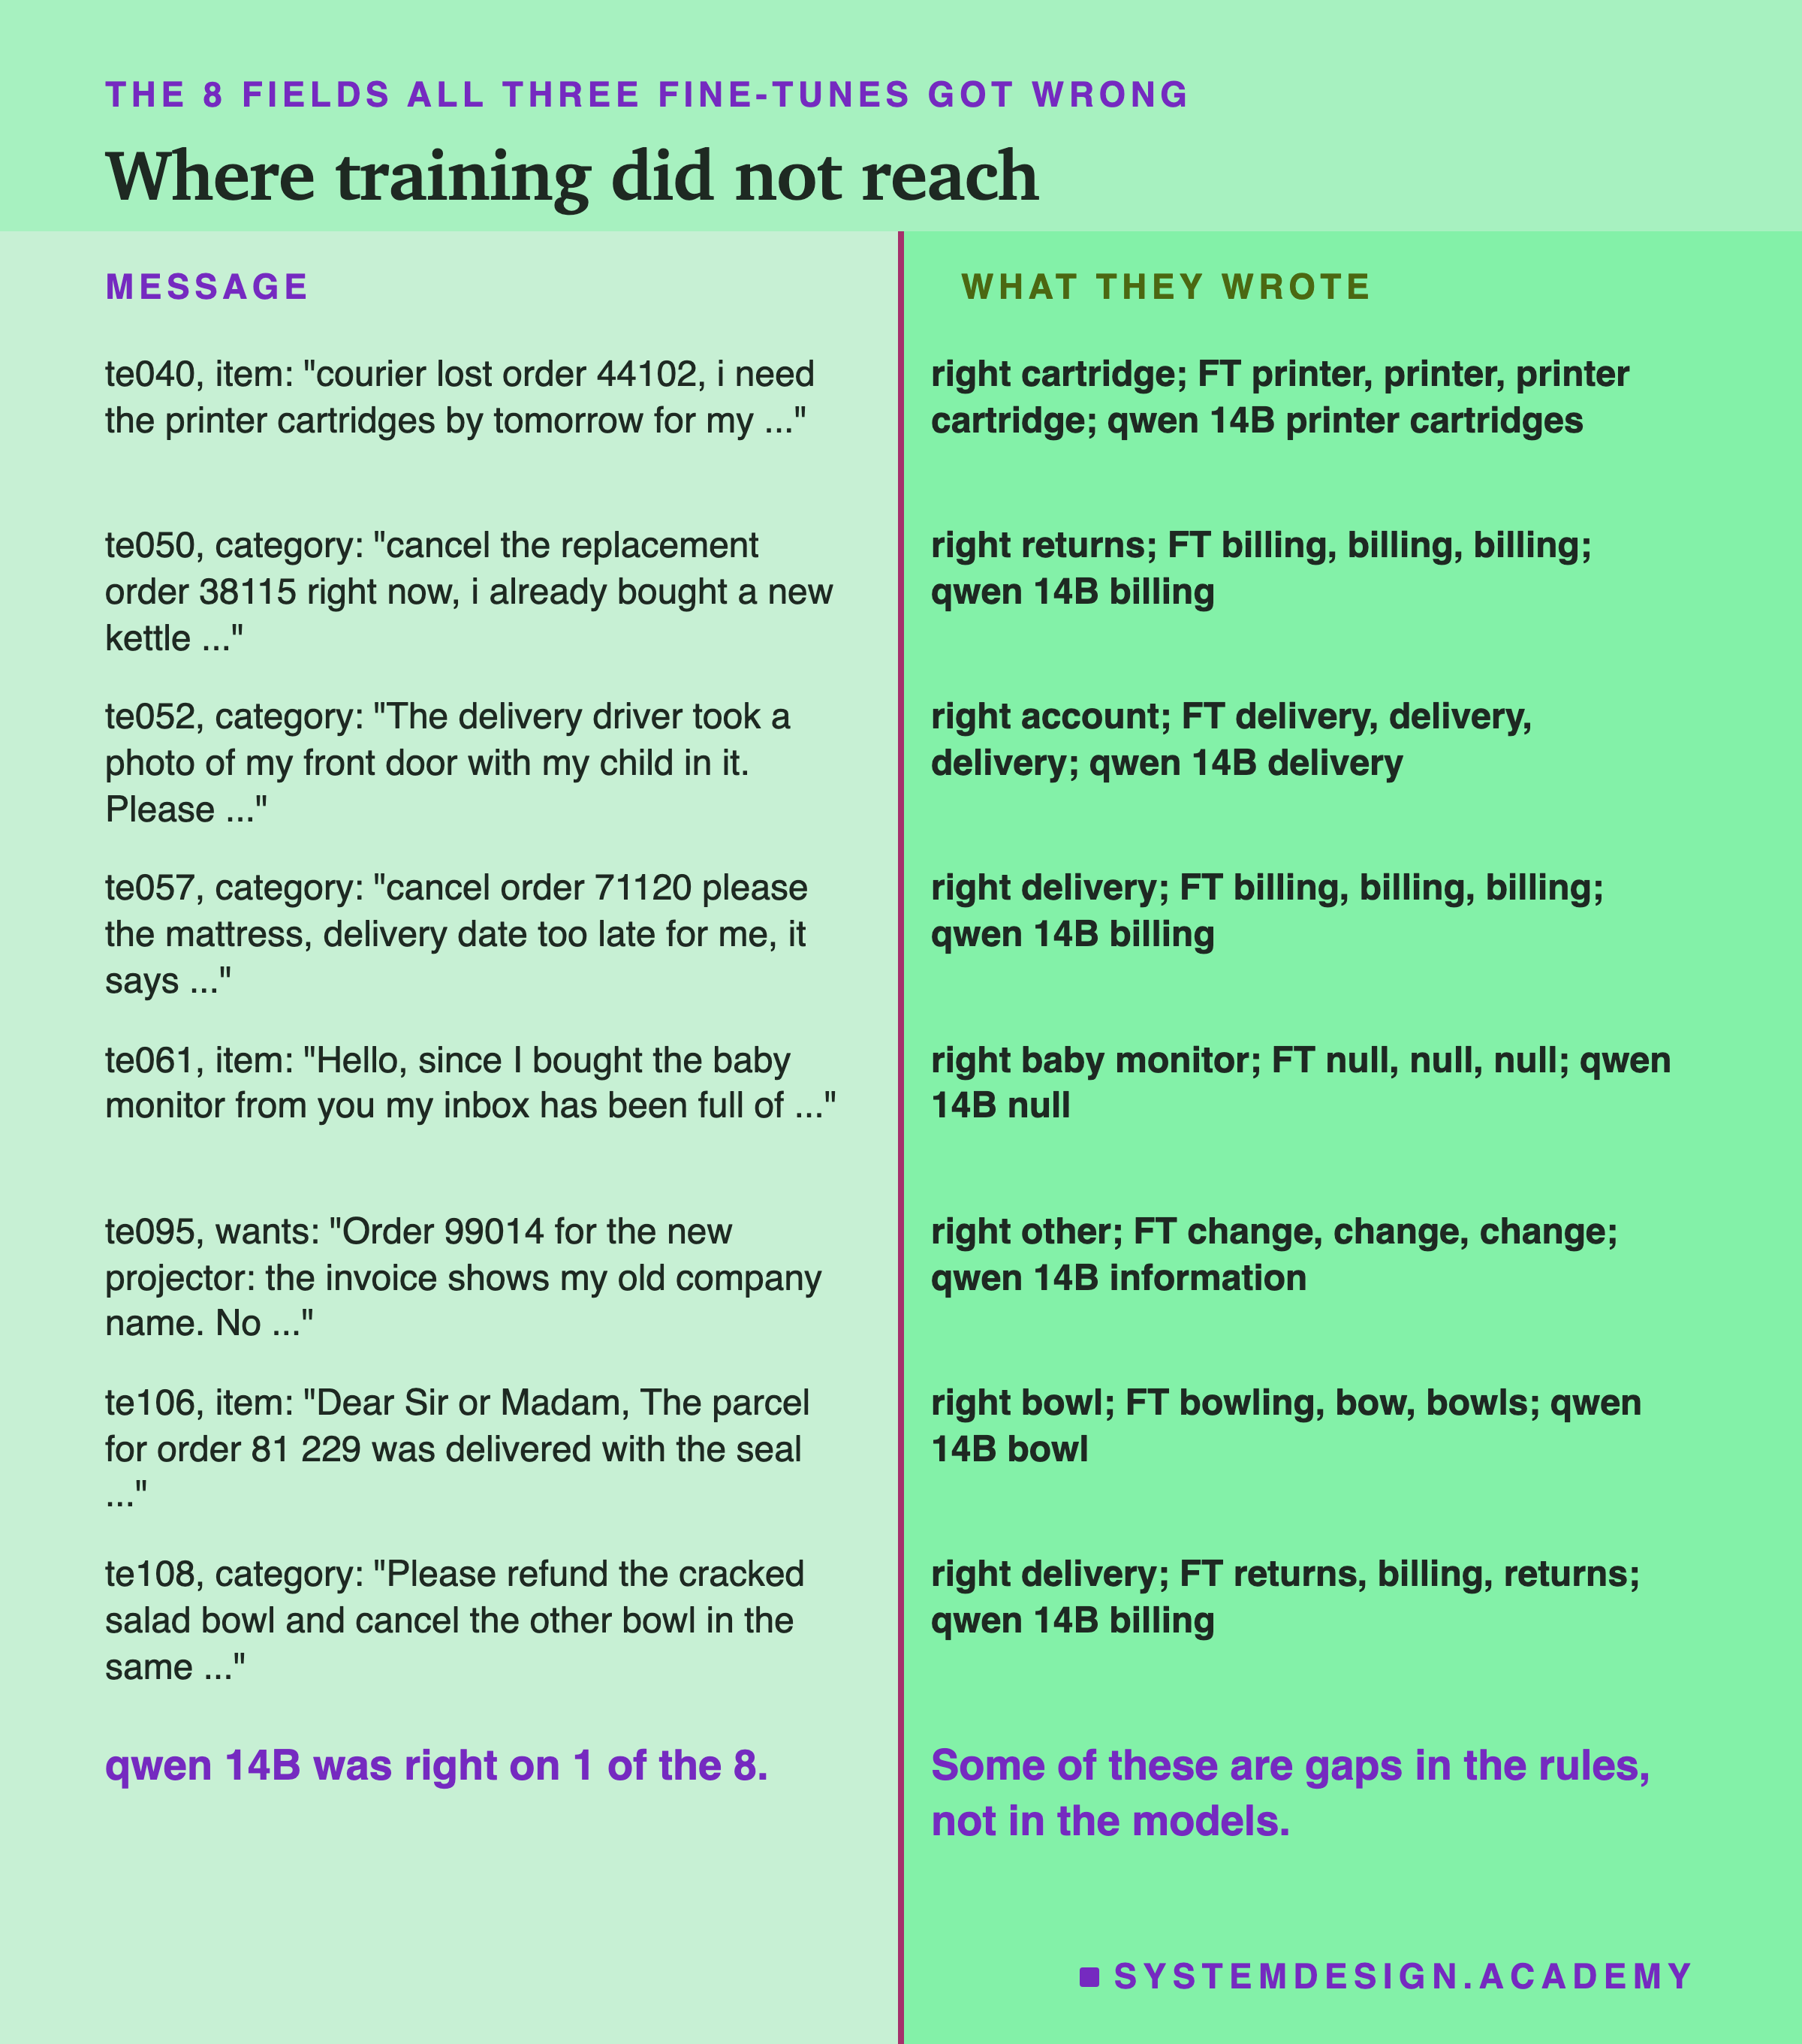
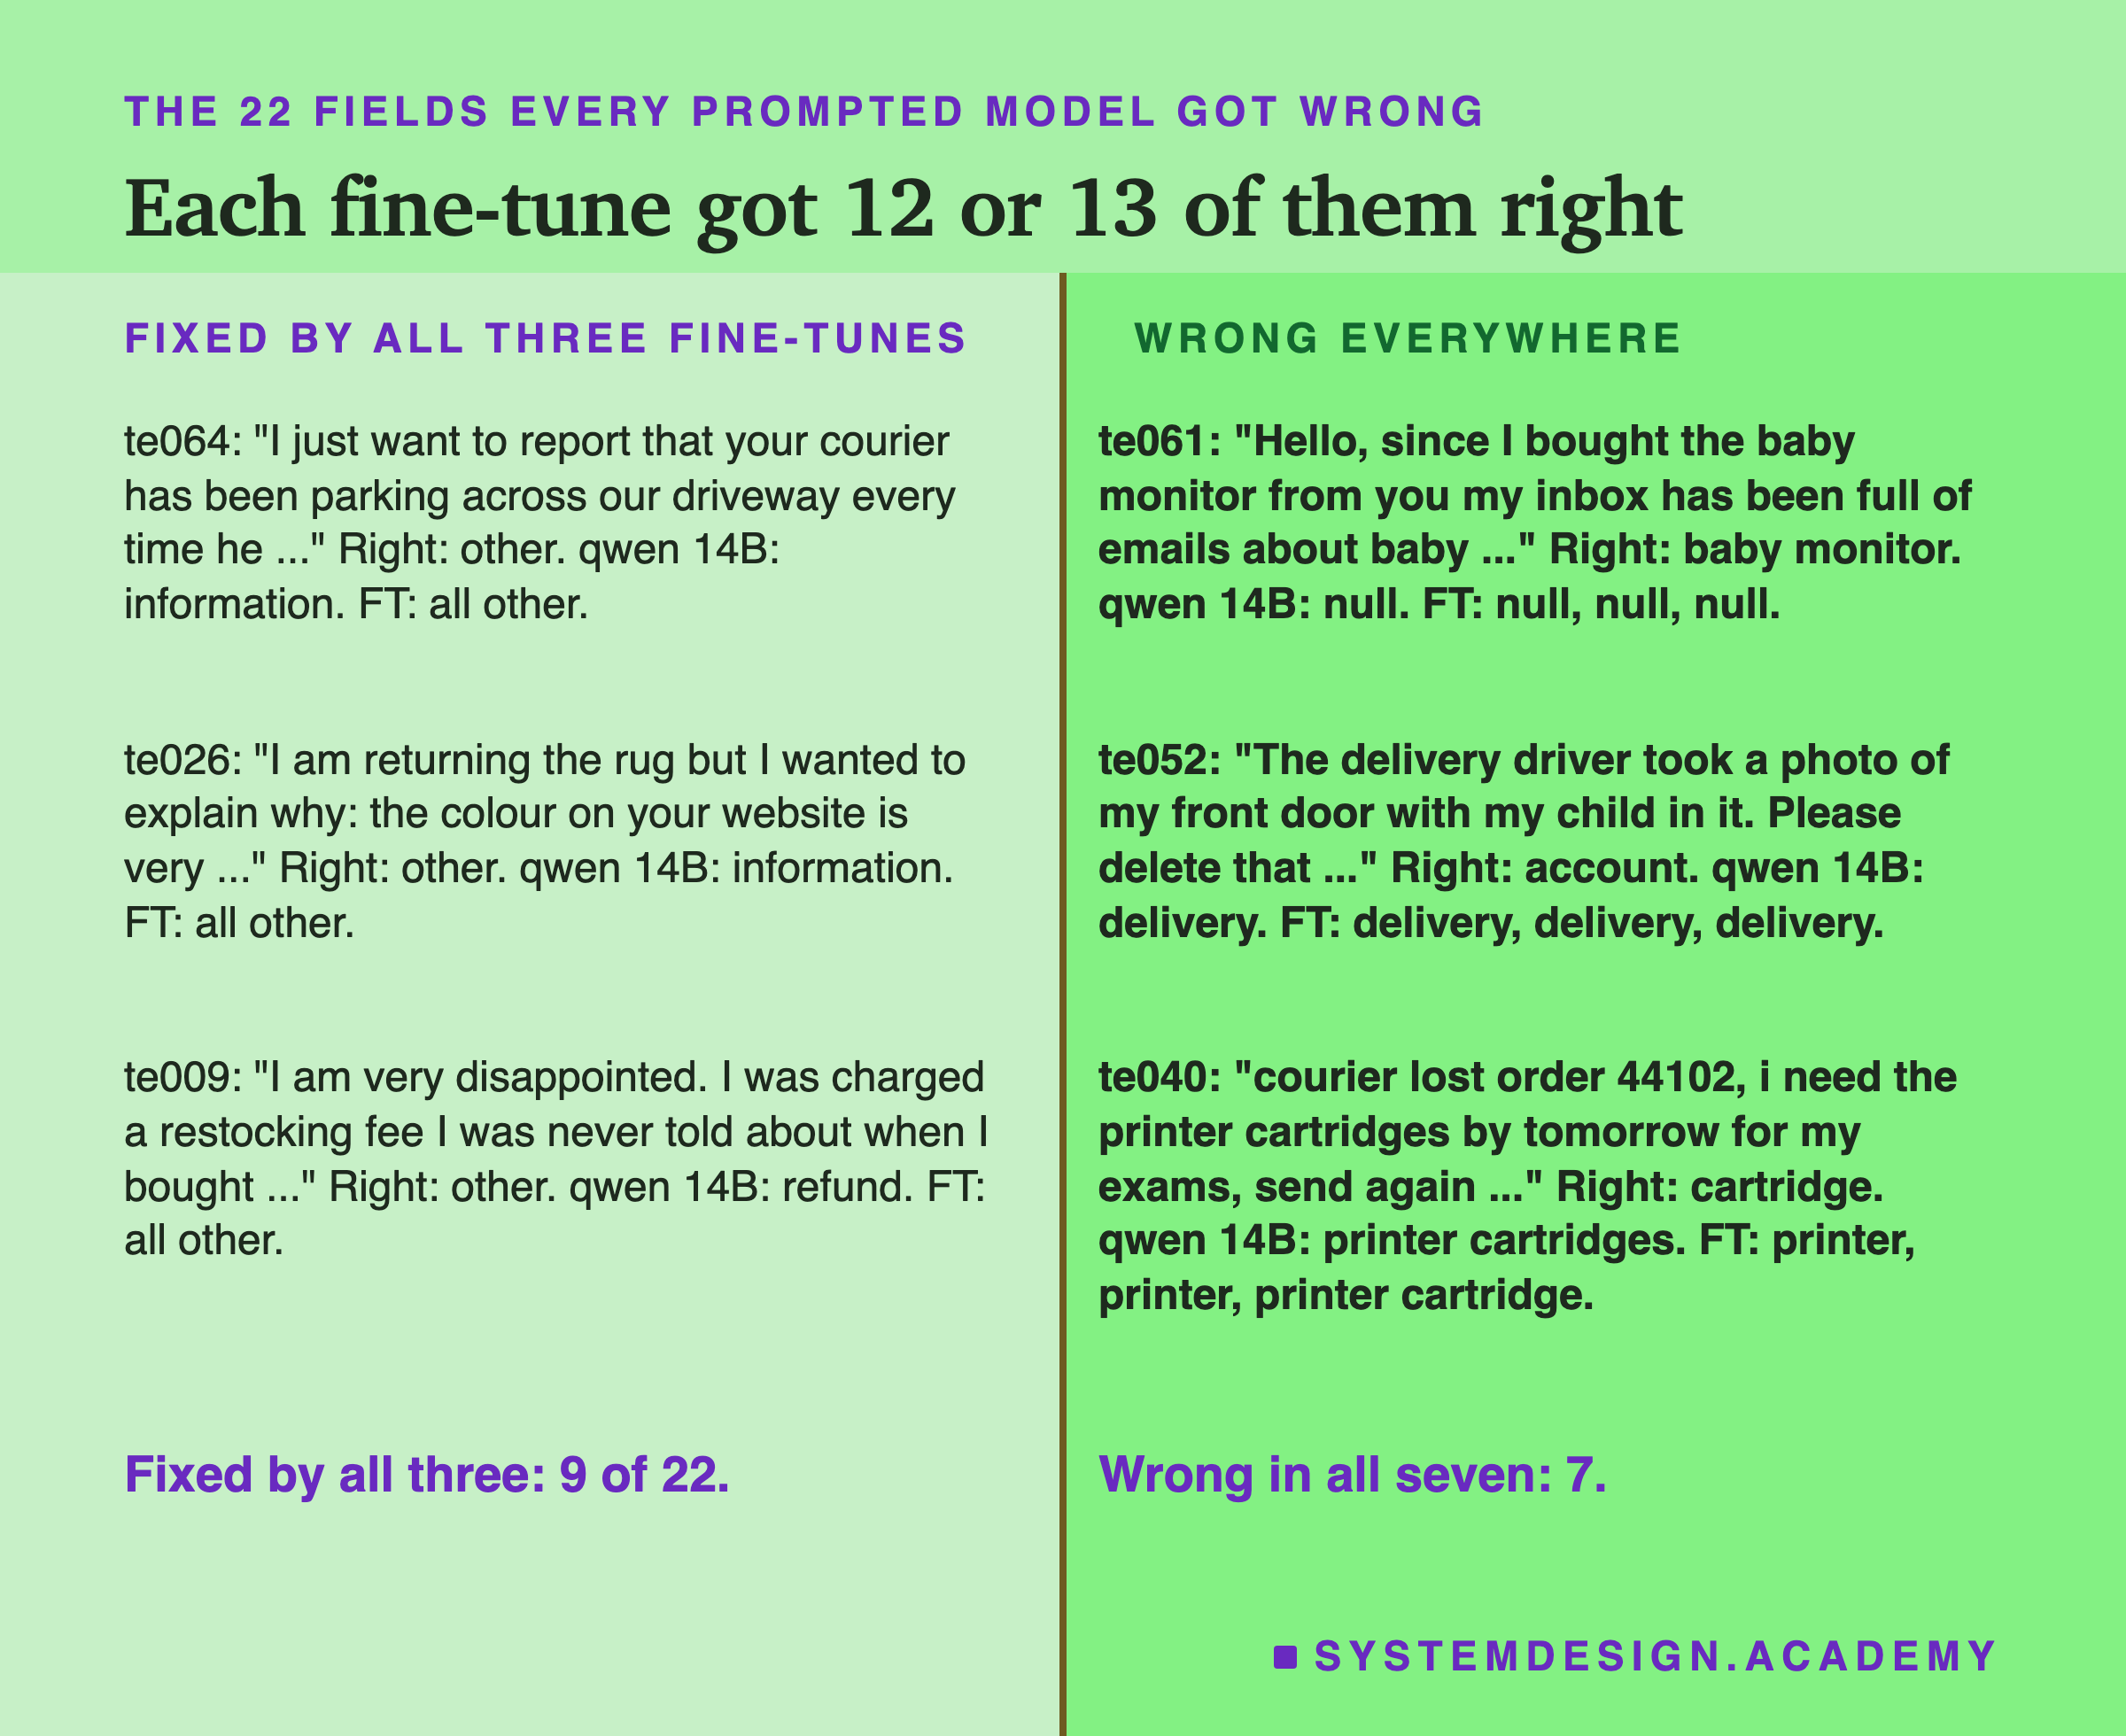
Only 8 fields were wrong in all three fine-tunes, and the prompted 14B got just one of those 8 right, the bowl. Several of the others sit where lesson 2 and lesson 3 found the rules themselves unclear. te057, a plain request to cancel an order, is the known gap: lesson 2 showed the rules say nothing about which team a plain cancellation goes to. The same is true of te058, te059 and te125, and these four cancel-only messages feed the category and whole-ticket scores in both directions: the fine-tunes got 3, 2 and 2 of their categories right, the prompted models 2, 3, 3 and 3. te050 is different: it cancels an exchange ("the replacement order"), which the rules do put in returns, so billing there is a real mistake by all seven models. "The printer cartridges" is the compound-name gap from the item paragraph. "The baby monitor" is another kind of question: every one of the seven models answered null, so the question there is whether a product mentioned in passing, in a message about marketing emails, counts as the ticket's item at all. A model cannot learn a rule that its own examples do not show consistently.
The Rule That Examples Taught
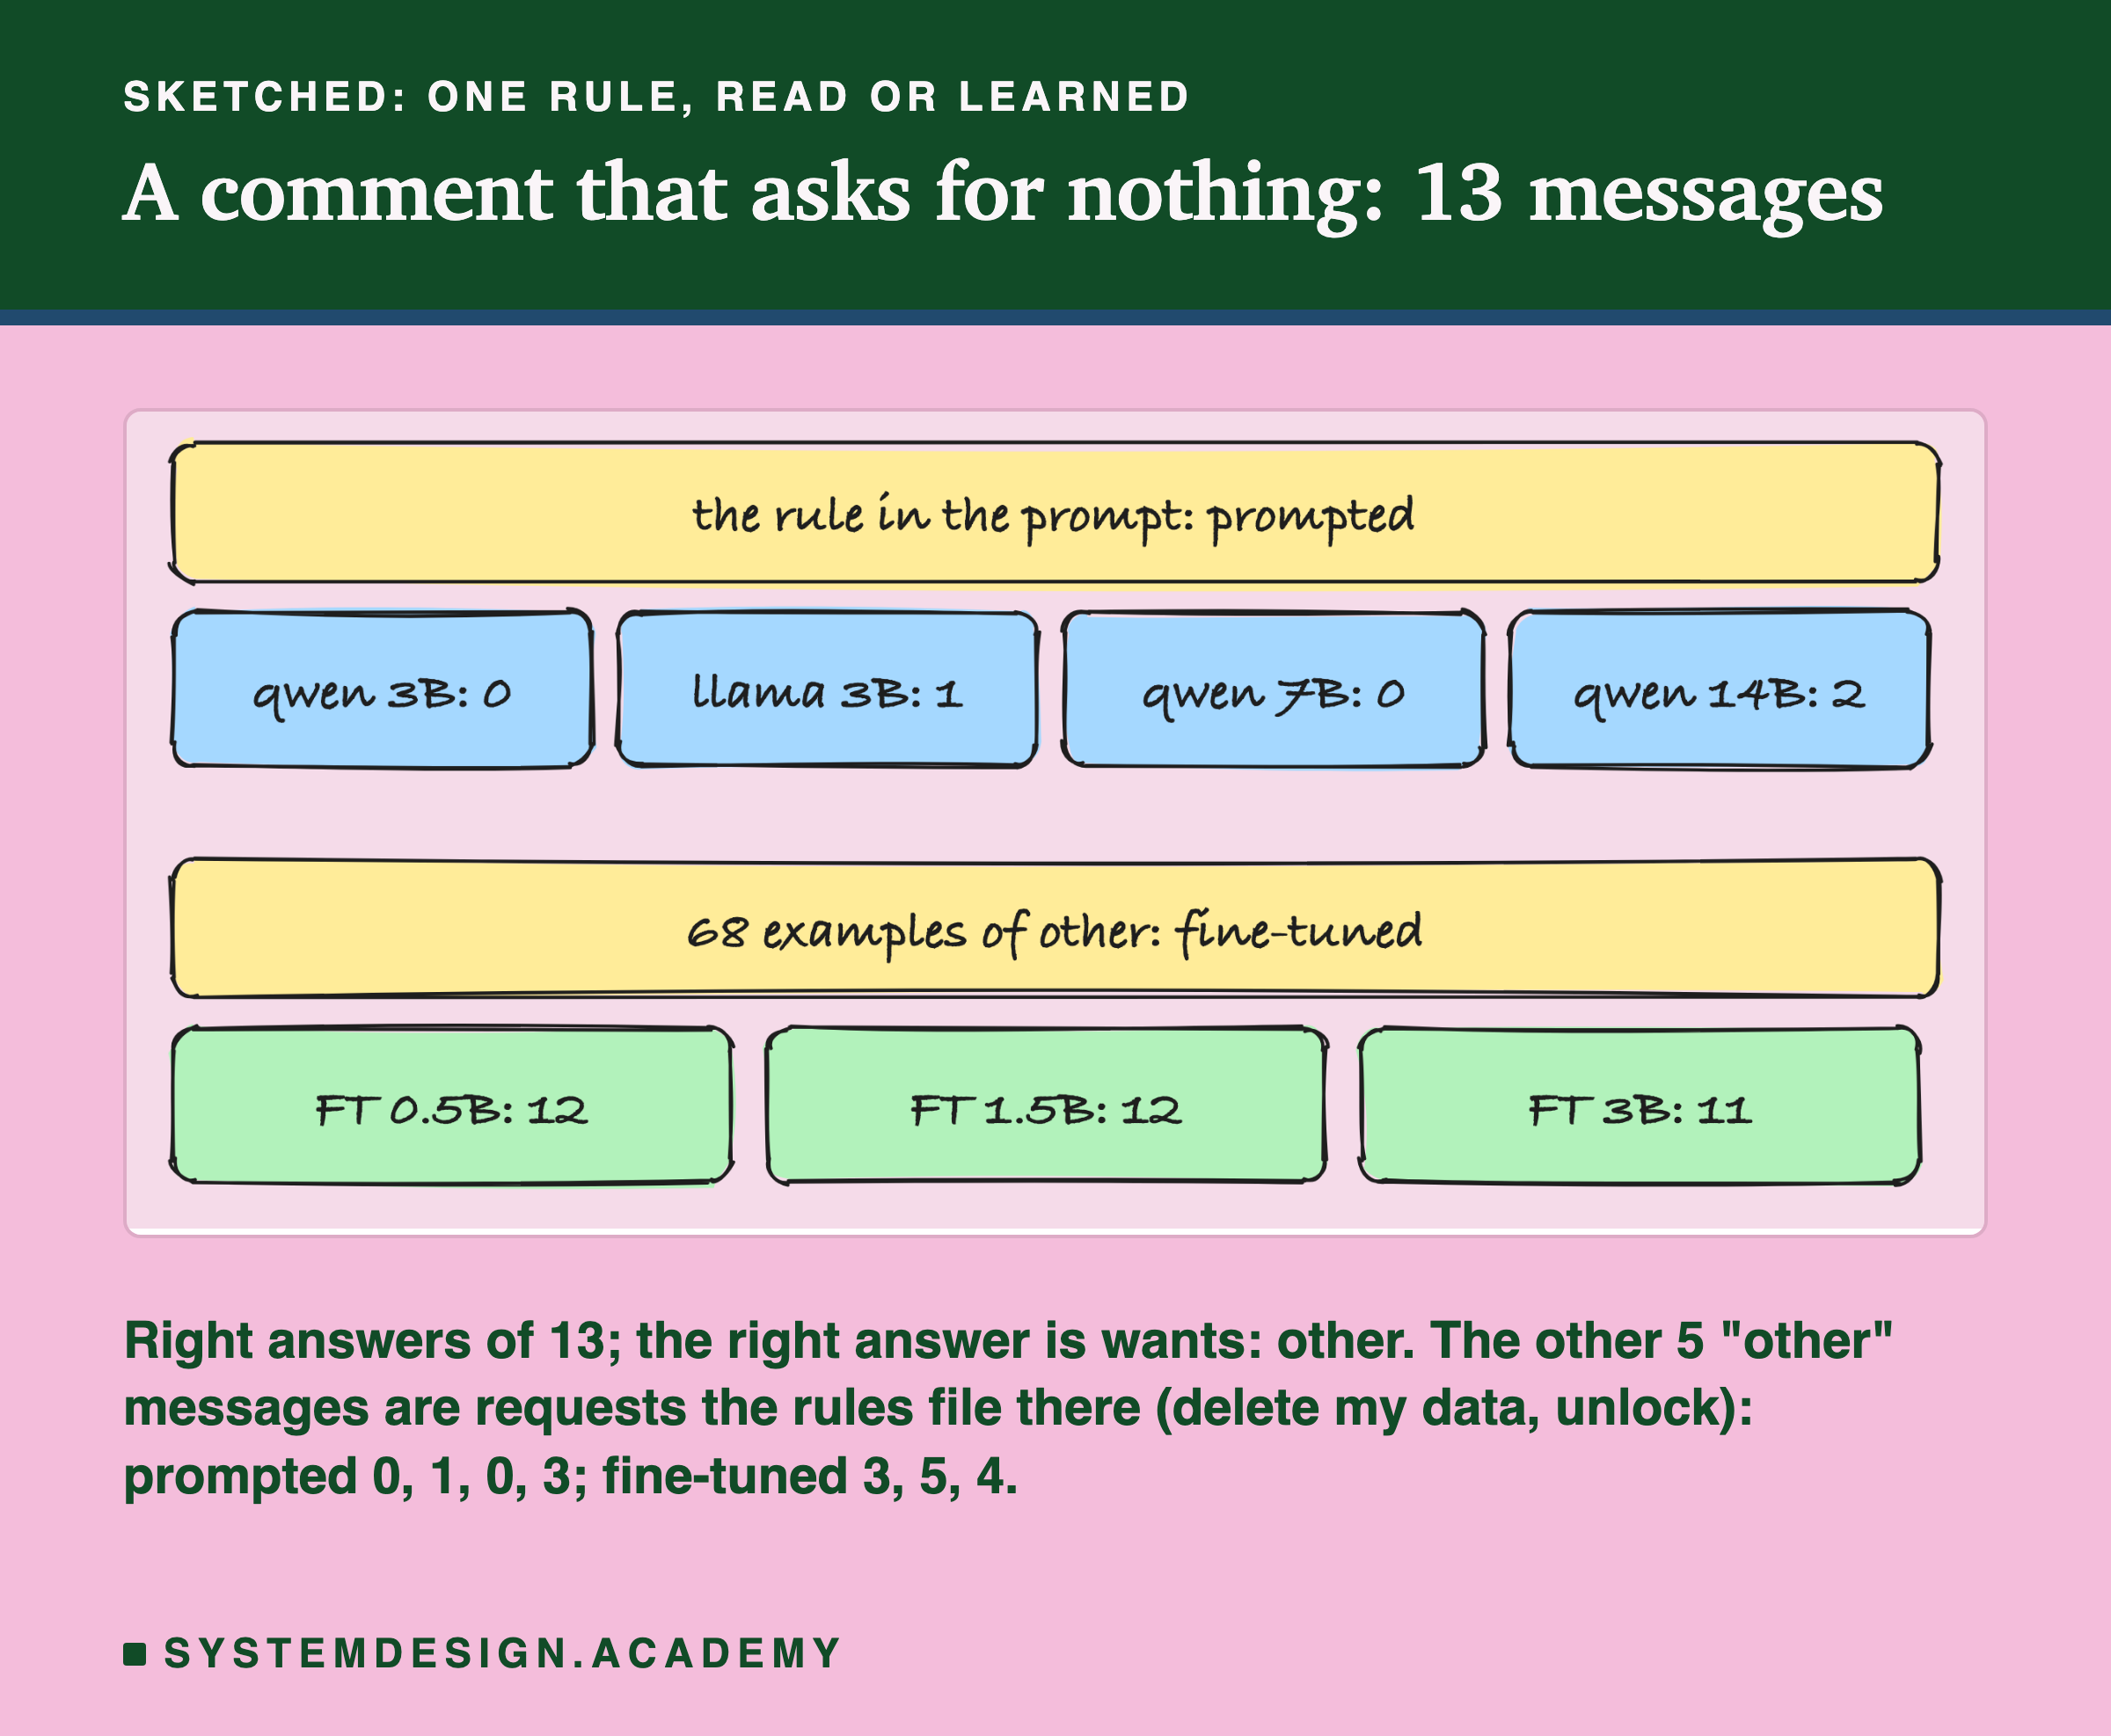
Lesson 3 found one rule that no prompted model kept, whatever its size: a message that only comments, thanks or complains, and asks for nothing, has wants "other". The prompted models kept answering "information" or guessing what the customer might want next. 18 test messages have the right answer "other", but they are two different groups, as lesson 3 showed. 13 are those pure comments. The other 5 are requests that the rules also file under "other", because none of the six actions fits them: delete my account (te043, te115), delete a photo (te052), send me a copy of my data (te094), and unlock my account (te127, which is arguably a change). I use lesson 3's own list of the 13, so the two lessons count the same messages.
On the 13 comments, the prompted models got 0, 1, 0 and 2 right. The fine-tunes got 12, 12 and 11. All four prompted models read the rule in plain words on every call; the fine-tunes never read it at all. What they had instead were 68 training examples whose right answer was "other", and on these 13 messages they gave that answer most of the time. On the 5 requests the gap is smaller: the prompted models got 0, 1, 0 and 3 (three of the 14B's are the delete-data requests), the fine-tunes 3, 5 and 4. Why the prompt failed on the comments I cannot say from this data. One possible reason is that a model trained to be helpful treats every message as a request; treat that as a guess.
The same pattern shows on the next rule down. On the 24 messages that only ask a question, the right answer is "information": the fine-tunes got 24, 24 and 23, the prompted models 15 to 23.
The strongest test of what training added is the list of fields that all four prompted models got wrong. On the current rules there are 22: 12 wants, 5 category, 4 item and 1 urgent. Each fine-tune got 12 or 13 of them right, and all three together got 9. Most of those are "other" answers on comments. What is left, 7 fields wrong in all seven models, is mostly the unclear rules from the last slide.
Where Training Did Not Help, or Made It Worse
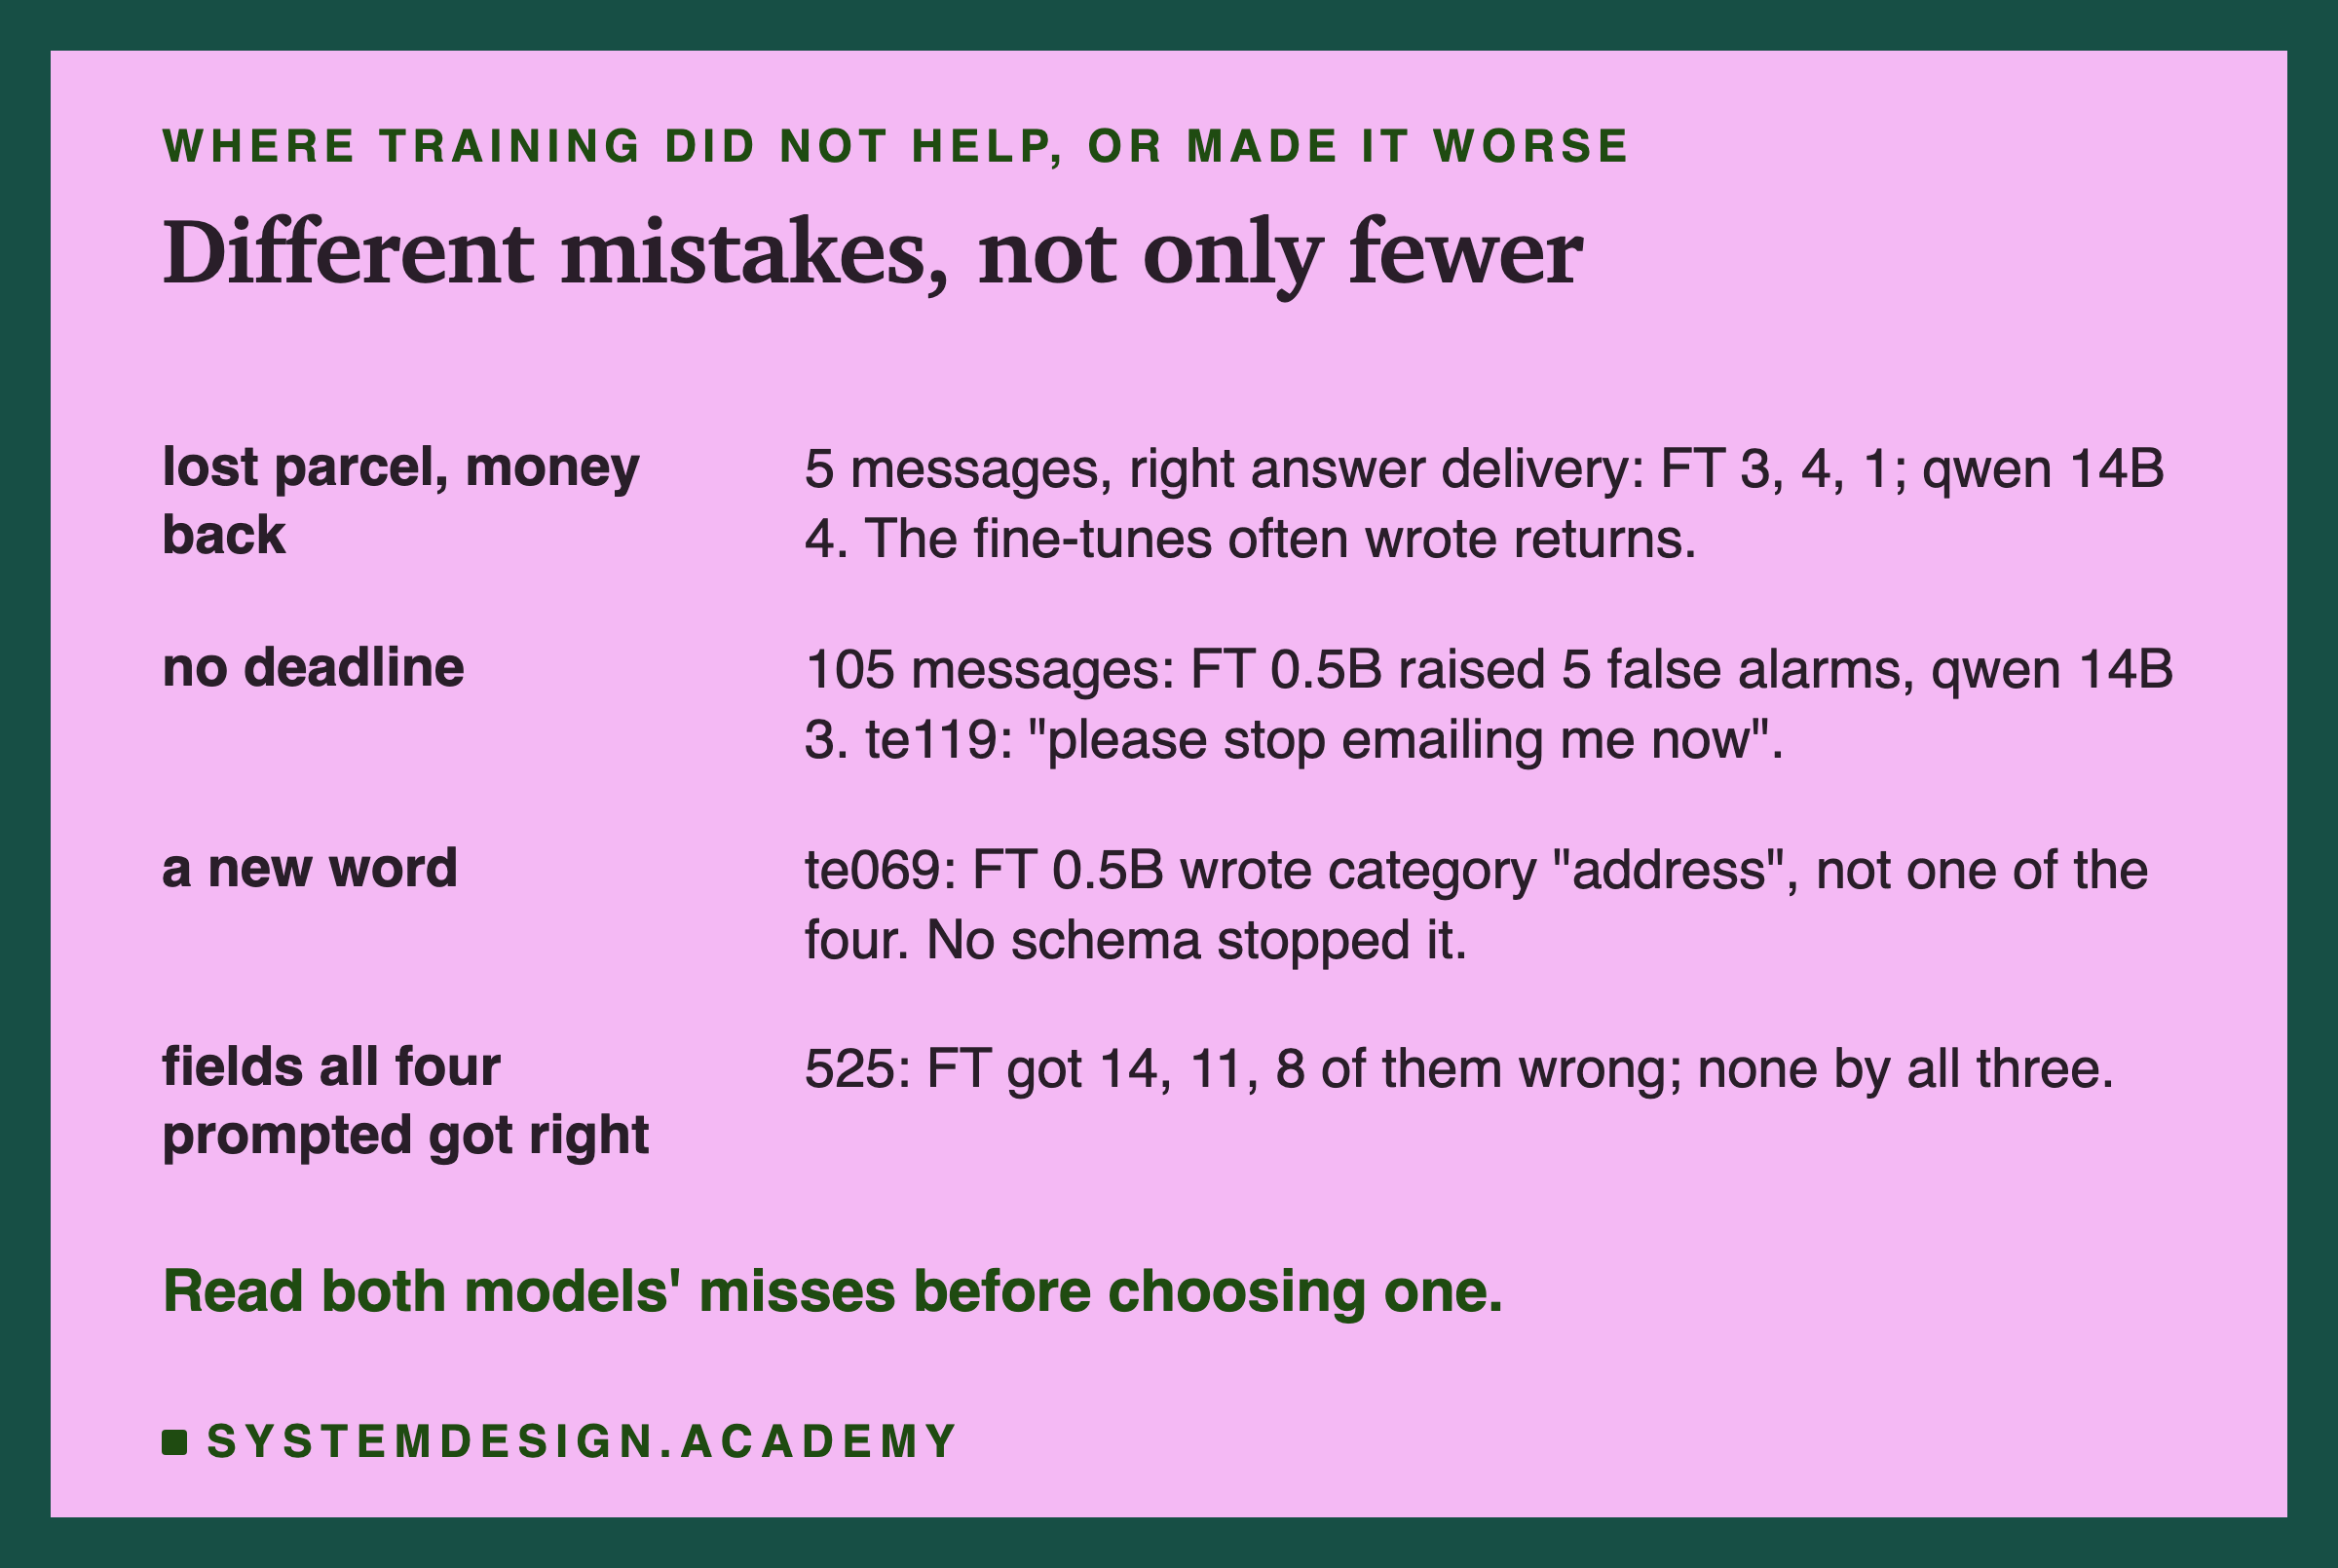
A fine-tune is not a prompted model with fewer mistakes. It is a model with different mistakes, and some of them are ones the prompts never made.
A lost parcel with money back. The rules say a parcel that never arrived or arrived damaged stays delivery, even when the customer asks for a refund. Five test messages are exactly that. The fine-tunes got 3, 4 and 1 of them right; the 14B got 4. The fine-tuned 3B sent most of them to returns. One possible reason is in the training data: it has only 7 examples of a delivery ticket with a refund, against 28 of a returns ticket with a refund, so "refund" may have been learned as a sign of returns. That is a guess from the counts, not something I tested.
False alarms. On the 105 messages that are not urgent, the 0.5B raised 5 false alarms and the 14B 3. One of them was "please stop emailing me now". The word "now" on its own is not on the rules' list; "right now" is. In the 500 training examples, "now" without "right" appears 12 times, and 4 of those examples are labelled urgent. All four also contain one of the listed words, such as "today" or "tonight", so the label is right; but a model learning from examples cannot tell which word earned it. That is one possible reason for the false alarm, not a tested one, and it points at a weakness of learning rules from examples: it learns whatever the examples have in common, including things the rule never said.
A word outside the list. Once, the 0.5B wrote the category "address". The prompted models could not do that, because the schema only allowed the four words. mlx had no schema, so nothing stopped it. When you serve a fine-tune, check its output against the list of allowed values, or use a runtime that can enforce a schema.
New mistakes. Of the 525 fields that all four prompted models got right, the fine-tunes got 14, 11 and 8 wrong. None of them was wrong in all three fine-tunes, which again looks like each small model learning slightly different patterns, not a rule that training broke.
The Chapter's 80 Older Messages
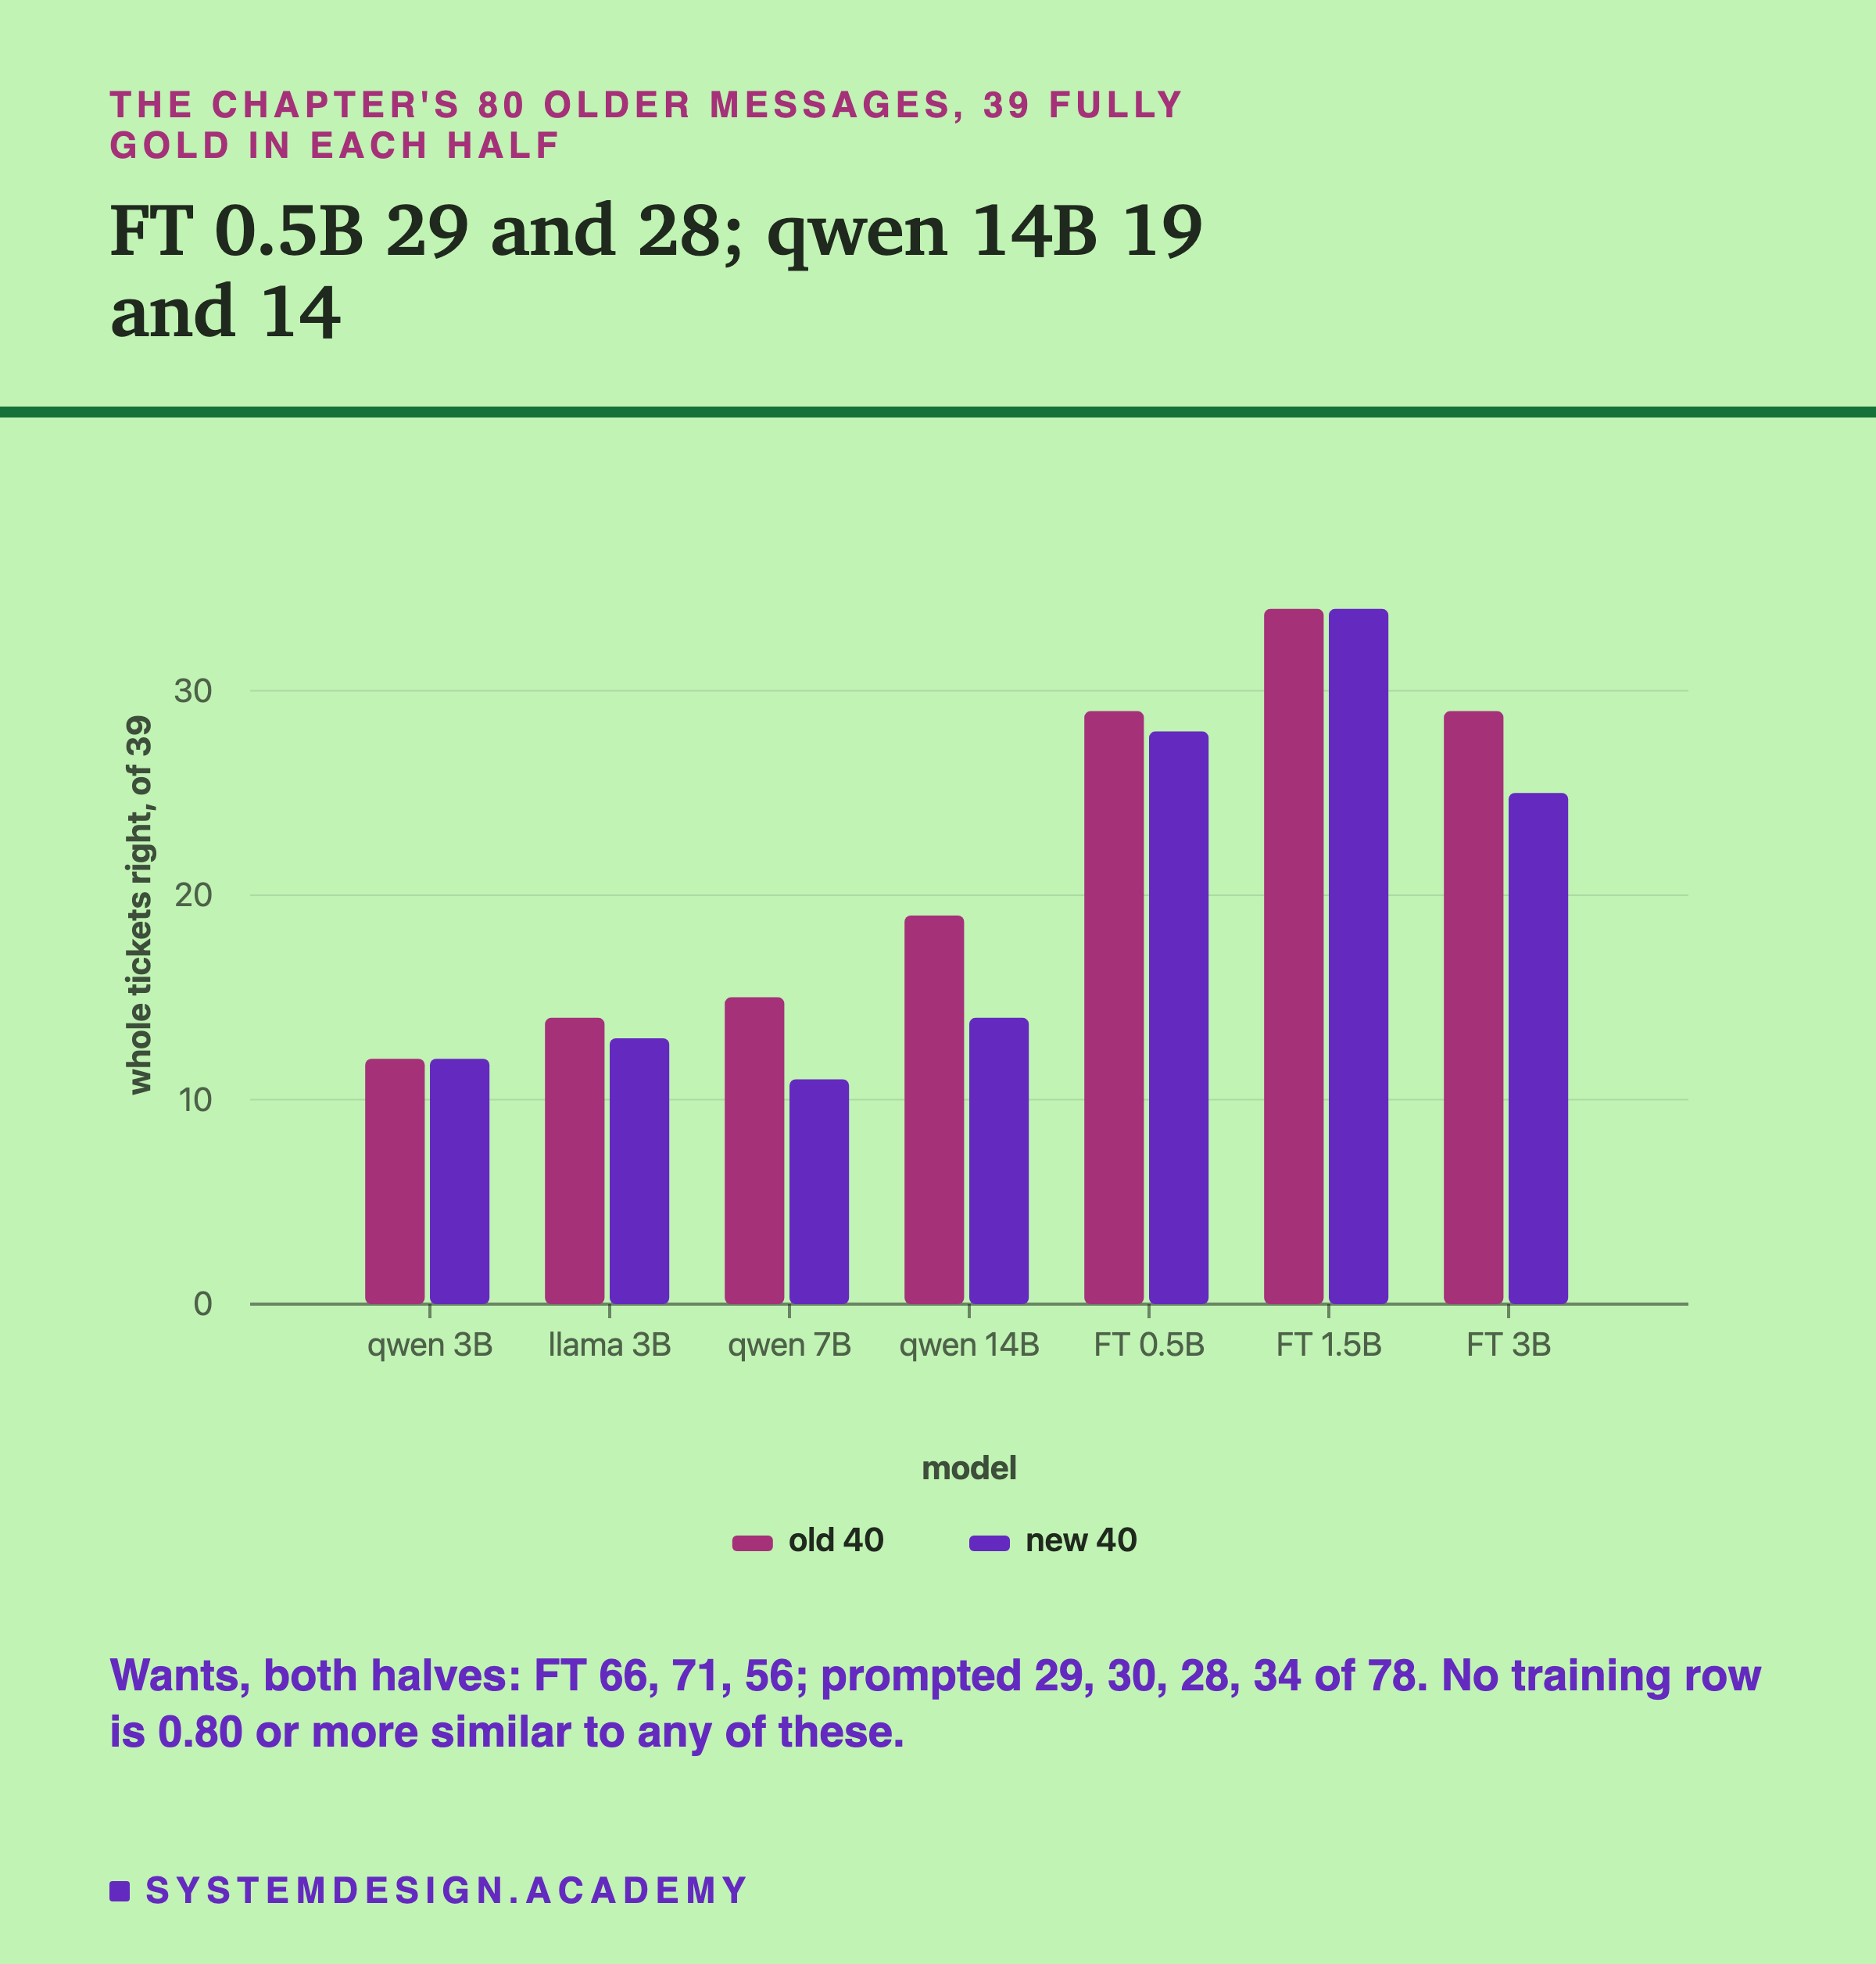
The chapter keeps the 80 test messages from the prompting chapter as a second, smaller test. 39 in each half have all five fields gold. These messages were written for the sorting task, so most of them state a problem without asking for anything, and their right "wants" is often "other".
Here the fine-tunes were far ahead. The 0.5B got 29 and 28 whole tickets right of 39, against 19 and 14 for the prompted 14B, and the sign test put that beyond luck. The reason is almost all one field. On wants, over both halves, the fine-tunes got 66, 71 and 56 of 78, the prompted models 28 to 34. It is the same "other" rule as before, showing up far more often because of how these messages were written.
A result this much better needs a check before I believe it. Could the training set contain these messages, or close copies? Lesson 2's leak rule dropped every training message with a similarity of 0.80 or more to any of the 220 test messages, including these 80. The highest similarity of any of the 500 kept training messages to any test message is 0.7986, and that pair shows what a line like this does and does not catch: "Order 30119 arrived with the box crushed and the lamp inside is broken" (training, tr208) against "The box arrived crushed and the two tall glasses inside are broken" (test, te107). They are close in meaning, and te107 is one of the 22 tickets only the fine-tuned 0.5B got right. An cutoff removes near copies; it does not remove close cousins, so I cannot rule out that some of the gain comes from similar training messages. What is clear is where the gain sits: on "other", an answer these messages are full of and the training set has 68 examples of.
Try It Yourself
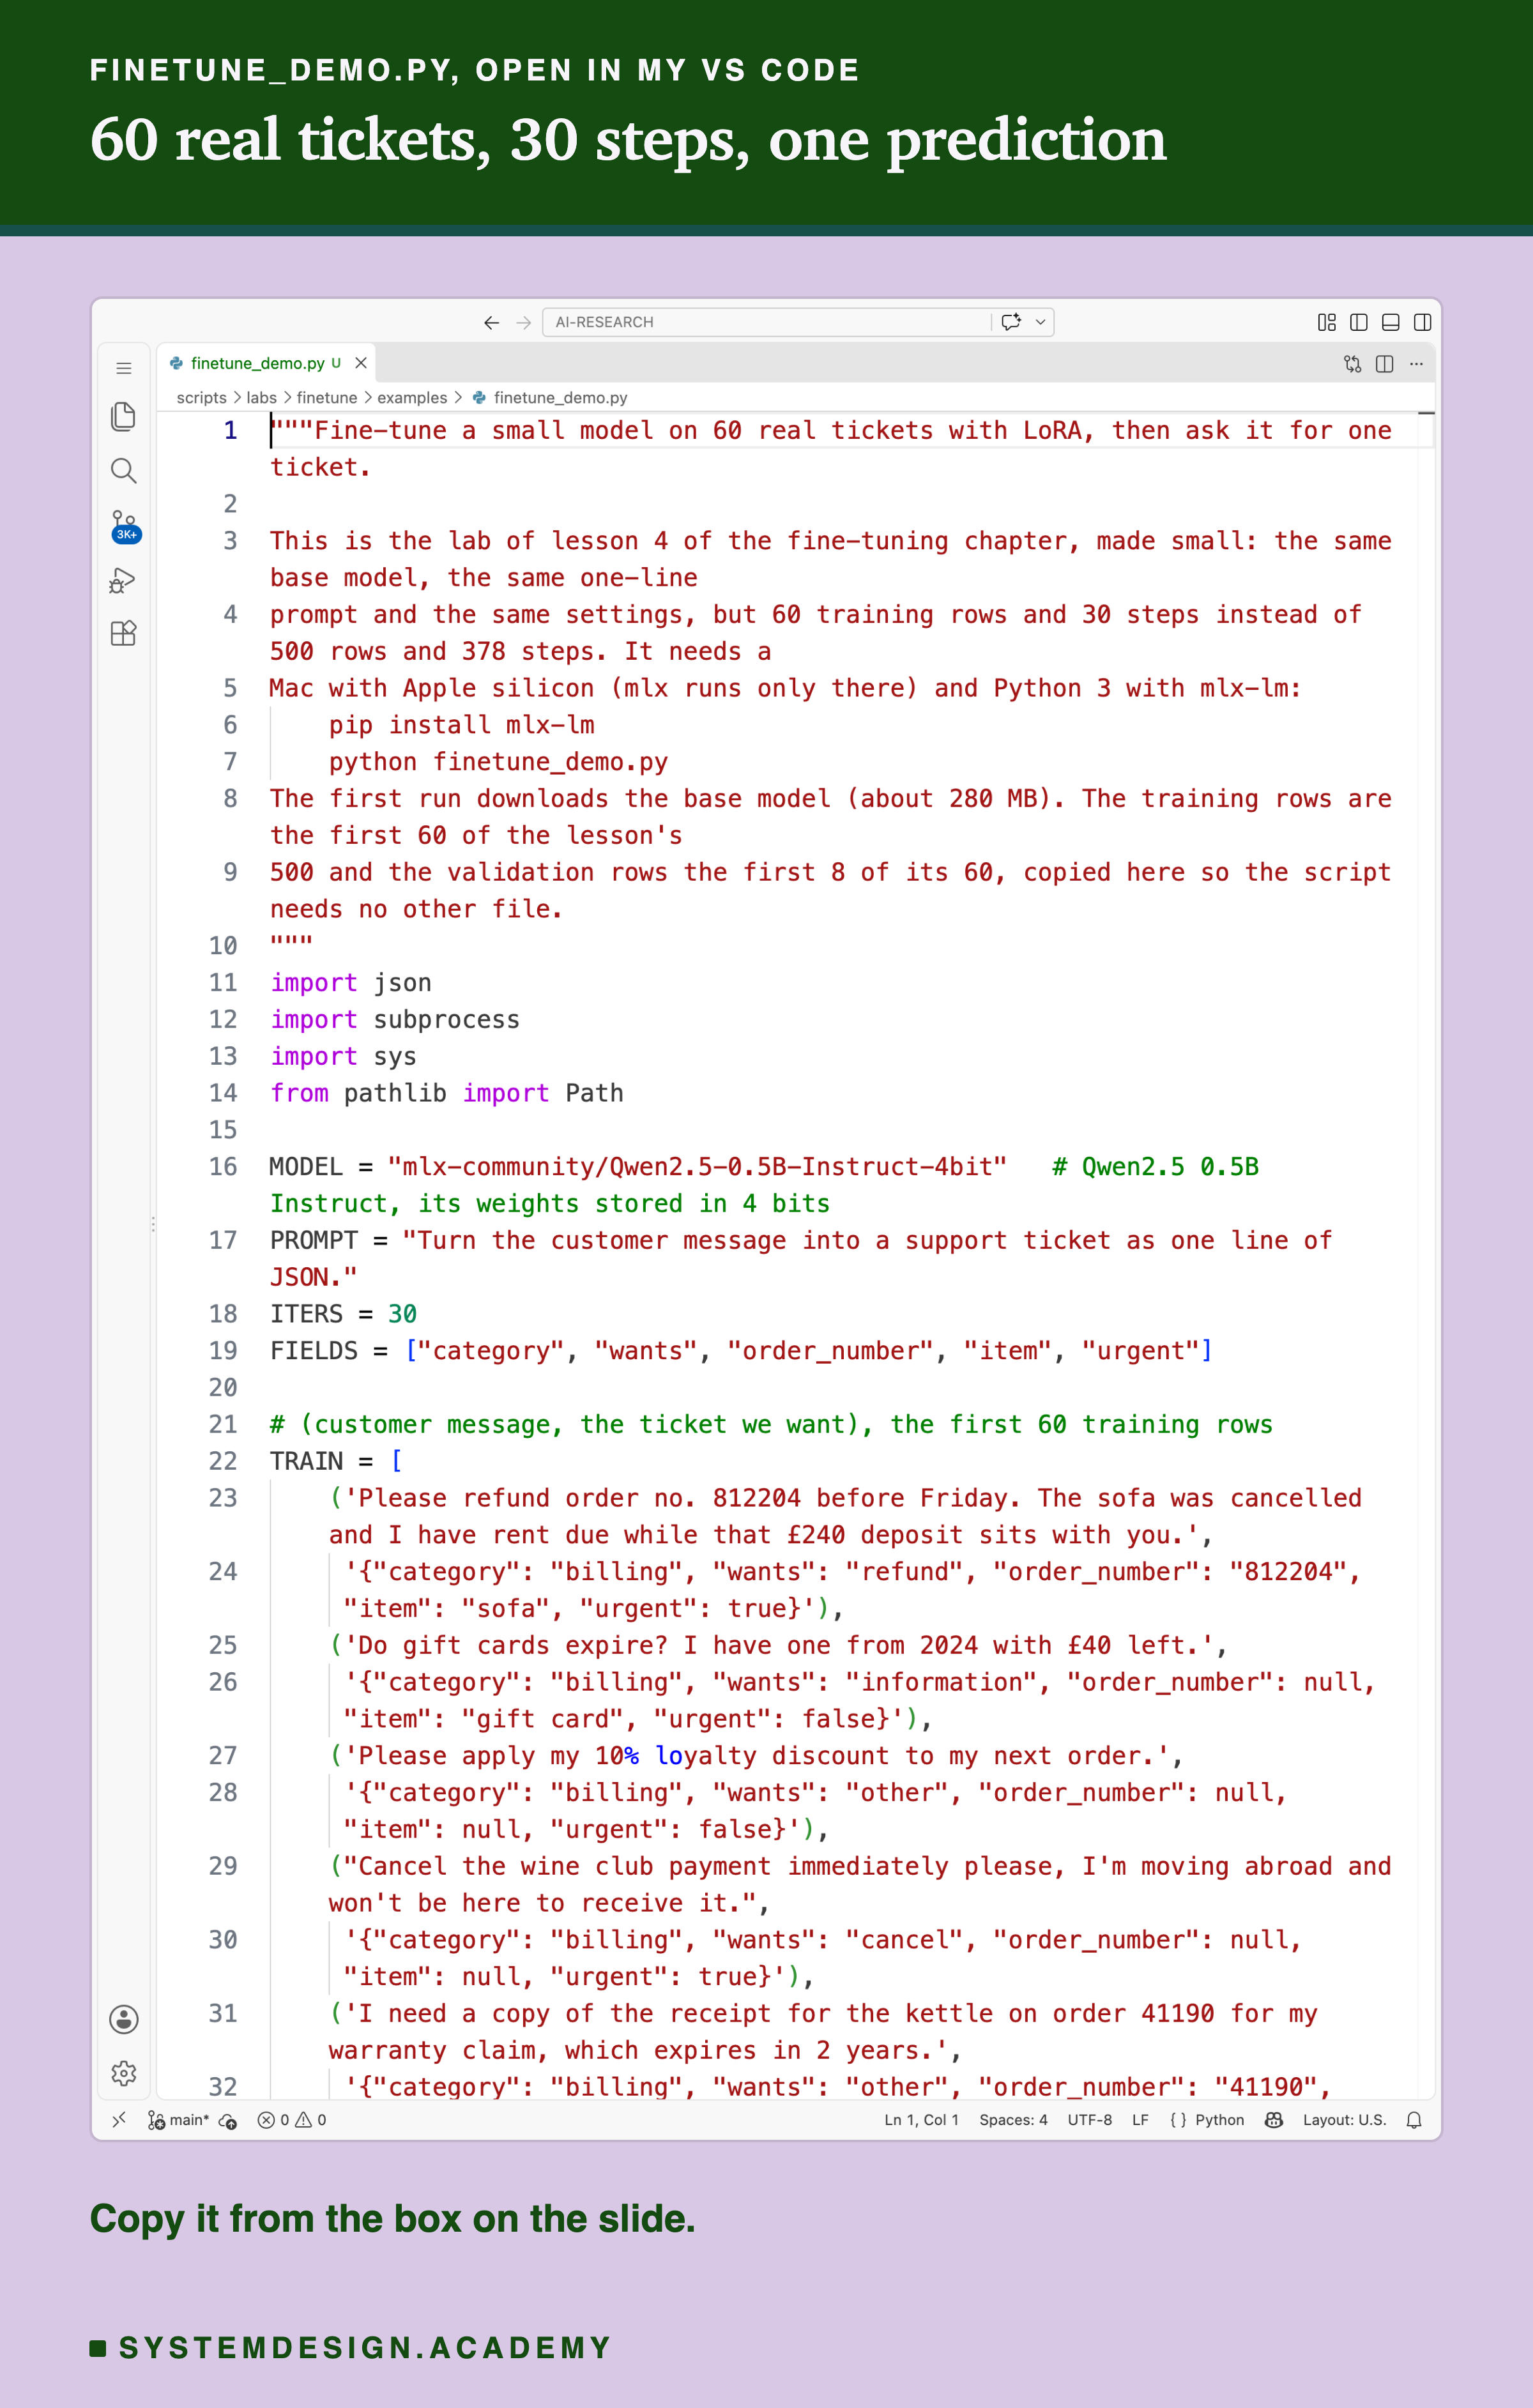
This script is the lab's training run, made small enough to watch. It carries the first 60 of the 500 training examples and the first 8 of the 60 validation examples inside the file, writes them in mlx-lm's format, and runs mlx-lm's training with the same base model, the same one-line prompt and the same settings as the lab, but for 30 steps instead of 378, printing the validation loss every 10 steps instead of every 20, and naming the 16 trained layers explicitly where the lab used the same number as the default. Then it loads the base model with the new adapter and asks for one ticket, for test message te114, the thank-you to the driver.
Before you run this lab. This one does not use Ollama; it uses Python with mlx-lm (pip install mlx-lm), and the first run downloads the 0.5B base model, about 280 MB. If you have not set up Python for the labs yet, the lab setup guide shows how, on macOS, Windows or Linux. I do not give a training time, because another lab was using the same GPU while mine ran.
If you use Windows or Linux: mlx runs only on Macs with Apple silicon, and this lab used mlx on a Mac, which is the only setup tested here. The same kind of LoRA training is commonly done with Hugging Face's library on a GPU, for example a free Google Colab one; I have not run it for this chapter. Your numbers will differ, and nothing in this lesson claims the Mac's numbers hold on other hardware.
"""Fine-tune a small model on 60 real tickets with LoRA, then ask it for one ticket.

This is the lab of lesson 4 of the fine-tuning chapter, made small: the same base model, the same one-line
prompt and the same settings, but 60 training rows and 30 steps instead of 500 rows and 378 steps. It needs a
Mac with Apple silicon (mlx runs only there) and Python 3 with mlx-lm:
    pip install mlx-lm
    python finetune_demo.py
The first run downloads the base model (about 280 MB). The training rows are the first 60 of the lesson's
500 and the validation rows the first 8 of its 60, copied here so the script needs no other file.
"""
import json
import subprocess
import sys
from pathlib import Path

MODEL = "mlx-community/Qwen2.5-0.5B-Instruct-4bit"   # Qwen2.5 0.5B Instruct, its weights stored in 4 bits
PROMPT = "Turn the customer message into a support ticket as one line of JSON."
ITERS = 30
FIELDS = ["category", "wants", "order_number", "item", "urgent"]

# (customer message, the ticket we want), the first 60 training rows
TRAIN = [
    ('Please refund order no. 812204 before Friday. The sofa was cancelled and I have rent due while that £240 deposit sits with you.',
     '{"category": "billing", "wants": "refund", "order_number": "812204", "item": "sofa", "urgent": true}'),
    ('Do gift cards expire? I have one from 2024 with £40 left.',
     '{"category": "billing", "wants": "information", "order_number": null, "item": "gift card", "urgent": false}'),
    ('Please apply my 10% loyalty discount to my next order.',
     '{"category": "billing", "wants": "other", "order_number": null, "item": null, "urgent": false}'),
    ("Cancel the wine club payment immediately please, I'm moving abroad and won't be here to receive it.",
     '{"category": "billing", "wants": "cancel", "order_number": null, "item": null, "urgent": true}'),
    ('I need a copy of the receipt for the kettle on order 41190 for my warranty claim, which expires in 2 years.',
     '{"category": "billing", "wants": "other", "order_number": "41190", "item": "kettle", "urgent": false}'),
    ('Someone has used my card on your site to buy perfume. Refund it right now and block the order.',
     '{"category": "billing", "wants": "refund", "order_number": null, "item": "perfume", "urgent": true}'),
    ("Please add our cost centre code to teh invoices from now on, and reissue last month's.",
     '{"category": "billing", "wants": "change", "order_number": null, "item": null, "urgent": false}'),
    ('Are my saved card details shared with anyone?',
     '{"category": "account", "wants": "information", "order_number": null, "item": null, "urgent": false}'),
    ('order no. 41876 was a duplicate, i clicked pay twice for the £120 bookcase when the page froze. please refund one of them',
     '{"category": "billing", "wants": "refund", "order_number": "41876", "item": "bookcase", "urgent": false}'),
    ("Hello, does next day delivery include Sundays for furniture? I'm in postcode LS6 3HN.",
     '{"category": "delivery", "wants": "information", "order_number": null, "item": "furniture", "urgent": false}'),
    ('Can you pleas tell me urgently why my card was declined for the laptop? I have tried three times.',
     '{"category": "billing", "wants": "information", "order_number": null, "item": "laptop", "urgent": true}'),
    ('Stop calling me at work. It must stop today, my manager has noticed.',
     '{"category": "account", "wants": "stop", "order_number": null, "item": null, "urgent": true}'),
    ('charged £189 for the printer and £189 AGAIN for the ink bundle that was meant to be £19. order 57018. fix it and refund me',
     '{"category": "billing", "wants": "refund", "order_number": "57018", "item": "ink", "urgent": false}'),
    ('you chraged me for a 4-slice toaster on 66018 that never shipped, I want my money back asap',
     '{"category": "delivery", "wants": "refund", "order_number": "66018", "item": "toaster", "urgent": true}'),
    ("we're away the week the hot tub is due. please rebook it for the week after",
     '{"category": "delivery", "wants": "change", "order_number": null, "item": "hot tub", "urgent": false}'),
    ('How do I change my password? Or can you jsut reset it for me?',
     '{"category": "account", "wants": "information", "order_number": null, "item": null, "urgent": false}'),
    ("Please delete my child's account, they are under 13.",
     '{"category": "account", "wants": "other", "order_number": null, "item": null, "urgent": false}'),
    ("Hi, what day will the sofa on order 50378 be delivered? I haven't had a date yet.",
     '{"category": "delivery", "wants": "information", "order_number": "50378", "item": "sofa", "urgent": false}'),
    ('The currency converter on your site is wrong, it showed 30 euros for a scarf and charged far more.',
     '{"category": "billing", "wants": "other", "order_number": null, "item": "scarf", "urgent": false}'),
    ("The tracking number you gave me for teh speaker on 40502 doesn't work on the courier's site. Is it the right one?",
     '{"category": "delivery", "wants": "information", "order_number": "40502", "item": "speaker", "urgent": false}'),
    ('Please switch me from monthly to annual billing and tell me what the new price is.',
     '{"category": "billing", "wants": "change", "order_number": null, "item": null, "urgent": false}'),
    ('Is there any delay to deliveries because of the strikes? I need my order by Friday.',
     '{"category": "delivery", "wants": "information", "order_number": null, "item": null, "urgent": true}'),
    ('I need a proper VAT receipt for the dishwasher on order 52480 today for a grant claim, the one you sent has no VAT number.',
     '{"category": "billing", "wants": "other", "order_number": "52480", "item": "dishwasher", "urgent": true}'),
    ('The desk lamp on #20931 was advertised with free delivery but I paid £4.95 postage at checkout. Can I get the postage refunded?',
     '{"category": "billing", "wants": "refund", "order_number": "20931", "item": "lamp", "urgent": false}'),
    ('Sofa delivery estimate is now January. Cancel my order and refund me.',
     '{"category": "delivery", "wants": "cancel", "order_number": null, "item": "sofa", "urgent": false}'),
    ('hoodie from 25003 came with the print peeling off. exchange for a new one please',
     '{"category": "returns", "wants": "replacement", "order_number": "25003", "item": "hoodie", "urgent": false}'),
    ('Thanks for making the return so easy, the drop-off took two minutes.',
     '{"category": "returns", "wants": "other", "order_number": null, "item": null, "urgent": false}'),
    ('can i change the delivery slot for my fridge freezer on 29706 to the evening one',
     '{"category": "delivery", "wants": "change", "order_number": "29706", "item": "fridge freezer", "urgent": false}'),
    ('Do you do returns collection for the armchair on order 39402 or do I have to take it to the post office?',
     '{"category": "returns", "wants": "information", "order_number": "39402", "item": "armchair", "urgent": false}'),
    ('Please unlink my social media login from my account.',
     '{"category": "account", "wants": "other", "order_number": null, "item": null, "urgent": false}'),
    ('Two of the four chairs have wobbly legs. Could you send two new ones and collect the bad ones?',
     '{"category": "returns", "wants": "replacement", "order_number": null, "item": "chair", "urgent": false}'),
    ('what does the charge "SVC FEE" on my receipt for the lawnmower, order 83110, mean',
     '{"category": "billing", "wants": "information", "order_number": "83110", "item": "lawnmower", "urgent": false}'),
    ('#84102 teh mirror is cracked right across. replacement please',
     '{"category": "delivery", "wants": "replacement", "order_number": "84102", "item": "mirror", "urgent": false}'),
    ('The shorts on oder 51408 are too big. Swap for a medium please.',
     '{"category": "returns", "wants": "replacement", "order_number": "51408", "item": "shorts", "urgent": false}'),
    ("The house number on my delivery should be 27 not 72. I've told you twice already. Fix it.",
     '{"category": "delivery", "wants": "change", "order_number": null, "item": null, "urgent": false}'),
    ('order 44720, cancel the telescope before the payment goes through at midnight please',
     '{"category": "billing", "wants": "cancel", "order_number": "44720", "item": "telescope", "urgent": true}'),
    ('Order 18026: is the delivery charge refunded too if I return the chairs?',
     '{"category": "returns", "wants": "information", "order_number": "18026", "item": "chair", "urgent": false}'),
    ('i paid for express shipping on my trainers (order 53308) and they came in 6 days. id like the express fee back',
     '{"category": "billing", "wants": "refund", "order_number": "53308", "item": "trainers", "urgent": false}'),
    ('The artificial tree delivery on #47033 is set for the 2nd. Could you push it back to the 9th?',
     '{"category": "delivery", "wants": "change", "order_number": "47033", "item": "tree", "urgent": false}'),
    ("Where do I find the returns form for the toaster on order 68830? It wasn't in the box.",
     '{"category": "returns", "wants": "information", "order_number": "68830", "item": "toaster", "urgent": false}'),
    ('hi just checking whether you do student discount on laptops, thanks',
     '{"category": "billing", "wants": "information", "order_number": null, "item": "laptop", "urgent": false}'),
    ('Nobody can be home on the booked day for the washing machine delivery. Please change it today.',
     '{"category": "delivery", "wants": "change", "order_number": null, "item": "washing machine", "urgent": true}'),
    ("why is there a pending charge of $1 on my card? i didn't buy anything. this is really dodgy",
     '{"category": "billing", "wants": "information", "order_number": null, "item": null, "urgent": false}'),
    ('order 64419 has been "processing" for 16 days. absolute joke. cancel it',
     '{"category": "delivery", "wants": "cancel", "order_number": "64419", "item": null, "urgent": false}'),
    ('Please cancel the magazine subscription before it renews tonight. I only wanted one issue.',
     '{"category": "billing", "wants": "cancel", "order_number": null, "item": "magazine", "urgent": true}'),
    ("cancel the garden bench before it ships today, I found out I'll be away for a month",
     '{"category": "billing", "wants": "cancel", "order_number": null, "item": "bench", "urgent": true}'),
    ("Please change the address for the cooker on my order right now. It's going to a flat I moved out of last week.",
     '{"category": "delivery", "wants": "change", "order_number": null, "item": "cooker", "urgent": true}'),
    ("Someone opened an account with my email address. It wasn't me. Please shut it down today and tell me what they ordered.",
     '{"category": "account", "wants": "other", "order_number": null, "item": null, "urgent": true}'),
    ('Hello, please cancel the recurring payemnt for the protein powder on order 27781. It was meant to be a one-off purchase.',
     '{"category": "billing", "wants": "cancel", "order_number": "27781", "item": "protein powder", "urgent": false}'),
    ('Do I need an account to place an order, or can I check out as a guest?',
     '{"category": "account", "wants": "information", "order_number": null, "item": null, "urgent": false}'),
    ('Good morning, please amend my profile so my first name reads Sam, not Samuel.',
     '{"category": "account", "wants": "change", "order_number": null, "item": null, "urgent": false}'),
    ("Can I return trainers I've worn outside once? They rub my heel.",
     '{"category": "returns", "wants": "information", "order_number": null, "item": "trainers", "urgent": false}'),
    ('Can you tell me which courier is bringing my trainers? Order 14408.',
     '{"category": "delivery", "wants": "information", "order_number": "14408", "item": "trainers", "urgent": false}'),
    ('Hi, this is about ref 24068. You agreed on the phone to refund the delivery charge on the wardrobe. Please send the refund you promised and confirm by email.',
     '{"category": "billing", "wants": "refund", "order_number": "24068", "item": "wardrobe", "urgent": false}'),
    ('Kindly correct the title on my account from Mr to Dr.',
     '{"category": "account", "wants": "change", "order_number": null, "item": null, "urgent": false}'),
    ('How long does it take for a new email address to show on my account? The receipt for the kettle on order 70211 still went to the old one.',
     '{"category": "account", "wants": "information", "order_number": "70211", "item": "kettle", "urgent": false}'),
    ('My account got locked after one wrong password. That seems excessive and frankly stupid.',
     '{"category": "account", "wants": "other", "order_number": null, "item": null, "urgent": false}'),
    ('i lost the return label for the rug on 44301, can i still send it back? the 30 days run out tomorrow',
     '{"category": "returns", "wants": "information", "order_number": "44301", "item": "rug", "urgent": true}'),
    ('Stop the "back in stock" emails for the laptop, I no longer need it.',
     '{"category": "account", "wants": "stop", "order_number": null, "item": "laptop", "urgent": false}'),
    ('This is a data protection request for my records.',
     '{"category": "account", "wants": "other", "order_number": null, "item": null, "urgent": false}'),
]

# the first 8 validation rows: never trained on, only used to report the loss
VALID = [
    ('The renewal is due in two days and I want it cancelled before then. Please act urgently.',
     '{"category": "billing", "wants": "cancel", "order_number": null, "item": null, "urgent": true}'),
    ("I bought the glass kettle in your sale and it rang up at the full price. I'd like the sale difference back, and please check your pricing.",
     '{"category": "billing", "wants": "refund", "order_number": null, "item": "kettle", "urgent": false}'),
    ('The tent on 15590 was charged once at checkout and again when it shipped. I would like the second charge refunded.',
     '{"category": "billing", "wants": "refund", "order_number": "15590", "item": "tent", "urgent": false}'),
    ('hello, i cancelled the jumper on #19934 within the hour and the paymnet still went through. refund when you can, thanks',
     '{"category": "billing", "wants": "refund", "order_number": "19934", "item": "jumper", "urgent": false}'),
    ('cancel my premium. never used it once',
     '{"category": "billing", "wants": "cancel", "order_number": null, "item": null, "urgent": false}'),
    ('The treadmill on order no. 56679 has to be stopped before teh van leaves this morning. Cancel it asap.',
     '{"category": "billing", "wants": "cancel", "order_number": "56679", "item": "treadmill", "urgent": true}'),
    ('Kindly cancel my pre-order payment for the game, order 16780. The release date slipped and I no longer need it.',
     '{"category": "billing", "wants": "cancel", "order_number": "16780", "item": "game", "urgent": false}'),
    ('Honestly this is ridiculous. Three emails and still no refund for the air purifier on order 30771. Just put the money back on my card.',
     '{"category": "billing", "wants": "refund", "order_number": "30771", "item": "air purifier", "urgent": false}'),
]

# one of the 140 test messages, never trained on, and its gold ticket
TEST_ID = "te114"
TEST_MESSAGE = 'Hi, please pass a thank you to the driver on order 12876, the big sofa. I paid extra for two-person delivery and it was worth it.'
TEST_GOLD = '{"category": "delivery", "wants": "other", "order_number": "12876", "item": "sofa", "urgent": false}'


def write(path, rows):
    """One chat per line: the one-line prompt, the customer message, and the ticket as the answer."""
    with open(path, "w") as f:
        for message, ticket in rows:
            f.write(json.dumps({"messages": [
                {"role": "system", "content": PROMPT},
                {"role": "user", "content": message},
                {"role": "assistant", "content": ticket}]}) + "\n")


data = Path("ft_demo_data")
data.mkdir(exist_ok=True)
write(data / "train.jsonl", TRAIN)
write(data / "valid.jsonl", VALID)

subprocess.run([
    sys.executable, "-m", "mlx_lm", "lora",
    "--model", MODEL,                     # the base model; its own weights stay frozen
    "--train",                            # train a new add-on (LoRA's rank 8 and scale 20 are mlx-lm's defaults)
    "--data", str(data),                  # the folder holding train.jsonl and valid.jsonl
    "--iters", str(ITERS),                # steps: each step reads one batch and nudges the add-on once
    "--batch-size", "4",                  # rows per step, so 30 steps read 120 rows: the 60, twice
    "--learning-rate", "1e-5",            # how big each nudge is; the lab used the same
    "--num-layers", "16",                 # put the add-on on the last 16 of the model's 24 layers
    "--adapter-path", "ft_demo_adapter",  # the folder where the trained add-on is saved
    "--steps-per-report", "10",           # print the training loss every 10 steps
    "--steps-per-eval", "10",             # print the validation loss every 10 steps
    "--seed", "1",                        # the same shuffle of the rows on every run
], check=True)

from mlx_lm import generate, load  # noqa: E402  (imported here, after training, to keep memory free)

model, tokenizer = load(MODEL, adapter_path="ft_demo_adapter")   # the frozen model with the add-on on top
chat = [{"role": "system", "content": PROMPT}, {"role": "user", "content": TEST_MESSAGE}]
text = tokenizer.apply_chat_template(chat, add_generation_prompt=True, tokenize=False)
reply = generate(model, tokenizer, prompt=text, max_tokens=80, verbose=False).strip()

print(f"\nmessage: {TEST_MESSAGE}")
print(f"reply: {reply}")
gold = json.loads(TEST_GOLD)
try:
    got = json.loads(reply)
except ValueError:
    got = {}
    print("the reply is not valid JSON")
for f in FIELDS:
    mark = "ok" if isinstance(got, dict) and got.get(f) == gold[f] else "WRONG"
    print(f"  {f:<13} {str(got.get(f) if isinstance(got, dict) else None):<14} right: {str(gold[f]):<14} {mark}")
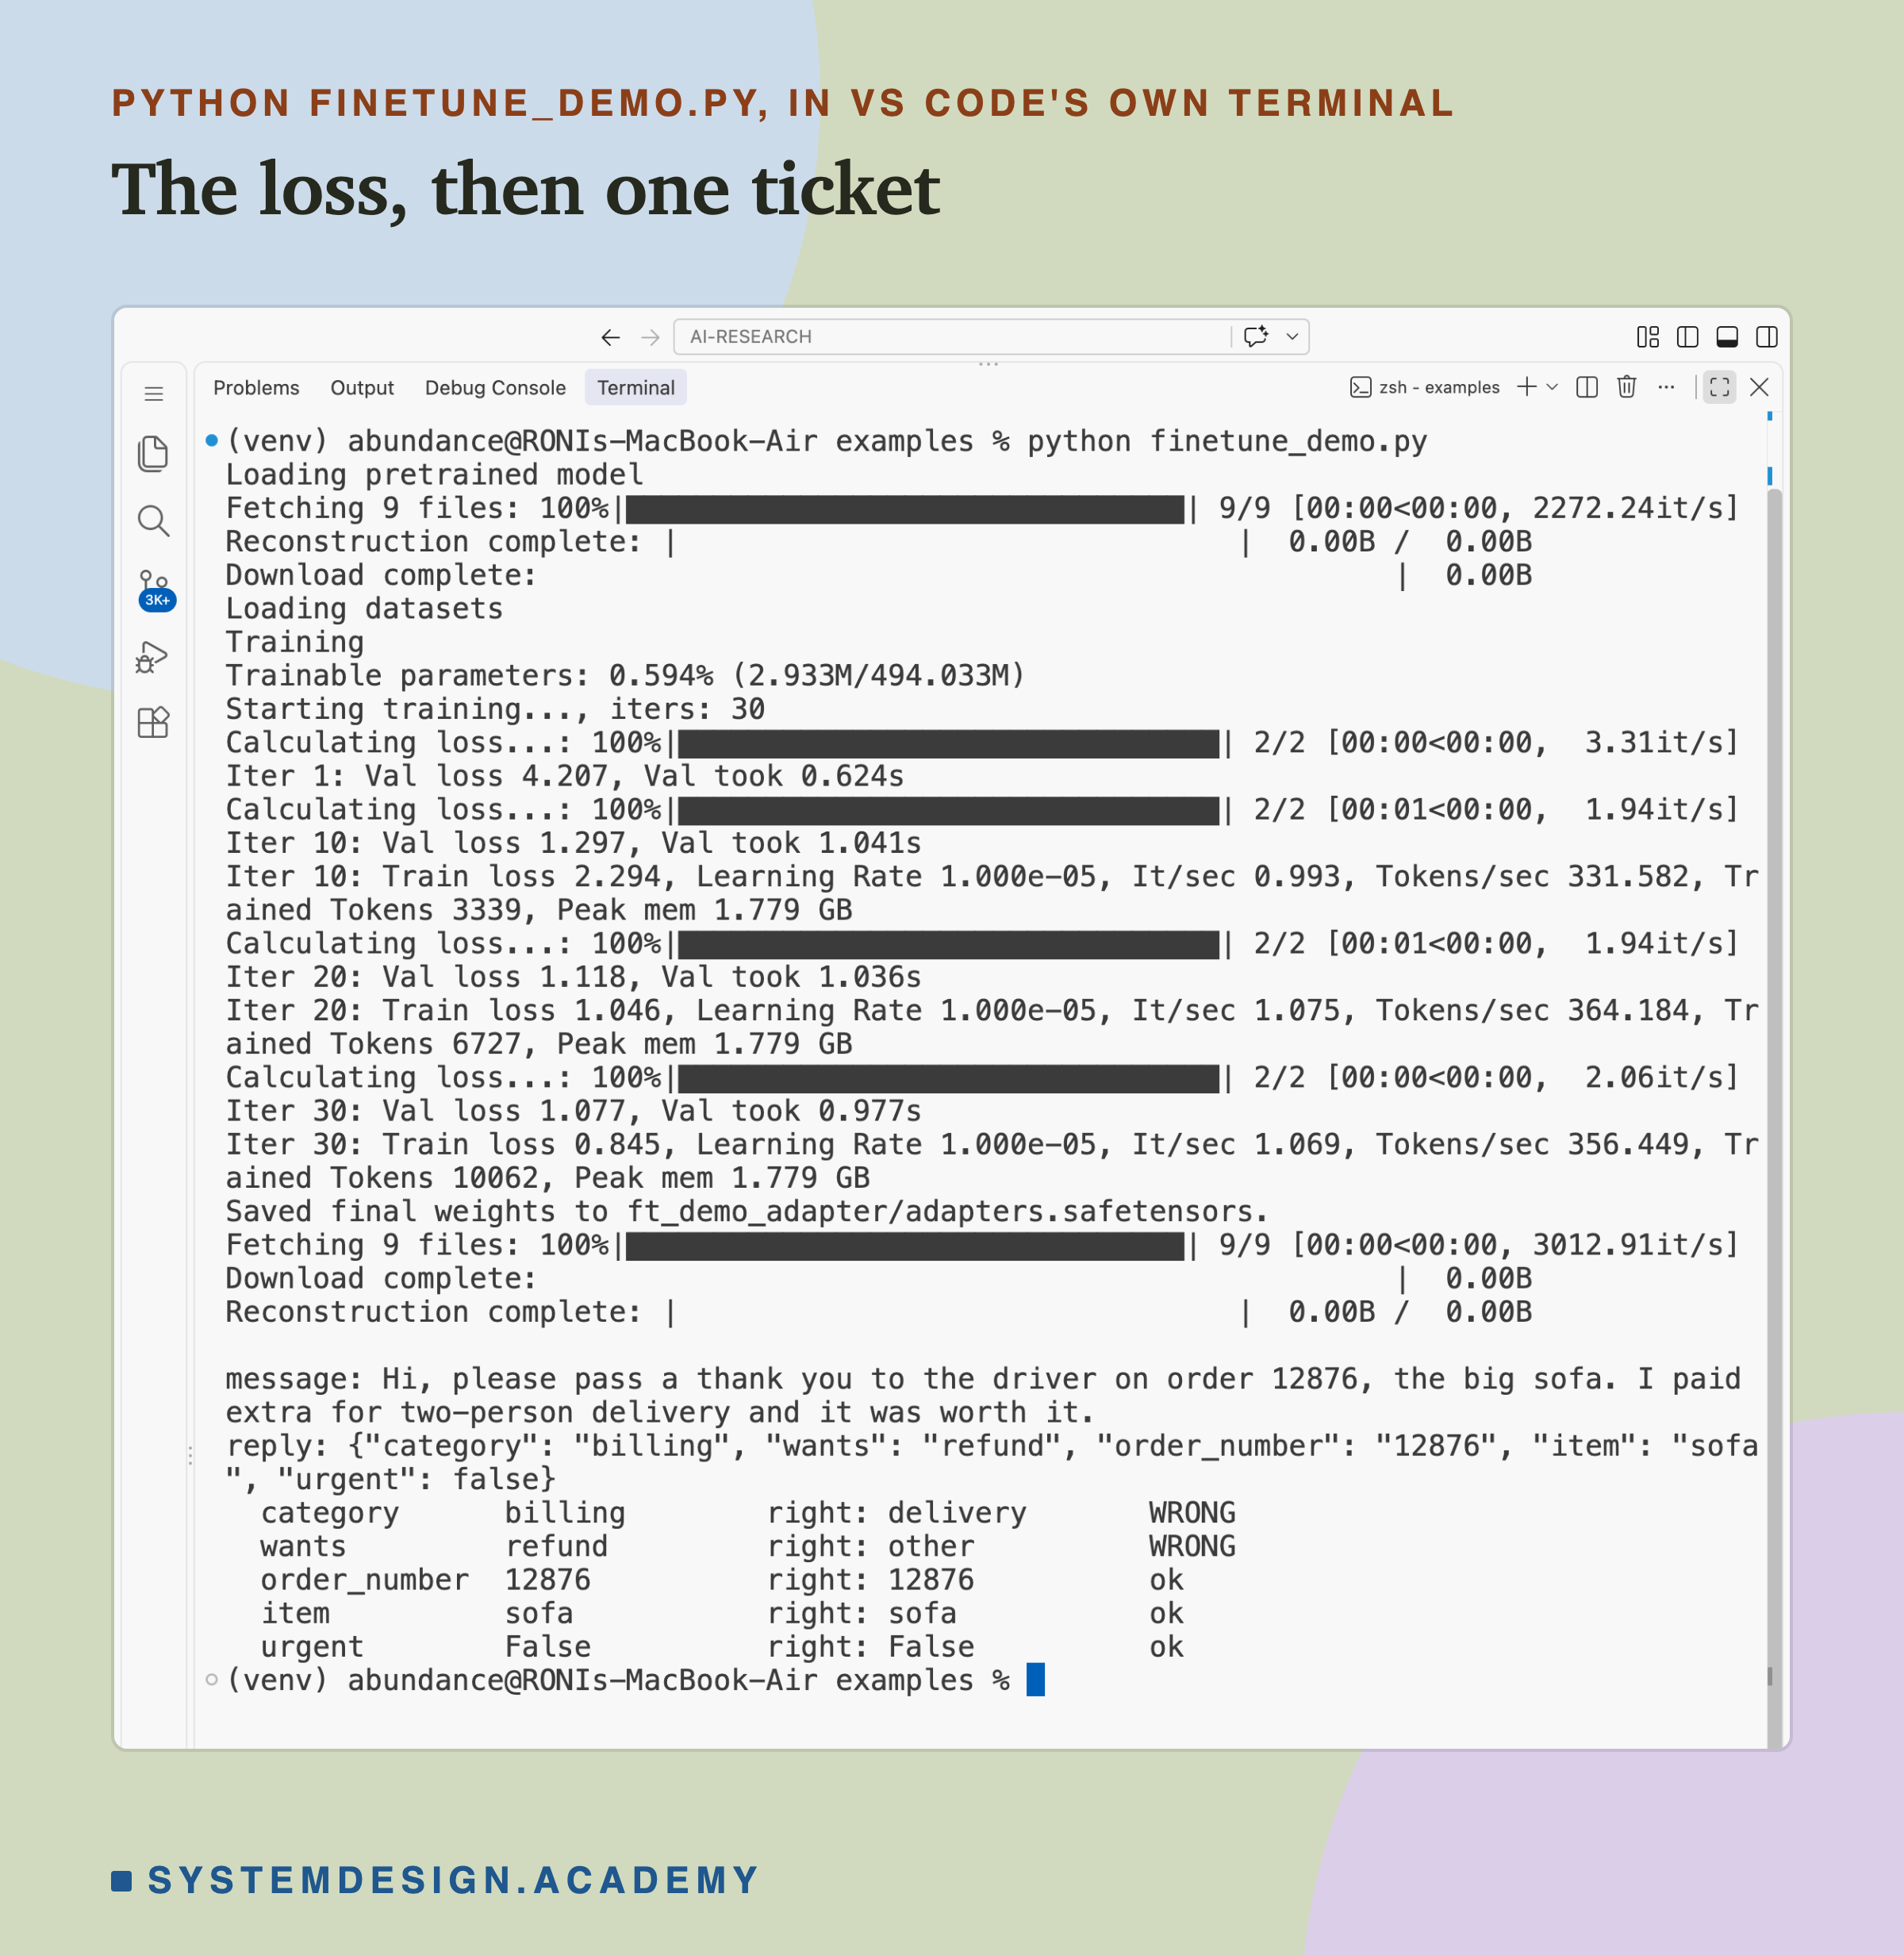
This is a real run in VS Code's terminal.
When I ran it, it printed "Trainable parameters: 0.594% (2.933M/494.033M)", the same count as the lab. The validation loss went from 4.207 at the start to 1.297 at step 10, 1.118 at step 20 and 1.077 at step 30. The reply was valid JSON with the right five keys, and three fields were right: the order number, the item "sofa" and urgent false. The category came out billing instead of delivery, and wants came out refund instead of other.
A 30-step demo is not the lab's 378-step run, and it is not meant to match its scores. Thirty steps on 60 examples is enough to learn the shape of a ticket, which is why the loss fell so fast and the JSON was right. It is not enough to learn the house rules: the lab's full 0.5B run, trained on all 500 examples for 378 steps, got every field of te114 right. The lab's demo mode checked that the script's 60 training rows and 8 validation rows are exactly the first rows of the lab's files, and that the message and its gold ticket match the test files; the output above is from my run, and your numbers can differ a little on a different Mac or version of mlx.
The Lab Report
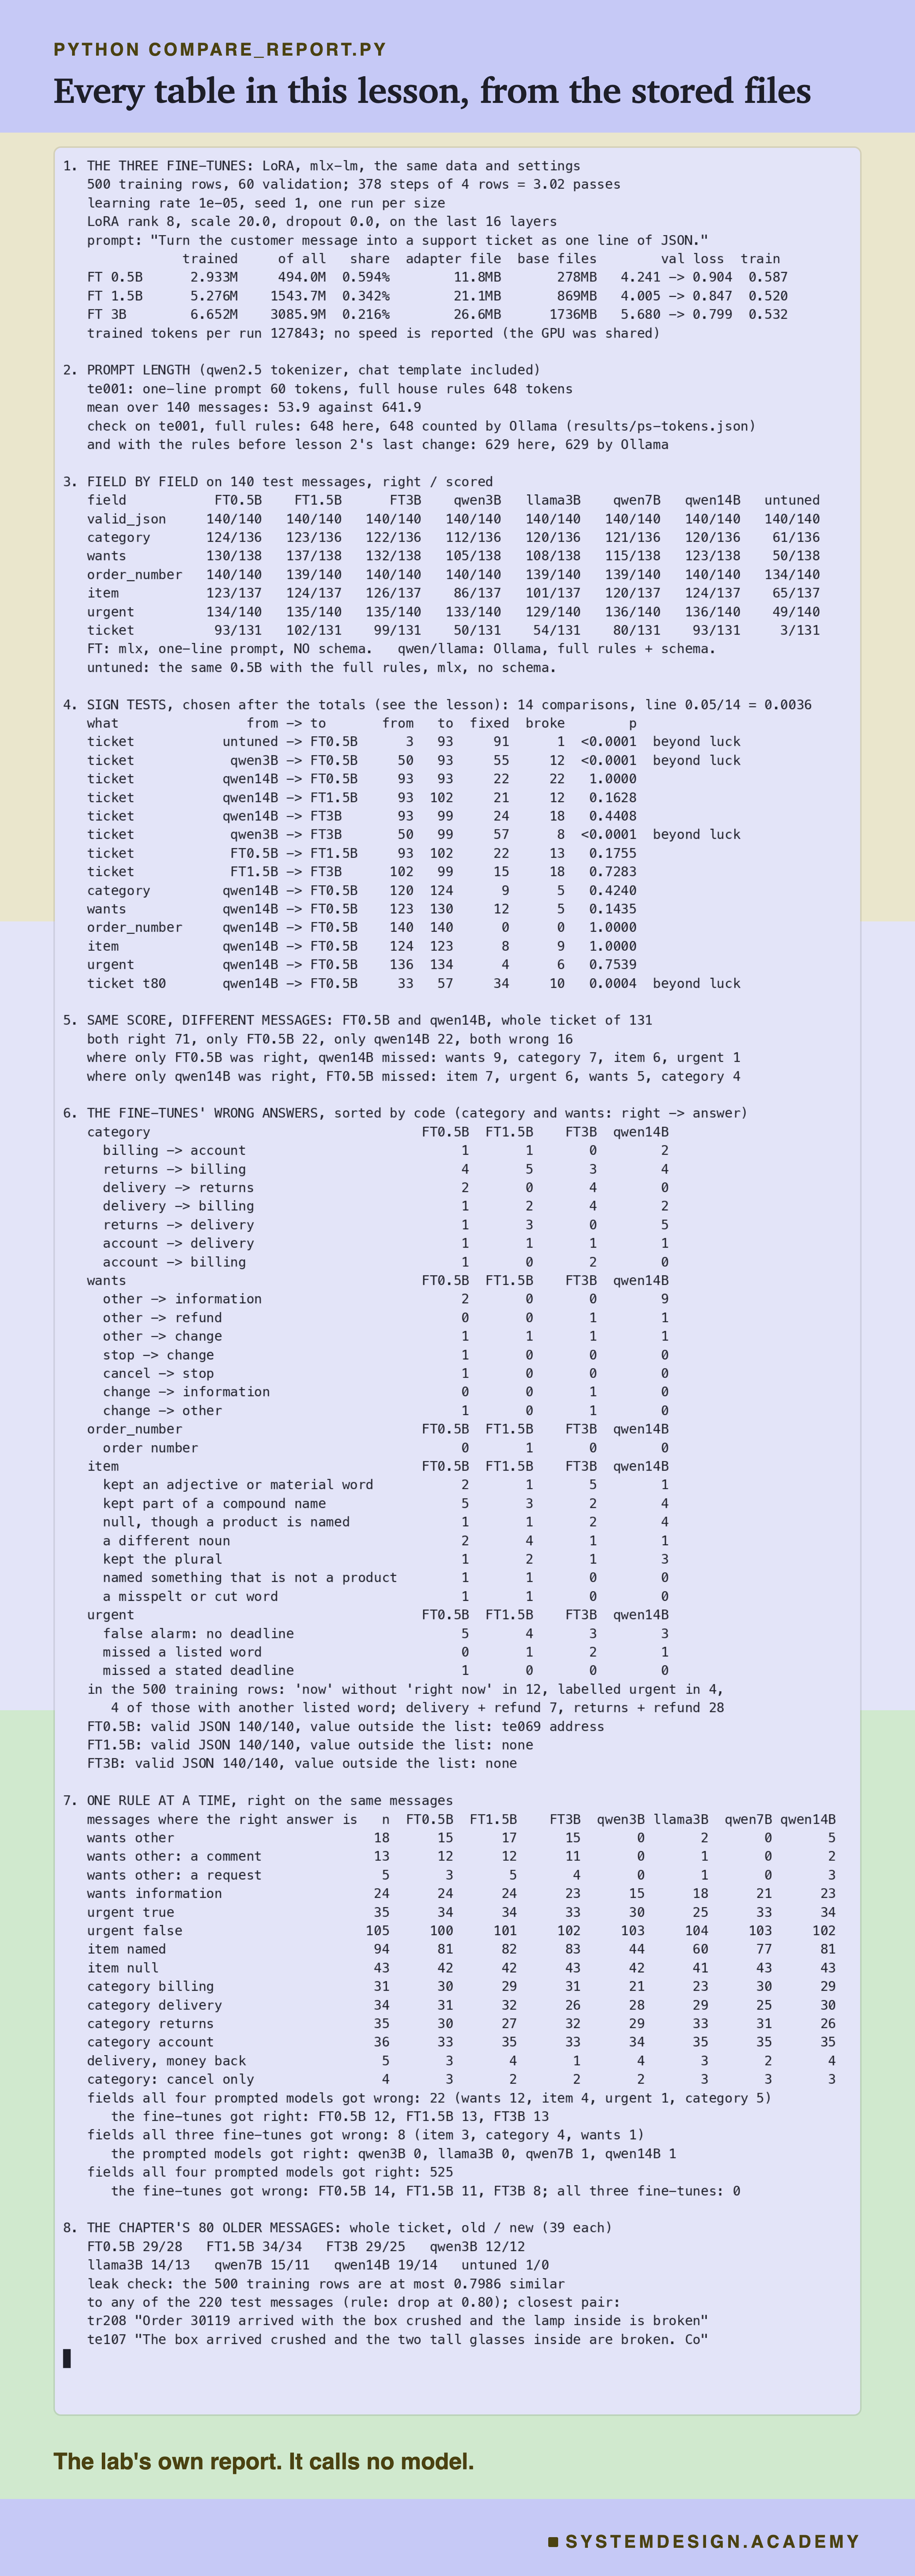
The report lives in scripts/labs/finetune/compare_report.py. It reads only stored files: the three training records (the exact command, every loss line and the end of the training output), the adapter settings and files, the stored replies of the three fine-tunes, the four prompted models and the untuned 0.5B, the test messages, and the gold files. A json mode writes the same numbers to results/tr-report.json, which is what the figures read.
Before it prints anything, it checks the files against each other and stops if one disagrees. It grades every stored reply again with the lab's own grader against the current gold, and stops if any stored mark differs. It checks the replies are in the order of the test messages, that the fine-tunes' results say they read the one-line prompt and the prompted ones the full rules, and that each training record matches its adapter settings.
Three modes do more than read results. The params mode counts the trained and total weights from the headers of the model files, without loading any weights; it exists because the stored training output kept only its last lines, and the count mlx-lm prints comes first. The tokens mode loads only the qwen2.5 tokenizer, no model, and counts the prompt tokens for all 140 messages. The demo mode checks the student script. A box mode writes the playground on the next slide.
What came after I saw the data: the 14 sign tests were chosen after the totals and after one message-by-message split was already known, as the luck slide explains, and the 80-message test after its totals. The split of "other" into comments and requests, and of item into adjectives and compound names, uses lesson 3's lists and was made after an independent review of this lesson. The two new item kinds ("a misspelt or cut word" and "dropped a word the gold keeps"), the "lost parcel, money back" count, the training-data counts for "now" and for refunds, the demo message and every example in the figures were chosen after I read the replies. The training data, the settings and the prompts were fixed before any fine-tune ran, in the batch plan.
Pick a Message and Compare Four Tickets
This box has no model in it. It holds all 140 test messages, the gold ticket for each, and the tickets written by the three fine-tunes (ft05, ft15, ft3) and by the prompted qwen2.5:14b (p14), taken from the stored replies with the lab's own clean-up (text fields in lower case). A gold value of '?' means the annotators disagreed on that field, so it is not scored. An x marks a field that does not match the gold.
As it is, the box shows two messages and then the split. The first, te095, is a customer telling us the invoice shows an old company name and saying "No need to change it": all three fine-tunes answered wants "change" and the 14B "information", where the right answer is "other". The second, te114, the thank-you to the driver, is right in every field for all three fine-tunes, and the 14B answered wants "information". Then split() lists the 22 tickets right only in the fine-tuned 0.5B and the 22 right only in the 14B.
Try wrong('item', 'ft05') to read every item the 0.5B got wrong, and wrong('wants', 'p14') to see how many of the 14B's wants misses have the right answer other. Try split('ft15', 'ft3') to compare the two larger fine-tunes, and find('refund') followed by show() on a message it prints.
The Code, Part by Part
The data.TRAIN holds 60 real training rows and VALID 8 validation rows, each as a pair: the customer's message and the ticket we want, as a line of JSON. TEST_ID, TEST_MESSAGE and TEST_GOLD are one of the 140 test messages, never trained on, and its gold ticket.
Writing the files. mlx-lm reads training data from a folder with a train.jsonl and a valid.jsonl file, one example per line. write() turns each pair into the three-part chat the model learns from: the one-line prompt as the system message, the customer's message as the user message, and the ticket as the assistant's answer.
The training call.subprocess.run runs mlx-lm's trainer as its own program, exactly as the lab did. Each argument has a comment. --model is the base model, whose weights stay frozen. --train asks for a new adapter; LoRA's rank of 8 and scale of 20 are mlx-lm's defaults, the same as the lab. The scale is a multiplier on the add-on's correction before it is added to the frozen weights, so the correction can matter while the add-on's own numbers stay small. --iters is the number of steps and --batch-size the number of examples per step, so 30 steps of 4 read 120 examples, the 60 twice. --learning-rate is the size of each nudge. --num-layers 16 puts the add-on on the last 16 of the model's 24 layers. --adapter-path is where the add-on is saved. The two --steps-per arguments decide how often the training and validation loss are printed, and --seed fixes the shuffle.
The prediction.load(MODEL, adapter_path=...) loads the frozen base model and puts the trained add-on on top. The chat template turns the prompt and message into the exact text format the model was trained on, and generate writes up to 80 tokens, always taking the most likely next one. The last loop compares each field with the gold ticket and prints ok or WRONG.
To use it on your own task, replace the rows with your own examples and answers, and the prompt with your own one line. Start with 30 steps to check that everything runs, then train on all your examples and score the result on a test set you kept apart.
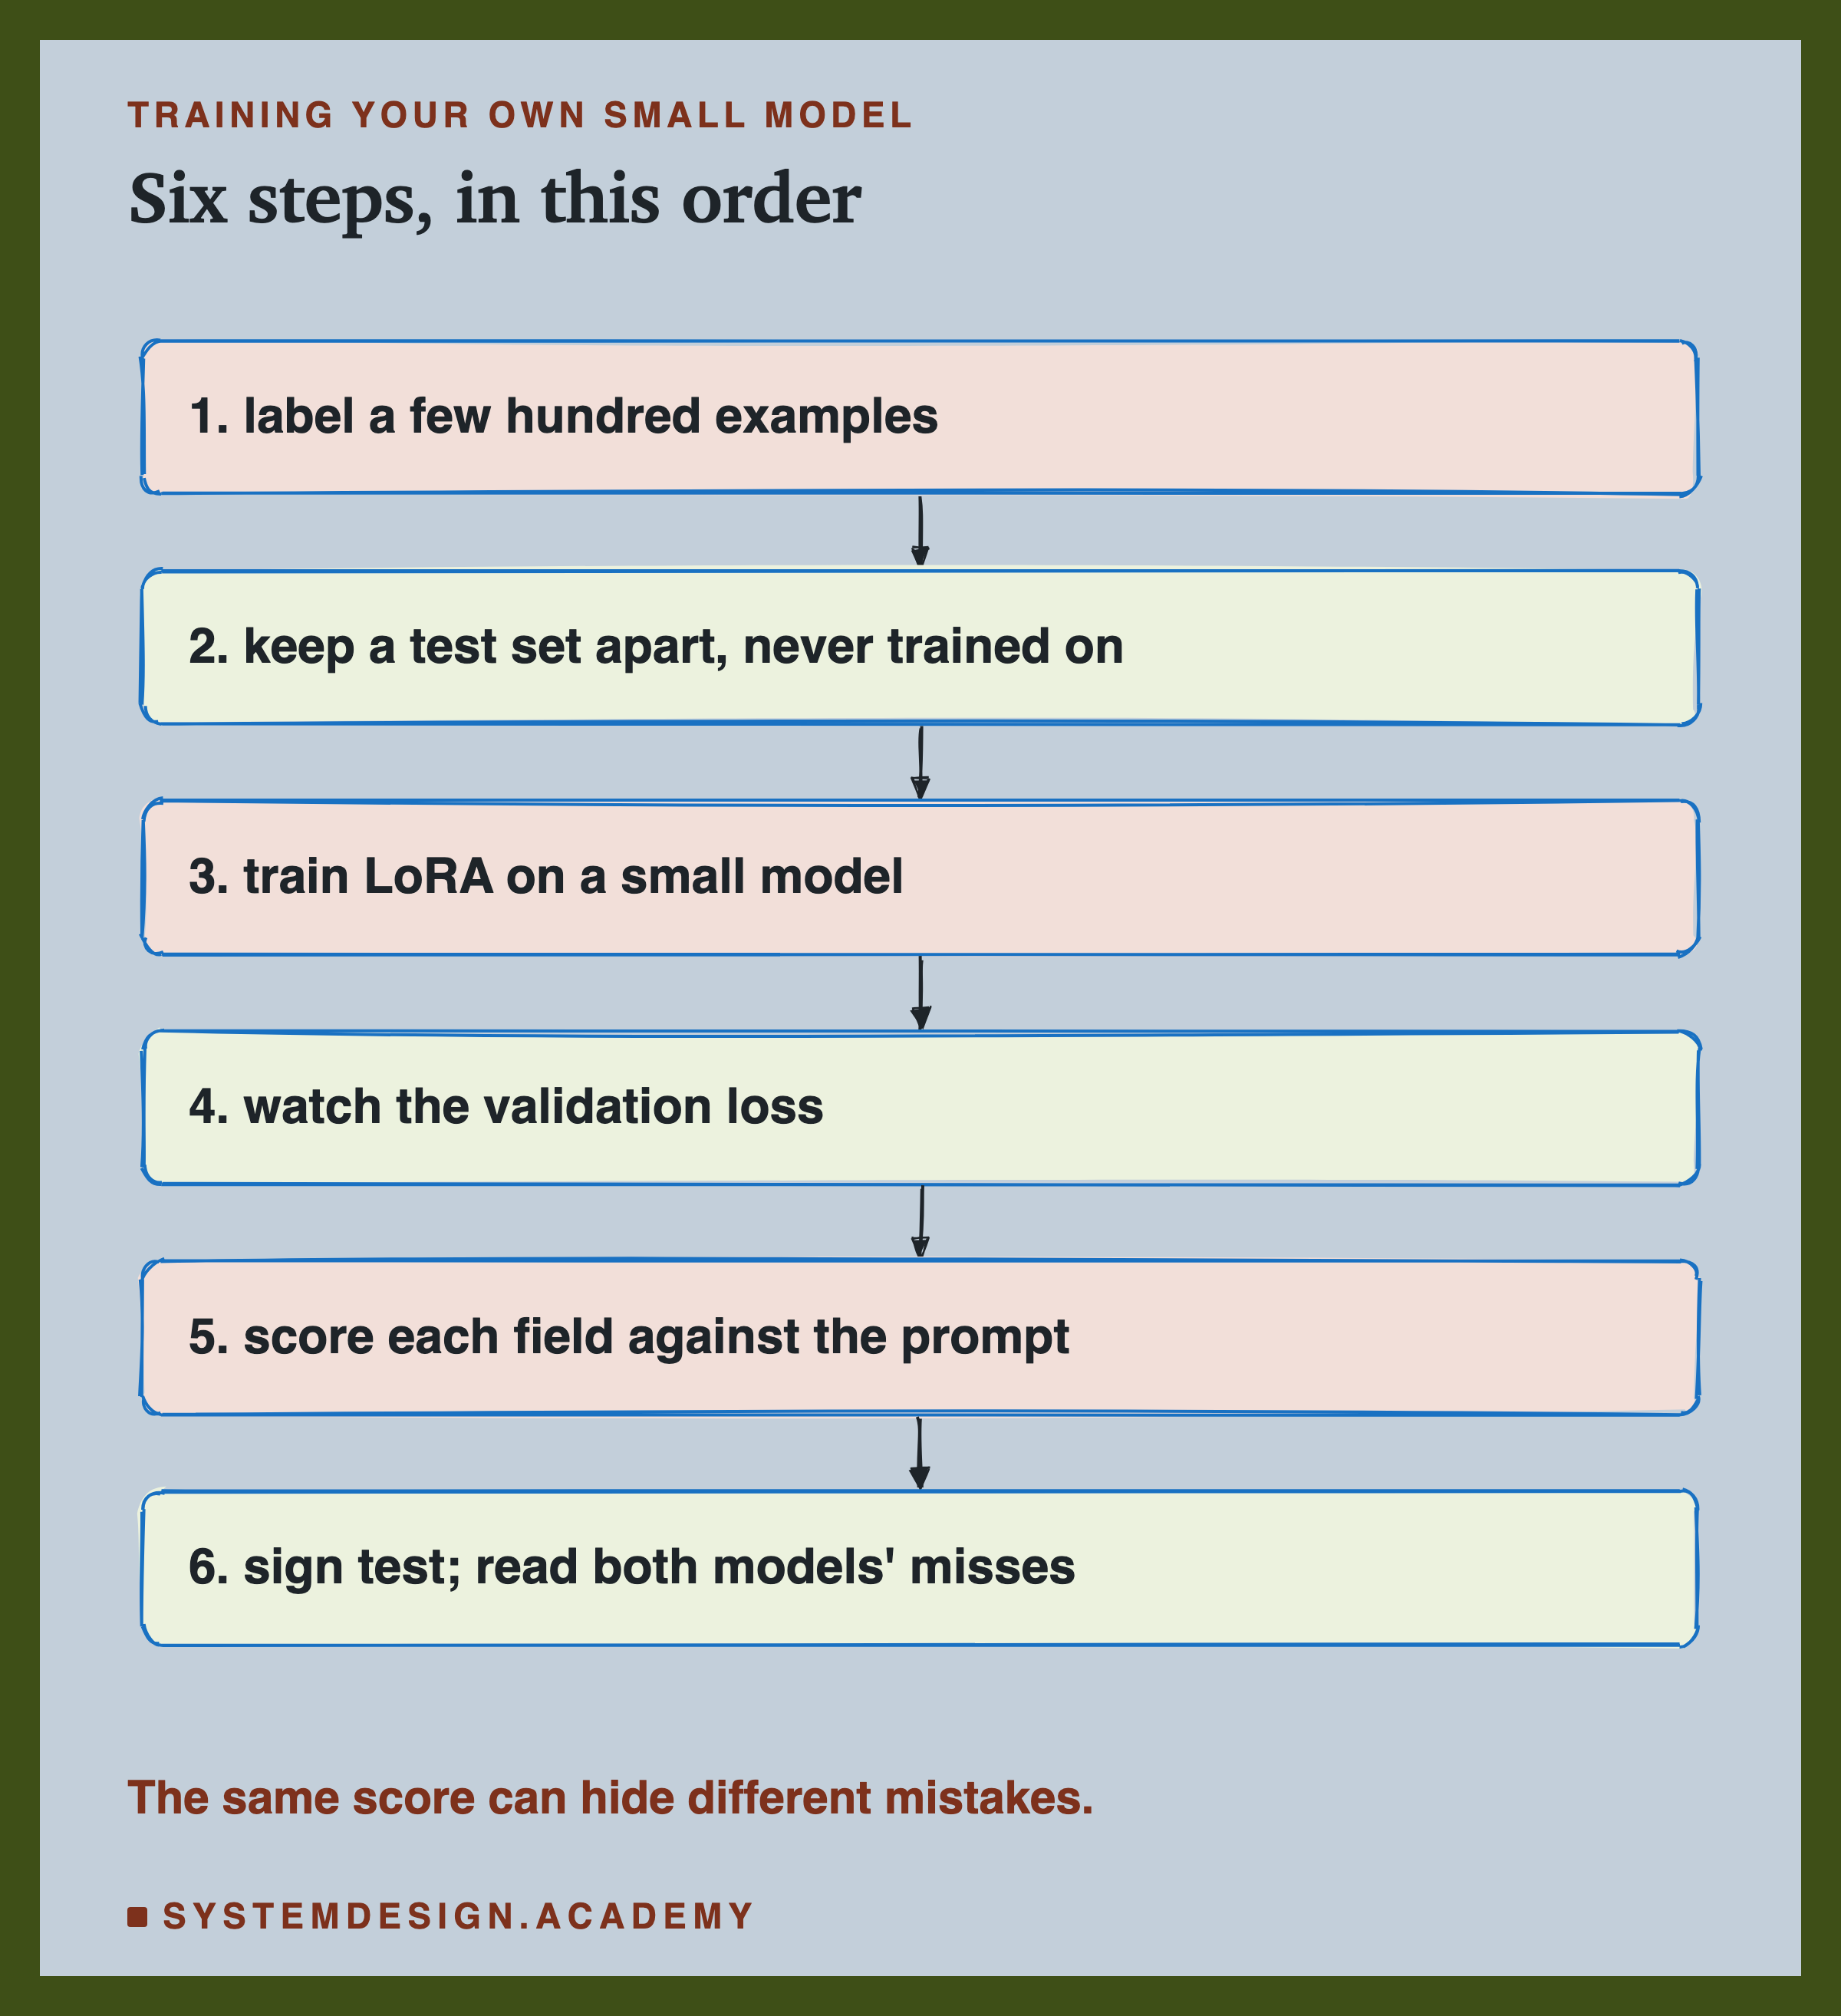
How to Train a Small Model for a Narrow Task
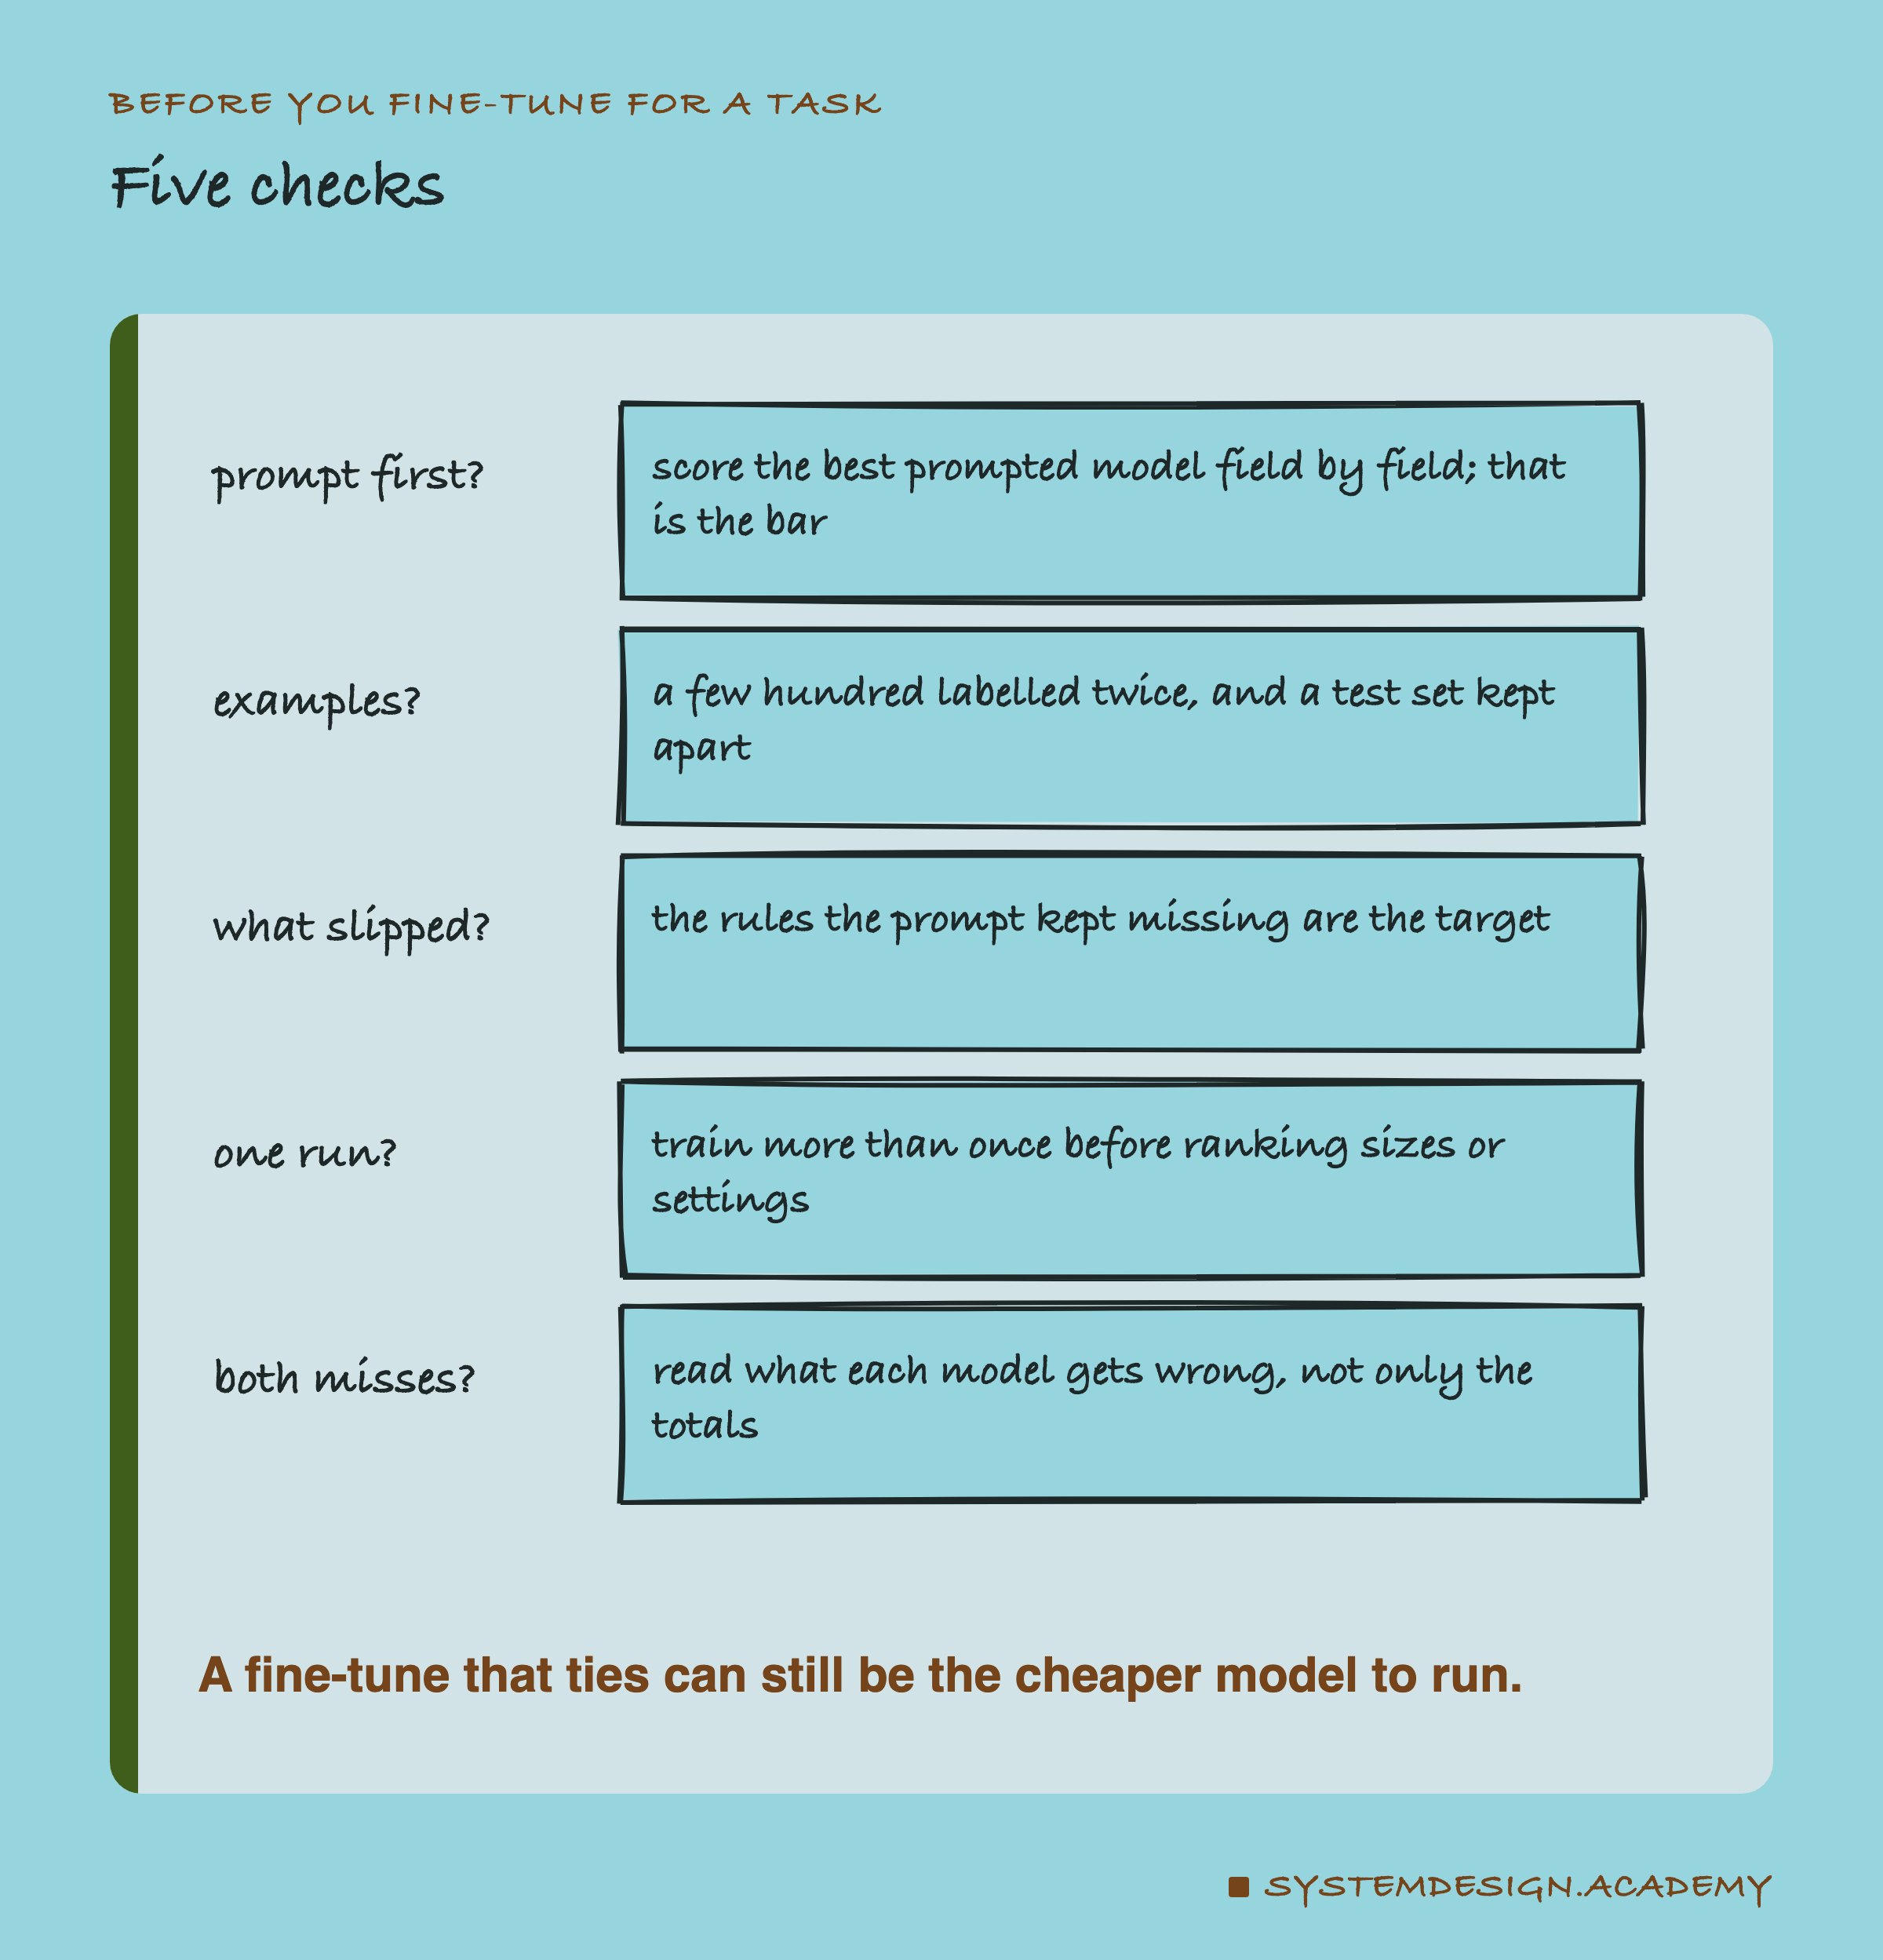
Label a few hundred examples, carefully. Everything the model learns comes from them, including their mistakes. Lesson 2 showed how: rules first, two labellers, and a record of every change. Here, 500 examples were enough for a 0.5B model to get the "other" comments right, where the one prompt I tried did not.
Keep a test set apart. Write it separately if you can, never train on it, and check that no training example is a near copy of a test one.
Train a small add-on on a small model. trains under 1% of the weights and leaves a file of a few megabytes, so trying it is cheap. Start with the smallest model that might work; here a 0.5B tied a prompted 14B.
Watch the validation loss, but do not judge by it. It tells you the training is working and warns you when the model starts to learn only its training examples. It does not tell you which rules it learned.
Score each field against your best prompt. Use the same test messages, the same gold and the same grader, and check every field, not only the total.
Sign test, then read both models' misses. A difference of a few tickets can easily be luck. Even a tie hides two different sets of mistakes, and which set you can live with is a decision for your team, not for the total.
When a Small Fine-Tune Is Worth It, and When It Is Not
It is worth it when a rule goes against a model's habits. The "other" rule was written plainly in the prompt, and four prompted models from 3B to 14B still missed it nearly every time. A 0.5B model trained on examples got 11 or 12 of the 13 comments right. If your prompted model keeps breaking one rule, and rewording the rule and adding examples to the prompt have not fixed it (I did not test either here), that is the case for training.
It is worth it when the prompt is long and the calls are many. Every prompted call here carried about 642 tokens; the fine-tune needed about 54. How much that saves I did not measure: a runtime that caches the repeated part of a prompt would cut the cost of the long rules, and I give no speeds, because the GPU was shared. What is certain is the size: a 0.5B model needs far less memory to run than a 14B one.
It is worth it when you want a small model you control. The adapter is a 12 MB file on top of a model you already have, and it runs on a laptop.
It is not worth it when a prompt already does the job. The order number was right on nearly every message whatever I did. If your fields are mechanical like that, a prompt with a schema is simpler and needs no training data.
It is not worth it without good labelled examples. The fine-tunes copied the habits of their data, including the unclear ones: "now" treated as urgent, lost-parcel refunds sent to returns. Five hundred careless examples would teach five hundred careless habits.
It is not a way to add facts. The model learned how this team writes a ticket, not new knowledge about the world. A later lesson tests that directly.
What These Numbers Can and Cannot Tell You
One training run per size. Each model was trained once, with seed 1. A different seed would shuffle the examples differently and could move the scores; by how much is measured in the next lesson. So the 3B scoring 99 against the 1.5B's 102 is not a finding about size, and the sign test agrees. A later lesson measures how much a score moves from one run to the next.
Not like for like. The fine-tunes ran in mlx with no schema and a one-line prompt; the prompted models ran in Ollama with a schema and the full rules. The comparison is between two complete recipes, not between two things that differ in one way only.
4-bit models on one Mac. Every model was a 4-bit version, trained and run on an Apple M4 with mlx 0.32.2 and mlx-lm 0.31.3. Full-precision models, other hardware or on a GPU could behave differently, and I make no claim that the numbers carry over.
Written and labelled with an AI model's help. The training messages, the test messages and all their labels were produced with an AI model, as lesson 2 explained. Real customers write differently, and people would label some fields differently.
The test labels changed once. Lesson 2 relabelled the category after prompted models had first been scored. The prompted numbers here are from reruns with the current rules, scored against the current labels, and the fine-tunes were trained after the change, so every number in this lesson uses the same labels.
131 fully gold messages, and accuracy only. One message is under 1% of the whole-ticket score. I measured whether the tickets were right, not how fast any model produced them.
What to Do Next
If you have a prompted model filling in fields from text, you can try this lesson's method this week. First score your best prompt field by field, as lesson 3 did; that is the bar a fine-tune has to clear. Then take a few hundred labelled examples, keep a test set apart, and run the demo script with your own rows, first for 30 steps to check it runs and then on everything. Score the fine-tune on the same test set, run a sign test, and then do the part that matters most: put the two models' wrong answers side by side and read them.
The next lesson is planned to ask how much of this result is luck: it trains the same 0.5B model several times with different seeds, to measure how far a score moves from one run to the next, before any lesson compares settings.
Knowledge Check
Knowledge Check
4 questions - Score 80% to pass
Q1
The fine-tuned 0.5B and the prompted qwen2.5:14b both got 93 of 131 whole tickets right. What does the message-by-message comparison add?
Q2
With LoRA on the 0.5B model, 2.933 million of 494.0 million weights were trained. What happens to the other weights?
Q3
The fine-tuned 3B got 99 whole tickets right and the fine-tuned 1.5B got 102. What is the honest reading?
Q4
On the 13 messages that only comment, thank or complain and ask for nothing (right answer: wants 'other'), the prompted models got 0 to 2 right and the fine-tunes 11 or 12. What is the most careful reading?