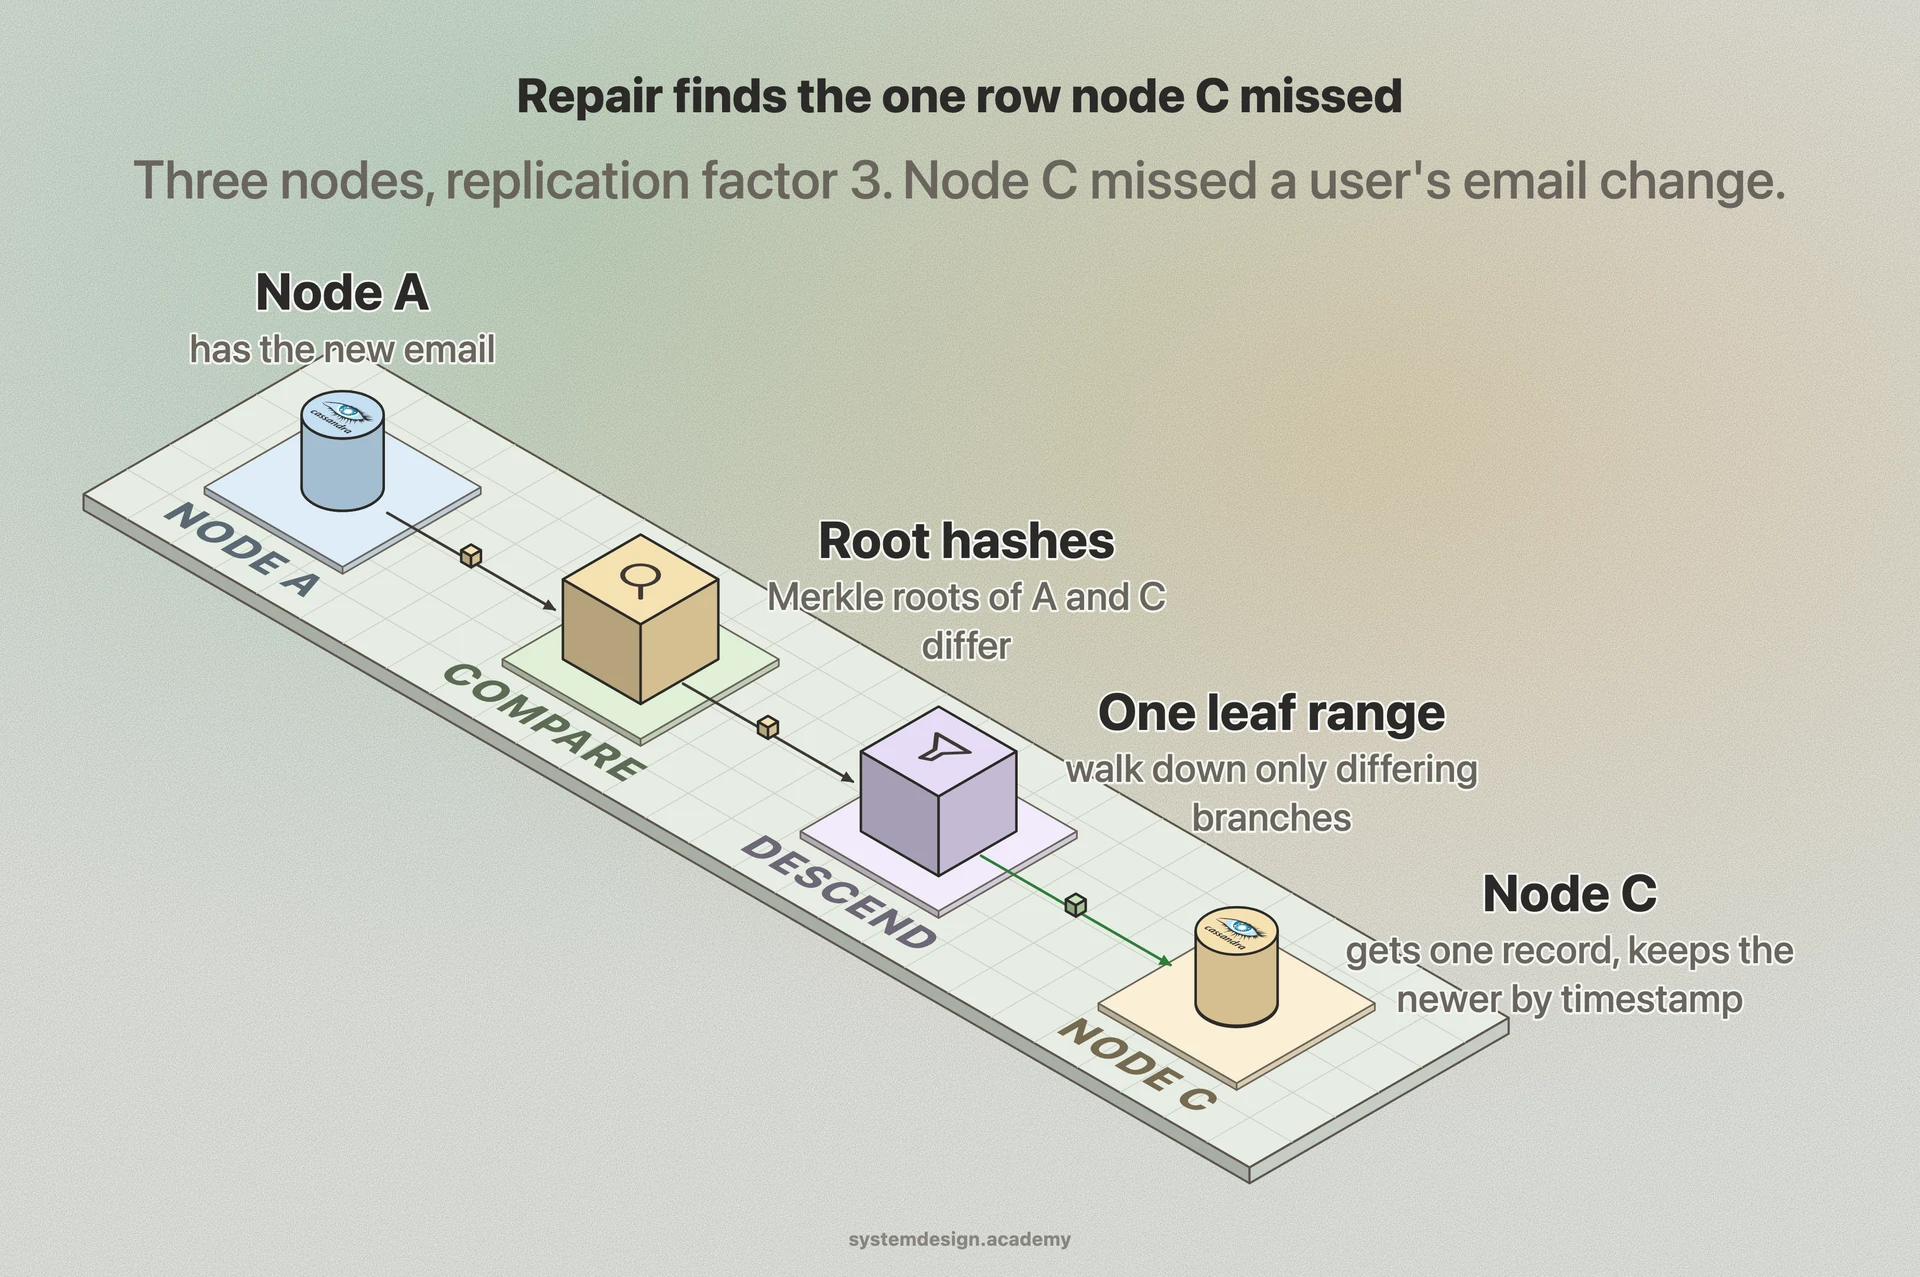
The naive approach is to ship every key and value from one replica to another and diff them. For a node holding hundreds of gigabytes that is far too much network traffic to run often. Merkle trees solve this.
Each replica hashes its keys in a range, then hashes those hashes upward into a tree where every parent node is the hash of its children, ending in one root hash. Two replicas first compare just the root. If the roots match, the entire range is identical and nothing needs to move. If they differ, they walk down the tree comparing child hashes, descending only into the branches that disagree. This turns a full data scan into a logarithmic search, so two terabytes of mostly-identical data can be reconciled by exchanging a few kilobytes of hashes plus only the records that genuinely differ.
Once the differing leaf ranges are found, the replicas exchange the actual rows for just those keys and resolve conflicts using whatever rule the database has, such as last-write-wins by timestamp or version vectors. The repaired data is then written back so the next comparison finds the trees in agreement.