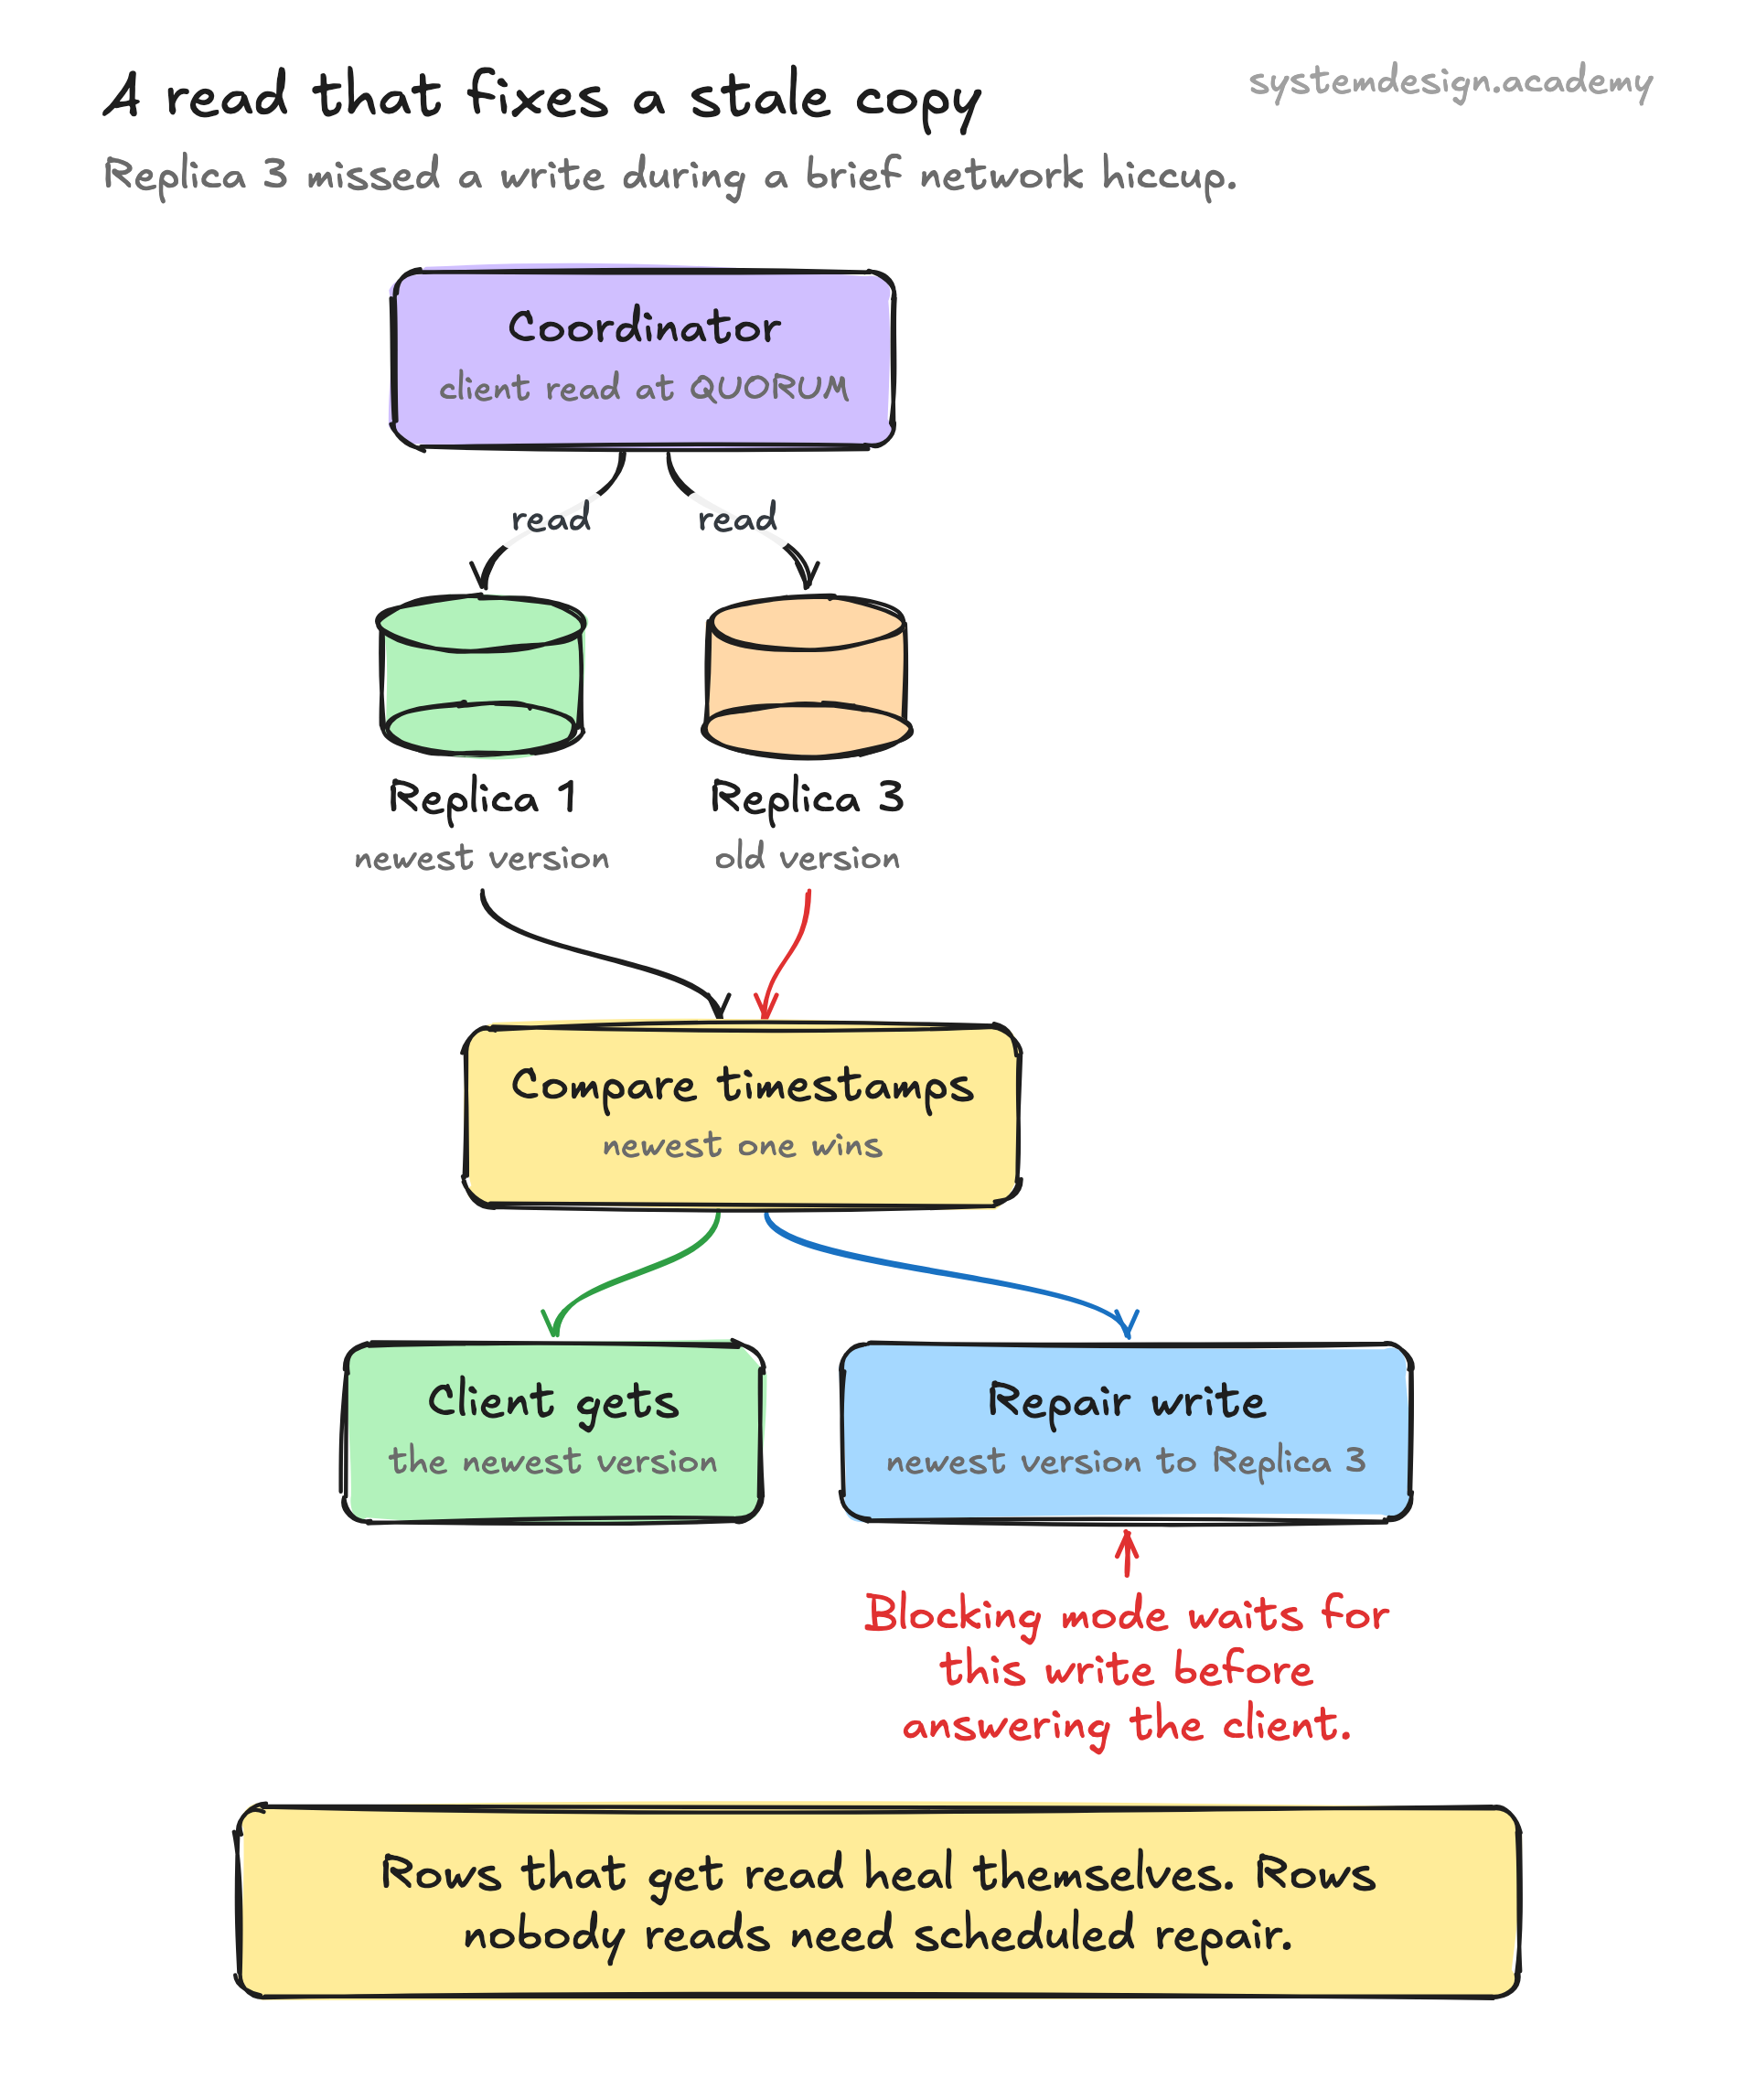
During a read, the coordinator sends the request to a set of replicas. Each replica responds with its data plus a version marker, usually a timestamp under last-write-wins. The coordinator picks the most recent version, returns it to the client, and notes which replicas were behind.
In blocking read repair, the coordinator writes the newest value to the stale replica and waits for that write to finish before answering the client. The repair is guaranteed to have happened, but the client pays one extra cross-replica hop on any read that finds a mismatch. In background read repair, the coordinator answers the client first and fires the repair write asynchronously, which is faster but can fail silently.
Because cell-level writes are idempotent under last-write-wins, repair is safe even when it overlaps with other recovery paths. If both a read repair and a hinted handoff replay try to fix the same node, whichever lands first wins and the second becomes a no-op because the write timestamp already matches.