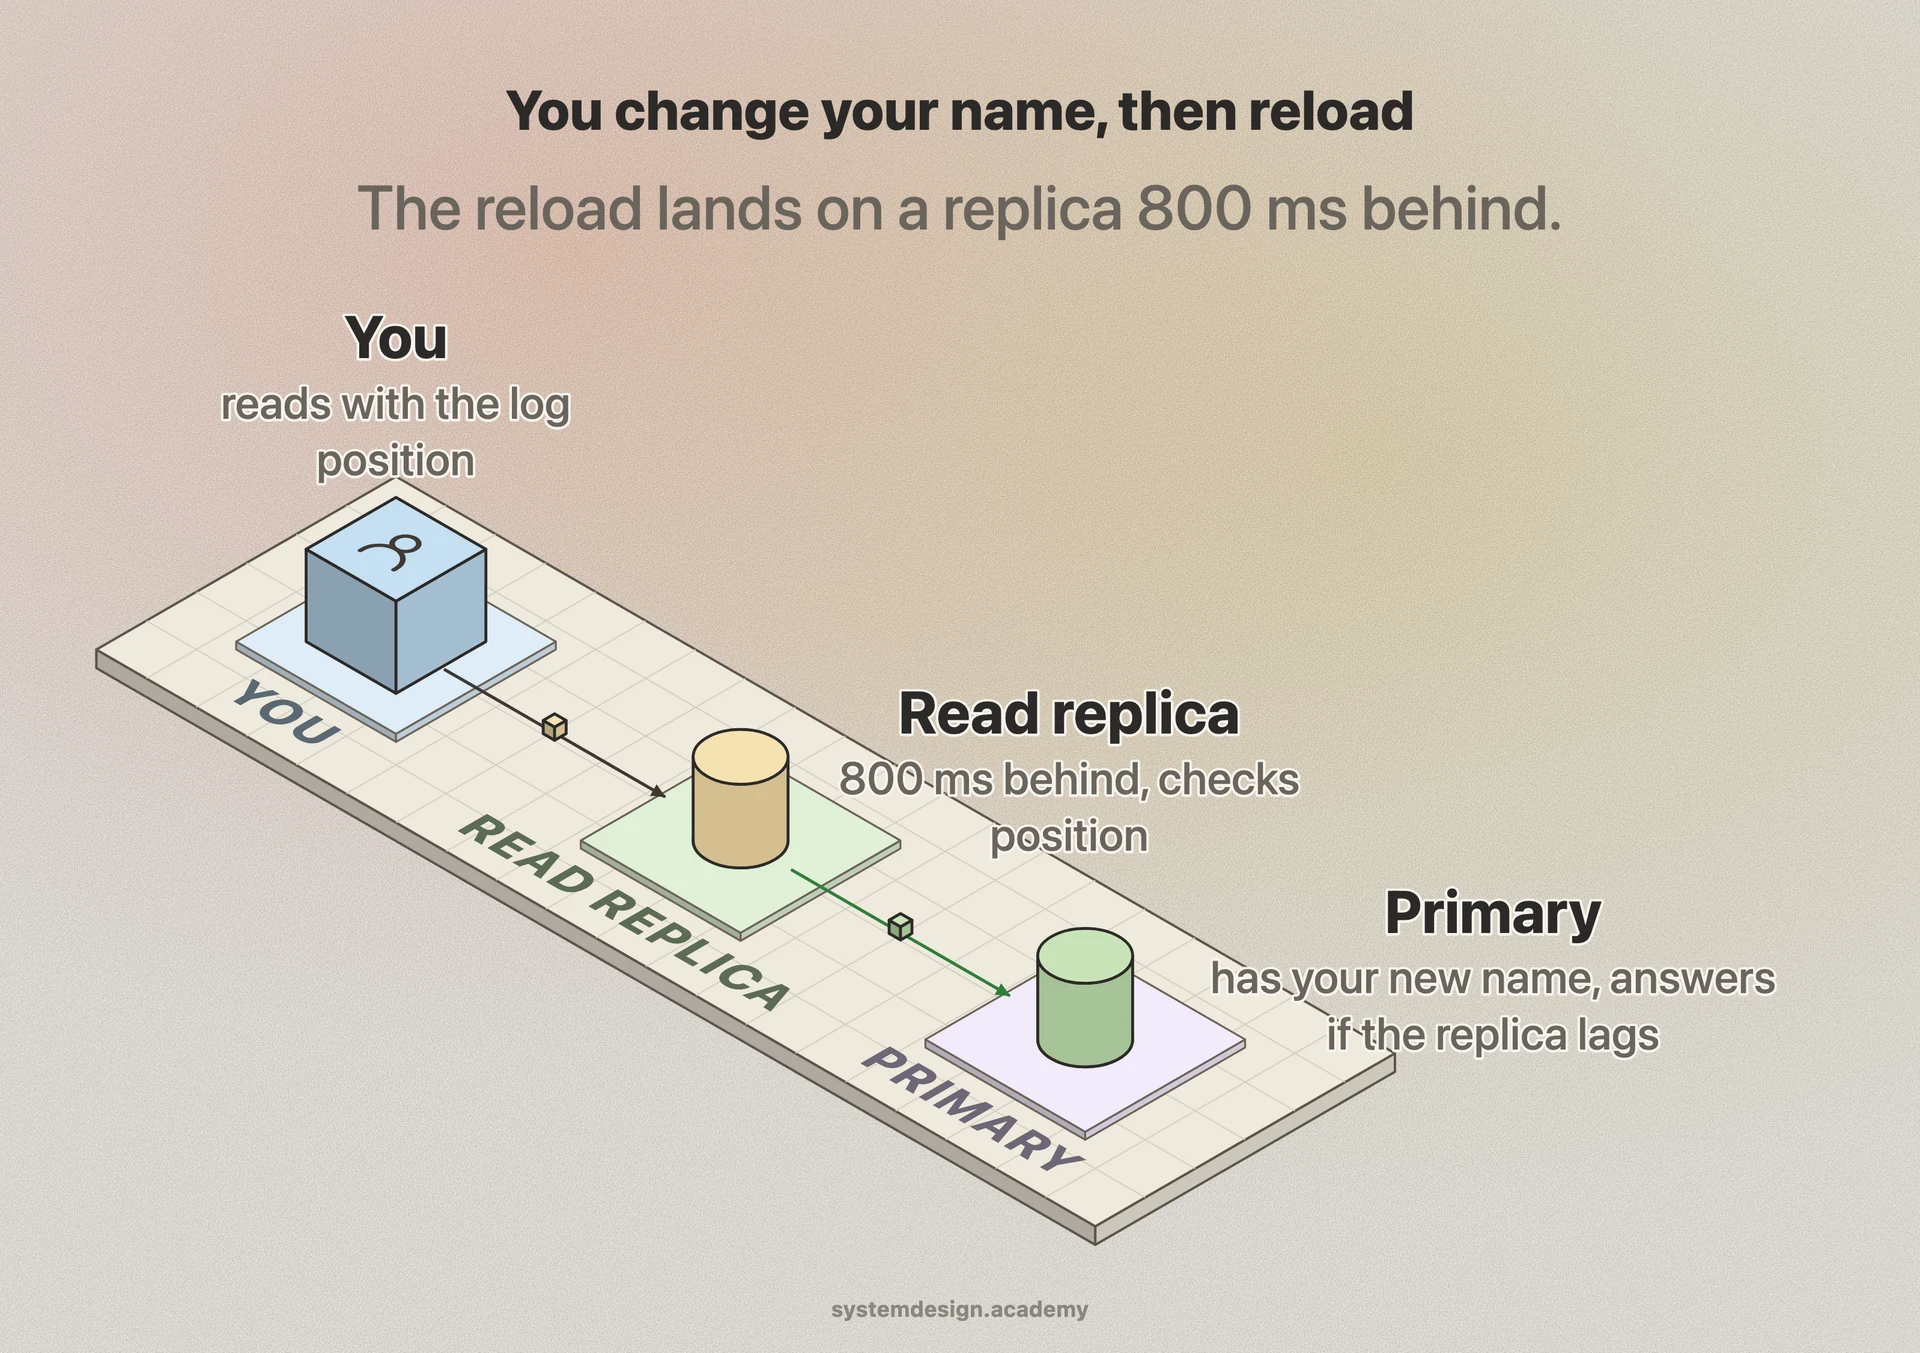
The hard case is a system with one primary that accepts writes and several read replicas that lag behind by anywhere from a few milliseconds to several seconds. A naive load balancer sends each read to whatever replica is closest or least busy, so a read right after a write often lands on a replica that has not caught up.
The simplest fix is sticky reads: route a user's reads to the same node, or to the primary, for a short window after they write. Many setups read from the primary for a few seconds following any write by that session, then fall back to replicas. This is cheap but concentrates load on the primary.
A more precise approach uses version tracking. When a client writes, the server returns a logical timestamp or log position, for example a PostgreSQL LSN (log sequence number) or a MySQL GTID (global transaction id). The client stores that marker and includes it on the next read. A replica only serves the read if it has applied changes up to that marker, otherwise it waits or the request is routed to a node that has. MySQL exposes this through GTID-based replica waits, and some drivers automate the whole loop.
A third option is to read from a quorum. If writes go to W replicas and reads consult R replicas out of N total, and you pick W plus R greater than N, every read overlaps at least one replica that holds the latest write. This is how Cassandra and DynamoDB-style systems can offer read-your-writes when you choose the right consistency level per request.