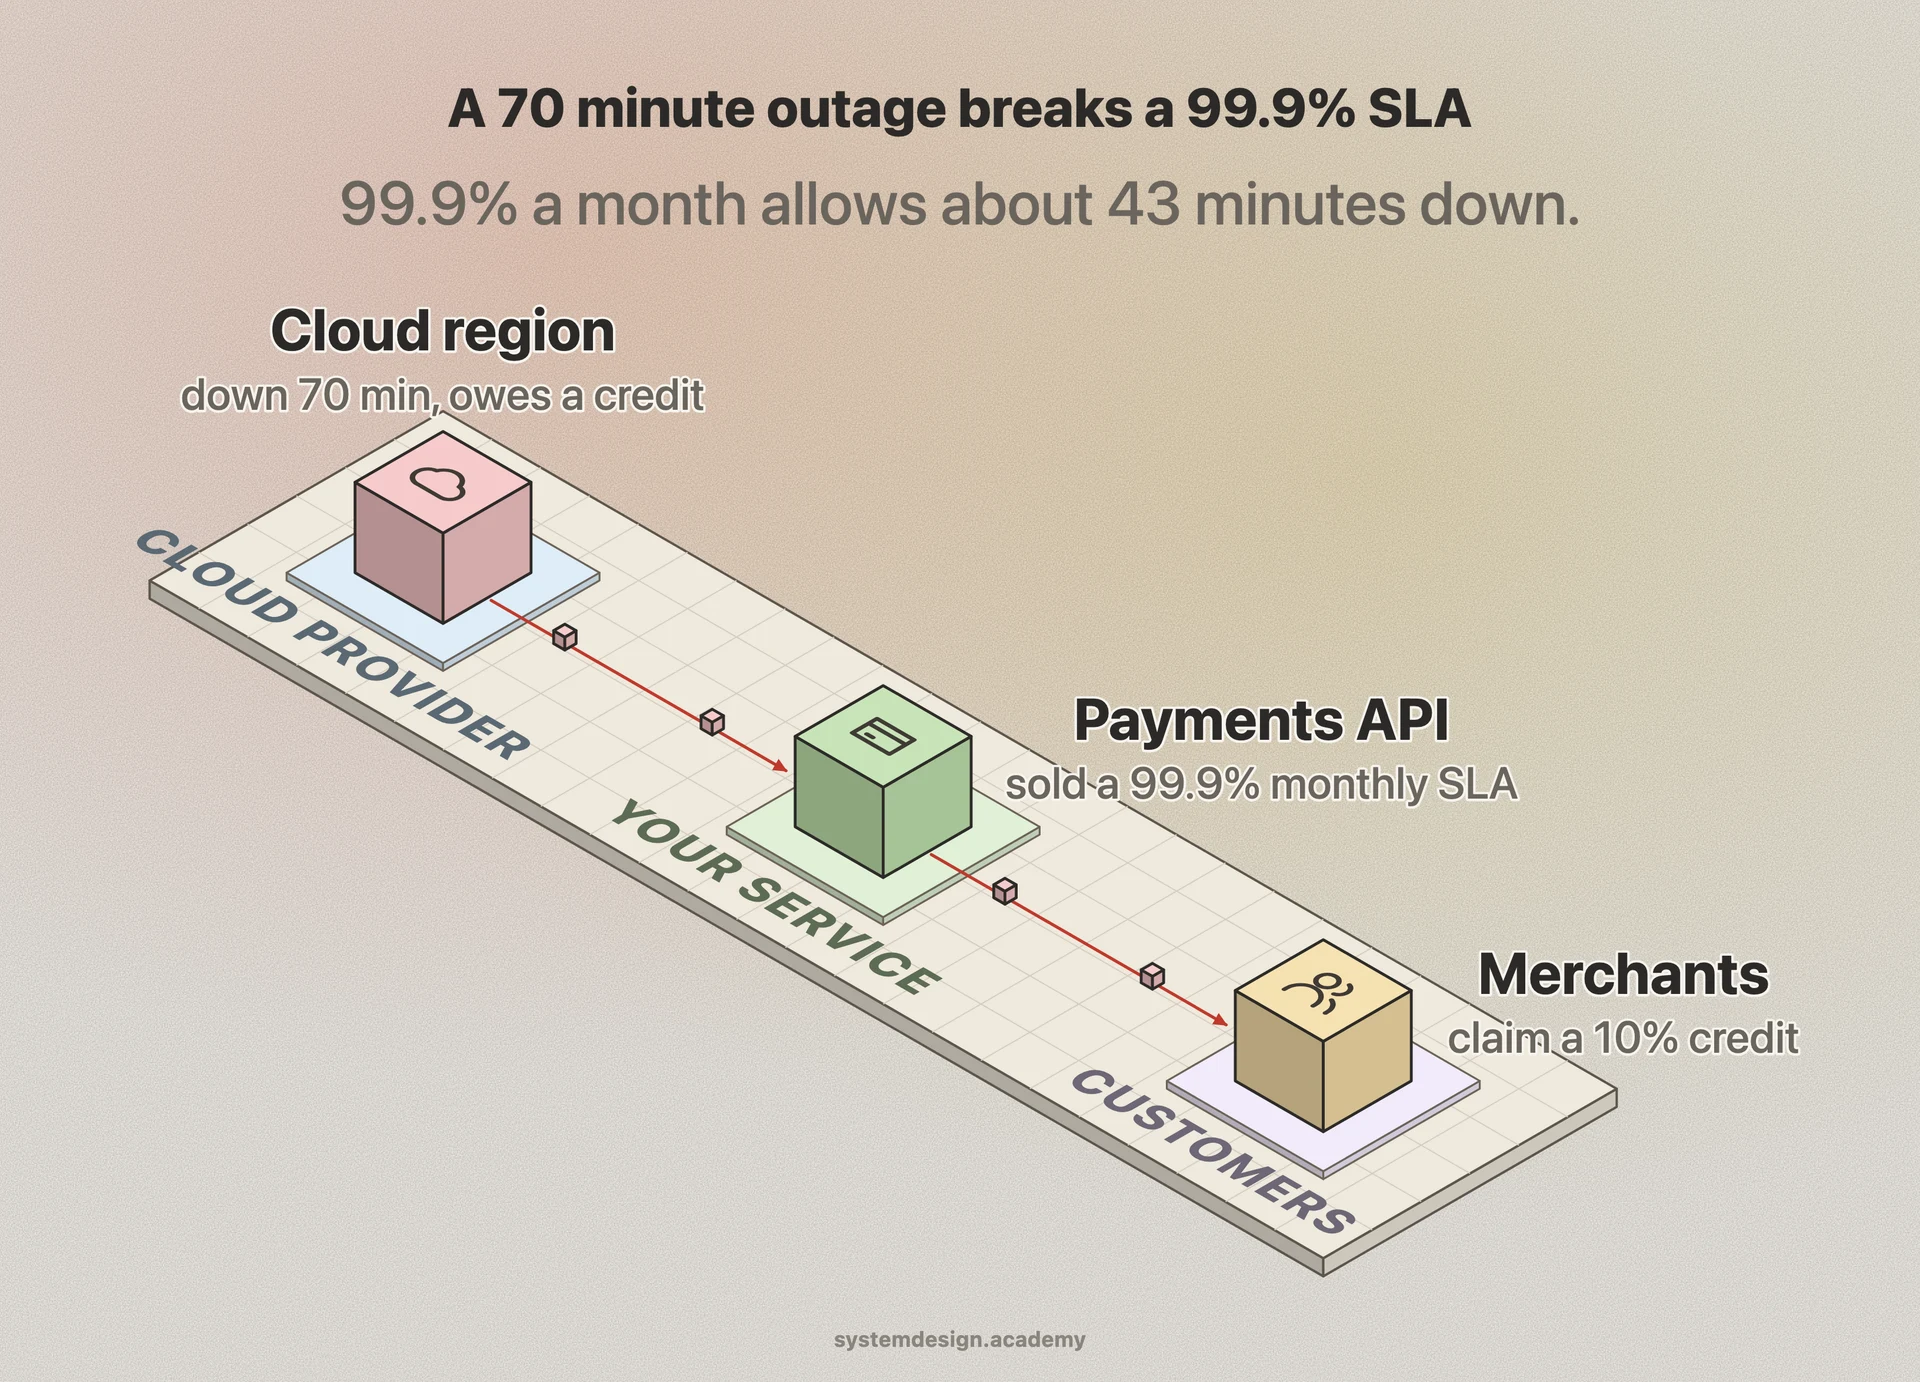
Every real SLA has three parts: the metric, the measurement window, and the remedy. The metric defines exactly what is being promised, for example uptime, p99 latency under 300 ms, or successful-request rate. The window is the period over which it is calculated, usually a calendar month. The remedy is what the customer collects when the target is missed.
The remedy is almost always a service credit, not cash and not damages for your lost revenue. Google Cloud's Compute Engine SLA is typical: drop below 99.99 percent monthly and you get a 10 percent credit, below 99 percent and you get 25 percent, below 95 percent and you get 100 percent. The credit caps out well below the actual cost of an outage to the customer, which is the point. The SLA limits the provider's liability as much as it reassures the buyer.
The fine print decides who really wins. SLAs exclude scheduled maintenance windows, force majeure events, problems caused by the customer's own misconfiguration, and anything outside the provider's network. They also put the burden of proof on the customer: you usually have to file a claim within 30 to 60 days with your own monitoring logs as evidence. Providers measure from their own vantage point, so an outage you experienced through a flaky region might not count if their global dashboard stayed green.