You pick a Service Level Indicator first, the raw measurement, such as the ratio of HTTP requests that return a non-5xx status, or the fraction of requests served faster than your latency threshold. You collect this from request logs, a load balancer, or a metrics system like Prometheus.
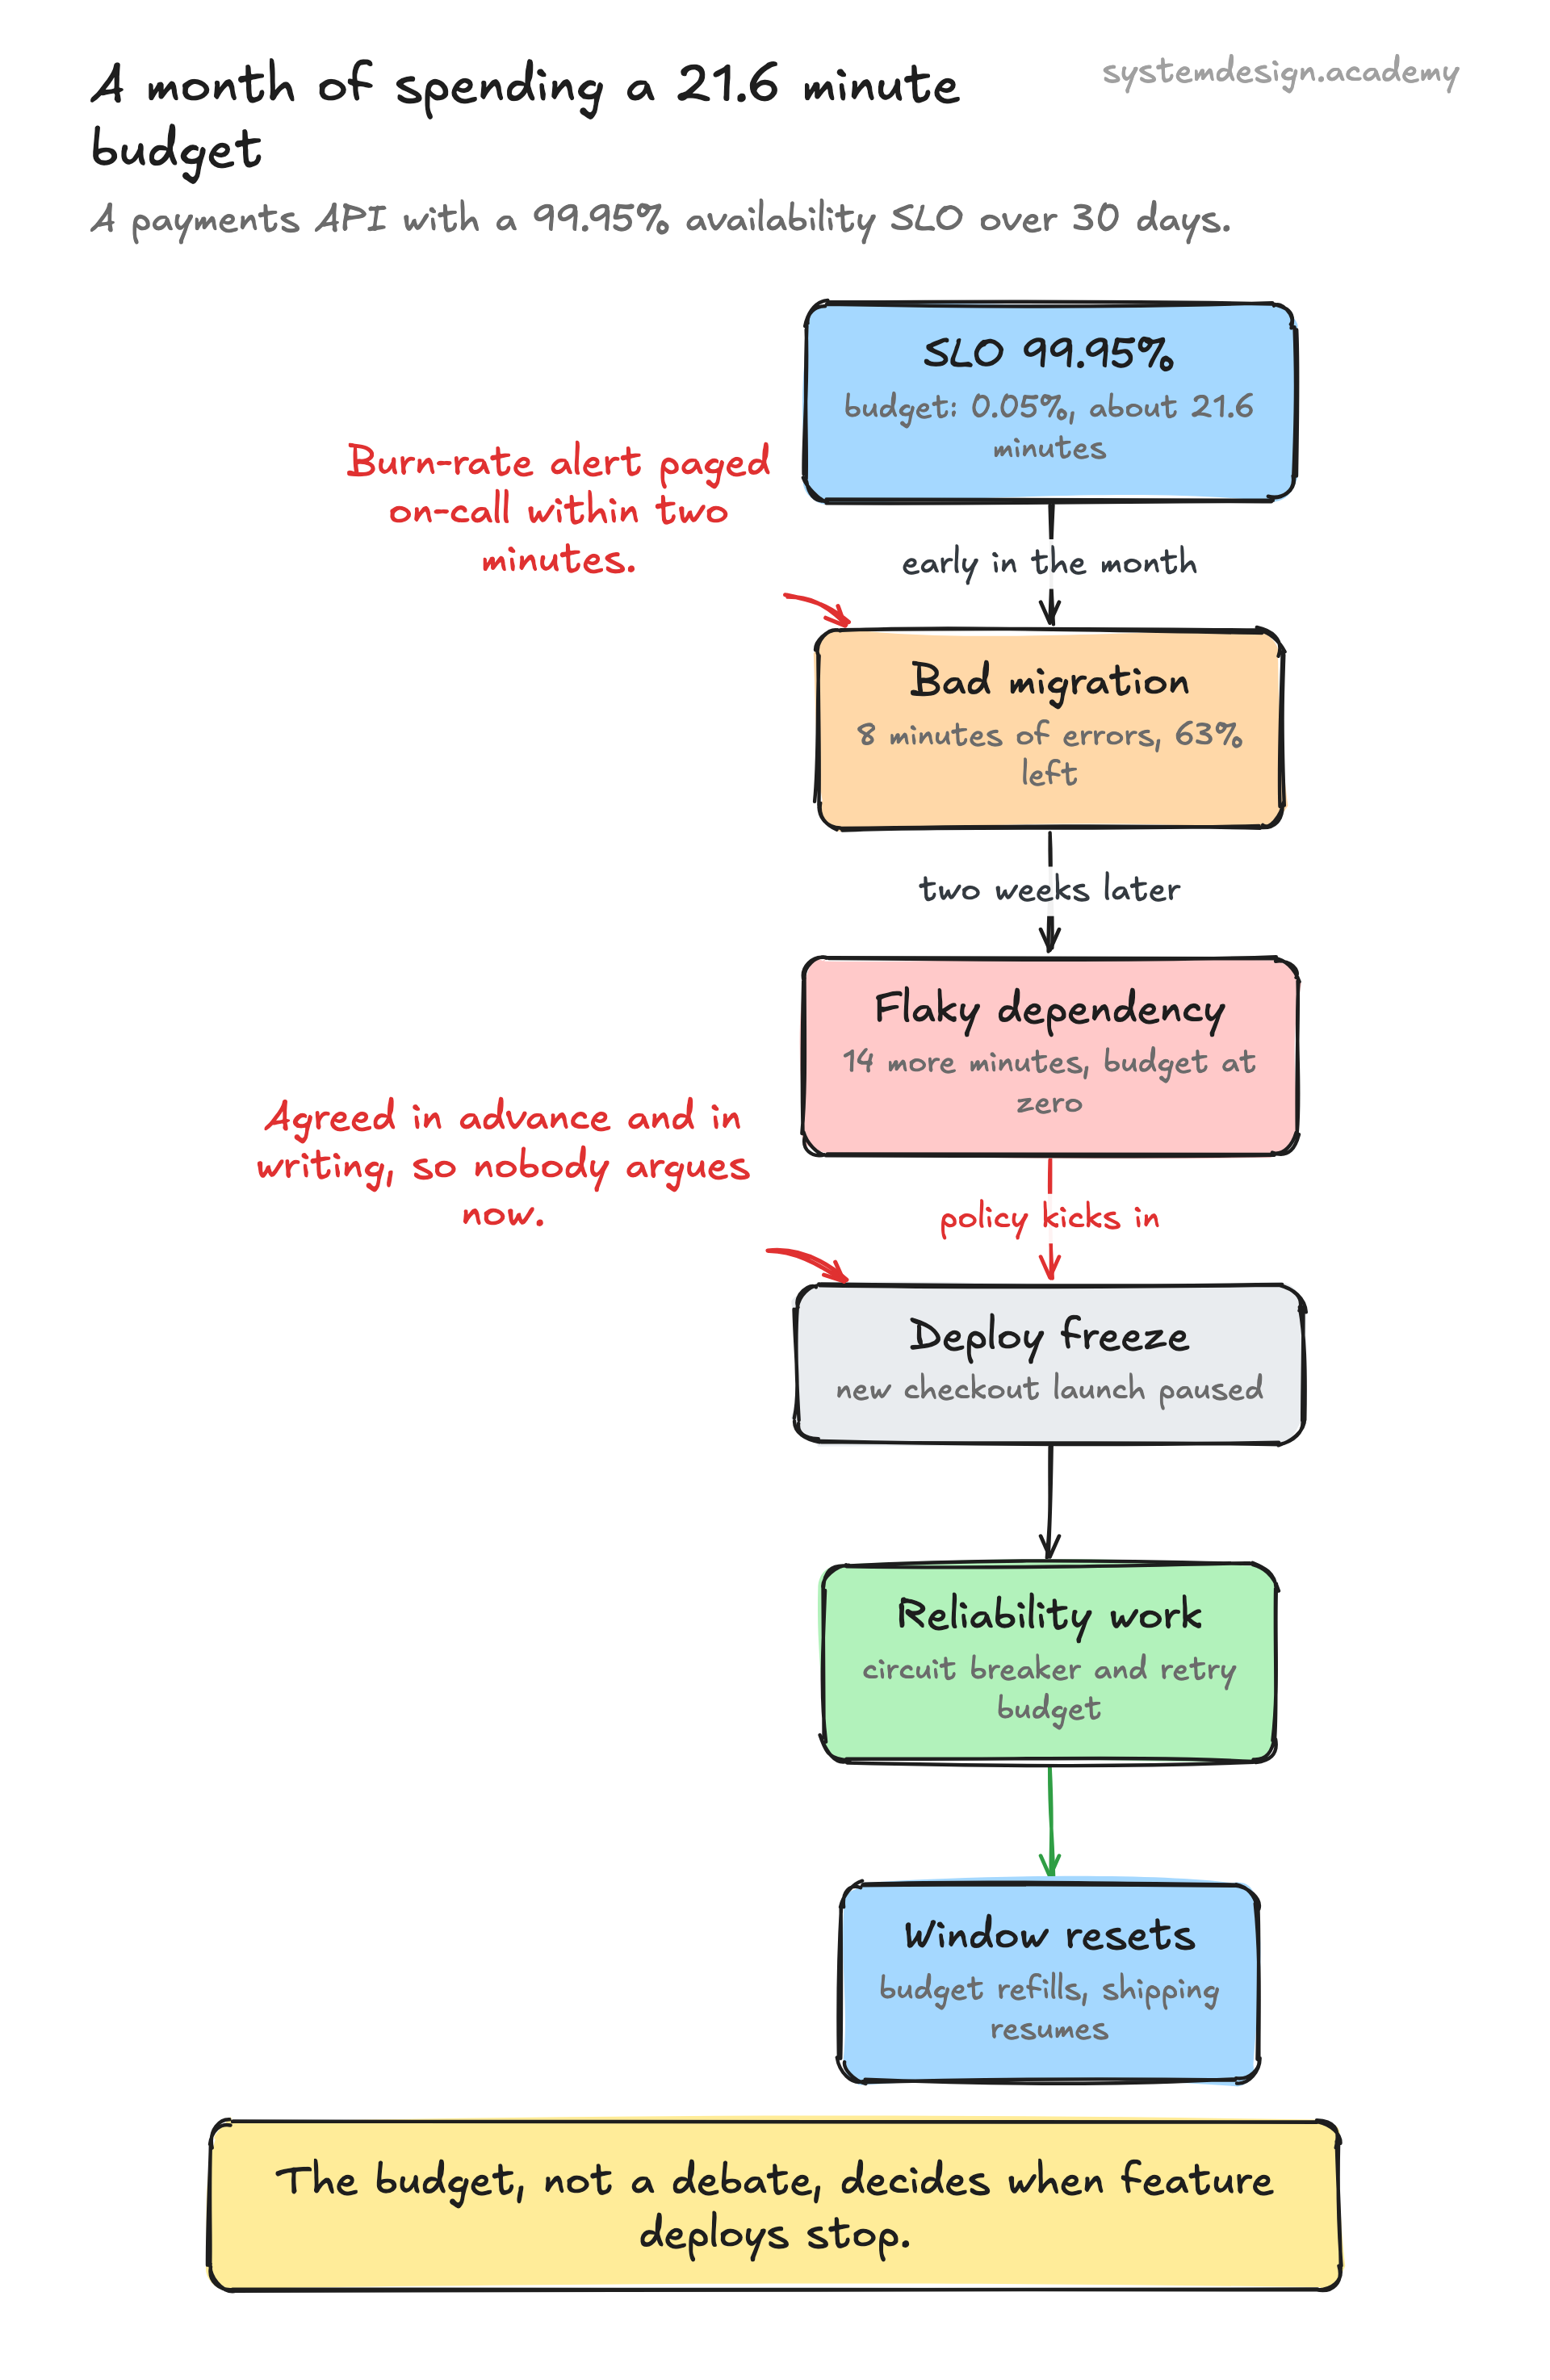
Over a rolling window, usually 28 or 30 days, you compare the SLI against the SLO. The gap between perfect and your target is the total budget. The gap between perfect and your actual performance is what you have spent. Budget remaining is the difference. A bad deploy that caused 15 minutes of 5xx errors burns 15 of your 43 minutes and the dashboard shows roughly 65% of the monthly budget still available.
Teams also watch burn rate, which is how fast the budget is being consumed relative to a steady spend. A burn rate of 1 means you will exactly exhaust the budget by the end of the window. A burn rate of 14 means a sudden incident is eating the budget 14 times faster than sustainable, and that triggers an urgent alert. Google's SRE practice popularized multi-window, multi-burn-rate alerting precisely so you page humans for fast burns and only ticket slow ones.