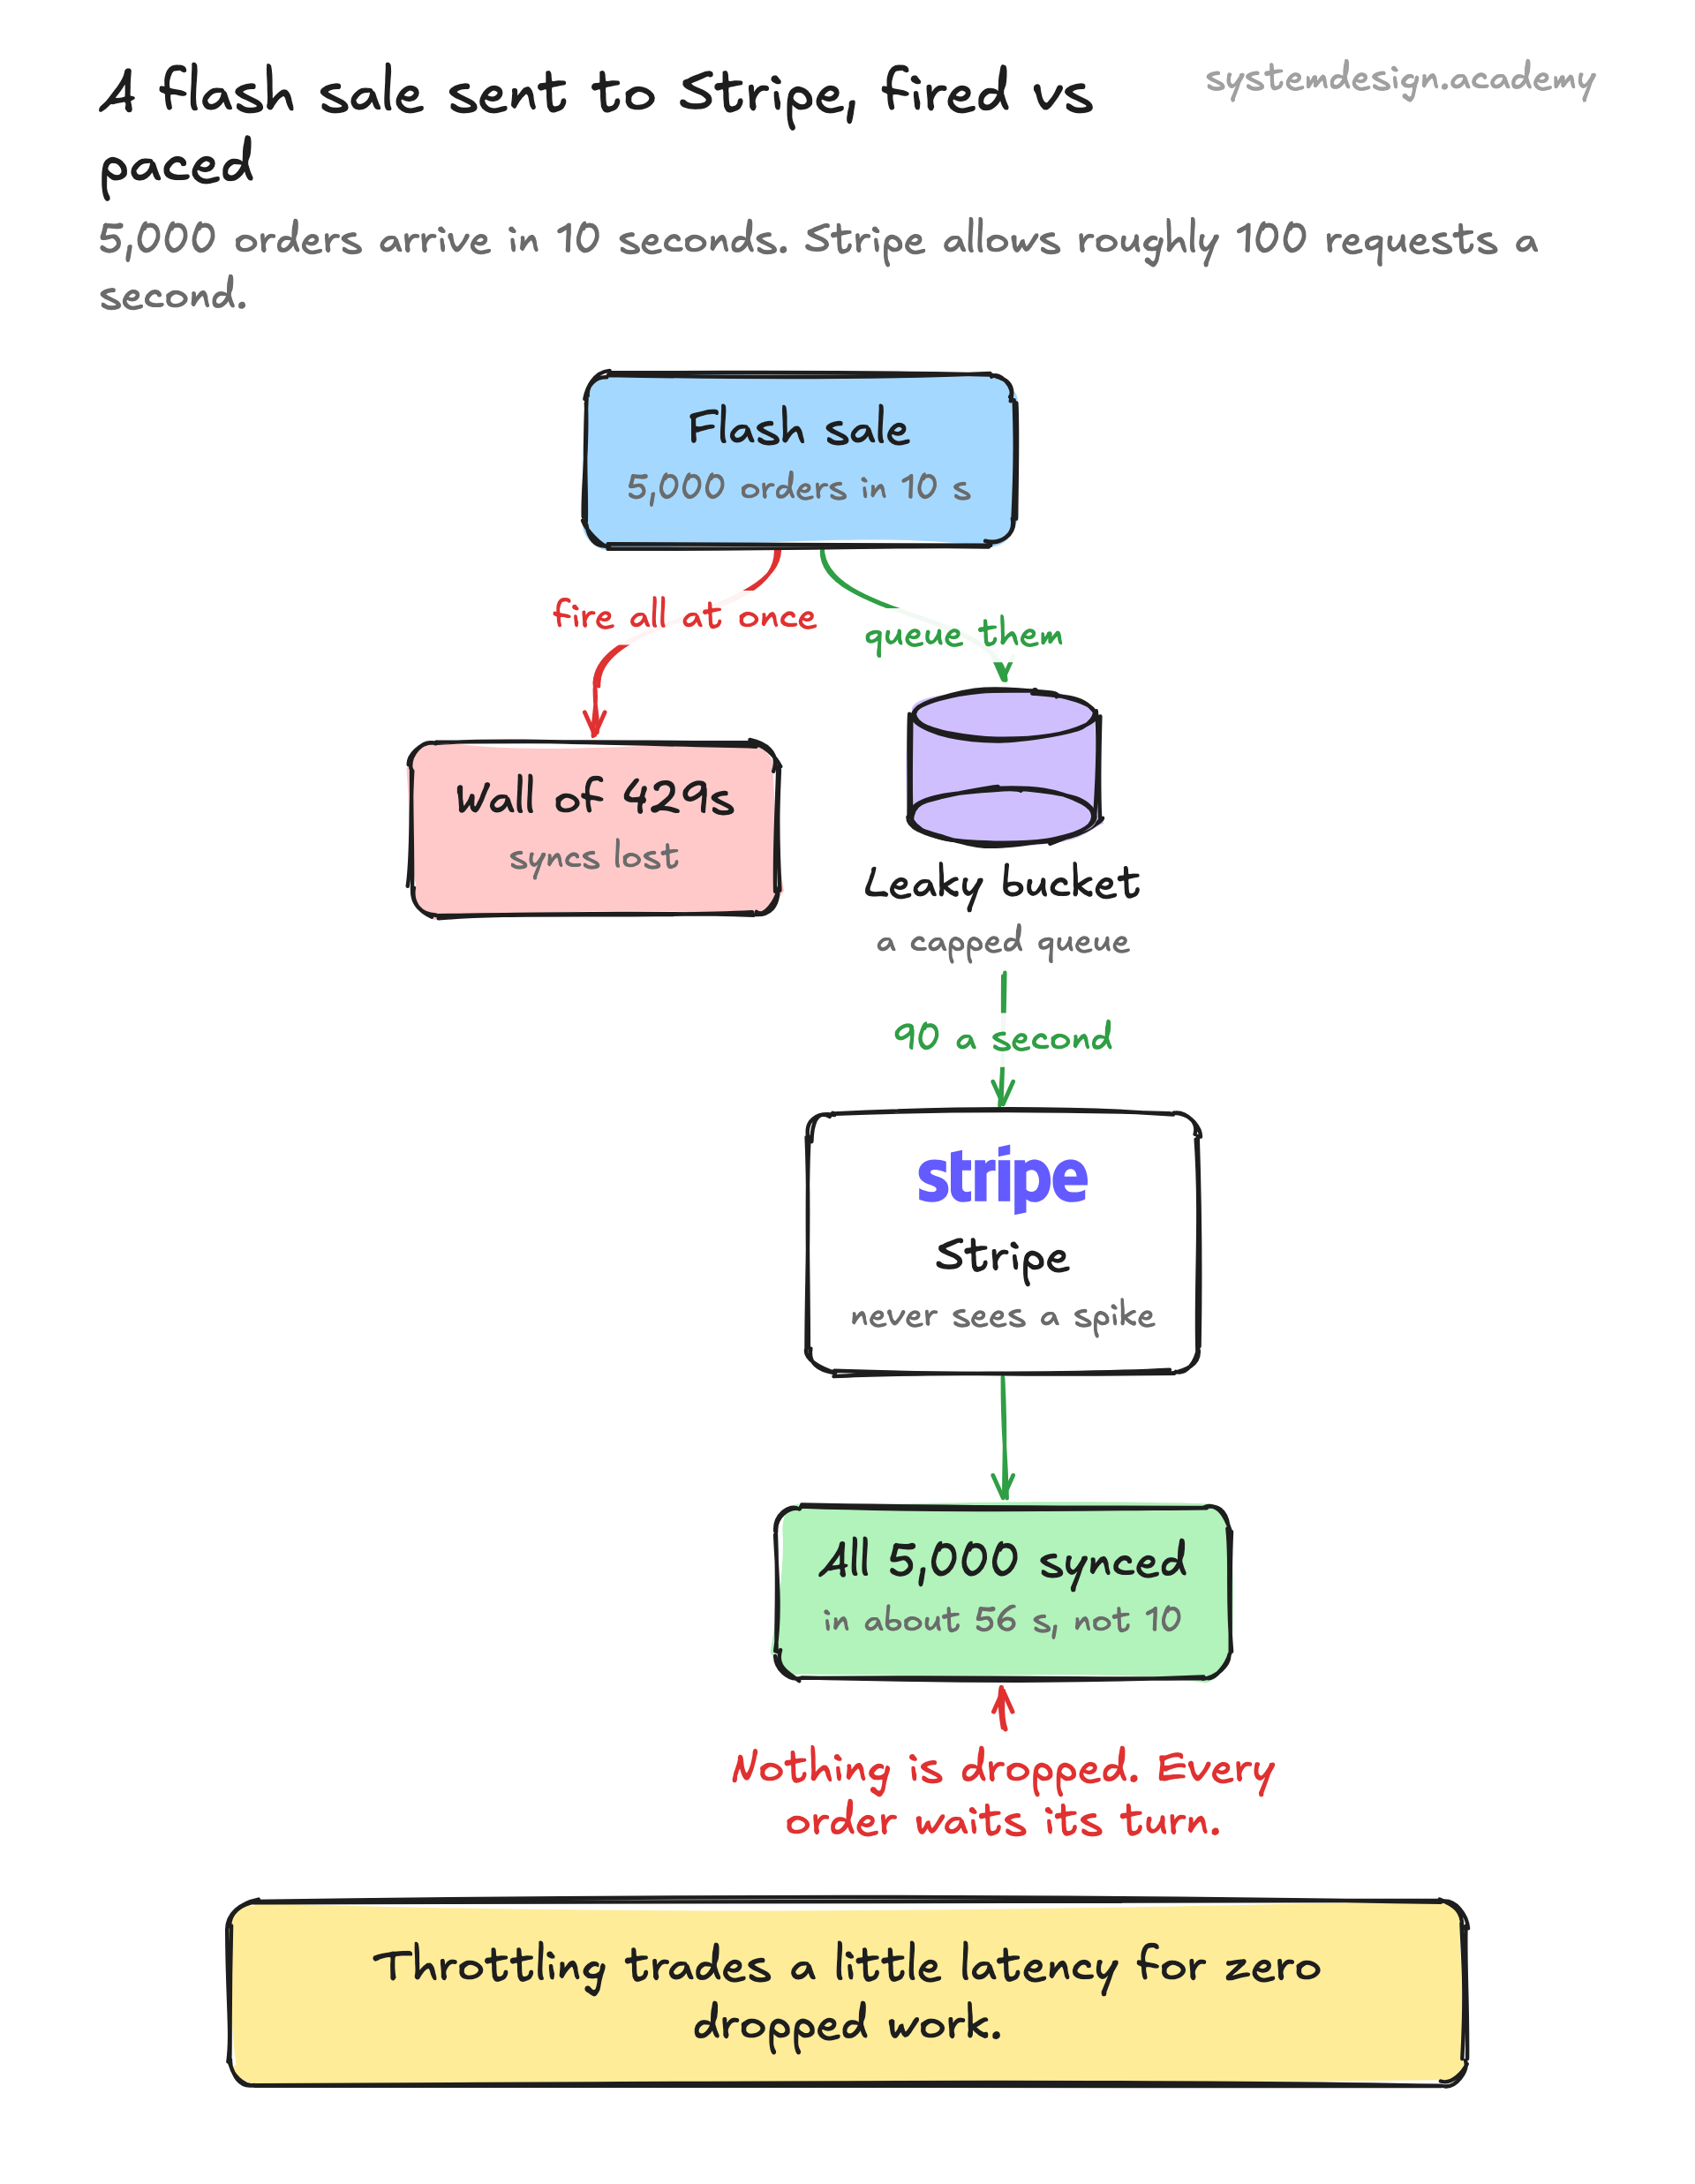
Most throttling is built on a token bucket or leaky bucket algorithm. In a token bucket, the system refills tokens at a steady rate, say 10 per second, up to a maximum. Each request spends one token. When the bucket is empty, requests wait for the next token instead of being dropped. That refill rate is your sustained throughput and the bucket size is how big a burst you tolerate.
A leaky bucket models it the other way around. Requests pour into a queue and drain out at a fixed rate, like water leaking from a bucket with a small hole. If requests arrive faster than the drain rate, they pile up in the queue and are processed later. This smooths a spiky traffic pattern into a steady stream the backend can handle.
On the client side, throttling shows up as backpressure. The server tells the caller to slow down, often through HTTP headers like Retry-After or X-RateLimit-Remaining, and a well-behaved client backs off, usually with exponential backoff and jitter so a thundering herd does not all retry at the same instant. AWS SDKs, for example, do this automatically when they get a throttling response.