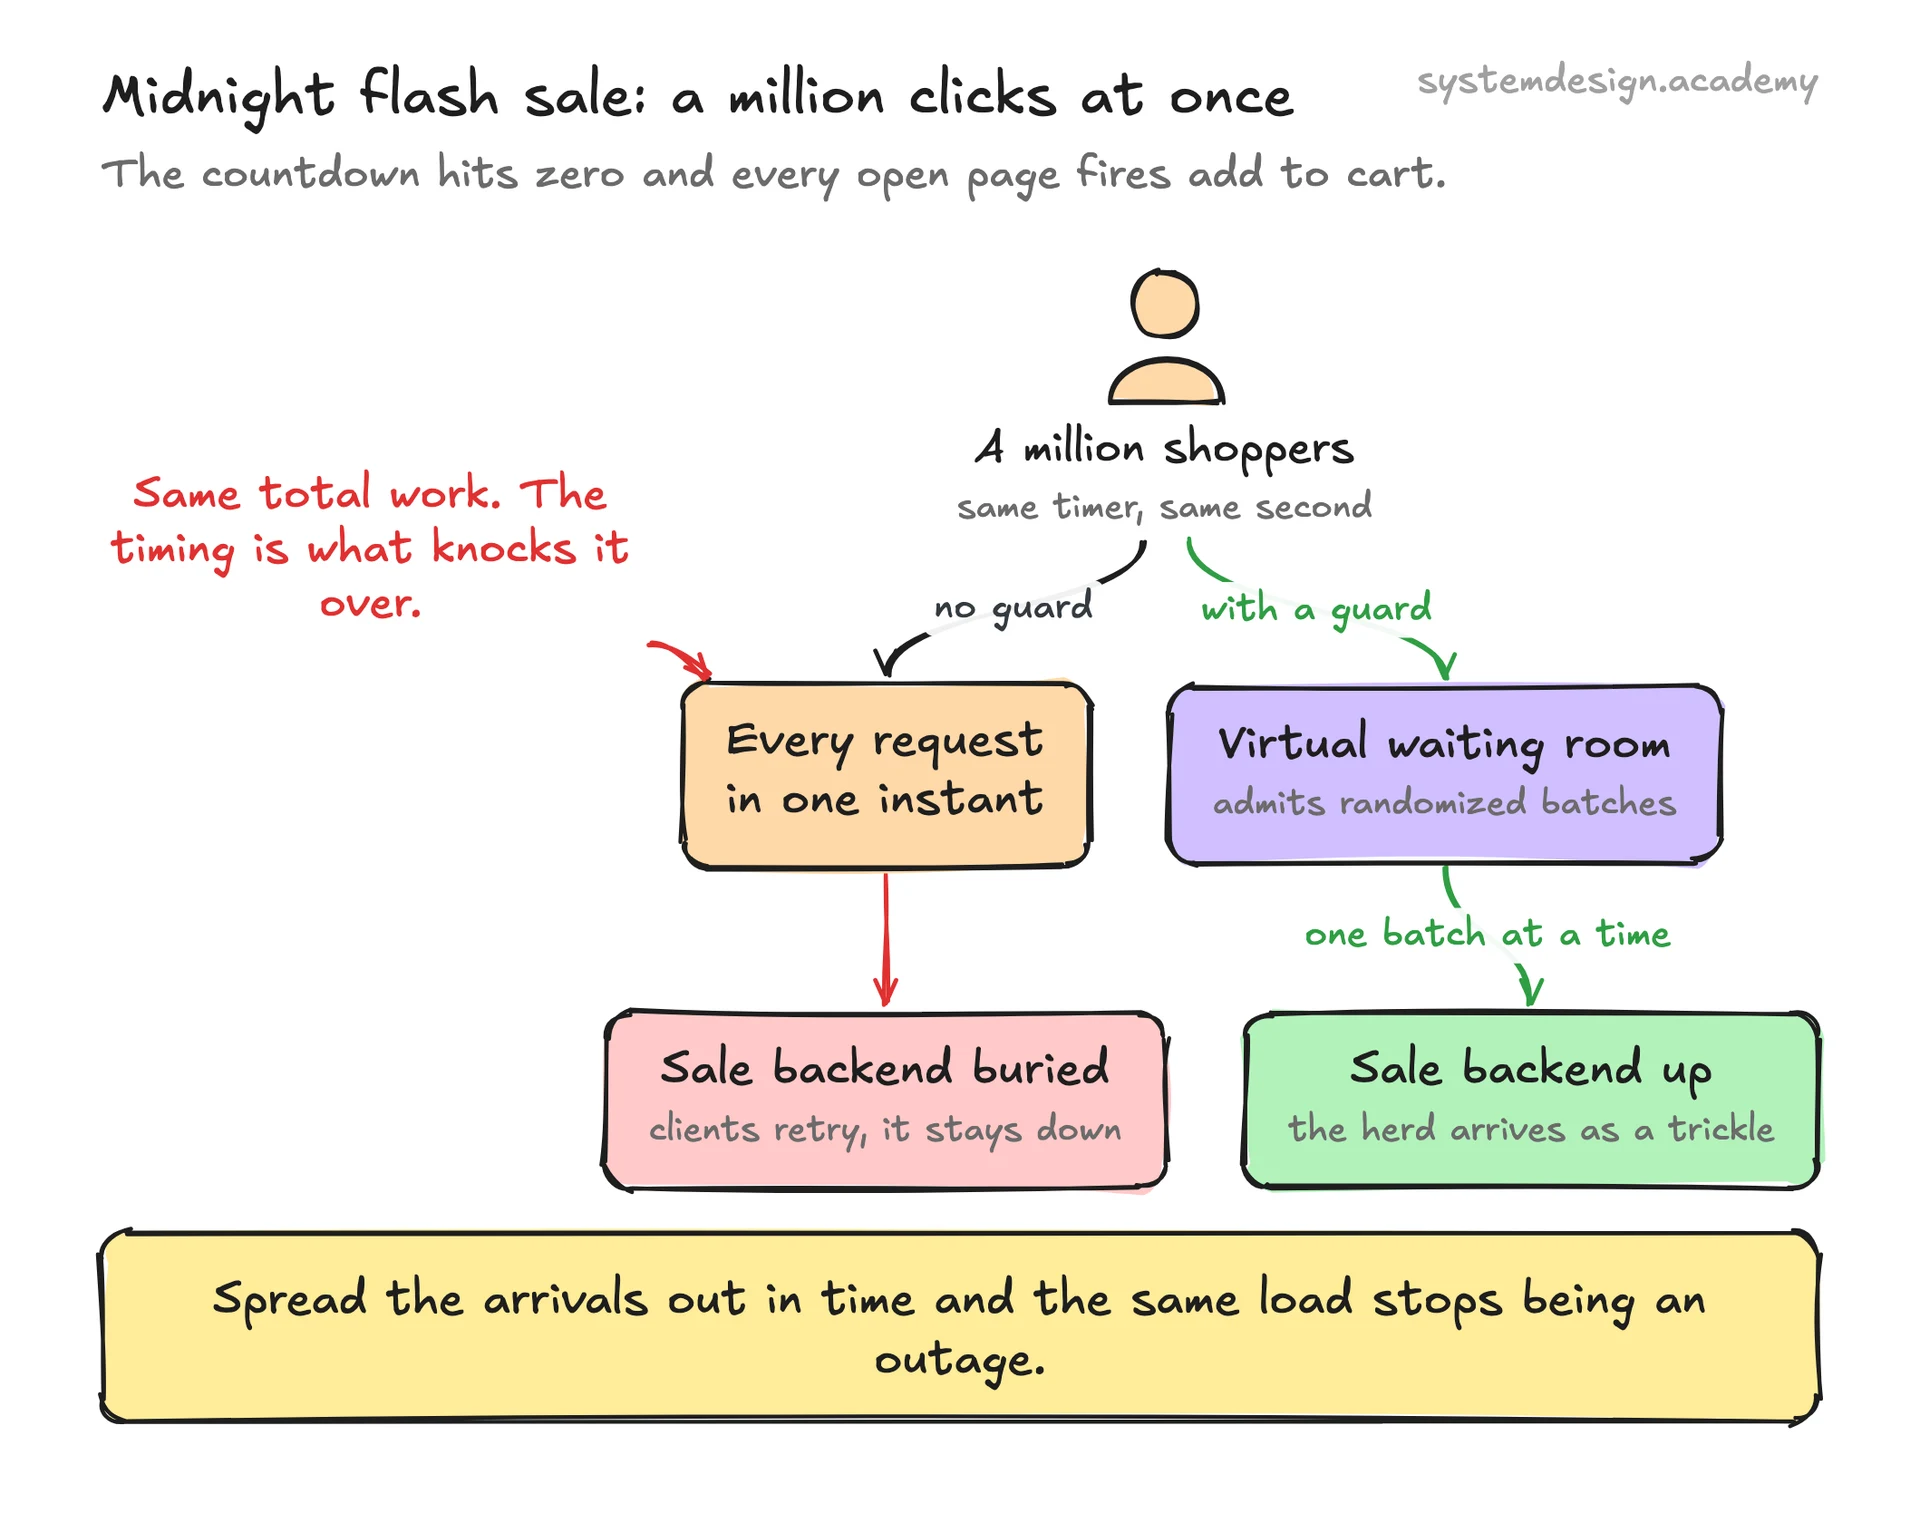
The root cause is synchronization. Independent clients accidentally line up on the same clock or the same event. Fixed retry intervals are the worst offender: if everyone retries exactly 1 second after a 503, they all come back together, fail together, and retry together forever.
Jittered exponential backoff breaks the synchronization. Each client waits a base delay that doubles on each failure (1s, 2s, 4s), then adds a random amount on top so the retries spread out instead of clustering. Full jitter, where the actual wait is a random value between zero and the current backoff ceiling, is the version AWS recommends and the one most SDKs ship.
Request coalescing attacks the duplicate-work angle. When many callers ask for the same thing that is not ready yet, only the first one does the real work and the rest wait on that single in-flight result. Go's singleflight package and Nginx proxy_cache_lock are direct implementations. For cache stampedes you also use a short lock on the key plus a stale-while-revalidate window so one request refreshes the value while everyone else keeps serving the old one.
Admission control is the last line. The recovering service decides how much it will accept rather than trying to serve everything. Concurrency limits, token buckets, load shedding that returns 429 early, and circuit breakers that stay open during recovery all cap the inbound rate so the herd arrives as a trickle.